Cloudflare Agent Memory: A Developer's Guide to the New Primitive
Agent Infrastructure
3 parts- 110 Tools We Built for Agent Infrastructure
- 2Vercel's New Durable Execution Programming Model: A Developer's Guide
- 3Cloudflare Agent Memory: A Developer's Guide to the New PrimitiveCurrent
TL;DR
Cloudflare's Agent Memory primitive. What it stores, how ingest and recall work, how it compares to mem0, and how to wire it into your stack.
Last updated: October 18, 2026
Updated October 18, 2026: Status, billing and scoping now match our verified Cloudflare Agent Memory directory page. Agent Memory is in private beta and is not billed during the beta, so the earlier free-tier and per-query billing notes are gone. Memory is not limited to one agent id: Cloudflare documents isolated profiles for users, agents, tenants, teams or application entities. The code sample, the storage and retrieval description, the latency and summarization claims, the gotchas and the FAQ were also corrected to match Cloudflare's Agent Memory docs; the code is now adapted from Cloudflare's own get-started example.
Why memory is the agent bottleneck#
If you have shipped a production agent in the last twelve months, you already know that memory is where the wheels come off. The model is not the bottleneck. The framework is not the bottleneck. The thing that keeps your agent from feeling like a real product is that it forgets everything between sessions and most things within a session.
For the design side of the same problem, read AI Agents Explained: A TypeScript Developer's Guide with How to Build AI Agents in TypeScript; they show how agent-generated interfaces fail and how to give coding agents better visual constraints.
There are three workable answers to this in the open. You can run mem0 and pay for the managed service. You can roll your own with a vector store, a summarization pass, and a lot of glue code. Or you can wait for the platform you already deploy on to ship a memory primitive.
Cloudflare just shipped that primitive. The Agent Memory announcement is the most opinionated take on agent state we have seen from a hyperscaler. It is worth comparing to mem0 directly because the two are aimed at exactly the same problem and they make very different tradeoffs.
What the announcement actually says#
Cloudflare Agent Memory is a managed memory service: per How Agent Memory works, it "automatically turns raw conversations into structured knowledge and retrieves the right context when you need it." You reach it from a Worker through a binding, or from external services through the Cloudflare API (API docs). Four things make it different from "just use D1 plus Vectorize." One status note before you plan around it: per Cloudflare's Agent Memory docs, "Agent Memory is in private beta."
It is entity-scoped. Cloudflare's docs describe "Isolated profiles for users, agents, tenants, teams, or application entities" (source). The isolation model has two levels: a namespace is the top-level container for a set of profiles (one per application, environment or memory layer), and a profile is an isolated memory store for a single entity, with its own memories and retrieval indexes. Sessions optionally group memories from one conversation inside a profile.
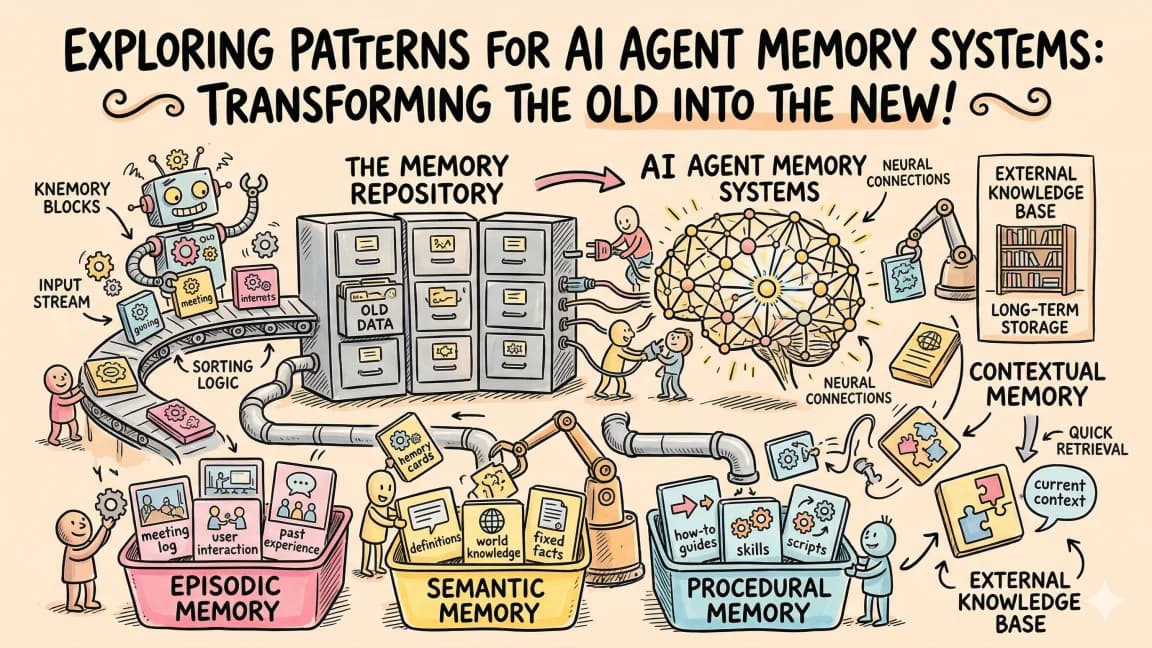
It classifies what it stores. Every extracted memory becomes one of four types: facts (stable knowledge such as preferences, identities, relationships and goals), events (completed actions anchored to a point in time), instructions (reusable procedures and conventions), and tasks (short-lived, session-scoped items). Facts and instructions evolve through supersession: when a newer memory shares a topic key with an older one, the old version is kept but the latest surfaces in recall.
It does the extraction for you. When you call ingest() with conversation messages, the docs describe four stages: AI extraction of discrete memorable items, classification into a type with a topic key, keywords and search queries, deduplication against the batch and existing memories, and storage. "Memories are written to durable storage with full-text search indexes. Non-task memories are also embedded as vectors for semantic search." The raw messages are kept too: "Raw conversation messages are always stored verbatim alongside extracted memories."
It answers, not just retrieves. A recall() call analyzes the query, then "simultaneously searches across keyword indexes, topic key lookups, semantic vector indexes, and raw conversation messages," ranks the combined results, and has AI generate a natural language answer from the top-ranked memories. "If no memories match the query, recall() returns an empty answer rather than hallucinating a response."
What it looks like in code#
The following is adapted from Cloudflare's get-started guide, trimmed to the memory calls and keeping Cloudflare's identifiers. First create a namespace and bind it in your Wrangler config:
npx wrangler agent-memory namespace create my-agent
[[agent_memory]]
binding = "MEMORY"
namespace = "my-agent"
Recall goes inside the Agents SDK Session API's searchable context provider, which turns search() into a search_context tool the model can call:
search: async (query: string) => {
  const profile = await this.env.MEMORY.getProfile(MEMORY_PROFILE_NAME);
  const { answer } = await profile.recall(query, {
    responseLength: "short",
  });
  return answer || "No relevant memories found.";
},
Ingestion runs on a schedule after the user goes idle, sending only the messages that have not been ingested yet:
const profile = await this.env.MEMORY.getProfile(MEMORY_PROFILE_NAME);
await profile.ingest(messages, { sessionId: this.name });
A few things to notice.
Recall has to be a tool. The guide is explicit: "The model cannot use memory just because your application has a memory binding. You need to expose recall through a tool and instruct the model when to call it." Cloudflare's example pairs the tool with a memory policy in the system prompt that says when to search, when not to, and to "Treat recalled memories as helpful context, not guaranteed truth."
Ingest in batches, not per turn. "Do not call ingest() after every model turn. Instead, batch ingestion after the user goes idle, when a conversation is compacted, or at another natural checkpoint." The example cancels and reschedules a pending ingest on every user message, and keeps a cursor so each batch only includes new messages. When your agent already knows exactly what to store, the guide points to remember() instead.
Re-ingestion is safe. "Messages are content-addressed": each message gets a deterministic ID from its content and session, so sending the same message twice does not create a duplicate. If you omit sessionId, one is derived from the message content.
Gotchas worth knowing#
There is no price to model yet. Cloudflare's pricing page says "We are not currently billing for Agent Memory during private beta," and "We will provide at least 30 days notice before we make any changes or start charging for Agent Memory usage." Profile how many reads and writes each turn makes now, so you can price it the day a rate card appears.
New memories are not instantly recallable. In the guide's test, ingestion runs 10 seconds after the user goes idle, "and Agent Memory then needs additional time to extract, classify, and index the memories before they are available for recall." The guide tells you to wait at least 30 seconds before testing recall. Design the UX so an agent does not promise to remember something it cannot recall yet.
Recall returns a synthesized answer. What comes back is AI-generated text grounded in the stored memories, not the raw rows, and it can be empty. Handle the empty case (the example falls back to "No relevant memories found.") and keep the system prompt guidance to confirm important memories with the user before irreversible actions.
Tasks fade on purpose. Tasks are session-scoped, and "Tasks are deprioritized after the session ends." If something must survive the session, it needs to land as a fact, event or instruction.
Respect the limits: 500 messages per ingest() call, 32 KB per message, 1 KB per recall query, 64-character session IDs, 100-character profile names and 32-character namespace names.
DD take: where it fits versus mem0#
mem0 is the incumbent here, and the comparison is interesting because the two products target the same problem from different sides.
mem0 is a managed service with a strong ergonomic story. The SDK feels designed for people who do not want to think about storage. It runs on its own infrastructure, exposes a clean REST API, and has the most mature schema for "extract preferences from raw turns automatically." If you are running outside Cloudflare and want a memory layer that feels like a finished product, mem0 is still the answer.
Cloudflare Agent Memory is closer to a finished memory product than to a managed database. Per the docs it extracts, classifies, deduplicates and stores memories on ingest, and on recall it searches several indexes in parallel and synthesizes an answer. What you still own is the wiring: exposing recall to the model as a tool, writing the memory policy in the system prompt, scheduling batched ingestion, and choosing profile and namespace scopes. It is reached through a Worker binding or the Cloudflare API, so it fits most naturally if you already build on Workers.
The right way to choose is by deploy target, and it is worth seeing where both sit against the wider field in best AI agent memory providers in 2026: Mem0 vs Zep vs Letta vs Cloudflare. If your agent runs on Workers, Cloudflare Agent Memory is the obvious primitive, once you have private beta access. If your agent runs on Vercel, AWS, or Fly, mem0's portability is the clearer win. Mixing the two is possible but probably overkill for an indie team.
Cost-wise, the comparison is not possible yet: mem0 publishes plan prices, while Cloudflare is "not currently billing for Agent Memory during private beta" (source). Re-run the math when Cloudflare publishes a rate card.
Wiring it into a real product#
We have been integrating Agent Memory into AgentFS, our virtual filesystem layer for AI agents that gives them durable, sandboxed working storage across runs. AgentFS started as a thin wrapper over R2 and Durable Objects to give agents a persistent /workspace directory between sessions. The memory primitive lets us layer a richer abstraction on top: the agent's beliefs about the workspace, not just the raw bytes in it.
The pattern is straightforward. AgentFS stores files in R2. Cloudflare Agent Memory holds what the agent learned about those files - what they are, what changed last session, what the user wanted - in a memory profile, filled by ingesting each session at a natural checkpoint. The agent walks into a new session, recalls "what was I working on in this directory," and gets back an answer without scanning the whole filesystem.
For observability, Traces is where we want memory activity to show up on the session timeline: which recall calls the agent made, what came back, and when each session was ingested. Cloudflare's docs list "Profile summaries for observing what Agent Memory remembers," which is the natural starting point for that view. Without visibility like this, you are guessing about why the agent forgot something or why it remembered something it should not have.
Wiring memory into a real product is not just about storage. It is about understanding what the agent saw and when. That is a tooling problem as much as an infrastructure problem.
What to watch next#
The interesting open questions.
Cross-agent memory. Memory is not tied to one agent id: the docs describe "Isolated profiles for users, agents, tenants, teams, or application entities" (source). Isolation is strict, though: "A recall() on Alice's profile never returns memories from Bob's profile." Real product use cases - a customer support agent that needs to know what the sales agent told the user yesterday - need a shared memory layer, so pick a profile scope both agents can read (the docs suggest namespaces for "memory layers such as user, team, and organization memory") and test it before you build around it. mem0 already supports it.
Memory pruning policy. The docs list "APIs to add, list, recall, and delete memories," but the pages we reviewed describe no TTL or retention window. Two details matter for GDPR and product hygiene: superseded facts are kept ("the full history is preserved"), and raw messages are stored verbatim. Confirm your deletion flow covers both before you rely on it.
The "memory as a graph" question. The docs describe topic keys, keywords, supersession and vector embeddings, not a graph. Some of the most interesting agent memory research is about graph structures over those memories. Whether platforms ship graph-native memory or push it to userland is the next architectural decision worth tracking.
We are running a deeper hands-on walkthrough on YouTube, building a customer support agent that uses Cloudflare Agent Memory end to end, with debug traces and a side-by-side comparison against mem0. If you are picking your memory layer this quarter, that comparison is the thing to watch. The platforms have converged faster than expected, and the choice is now mostly about deploy target rather than capability.
FAQ#
What is Cloudflare Agent Memory?#
Cloudflare Agent Memory is a managed memory service for agents, accessed through a Worker binding or the Cloudflare API. You ingest conversations and it extracts, classifies and deduplicates durable memories into isolated profiles inside a namespace; you call recall and it searches keyword, topic key, semantic and raw-message indexes in parallel and returns a synthesized answer. It is not generally available yet: "Agent Memory is in private beta," per Cloudflare's docs.
How does Cloudflare Agent Memory compare to mem0?#
mem0 is a standalone managed service with a polished SDK and automatic preference extraction - ideal if you want minimal code and run outside Cloudflare. Cloudflare Agent Memory also extracts memories automatically and synthesizes recall answers, but it is reached through a Worker binding or the Cloudflare API, and you wire recall into your agent as a tool yourself. Choose by deploy target: Cloudflare Agent Memory for Workers, mem0 for Vercel, AWS, or Fly. A cost comparison has to wait: Cloudflare is "not currently billing for Agent Memory during private beta" (source).
What memory types does it store?#
Four, per How Agent Memory works: facts (stable knowledge such as preferences and relationships), events (completed actions anchored to a point in time), instructions (reusable procedures and conventions) and tasks (short-lived, session-scoped items that are deprioritized after the session ends). Facts and instructions with the same topic key supersede older versions while keeping the history.
How does recall work?#
recall() analyzes your query, searches keyword indexes, topic key lookups, semantic vector indexes and raw conversation messages in parallel, ranks the combined results, and has AI write a natural language answer grounded in the top-ranked memories. If nothing matches, it returns an empty answer. The model only uses it if you expose recall as a tool, which the get-started guide does through the Agents SDK Session API.
What are the billing gotchas?#
There is no bill yet. Cloudflare's pricing page says "We are not currently billing for Agent Memory during private beta," and promises "at least 30 days notice before we make any changes or start charging for Agent Memory usage." The gotcha is planning: profile your per-turn reads and writes now so you can compare against mem0's pricing once Cloudflare publishes rates.
What limits apply?#
Per the limits page: 500 messages per ingest() call, 32 KB (32,768 bytes UTF-8) per message, 1 KB per recall query, 64 characters per session ID, 100 characters per profile name, 32 characters per namespace name, and list API pages of 1 to 1,000 items (default 20).
Does Cloudflare Agent Memory support cross-agent memory?#
Memory is not scoped to a single agent id. Cloudflare's docs describe "Isolated profiles for users, agents, tenants, teams, or application entities" (source), so a profile can belong to a user, team or tenant rather than one agent. Test that a shared profile covers your case - like a support agent that needs to know what a sales agent told the user yesterday - before relying on it. mem0 already supports cross-agent memory sharing.
What about GDPR and data deletion?#
The docs list "APIs to add, list, recall, and delete memories," so deletion is part of the API. The pages we reviewed do not describe a TTL or automatic retention window. Keep in mind that superseded facts and instructions are preserved and raw conversation messages are stored verbatim, so build your deletion and retention logic explicitly and confirm it covers both.
Official Sources#
| Resource | Link |
|---|---|
| Cloudflare Agent Memory Announcement | blog.cloudflare.com/introducing-agent-memory |
| Cloudflare Agent Memory Docs (status, scopes) | cloudflare-docs: agent-memory/index.mdx |
| Cloudflare Agent Memory Get Started (code source) | cloudflare-docs: agent-memory/get-started.mdx |
| How Agent Memory Works (types, ingest, recall) | cloudflare-docs: agent-memory/concepts/how-agent-memory-works.mdx |
| Namespaces and Profiles | cloudflare-docs: agent-memory/concepts/namespaces-profiles.mdx |
| Cloudflare Agent Memory Limits | cloudflare-docs: agent-memory/platform/limits.mdx |
| Cloudflare Agent Memory Pricing | cloudflare-docs: agent-memory/platform/pricing.mdx |
| Cloudflare Agents SDK Docs | developers.cloudflare.com/agents |
| Cloudflare Workers AI | developers.cloudflare.com/workers-ai |
| Cloudflare Durable Objects | developers.cloudflare.com/durable-objects |
| Cloudflare Vectorize | developers.cloudflare.com/vectorize |
| mem0 (Alternative) | mem0.ai |
Continue Reading#
- AI Agent Frameworks Compared - LangGraph, CrewAI, Mastra, CopilotKit, AutoGen and Claude Code side by side
- AI Agent Memory Services and Frameworks Compared - Cloudflare Agent Memory beside Mem0, Zep, Google Memory Bank, AgentCore Memory and more, every value quoted
Get the next deep dive like this in your inbox
One email a week on Cloudflare and the rest of the AI dev stack. Free.
Read next on AI coding tools
AI Agent Memory Patterns
AI agent memory patterns that fix forgetting between sessions: CLAUDE.md persistence, RAG retrieval, conversation summarization, structured and tiered memory.
9 min readThe Agentic Development Tech Stack for 2026
Coding changed more in the past two years than in the previous decade. We moved from manual typing to autocomplete, then to multi-file edits.
12 min readVercel's New Durable Execution Programming Model: A Developer's Guide
Vercel Workflows is GA: durable TypeScript with "use workflow" and "use step". What it means for agents and long-running flows, with code adapted from Vercel's own examples.
10 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.