10 Tools We Built for Agent Infrastructure
Agent Infrastructure
3 parts- 110 Tools We Built for Agent InfrastructureCurrent
- 2Vercel's New Durable Execution Programming Model: A Developer's Guide
- 3Cloudflare Agent Memory: A Developer's Guide to the New Primitive
TL;DR
Ten private tools shipped overnight - observability, skills, hooks, prompts, and evals - aimed at the agent infrastructure gap small teams keep falling into.
Last updated: April 28, 2026
The gap nobody is filling#
The big agent platforms ship for enterprise. The open-source frameworks ship for hobbyists. In the middle sits a small but growing group of teams running agents in production every day - two engineers, four engineers, ten engineers - who need real tooling but cannot stomach Langsmith pricing or wire up Datadog for a side project. That is the gap we keep falling into ourselves at Developers Digest. So over the past week we built ten tools for it, all private for now, all aimed at the same thesis: agent infrastructure for small teams is a real category, and the surface area is much wider than observability alone.
Here is what dropped, why each one exists, and how the pieces compose.
The directory#
1. SkillForge CI#
Claude Code skills are markdown files. Markdown is forgiving. That is the problem. A typo in a skill's frontmatter, a malformed trigger line, a missing description - none of it surfaces until the skill silently fails to load on someone else's machine. SkillForge CI is a GitHub Action that lints every SKILL.md in a repo on push. It checks frontmatter shape, validates triggers, flags drift between the description line and what the skill actually does, and refuses to merge skills with broken script references.
Install is one workflow file. The action is private today; once we have a stable rule set we will open it up.
- uses: developersdigest/skillforge-ci@v0
If your team shares skills across repos, this is the seatbelt. Note that as of today Org Actions billing is paused for us, so CI is red regardless - the action runs locally via act until that clears.
2. MCP Lens#
MCP servers communicate over stdio. When something breaks, you see nothing. MCP Lens is a transparent proxy that sits between your MCP host and any server, captures every JSON-RPC frame in both directions to a JSONL log, and serves a local inspector at localhost:4040. We call it Wireshark for MCP because that is exactly what it is.
mcp-lens --ui -- npx -y @modelcontextprotocol/server-filesystem /tmp
The full walk-through is in the MCP Lens debugging tutorial. If you have ever watched a Claude Code tool call hang for forty seconds with no idea why, this is the tool you wished you had. Replay, schema-diff, and shareable session links are next.
3. TraceTrail#
Once you can capture an agent run, you want to share it. TraceTrail is Loom for agent runs. Upload a Claude Code JSONL transcript, get a public read-only replay URL with a stepped timeline, tool calls expanded inline, costs per step, and a permalink anyone can open without an account. Auth-gated upload, public replay - same shape as Loom.
curl -F "file=@session.jsonl" https://tracetrail.dev/api/upload
The full walk-through is in the TraceTrail tutorial. We are using it internally for bug reports, demos, and onboarding. It is the one tool on this list that already feels indispensable a week in.
4. dd-ga (Drift Doctor for Google Analytics)#
We run twenty-four sites under the Developers Digest umbrella. Every one needs Google Analytics. Every one ends up with a slightly different GA wiring - hardcoded measurement IDs in some, helper paths inconsistent across others, a few that only fire page views and miss events entirely. dd-ga audits a Next.js repo or a glob of them, flags the drift, and exits non-zero on errors so it can run in CI.
node bin/dd-ga.js audit-all '/Users/j/Developer/dd-*'
It found three sites with broken GA in our portfolio the first time we ran it. Not glamorous. Extremely useful. Same pattern will work for Sentry, sitemap, robots, OG, llms.txt - every shared-infra concern that silently rots across a portfolio of small apps.
5. Cost Tape#
Every developer running agents has had the moment where they look at the Anthropic dashboard at the end of a session and feel something cold in their stomach. Cost Tape is a VS Code status bar extension that polls the Anthropic and OpenAI org cost endpoints every five minutes and renders a tape: $3.60 today / $96.65 mtd. Click it for a per-provider breakdown. Bring your own admin key.
{
  "costTape.anthropicAdminKey": "sk-ant-admin-...",
  "costTape.openaiAdminKey": "sk-admin-..."
}
It is the cheapest possible answer to "how much am I spending right now." Webview dashboards and shareable charts come later. Pairs naturally with our overnight bill post-mortem.
6. Hookyard#
Claude Code hooks are powerful and almost nobody uses them, because writing one means hand-editing ~/.claude/settings.json and getting the JSON shape exactly right. Hookyard is a curated directory of hooks plus a CLI installer that patches your settings file idempotently with a .bak backup before each write. Think npm install but for hooks.
npx hookyard install obsidian-auto-commit
The full walk-through is in the Hookyard tutorial. The directory site is browsable, every hook is typed, and the installer never touches your real settings without a snapshot. We are seeding it with the hooks from our own stack and opening submissions once the schema settles.
7. Promptlock#
Your prompts are production code, but most teams ship them as raw markdown with no version IDs, no diffs, no provenance. A whitespace tweak in a system prompt can shift eval scores by ten points and you would never know which commit did it. Promptlock turns every prompt into a content-addressable artifact - twelve-character ID, model, temperature, vars, note - that you can commit, diff, and roll back.
promptlock add prompt.md --model claude-opus-4-7 --temperature 0.2
The full walk-through is in the Promptlock versioning tutorial. Cloud sync, eval suite integration, and PR-comment diffs are intentionally out of scope for v0.1. Step one is just giving prompts a stable identity. Everything else builds on that.
8. dd-utm#
The most embarrassing reason for clean attribution data on your video distribution: we kept forgetting to tag links. Different videos used different UTM conventions, half the social posts had no UTM at all, the newsletter had its own scheme. dd-utm is a one-prompt CLI that standardizes UTM tagging across YouTube, X, LinkedIn, Threads, Bluesky, and the newsletter, with templates for each platform.
dd-utm https://devdigest.tv/blog/prompt-versioning-with-promptlock --template youtube --campaign launch-promptlock
Tiny tool. Solved a real recurring annoyance the day we shipped it. The principle generalizes: most "agent infrastructure" is just removing friction from work the team is already doing.
9. Subagent Studio#
Claude Code subagents live in .claude/agents/*.md files with strict frontmatter rules. Get the kebab-case wrong, embed a newline in the description, list a tool that does not exist - the agent silently fails to load. Subagent Studio is a visual designer with a form-based editor on the left and a live preview on the right. Three starter templates: research, code reviewer, test writer. Copy or download the rendered markdown - it never writes to your real ~/.claude/agents/ directory.
pnpm dev # http://localhost:3000
If SkillForge CI is the seatbelt for skills, Subagent Studio is the seatbelt for agents. Lower the floor, fewer broken configs, more people shipping agent fan-outs that actually work.
10. Agent Eval Bench#
The last piece. Once you have versioned prompts, captured runs, and observability tape, you need a way to ask "did this change make things better." Agent Eval Bench is a deterministic eval suite runner. Define test cases as YAML, run them concurrently against any model, score with assertions or a small judge prompt, write a report.
aeb run examples/basic-suite.yaml --model claude-sonnet-4-6 --concurrency 4
Scorers today are contains, regex, and a judge prompt. JSON and Markdown reports out of the box. It is the smallest possible thing that lets you catch a regression in a prompt change before it ships. Pairs directly with Promptlock - lock the prompt, eval the lock.
The through-line#
Look at the list again and the shape gets clearer.
Observability: MCP Lens captures the wire, TraceTrail shares the run, Cost Tape watches the spend. You cannot improve what you cannot see, and the existing tools either cost too much or assume too much.
Skills and hooks: SkillForge CI lints, Hookyard installs, Subagent Studio designs. These are the extension surfaces of Claude Code, and right now there is no tooling around them at all - everyone is hand-editing markdown and praying.
Prompts and evals: Promptlock versions, Agent Eval Bench scores. Together they let a small team treat prompts like code: identity, diffs, regressions caught in CI.
Portfolio infrastructure: dd-ga audits drift, dd-utm standardizes outbound. The boring connective tissue that keeps a portfolio of small apps coherent without a platform team.
That is the thesis. Agent infrastructure for small teams is not one tool, it is a stack - and most of the stack does not exist yet because the big platforms are too busy chasing enterprise and the open-source frameworks are too busy chasing star counts. The middle is wide open. The agent ecosystem report makes the case in more detail.
Roadmap honesty#
None of these are production-ready. None of them are public yet. Every one is at v0.1 or earlier and was built on a single overnight push, which is exactly the right amount of stress test for a thesis like this - if a tool does not survive its own author using it for a week, it does not get released.
The plan from here:
- Eat our own dog food for two weeks. Every tool gets used internally on the Developers Digest portfolio and on real work. Tools that do not survive get killed.
- Open the four with tutorials first - Promptlock, TraceTrail, Hookyard, MCP Lens - because each one already has a written narrative we are willing to defend in public.
- Open the rest only when they earn it. Cost Tape needs polish on the click-through dashboard. Subagent Studio needs templates. Agent Eval Bench needs more scorers. SkillForge CI needs a stable rule set. dd-ga and dd-utm are useful internal tools that may stay internal.
If you want to see how these compare to the alternatives, the tools comparison page covers the existing landscape. We will update it as each of these ten goes public.
Comments and DMs welcome. The thesis is the part we want to be wrong about, fast.
FAQ#
What are the ten agent infrastructure tools?#
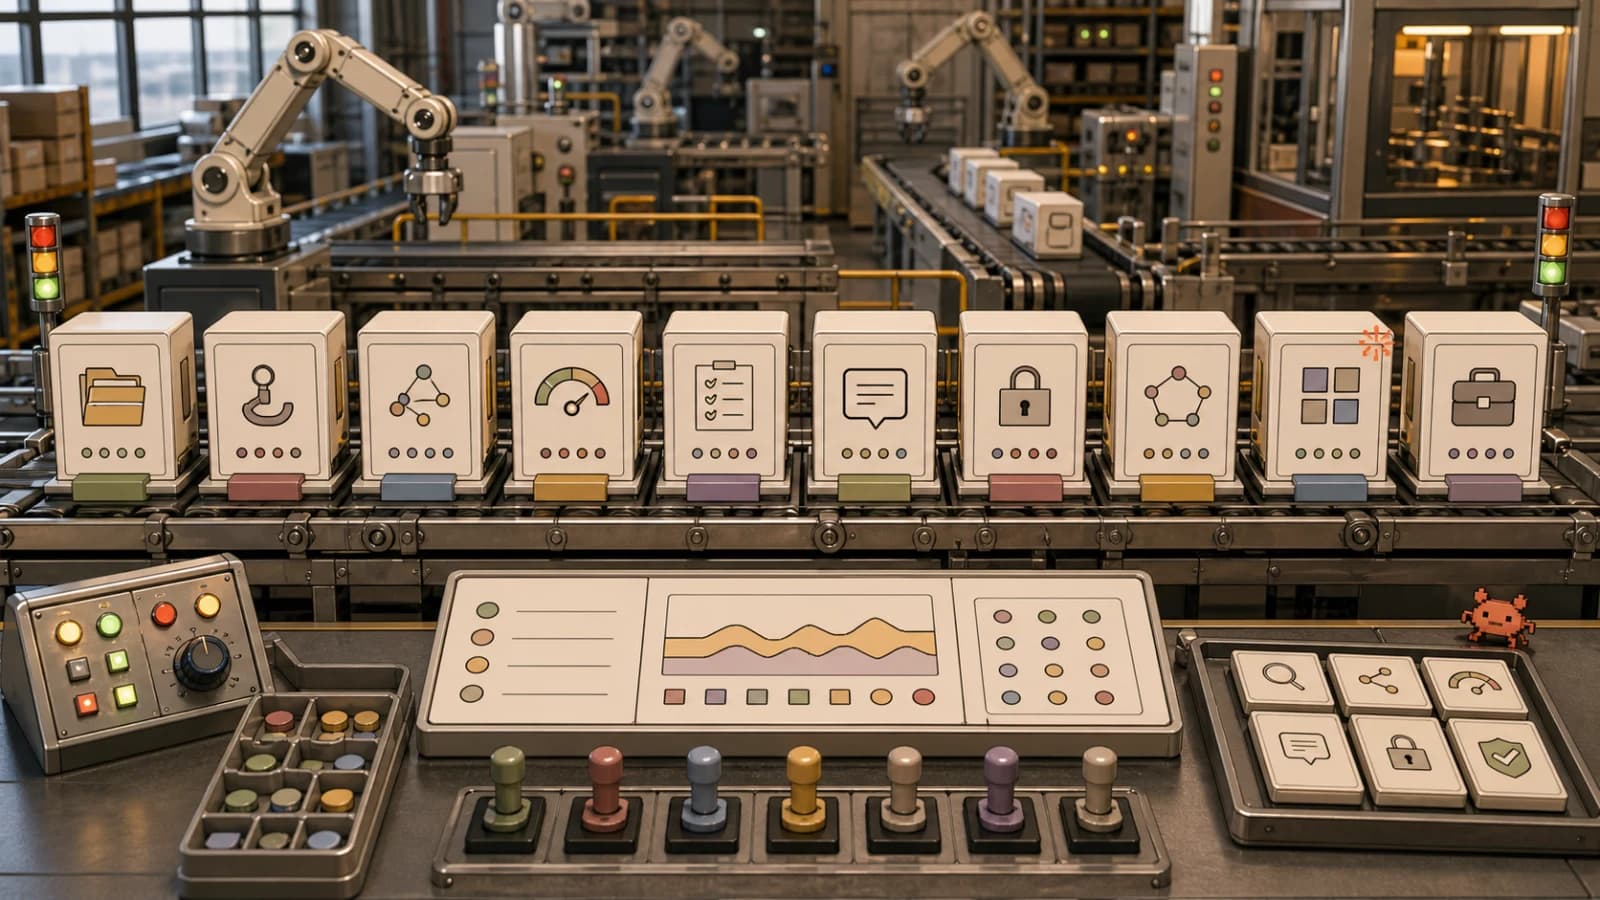
SkillForge CI, MCP Lens, TraceTrail, dd-ga, Cost Tape, Hookyard, Promptlock, dd-utm, Subagent Studio and Agent Eval Bench. They group into observability (MCP Lens, TraceTrail, Cost Tape), skills and hooks (SkillForge CI, Hookyard, Subagent Studio), prompts and evals (Promptlock, Agent Eval Bench), and portfolio infrastructure (dd-ga, dd-utm).
Are these tools publicly available?#
Not yet. All ten are private, at v0.1 or earlier, and none are production-ready. The plan is to use them internally for two weeks, open the four with tutorials first (Promptlock, TraceTrail, Hookyard and MCP Lens), and open the rest only when they earn it.
What does MCP Lens do?#
MCP Lens is a transparent proxy that sits between your MCP host and any MCP server. It captures every JSON-RPC frame in both directions to a JSONL log and serves a local inspector at localhost:4040, which makes stdio traffic visible when a tool call hangs or breaks.
How do Promptlock and Agent Eval Bench work together?#
Promptlock turns each prompt into a content-addressable artifact with a twelve-character ID, model, temperature, vars and note that you can commit, diff and roll back. Agent Eval Bench runs YAML test cases against a model and scores them with contains, regex or a judge prompt. Together they let a small team lock a prompt and then eval the lock to catch regressions before shipping.
Get the next deep dive like this in your inbox
One email a week on AI Agents and the rest of the AI dev stack. Free.
Read next on Claude Code
Six More Tools for the Agent Infrastructure Stack
The second half of our agent tooling release: distribution, validation, and ergonomics layered on top of the first six. Six small CLIs, one through-line.
9 min readClaude Code Agent Teams, Subagents, and MCP: The 2026 Playbook
Claude Code is turning into an orchestration layer for agent teams. Here is how subagents, MCP, hooks, and long context fit together in 2026.
9 min readGitHub Copilot Agent Finder: What ARD Means for Third-Party AI Tools in 2026
GitHub Copilot Agent Finder discovers and invokes MCP servers, skills and agents like Claude and Codex. How the open ARD spec changes AI tool integration.
8 min readTechnical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.