Topic
INFERENCE
All blog posts, tools, and guides about Inference from Developers Digest.
17 resources - 10 posts, 7 tools
Blog Posts
View in blog →
GLM-5.3 on Workers AI Leaked Other Users' Prompts: SGLang Fix List
Cloudflare's GLM-5.3 Workers AI endpoint returned other customers' data in 155 long-prompt responses. What broke in SGLang, the upgrade and config checklist, and what API users should ask.
8 min read
DeepInfer: What DeepSeek Open-Sourced and What You Can Run
DeepSeek open-sourced DeepInfer, the inference engine behind its API. It is offline-only, V4.1-Flash-only and Blackwell-or-Ascend-only. What it is, what is missing, and who benefits.
7 min read
Magnitude: A Self-Tuning Inference Engine Bids to Be Your Agent's Local Backend
Magnitude is an Apache-2.0 inference engine that tunes kernels on your hardware and plugs into OpenCode, Codex and Claude Code. What shipped, where it breaks.
6 min read
Cloudflare Runs Kimi and GLM at Scale: FP8 KV Caches, INT4 Weights, and a Cache Safety Net
Cloudflare runs Kimi K2.6 and GLM 5.2 on Workers AI with FP8 KV caches, INT4 weights and a KV cache integrity check. What each technique buys on GPU fleets.
7 min read
AMD MI355X vs NVIDIA B200 vs B300 for Open-Weight Serving
AMD MI355X vs NVIDIA B200 vs B300 for serving Kimi K3's about 1.5TB of open weights: verified specs, the Wafer benchmark, and cost per token for each.
9 min read
Echo Claims Fable-Level Results at One-Third the Cost Using Open-Weight Models
A new multi-model orchestration system routes requests across open-weight models to match frontier performance at reduced inference cost. Here is what we know.
7 min read
vLLM vs TGI vs SGLang: Which Inference Server to Self-Host
A fair comparison of vLLM, TGI, SGLang, TensorRT-LLM, llama.cpp, and LMDeploy for self-hosted LLM inference - batching, quantization, hardware, and ops.
7 min read
Cerebras Stock Is a Public Test of AI Inference Demand
CBRS stock trended after Cerebras' first public earnings. What public-market scrutiny of fast AI inference means for developers - not investment advice.
7 min read
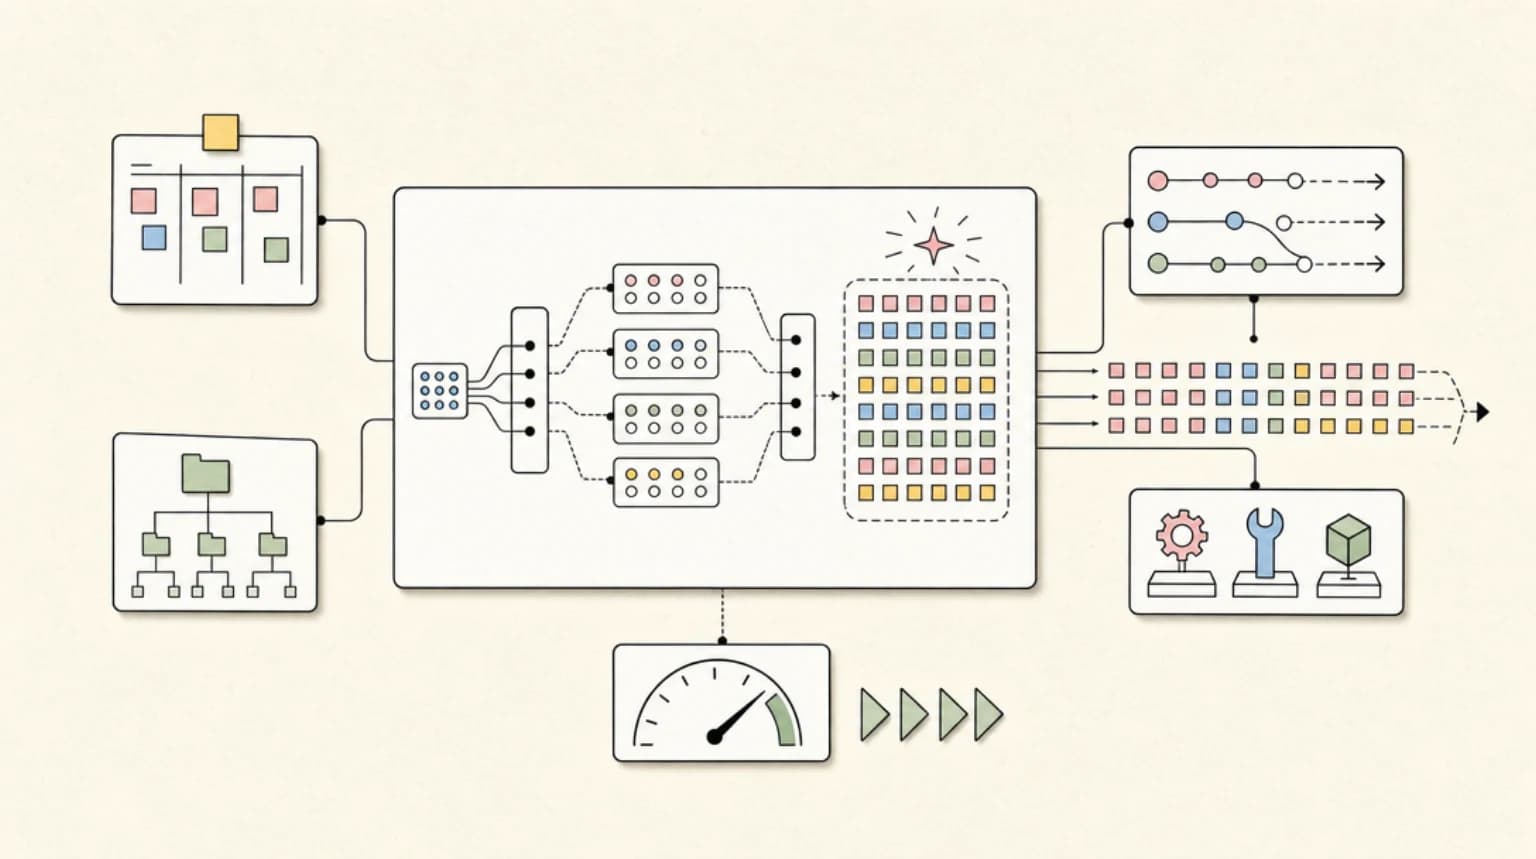
DiffusionGemma: Google Bets Diffusion Can Make Text Generation 4x Faster
DiffusionGemma is Google's 26B MoE open model that generates 256-token blocks in parallel. What diffusion generation means for latency and local inference.
8 min read
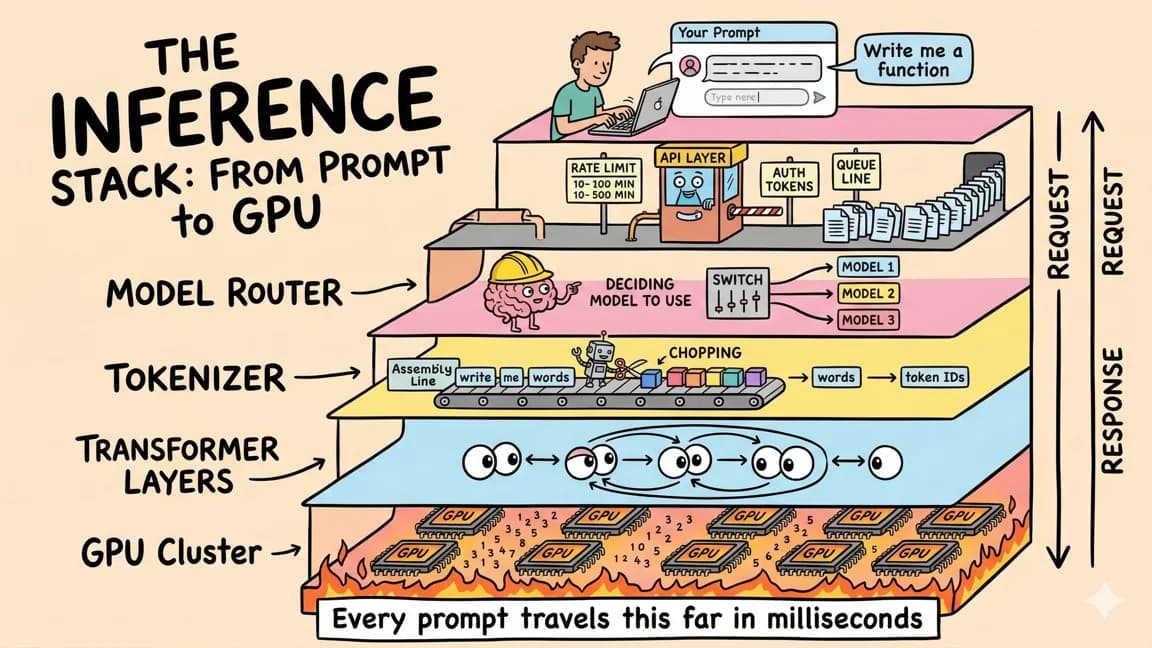
KV Caching: A Practical Guide to Optimizing Transformer Inference
How KV caching speeds up LLM inference - the math, the code, the memory tradeoffs, and when it stops helping. Every dev running local models hits this wall.
11 min read
Related Tools
All tools →Replicate
Run 50,000+ ML models with a simple API. No infrastructure management. Pay-per-second billing. Deploy custom models with Cog. Popular for image generation and audio.
InfrastructureTogether AI
Fastest inference for open-source models. 200+ models via unified API. Ranks #1 on speed benchmarks for DeepSeek, Qwen, Kimi, and Llama. Serverless pay-per-token pricing.
InfrastructureGroq
LPU-powered inference at about 500 to 1,000 tokens/sec on GPT OSS models. Purpose-built chip with on-chip SRAM instead of HBM. OpenAI-compatible API. Free tier available.
InfrastructureCerebras
Wafer-scale AI inference at 3,000+ tokens/sec. The WSE-3 chip has 4 trillion transistors and 900K AI cores. 20x faster than GPU providers. OpenAI partnership for inference.
Infrastructurellama.cpp
C++ inference engine for LLMs. GGUF format, quantization, CPU and Metal/CUDA support. The foundation most local tools build on.
Local AIvLLM
High-throughput inference server for LLMs. PagedAttention memory management. The go-to for serious local or self-hosted serving.
Local AIMLX
Apple's array framework for machine learning on Apple Silicon. Native Metal support, unified memory, first-class LLM inference.
Local AIKeep exploring
More on Inference
- - Replicate - recommended Inference tool from the Developers Digest directory
- - Compare Tools - dive deeper across the Developers Digest knowledge base
- - All Inference articles in the blog archive
- - Developers Digest on YouTube - video tutorials covering Inference and more
Get Smarter About AI Dev
New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
One email per weekReal code, not theoryFree forever
Explore 844 topics
Browse All Topics