Topic
LLM
Large language models - architecture, capabilities, and how to pick the right one for the job.
35 resources - 26 posts, 9 tools
Blog Posts
View in blog →
Agent Memory Architectures Explained: 5 Layers and How Each Framework Builds Them
Agent memory is five layers: history, compaction, semantic recall, working memory and files. How Mastra, LangGraph, OpenAI and Claude implement each.
12 min read
ACE vs ALTK-Evolve: How You Deliver Agent Memory Determines the Token Bill
ACE vs ALTK-Evolve for agent memory: both turn trajectories into lessons, but calibrated delivery matches accuracy on AppWorld at a fraction of the tokens.
7 min read
DCAS: Why Fine-Tuned Coding Agents Fall Apart When You Switch Scaffolds
Fine-tuned coding agents collapse when you switch scaffolds, from 52.6% to 8.4% on SWE-bench Verified. DCAS shows how to train planning into the model.
8 min read
OpenJDK Bans AI-Generated Code: What the New Policy Means for Java Contributors
OpenJDK's interim AI policy bans code generated in full or in part by LLMs. What it still allows, how it is enforced, and what it means for Java contributors.
8 min read
SkillSV: A Shapley Framework That Values the Lines Inside an Agent Skill
SkillSV is a Shapley framework that values the rules, examples and scripts inside an agent skill, cutting skills to 69% of tokens without significant loss.
8 min read
SIGIL Compiles Agent Skills into Harnesses: Prose Runs Skip 44% of Mandated Steps
SIGIL compiles prose SKILL.md files into typed agent harnesses. Prose runs execute 56% of mandated steps; compiled harnesses reach 86% with 0.58x the tokens.
8 min read
The Underground Relay Market for AI API Tokens: How Resellers Get 97% Off
AI API token relays resell OpenAI, Anthropic, and Google access at up to 97.8% off. How the gray market works and what it means for developers on AI APIs.
9 min read
Debian Debates LLM Usage: Four Proposals, One Fork in the Road
Debian LLM policy debate: four proposals on AI-generated contributions, from an outright ban to full acceptance, and the fault lines in the HN discussion.
9 min read
Running Gemma 4 26B at 5 Tokens/Sec on a 13-Year-Old Xeon With No GPU
Gemma 4 26B on a 2013 Xeon with no GPU: how a sub-$300 box reached about 5 tokens/sec, the silent MoE bug behind the gibberish, and the upstream fix.
6 min read
Mesh LLM: Run 235B Models Across Your Home Lab with iroh
Mesh LLM pools GPUs across home lab machines behind one OpenAI-compatible API, splitting 235B models over iroh and QUIC with no RDMA or NVLink required.
6 min read
Self-Hosted vs Managed AI Gateways: A Decision Guide
Self-host LiteLLM or Kong, or use a managed gateway like Portkey, OpenRouter, or Cloudflare AI Gateway? A factual breakdown of cost, control, and ops tradeoffs.
11 min read
Program-as-Weights Turns Prompts Into Local Fuzzy Functions
Program-as-Weights compiles prompts into compact local adapters that act as fuzzy functions. What the paper claims and where developers could use it first.
7 min read
The One-Cent Attack: Prompt Injection Through Bank Transfer Memos
Prompt injection through a bank transfer memo: how a €0.02 transfer compromised a banking AI assistant, and the five defense layers agent builders need.
8 min read
Mastra: Review and Setup Guide for TypeScript Agent Apps (2026)
Mastra review and setup for TypeScript AI agents - verified create commands, Mastra Studio, workflows and memory, plus pricing and who should skip it.
8 min read
OpenRouter in 2026: Review, Setup, and When Model Routing Pays
OpenRouter review and setup - one API key for 300+ models with fallbacks and provider routing, what it costs, and when to go direct to a provider instead.
8 min read
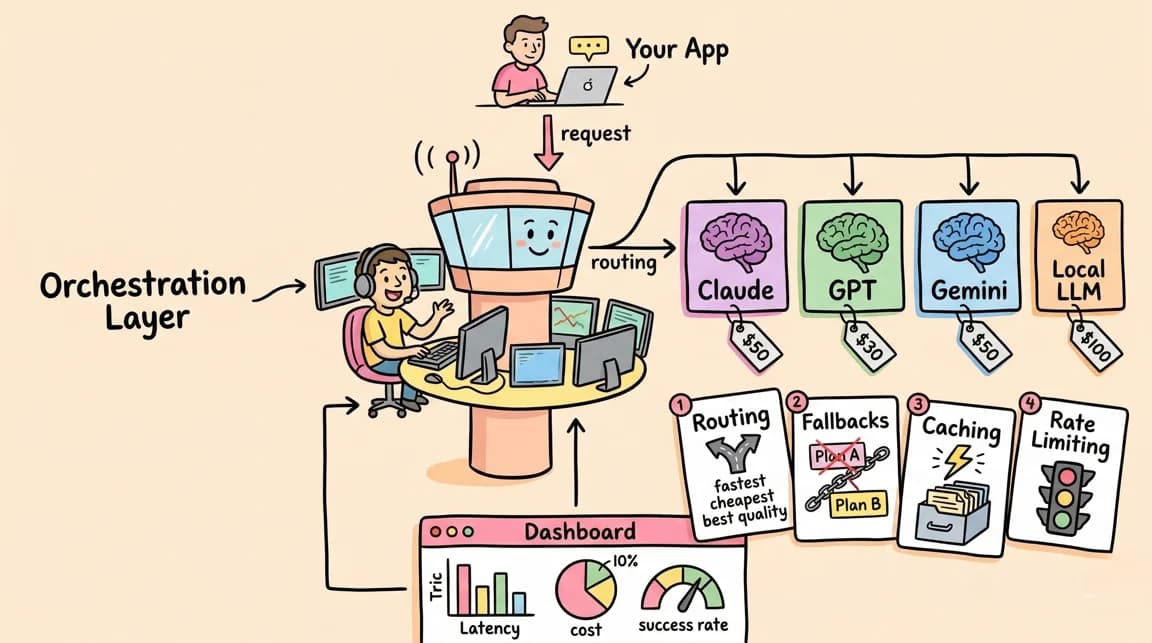
LLM Routers Compared: LiteLLM vs Portkey vs OpenRouter in 2026
LiteLLM vs Portkey vs OpenRouter compared for production AI apps: cost tracking, fallbacks, caching, and load balancing, plus when to use each router.
10 min read
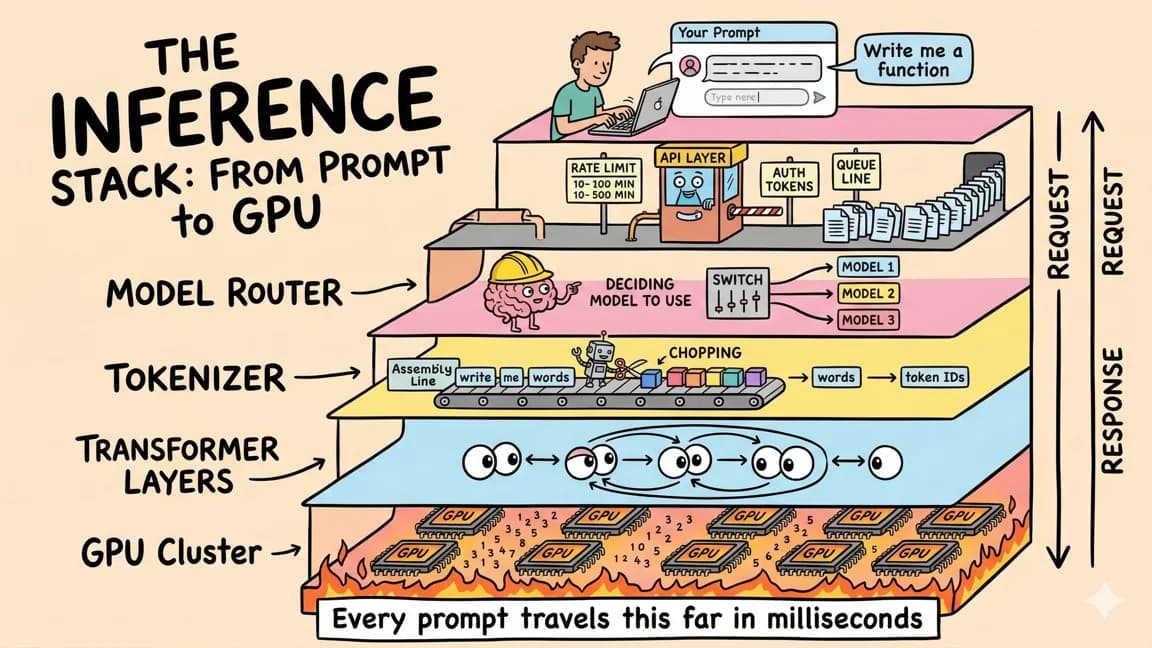
KV Caching: A Practical Guide to Optimizing Transformer Inference
How KV caching speeds up LLM inference - the math, the code, the memory tradeoffs, and when it stops helping. Every dev running local models hits this wall.
11 min read
Mercury 2 Developer Guide: Building With a Diffusion LLM in Production
Mercury 2 developer guide: the OpenAI-compatible API, tool use, structured outputs, reasoning levels, and when a diffusion LLM beats an autoregressive one.
10 min read
Promptlock: Deterministic Prompt Versioning for LLM Apps
Promptlock gives every prompt a 12-char content-addressable id and a diff-able artifact, turning silent prompt drift into a reviewable change.
7 min read
Mercury 2: The LLM That Doesn't Generate Like an LLM
Mercury 2 from Inception Labs is a diffusion reasoning LLM that refines outputs in parallel at over 1,000 tokens per second. How it works and where it fits.
8 min read
Claude Skills: A technical deep dive into Anthropic's new approach to AI context management
Claude Skills load instructions, scripts and resources progressively so context stays small. A technical deep dive into SKILL.md, the API and Claude Code use.
8 min read
GPT-5: OpenAI's Most Capable Model
GPT-5 routes each query by complexity instead of making developers pick a reasoning mode. Its benchmarks, front-end coding gains and four API models explained.
7 min read
Diffusion Language Models: How Mercury Changed the LLM Speed Game
Diffusion language models like Inception Labs' Mercury draft a whole response and refine it instead of going token by token. See why that makes them so fast.
7 min read
Unstract: Open-Source AI Document Parsing at Scale
Unstract is an open-source, no-code platform that uses LLMs to extract structured JSON from PDFs, invoices and scans. How Prompt Studio and self-hosting work.
10 min read
Microsoft PHI-4: A 14B Parameter Model That Rivals Models 5x Its Size
Microsoft PHI-4 is an MIT-licensed 14B model that matches Llama 3.3 70B on key benchmarks. See its specs, how to run it locally with Ollama, and when to use it.
9 min read
Llama 3.3 70B: Meta's Cost-Effective Frontier Model
Llama 3.3 70B delivers 405B-class performance at a fraction of the cost. See the benchmarks, pricing versus GPT-4o, where to run it, and when to pick it.
8 min read
Related Tools
All tools →Ollama
The easiest way to run LLMs locally. One command to pull and run any model. OpenAI-compatible API. 52M+ monthly downloads. Supports GGUF, Safetensors, and custom Modelfiles.
Local AILM Studio
Desktop app for discovering, downloading, and running local LLMs. Clean chat UI, OpenAI-compatible API server, and automatic GPU detection. MLX engine optimized for Apple Silicon.
Local AIJan
Open-source ChatGPT alternative that runs models fully offline. Desktop app with local models, cloud API connections, custom assistants, and MCP integration. Apache 2.0 licensed.
Local AIGPT4All
Private local AI chatbot by Nomic. MIT licensed with 77K+ GitHub stars. LocalDocs lets you chat with your own files. Runs on Windows, macOS, and Linux; latest release is v3.10.0 from February 2025.
Local AILocalAI
Open-source OpenAI API replacement. Runs LLMs, vision, voice, image, and video models on any hardware, no GPU required. 60+ backends. Distributed mode for scaling.
Local AIvLLM
High-throughput inference server for LLMs. PagedAttention memory management. The go-to for serious local or self-hosted serving.
Local AIBrowser Harness
Self-healing browser automation harness that lets LLMs complete any browser task. 5,000+ stars in under a week.
InfrastructureLiteLLM
Open sourceOpen-source AI gateway: call 100+ LLM providers in the OpenAI format via a Python SDK or proxy. Spend tracking, budgets, rate limiting, load balancing, and fallbacks built in.
AI FrameworksLangfuse
Open sourceOpen-source LLM engineering platform: tracing, evals, prompt management, and datasets. Self-hostable, OpenTelemetry-native, with 50+ framework integrations.
InfrastructureKeep exploring
More on LLM
- - Ollama - recommended LLM tool from the Developers Digest directory
- - Compare Tools - dive deeper across the Developers Digest knowledge base
- - All LLM articles in the blog archive
- - Developers Digest on YouTube - video tutorials covering LLM and more
Get Smarter About AI Dev
New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
One email per weekReal code, not theoryFree forever
Explore 848 topics
Browse All Topics