Topic
LOCAL MODELS
All blog posts, tools, and guides about Local Models from Developers Digest.
16 resources - 15 posts, 1 tool
Blog Posts
View in blog →
How much VRAM do you need to run a local LLM in 2026?
How much VRAM a local LLM needs: Q4 weights are about 30% of BF16, plus a KV cache that grows per token. Real numbers from 8 GB to 256 GB.
13 min read
Local LLM Speed by Hardware: What llmspeed Gets Right
llmspeed estimates tokens per second for 30 machines and 15 models. What its numbers mean, the memory-bandwidth rule behind them, and why prefill matters for coding agents.
7 min read
Ollama Decision Models: Run Nimble Locally with --ask
Ollama 0.40.4 runs decision models locally: ollama run nimble --ask answers yes/no, label and score questions with probabilities. Commands and limits.
7 min read
Anthropic Self-Replicating AI Research: What Small Models Can Actually Do
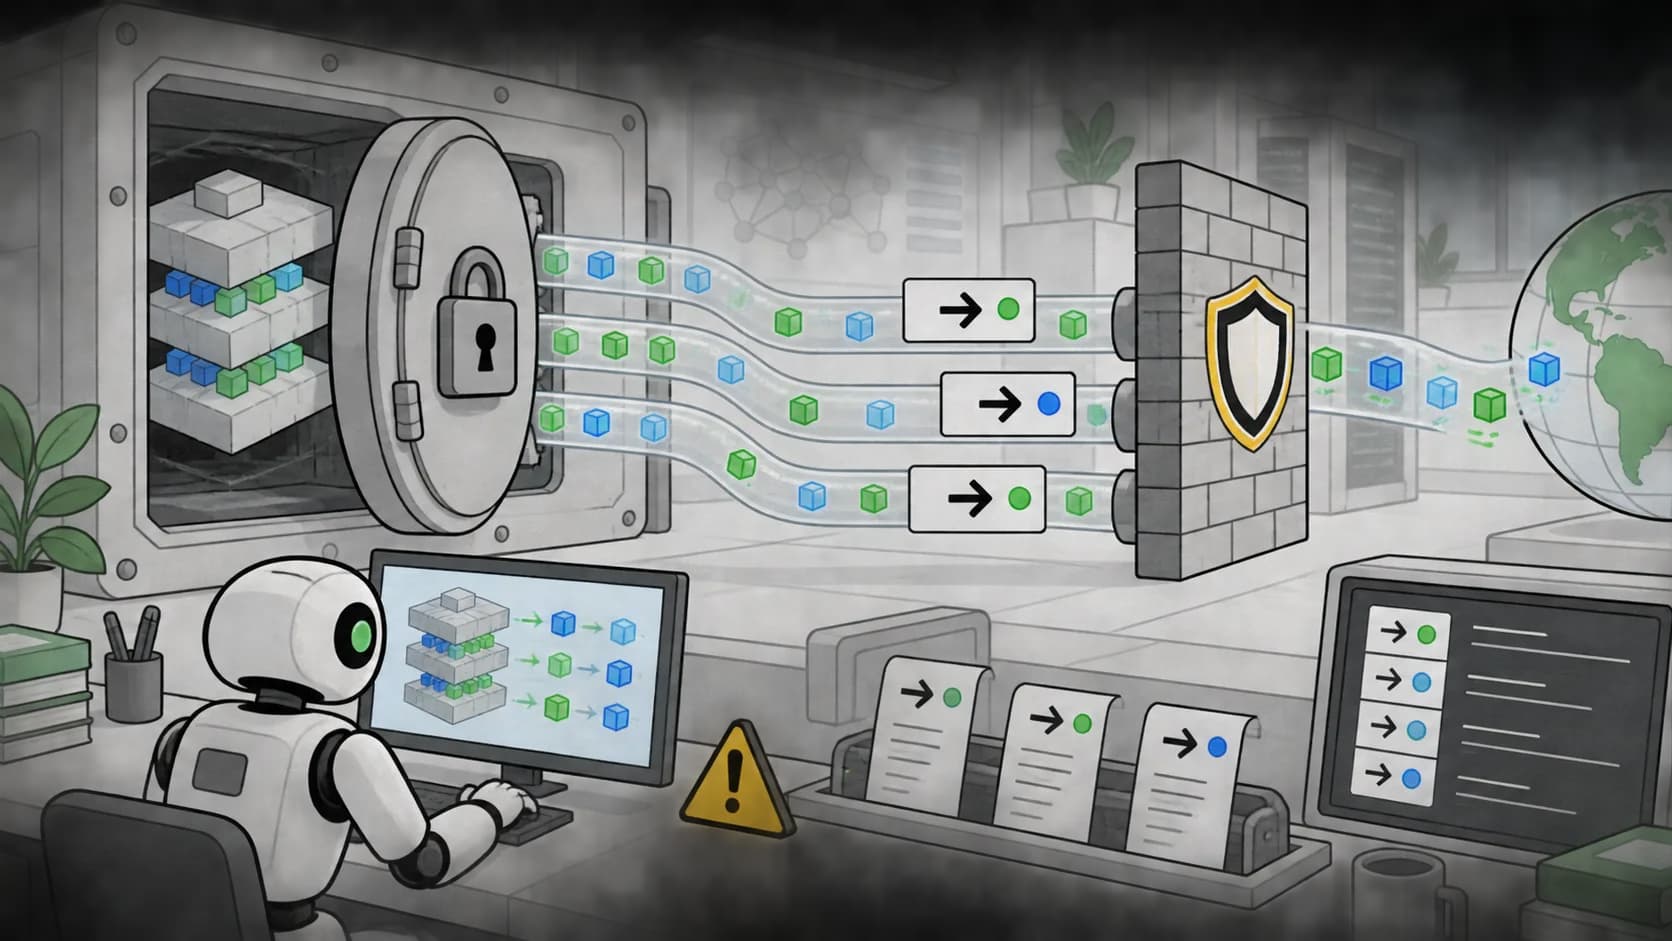
Anthropic's Frontier Red Team says small open models may be months from self-replicating across cheap IoT devices. What it measured and where the claim is thin.
7 min read
RTX Spark for Local LLMs: Will It Run a Coding Agent?
RTX Spark laptops ship October 16 with up to 128 GB of unified memory. Why the 600 GB/s figure is not memory bandwidth and which local coding models fit.
8 min read
How to Run Kolibri Locally: GGUF, MLX and Hardware Picks
Kolibri 1 runs locally from 28.6 GB (Q2_K) to 83.1 GB (Q8_0). Which quant fits your RAM or Mac, measured speeds, and why Ollama cannot load it yet.
10 min read
Run Qwen3.8-Flash-Next on a Gaming PC With Strata
Run Qwen3.8-Flash-Next locally with Strata on a 12 GB GPU: hardware needs, speeds by quant, the license catch, and when the hosted API is the better call.
8 min read
Jeff: Jev-Style Decision Models Trained at Home on One GPU
Jeff fine-tunes Qwen3.5 and Gemma 4 into small Jev-compatible decision models on one GPU. The numbers, run commands, and where the benchmark misses real work.
6 min read
Qwen3.8-27B vs Opus 4.6 Max: Local Agentic Coding Benchmarks
Qwen3.8-27B is a 27B dense Apache-2.0 model that beats Opus 4.6 Max on SWE-bench Pro (61.7 vs 53.4). Benchmarks, hardware, cost and when to run it.
10 min read
Ornith-1.0: What an Open Source Self-Improving Coding Model Actually Means
Ornith-1.0 open-source coding models explained: what "self-improving" really means, the four model sizes, hardware needs, HN reactions and whether to try it.
7 min read
Mellum2 Developer Guide: JetBrains' Open-Source Coding Model
Mellum2 developer guide: JetBrains' open-source 12B MoE coding model with 2.5B active parameters. How to run it locally and where it fits in your coding stack.
7 min read
Forge Shows the Local Agent Reliability Gap Is a Harness Problem
Forge makes small local models more reliable at tool-calling with a harness that catches structural failures, retries intelligently and controls context.
7 min read
Free Claude Code Is Really a Model Gateway Bet
The trending Free Claude Code repo is not just about avoiding API bills. It points at a bigger developer-tool pattern: model gateways for AI coding agents.
7 min read
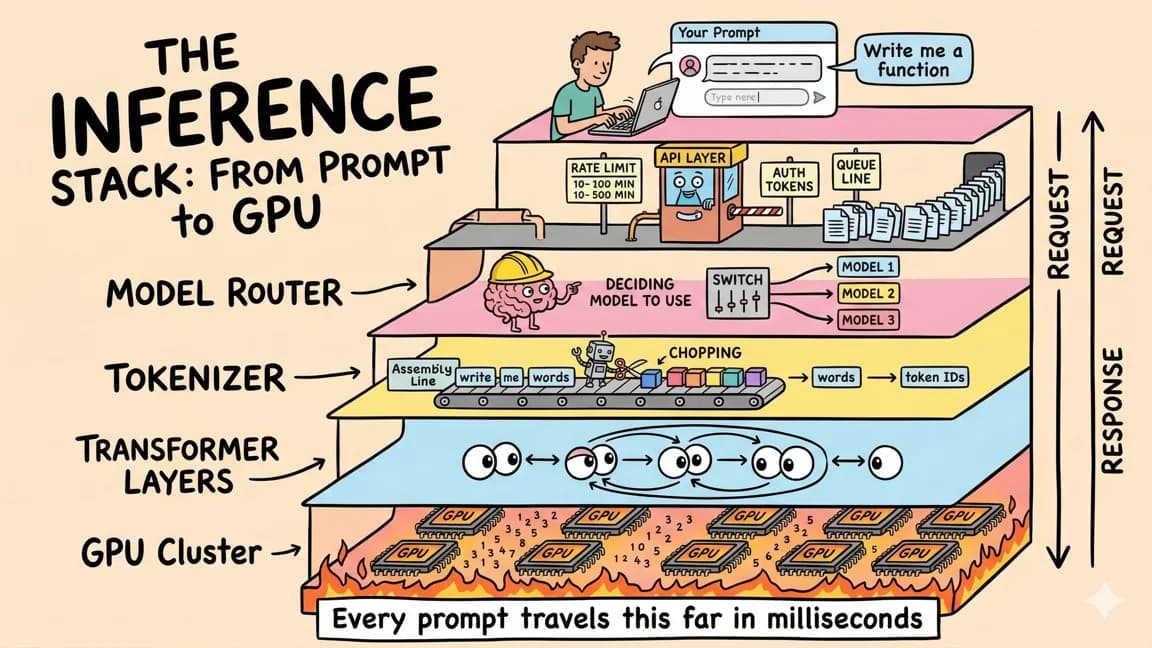
KV Caching: A Practical Guide to Optimizing Transformer Inference
How KV caching speeds up LLM inference - the math, the code, the memory tradeoffs, and when it stops helping. Every dev running local models hits this wall.
11 min read
Qwen3.6-27B Is the Local Coding Model to Test First
Qwen3.6-27B is the local coding model to benchmark first: what hardware it needs, which jobs it should take over, and where a frontier API still wins.
8 min read
Keep exploring
More on Local Models
- - Continue.dev - recommended Local Models tool from the Developers Digest directory
- - Compare Tools - dive deeper across the Developers Digest knowledge base
- - All Local Models articles in the blog archive
- - Developers Digest on YouTube - video tutorials covering Local Models and more

Get Smarter About AI Dev
New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
One email per weekReal code, not theoryFree forever
Explore 840 topics
Browse All Topics