Run Qwen3.8-Flash-Next on a Gaming PC With Strata
TL;DR
Strata runs the 125B Qwen3.8-Flash-Next on a 12 GB GPU with 64 GB of RAM at up to 94 tokens per second. Hardware needs, speeds by quant, the license catch, and when the $0.15 hosted API is the better call.
Strata, a free MIT-licensed program, runs Qwen's 125-billion-parameter Qwen3.8-Flash-Next on a normal gaming PC: an NVIDIA or AMD card with 12 GB of VRAM or more, 32 GB of RAM or more, and about 80 GB of disk. Its own measurements on an RTX 5070 (12 GB) with 64 GB of RAM range from 94 tokens per second for writing answers at the smallest quantization to 53 at the largest of the standard sizes. It reached the Hacker News front page on October 4. Below: what you need, which size to pick, how to point Claude Code or Codex at it, and where it breaks.
Last updated: October 4, 2026. We have not run Strata ourselves. Every speed below is the Strata author's measurement or a Hacker News commenter's report, and the benchmark scores are Qwen's own.
What the model is#
Qwen3.8-Flash-Next is an open-weight mixture-of-experts model from the Qwen team, published on Hugging Face in late August. The model card lists:
- 125B parameters with 6B activated per token, plus a 51B n-gram embedding and a 4B multi-token-prediction head.
- 48 layers, 512 experts per layer with 10 routed and 1 shared active, and a vision encoder.
- A 262,144-token native context, extensible to 1 million tokens with YaRN.
- A new hybrid attention design the card calls a preview of the architecture behind Qwen4.
Qwen's own benchmark table, which is vendor-reported, has it at 62.5 on SWE-bench Pro and 58.7 on DeepSWE 1.1, ahead of Qwen3.8-27B (61.7 and 42.2) and DeepSeek-V4-Flash-0731 (56.0 and 54.4). DeepSeek wins one coding row, NL2Repo-Bench, at 54.2 against 48.1. The model also lists 73.5 on Toolathlon and 91.7 on GPQA Diamond. Treat all of it as marketing until someone reproduces it. For the smaller dense sibling that fits one consumer GPU, see our Qwen3.8-27B local coding guide.
What Strata does#
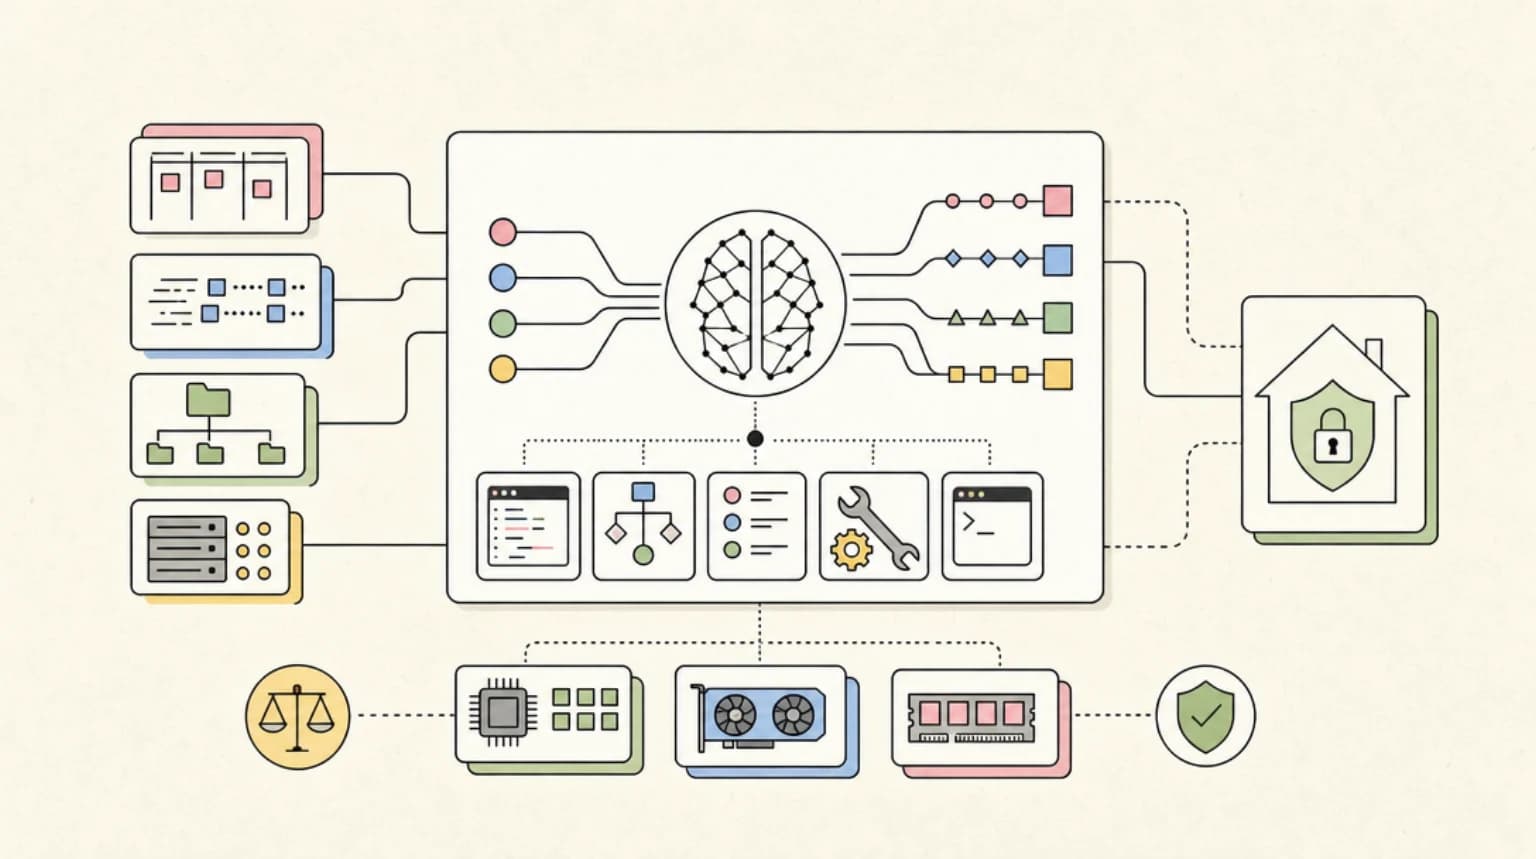
Strata is an installer and engine built on parts of llama.cpp. Its README says it makes a model this large fit a consumer PC by spreading the work: the most-used experts stay on the graphics card, all experts live in system RAM, and the processor works on the rest at the same time. It also uses a small draft model to guess ahead and verifies the guesses in one pass, which the README says gives the same answers 1.6 to 1.8 times sooner.
Requirements from the README:
| Part | Needs |
|---|---|
| Graphics card | NVIDIA RTX 20, 30, 40 or 50 series, or a supported AMD Radeon, with 12 GB of VRAM or more |
| RAM | 32 GB or more; your RAM decides which size fits |
| Disk | About 80 GB free, SSD recommended |
| System | Windows 10 or 11, or Linux |
How fast, and which size to pick#
The README's own measurements, writing a 4K-token answer and reading a 32K-token prompt:
| Quant (RTX 5070, 12 GB, 64 GB RAM) | Writes answers | Reads your prompt |
|---|---|---|
| Q2_0 | 94 tokens/s | 2,650 tokens/s |
| IQ2_XS | 79 tokens/s | 2,090 tokens/s |
| IQ3_XXS | 62 tokens/s | 1,750 tokens/s |
| IQ3_S | 53 tokens/s | 1,620 tokens/s |
| Coder | 55 tokens/s | 2,180 tokens/s |
On an AMD RX 9070 XT (16 GB, 47 GB RAM) the same table reads 60, 52 and 44 tokens per second for Q2_0, IQ2_XS and the Coder build. The author estimates an RTX 3090 would write about 100 to 140 tokens per second. In the Hacker News thread, one commenter reported 124 tokens per second on an RTX 4090 with 128 GB of DDR5, which fits that range but is a single unverified report.
The README's picks by RAM:
- 32 GB: the Coder build, a coding variant with half of the experts removed. Its authors say it reaches 91% of the full model's SWE-bench Verified score, and the README warns it is weaker outside code, including Chinese and other CJK text.
- 48 GB: IQ2_XS, or Q2_0 if you want the fastest.
- 64 GB: IQ2_XS is recommended; every size fits.
- 96 GB or more: IQ3_S, or Unsloth's roughly 4-bit UD-IQ4_XS.
Closer-to-full-quality builds exist but pay for it: the README says Unsloth's UD-Q4_K_XL reads most of its weights from the SSD while answering and writes only 7 to 8.5 tokens per second on a 64 GB PC.
Point your coding agent at it#
Strata serves an OpenAI-compatible endpoint at http://127.0.0.1:8080/v1, with any API key and any model name accepted. According to the README it also serves the Anthropic Messages API, so Claude Code works with ANTHROPIC_BASE_URL=http://127.0.0.1:8080, and Codex CLI works through the Responses API at /v1/responses. A reasoning setting of off, low, medium or high is exposed in the chat menu and as your app's reasoning effort. If you already use a local model in a coding agent, this slots in the same way as in our best local coding LLMs roundup.
Where it breaks#
- Quality at 2-bit. The loudest Hacker News objection is quantization. Commenters call Q2 a poor trade and note that the Coder build, with half its experts removed, will not hold up on long-horizon coding that depends on reasoning. One asks for benchmarks on the quantized builds, which the README does not publish. The "Qwen3.8-Flash-Next beats Opus 4.6 on SWE-bench Pro" numbers above are for the full-precision model, not what you run at Q2.
- The first start can freeze the PC. The README says the machine may be slow or stop responding for one to three minutes while 35 to 55 GB loads into RAM, and a 70 GB download comes first.
- Slow first prompt. It reads the first message of a chat at roughly one minute per 30,000 tokens, with follow-ups starting in seconds. One commenter asked for prompt-processing speed at 16K context, which is the number that matters for coding agents.
- One request at a time by default. Extra requests queue unless you set
"parallel": 2, which the README says makes each answer slower on a 12 GB card. - A paste-this-into-your-AI install. The README offers a prompt that tells your coding assistant to follow a setup doc in the repository, and a commenter immediately compared it to piping a script into bash. Read
docs/AI_SETUP.mdand the installer yourself before you let an agent run them.
Local or hosted?#
Qwen's own hosted model, Qwen3.8-Flash on Qwen Cloud, is described as the official production version of Flash-Next with a 1M-token context and built-in tools. The listed price, checked on October 4, is $0.15 per million input tokens and $0.47 per million output tokens, with cached input at $0.016. That is within a cent of GLM-5.3-Flash's first-party price in our GLM-5.3 access guide.
| Choose | When |
|---|---|
| Strata, local | Your code cannot leave the machine, you already own a 12 GB or larger card and 64 GB of RAM, or you want an offline fallback |
| Qwen Cloud, hosted | You need the full-precision model, steady long-context agent runs, or several requests at once |
| A smaller local model | You have 8 to 16 GB of RAM total, which is the commenter objection that most of this hardware is out of reach |
One license point if you build a product on it: the model ships under the Qwen Community License 1.0, not Apache or MIT. Its text says a licensee that runs a "Model as a Service" or "AI Work Assistant" business must get a separate license from Qwen first. Strata's MIT license covers the engine, not the model weights. Read the license file before you ship anything on top of it.
FAQ#
Can I run a 125B model on an RTX 4090?#
According to Strata's README, yes: it needs a 12 GB or larger NVIDIA or AMD card plus 32 GB or more of system RAM, and it runs the model by keeping the busiest experts on the card and the rest in RAM. The author estimates 100 to 140 tokens per second on a 24 GB RTX 3090, and one Hacker News commenter reports 124 on a 4090 with 128 GB of RAM.
How much RAM do I need for Qwen3.8-Flash-Next?#
The README recommends 32 GB for the Coder build, 48 GB for IQ2_XS or Q2_0, 64 GB for IQ2_XS as the sweet spot, and 96 GB or more for the larger sizes.
Does it work with Claude Code?#
Strata serves an Anthropic-compatible endpoint, and the README gives ANTHROPIC_BASE_URL=http://127.0.0.1:8080 for Claude Code. We have not tested it ourselves. Our Claude Code permissions guide covers keeping an agent on a short leash.
Is Qwen3.8-Flash-Next free to use commercially?#
The weights are free to download, but the Qwen Community License 1.0 requires a separate license from Qwen if you run a hosted model service or a coding or office assistant product on it. Strata itself is MIT licensed.
Continue Reading#
- Qwen3.8-27B for Local Agentic Coding - the dense 27B sibling that fits a single consumer GPU
- The Best Local Coding LLMs of 2026 - where the local options stack up
- Qwen 3.8 Max Release Guide - the hosted flagship from the same team
- Where to Run GLM-5.3 Free and Cheap - the closest hosted price comparison
- Budget AI Coding Models Compared - cost per task for the cheap tier
Sources#
| Source | URL |
|---|---|
| Strata README (speeds, requirements, model picks), fetched October 4, 2026 | https://github.com/Niko1221/Strata |
| Qwen3.8-Flash-Next model card, fetched October 4, 2026 | https://huggingface.co/Qwen/Qwen3.8-Flash-Next |
| Qwen Community License 1.0 (model license text) | https://huggingface.co/Qwen/Qwen3.8-Flash-Next/raw/main/LICENSE |
| Qwen3.8-Flash on Qwen Cloud, pricing checked October 4, 2026 | https://www.qwencloud.com/models/qwen3.8-flash |
| Hacker News discussion, read October 4, 2026 | https://news.ycombinator.com/item?id=49953495 |
Get the next deep dive like this in your inbox
One email a week on Qwen and the rest of the AI dev stack. Free.
Read next on local and open-weight models
Qwen3.8-27B vs Opus 4.6 Max: The Laptop-Sized Model That Beat a Frontier Flagship on Agentic Benchmarks
Qwen3.8-27B is a 27B dense Apache-2.0 model that scores 61.7 on SWE-bench Pro and 42.2 on DeepSWE 1.1 - ahead of Opus 4.6 Max on both - while running on consumer hardware. Benchmarks, hardware math, and an honest when-to-use-it guide.
10 min readThe Best Local Coding LLMs in 2026: Run Enterprise-Grade AI Without the Cloud
Choosing a local coding LLM in 2026 means balancing benchmark performance, hardware cost, and the compliance pressure to keep code off third-party servers. Here is what to run and on what hardware.
8 min readQwen 3.8 Max Ships: 2.4T MoE, 1M Context, $2/$6 per MTok, Open Weights Next Week
Alibaba released Qwen 3.8 Max on August 3, 2026 - a 2.4T-parameter MoE with 95B active per token, a 1M context window, and $2/$6 per million tokens on QwenCloud. It leads PaperBench at 93.0, and the weights open next week.
8 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.