Speed Up a Local LLM: The Agent Skill That Computes the Ceiling First
TL;DR
A new open-source agent skill hill-climbs local LLM serving speed. Its method - ceiling first, one change at a time, interleaved controls - is worth stealing even if you never install it.
Last updated: November 17, 2026
If you want to speed up a local LLM, the hard part is not finding flags - it is knowing whether a change helped. A new open-source agent skill, inference-optimisation, packages a method for that: compute the theoretical ceiling first, change one thing at a time, and accept a win only if it beats control runs on both sides. It reached roughly 588 GitHub stars within a day of its first commit, and the method is useful whether or not you install it.
Everything below comes from the repository's README, SKILL.md, levers.md and methodology.md, which we read on November 17, 2026. The speedups are the authors' own numbers on their hardware. We have not reproduced any of them.
What the skill is#
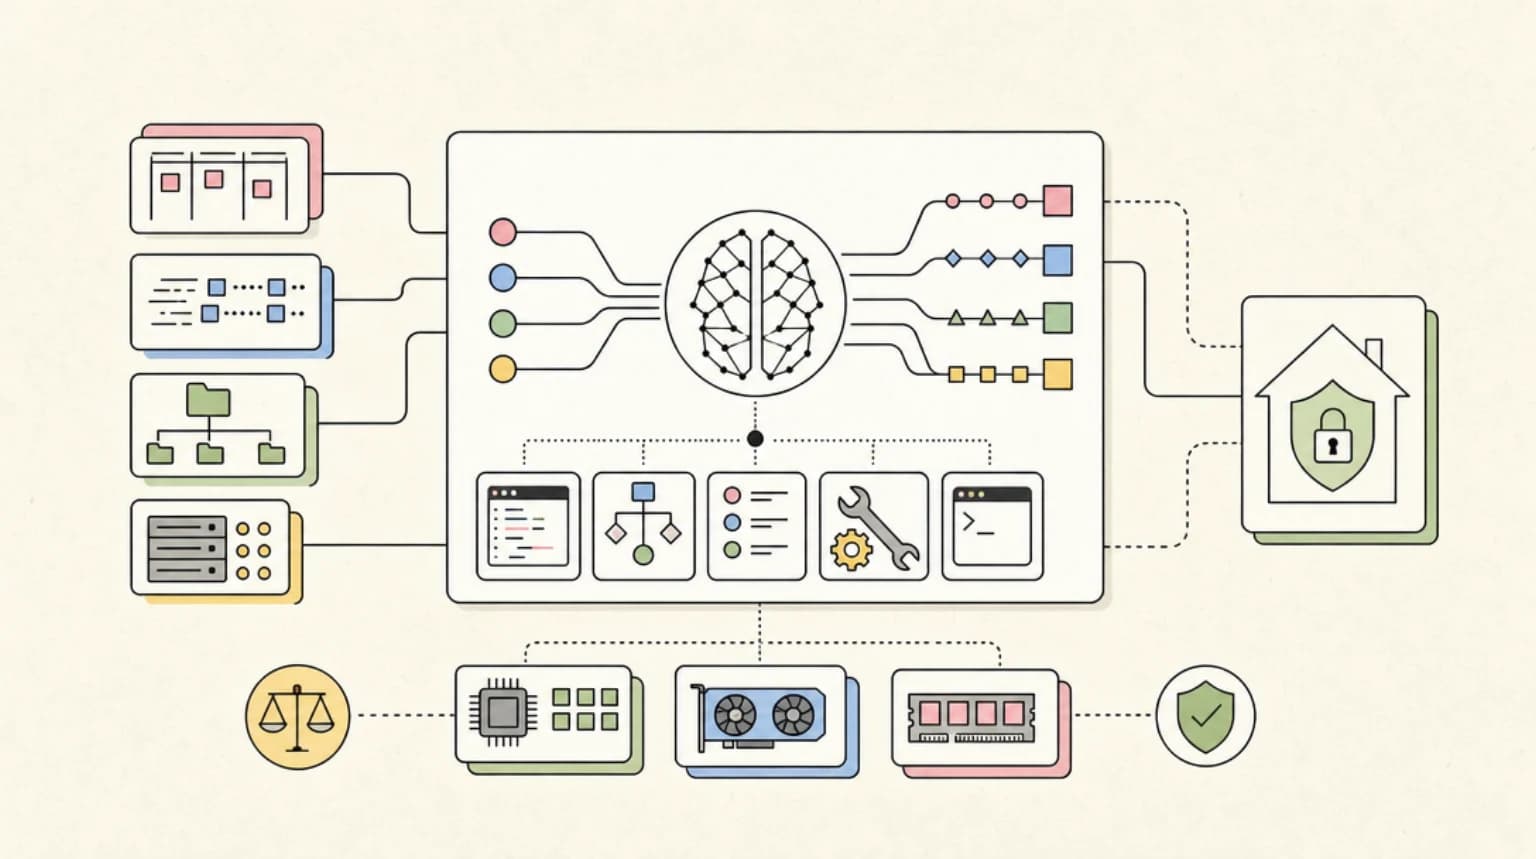
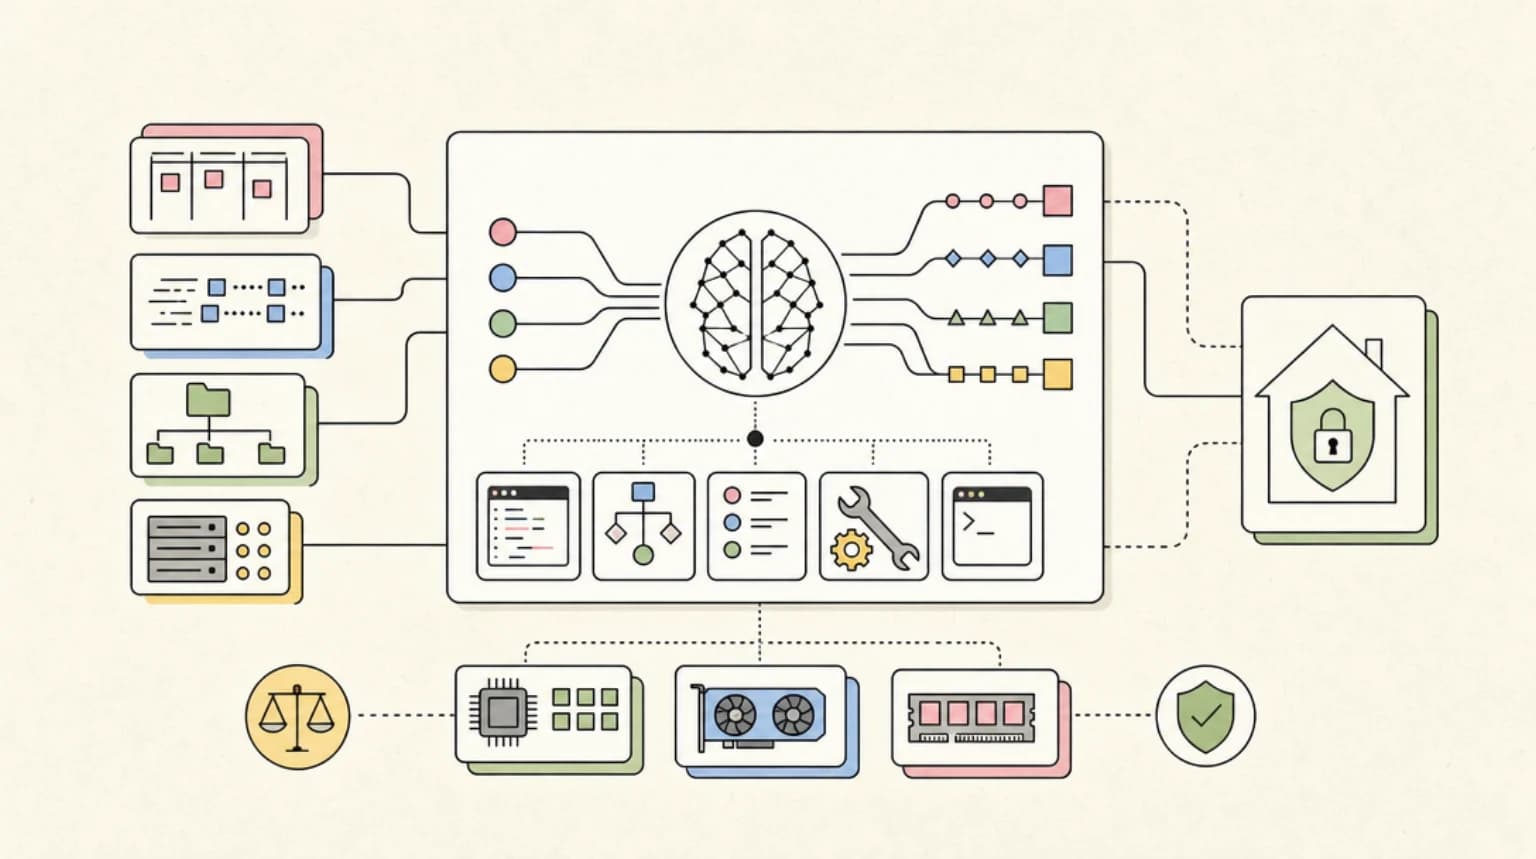
It is an agent skill in the SKILL.md format for tuning the speed of a local model server: single-user and concurrent decode, speculative decoding, prefill, KV cache size, startup time and time to first token, all under a memory cap. It ships three things:
SKILL.md, the procedure: inventory, ceilings, ground rules, the loop and the order of levers.references/, loaded only when needed: ceilings, measurement pitfalls, levers with measured evidence, engine gotchas and publishing gates.scripts/, a small harness in standard-library Python and bash:bench.pyagainst any OpenAI-compatible server,ceiling.py, a serialized run queue and a memory watchdog.
For Claude Code the install is a copy into your skills folder, per the README:
git clone https://github.com/sybil-solutions/inference-optimisation-skill
mkdir -p ~/.claude/skills
cp -r inference-optimisation-skill/skills/inference-optimisation ~/.claude/skills/
The README also documents a no-agent path: ceiling.py for the ceiling, then bench.py run configs/base.json --long 131072 for one run and queue.sh base cand base for an interleaved comparison. See our guide to the best Claude Code skills for how skills load.
The method worth stealing#
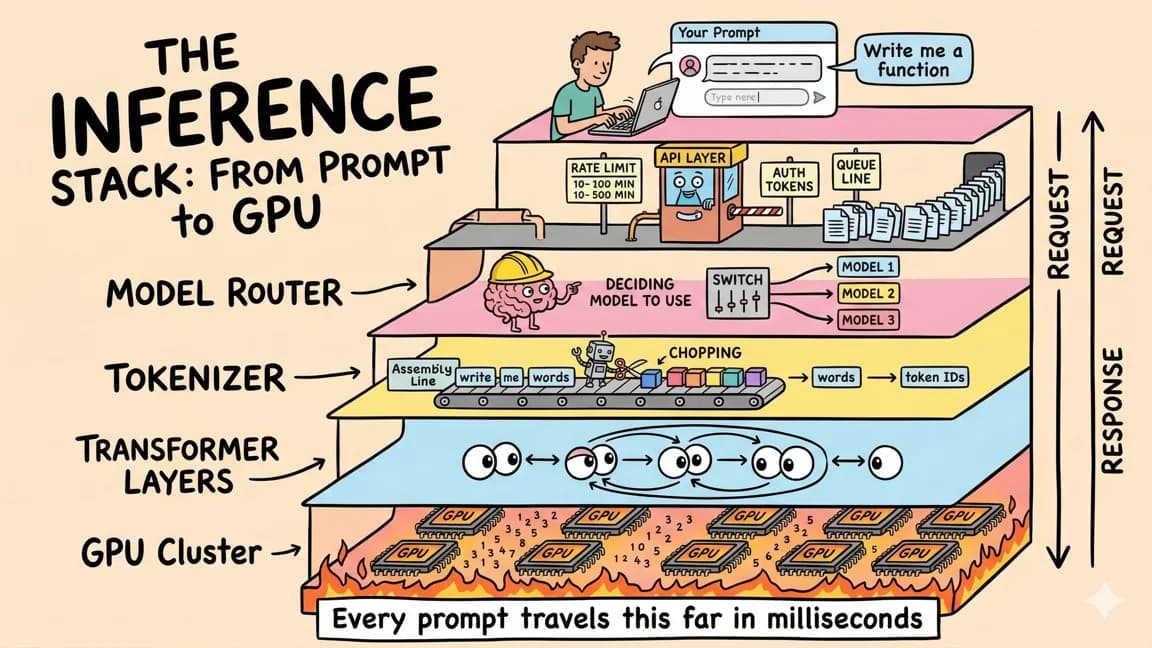
1. Ceiling first. The skill says decode is memory-bandwidth bound: count the bytes read per emitted token (dense weights, the active experts, the LM head, the KV read) and divide by measured bandwidth. Prefill is compute bound: roughly 2 x active parameters in FLOPs per token, divided by about half of measured peak. If your target is above the ceiling, it tells you so with the arithmetic. This is the same bandwidth rule behind llmspeed's estimates and the RTX Spark bandwidth math, applied as a stopping rule rather than a buying guide.
2. Control for noise. The skill puts run-to-run noise at 5 to 10 percent and requires at least six decode samples and the median. A candidate is accepted only if it beats both neighbouring controls (control, candidate, control) and regresses nothing by more than about 3 percent. Its methodology notes record the same config measuring 53.8 tok/s and then 49.5 an hour later, which is why single-run wins are suspect.
3. Measure the right thing. Count tokens from server usage stats, not streamed chunks (speculative decoding emits several tokens per chunk and under-reports). Size prompts with the real tokenizer: the authors found "random word" documents ran about 3.5 tokens per word, so nominal 32K and 128K cells were really 58K and 232K.
4. Gate on long context. A config is only "best" after exact-match needle retrieval at about 50 percent and 100 percent of context, plus a concurrent full-length soak if the KV pool is sized for several users. This matters for coding agents, which live on long prompts.
5. Write down failures. The skill keeps a PLAN.md log of every experiment with its verdict. Its stated reason: negative results are the most reusable output.
Lever order, and what the authors measured#
The skill orders levers cheapest first. These figures are from its levers.md, reported by the authors on named hardware:
| Lever | Reported evidence |
|---|---|
| Persist JIT and compile caches | Arc B390 with SGLang: startup 113 s to 43 s |
| Decode graphs | Arc Pro B70: 14.4 to 28.4 tok/s |
| Prune the draft head's vocabulary | B70 with vLLM: 37.9 to 48.2 tok/s (+27 percent) |
| Tune draft length per concurrency | B70: best k was 4 at one user, 3 at four, 2 at sixteen |
| Explicit prefix caching | 66K-token second-turn TTFT: 36 s to 0.45 s |
| Fusing small kernels under graphs | Three attempts on B390, correct output, 0 percent gain |
The headline README result is an Intel Arc B390 laptop iGPU going from 43.6 to 53 tok/s single-user decode and 297 to 628 tok/s at 256K prefill. Against a calculated ceiling of roughly 670 to 684 tok/s for that prefill, the authors report reaching most of it. These are self-published, vendor-reported-style numbers from the authors on one stack, not independent results; treat them as priors, as the skill itself says.
What you do Monday#
You do not need Intel hardware to use the idea. On any machine running an OpenAI-compatible server (llama.cpp, vLLM, SGLang, Ollama-compatible endpoints):
- Measure real bandwidth with a device copy, not the spec sheet, and run
ceiling.pywith your model's component sizes. - Run
bench.pythree times as control, candidate, control, changing exactly one flag. - Keep the change only if both controls lose. Log it either way.
- Before you call a config best, run the long-context needle check at your real working context.
Pair this with how much VRAM you need for the memory side and the KV caching guide for why KV sizing caps concurrency.
What people are actually saying#
We found no Hacker News or Reddit thread about this repository yet, so there is no community discussion to paraphrase. The only public signal is on GitHub: about 588 stars and 60 forks a day after the first commit, which shows interest, not validation. The one contributor besides the maintainer is listed as claude, and the commit message credits Claude Opus 5.5 as co-author, so treat it as an agent-assisted distillation of the maintainers' own hill-climbs.
The counter-case is in the skill itself. It records speculative decoding losing outright on bandwidth-poor devices: Apple M4 fell from 6.35 to 3.25 tok/s with three MTP drafts, and llama.cpp MTP on hard prompts measured 36.7 against 45.4 without it. The defensible read is that the method generalizes and the specific numbers do not. A skill that tells your agent to run six interleaved samples per change also burns real GPU hours, so budget for that.
FAQ#
How do I speed up a local LLM?#
Compute the ceiling first, then change one thing at a time and compare each change against controls on both sides. The skill's order is compile caches, decode graphs, speculative decoding, KV and concurrency sizing, then prefill and kernels.
Does speculative decoding always make a local model faster?#
No. The skill's own notes show it losing on an Apple M4 and on hard llama.cpp prompts. Measure per step and per workload.
Do I need Claude Code to use the skill?#
No. It is a SKILL.md procedure plus a standard-library Python harness that works against any OpenAI-compatible server.
Continue Reading#
- Local LLM Speed by Hardware: What llmspeed Gets Right - the bandwidth rule behind the ceilings
- How much VRAM do you need to run a local LLM in 2026? - the memory-size half
- KV caching in transformer inference - why KV sizing caps concurrency
- The Best Local Coding LLMs in 2026 - what to run by hardware tier
- The best Claude Code skills in 2026 - how skills load and compose
Sources#
- sybil-solutions/inference-optimisation-skill - README, results table, install; read November 17, 2026
- SKILL.md - procedure, ground rules, lever order
- levers.md - measured evidence per lever
- methodology.md - noise, counting and prompt-size pitfalls
Get the next deep dive like this in your inbox
One email a week on Local Models and the rest of the AI dev stack. Free.
Read next on local and open-weight models
Local LLM Speed by Hardware: What llmspeed Gets Right
llmspeed estimates tokens per second for 30 machines and 15 models. What its numbers mean, the memory-bandwidth rule behind them, and why prefill matters for coding agents.
7 min readHow much VRAM do you need to run a local LLM in 2026?
How much VRAM a local LLM needs: Q4 weights are about 30% of BF16, plus a KV cache that grows per token. Real numbers from 8 GB to 256 GB.
13 min readKV Caching: A Practical Guide to Optimizing Transformer Inference
How KV caching speeds up LLM inference - the math, the code, the memory tradeoffs, and when it stops helping. Every dev running local models hits this wall.
11 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.