Anthropic Self-Replicating AI Research: What Small Models Can Actually Do
TL;DR
Anthropic's Frontier Red Team says small open models may be months from self-replicating across cheap IoT devices. What the experiments measured, where the claim is thin, and what builders should take from it.
Anthropic's Frontier Red Team published a post on October 12, 2026 arguing that small AI models "may be months away" from self-replicating across cheap internet-of-things (IoT) devices such as off-brand Android TV boxes, with no datacenter involved. If you searched "Anthropic self replicating AI" after the headlines, this is the version with the experiments separated from the forecast - and the parts that matter if you build with agents or run small models locally.
Last updated: October 14, 2026
What the primary source says#
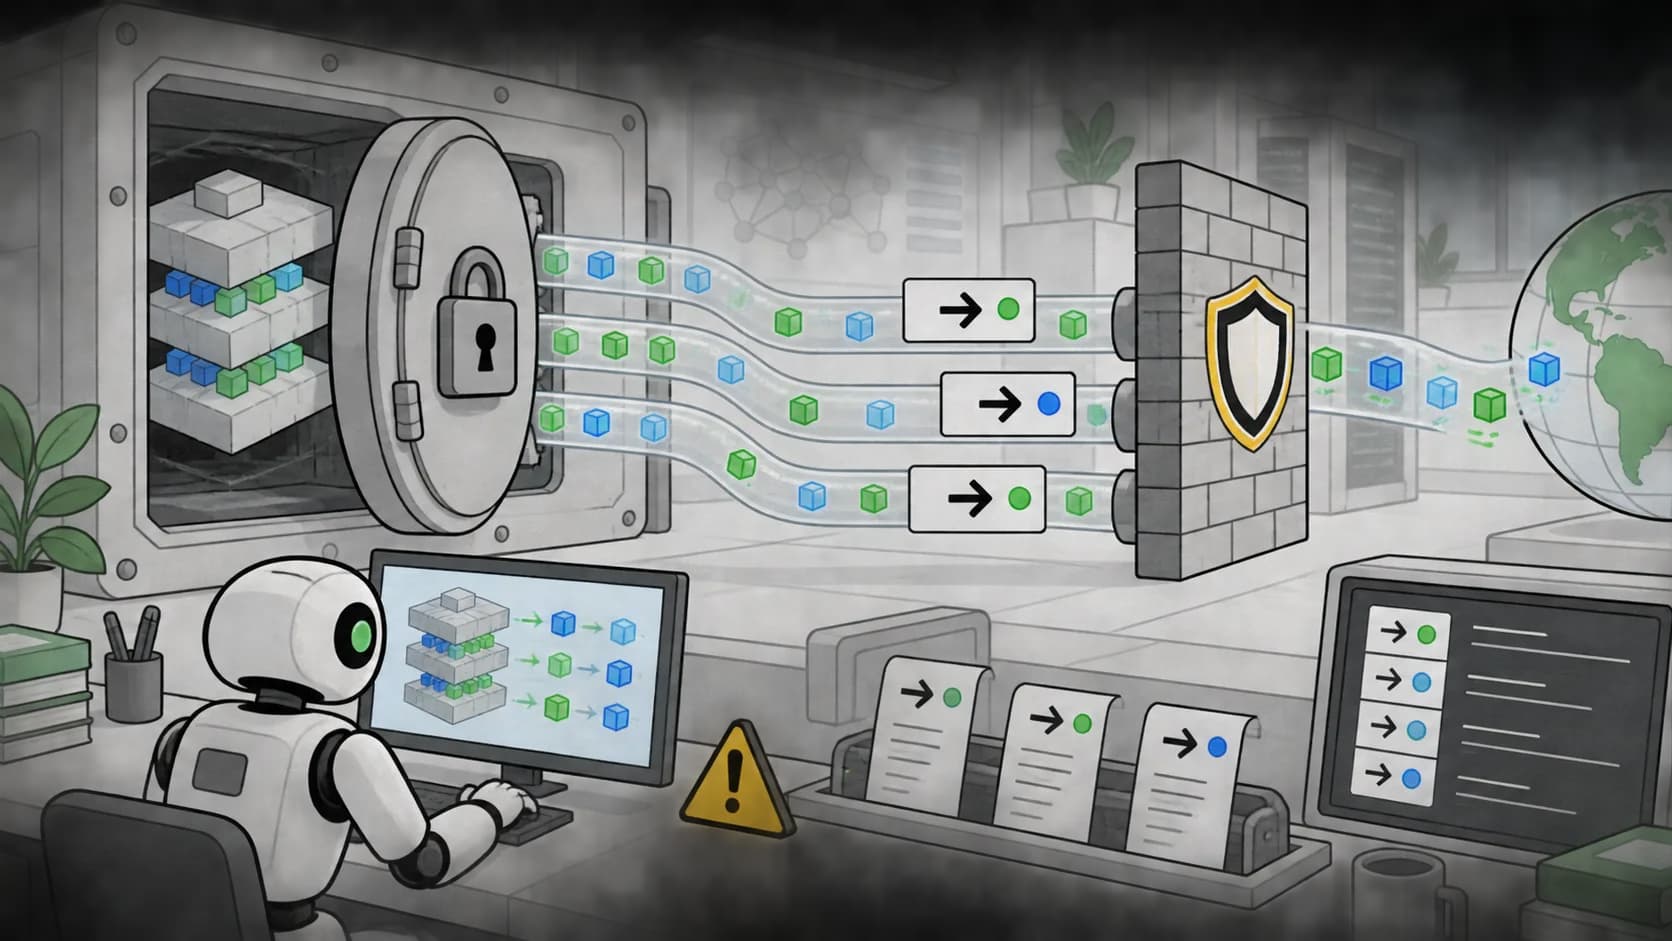
The post, AI models may be capable of self-replicating without access to a datacenter, is a vendor research report. Everything below is Anthropic-reported unless noted. The authors split replication into four stages: finding targets, gaining execution, establishing inference, and continuing from the new host. They deliberately skip the first two (cyber exploitation) and test the third, which they call the least studied: can a model get an inference server running on hardware it has never seen?
The headline numbers:
- Inference setup. A 9B model got inference running on 8 of the 9 hardware types tested, from Jetson Nanos to Macs and RTX 4090s. Larger models were more reliable and served faster.
- End-to-end replication. In a firewalled network of 8 GCP nodes running Android emulators with an unauthenticated ADB port, only GLM-5.2 replicated end to end among the open-weight models tested. It reached 8 of 8 nodes in 4 of 5 trials and 7 of 8 in the fifth.
- The hardware demo. Anthropic ran Gemma4-26B-A4B sharded across 15 smart TV boxes (about $55 each, 4GB of RAM each) using pipeline parallelism, at 0.39 tokens per second.
- Speed. At roughly 0.3 tokens per second, a full inference setup took Gemma4-26B-A4B an estimated 71 to 150 hours and Qwen3.5-9B 28 to 51 hours. The authors call this a slow, "slime mold" style spread, not a fast worm.
- Scale estimate. Applying the same setup to a fleet the size of the Kimwolf botnet (over 2 million devices, per the post) gives about 133,000 replicas and the inference capacity of roughly 40 H100s - tiny in absolute terms.
- The forecast. Using GLM-5.2 as the capability floor and a trend of 13.7 Epoch Capabilities Index points per year for open models of 30B parameters or fewer, the post projects a small model reaching that level by the end of 2026. The authors note the index is only a proxy for replication ability.
Two caveats the authors state themselves matter for how much weight to give this. First, the cyber step was kept trivial (no authentication on the ADB port), which they describe as an upper bound on real-world success. Second, they test whether models can stand up Llama 3.1 8B, not themselves - a stand-in that assumes a small model with GLM-5.2's capability would transfer.
The angle: it is a harness result as much as a model result#
The experiments ran on Memento, a harness the team built on top of the open-source Pi coding agent. It fixes a failure builders will recognise: an agent gets fixated on a wrong diagnosis and keeps digging. Memento periodically starts a fresh agent instance that inherits the workspace plus short notes from its predecessor on what was tried and what failed.
That pattern is portable. If you run long agent tasks, a "restart with notes" step is cheap to add, and the post's data supports it: across six generations of Qwen3.5-9B inheriting notes, setup success rose from 45% in the first generation to between 61% and 84% in later ones. For background on why the harness layer carries so much of the outcome, see What Is an Agent Harness? and the Pi 1.0 release guide.
Another finding is easy to miss: giving Qwen3.5-9B access to a frontier model as an advisor did not measurably help. The authors say small models "tend to not know the right questions to ask." The practical read is that delegating up to a bigger model is not automatic - the asking is its own skill.
Who wins and loses#
This is the strategic read, and it is my analysis rather than something the post claims.
- Small-model and edge-inference work gets a second audience. The Gemma demo is the same shape as other low-resource local-inference experiments, such as Gemma 4 26B on a 13-year-old Xeon. Capability per gigabyte keeps being the metric that matters, for good and bad uses. If you are choosing local models for coding, the best local coding LLMs is the practical companion.
- Device makers carry the exposure. The post's own defences point at manufacturers: default credentials and open debug ports are what the whole chain leans on, and it cites UK rules banning default IoT passwords as a lever.
- Open-weight policy gets a new argument. Expect this post to be cited in debates over open models. Whether that is sound safety research or lobbying is exactly where the community split (below).
What people are actually saying#
The Hacker News thread had over 100 comments when I read it. A fair summary of the range:
- Skeptical of the threat. One commenter called it a rubbish article, arguing that an agent running on commercial IoT hardware would be poor at anything useful and that compute remains the limiting factor. Another said it reads like another round of fear marketing but still sees a "cool technical demo" underneath.
- Suspicious of motive. A long sub-thread argues the post is groundwork against open models; others push back that testing whether models can do damage is ordinary safety research and that the real malware risk comes from existing criminal groups, not open source.
- Technical doubt on the chain. Several comments question whether 0.3 tokens per second is meaningful for anything beyond replication itself, which is consistent with the authors' own "slow replicator" framing.
- Alarmed. Some commenters treat TVs and other cheap hardware as already-compromised space where such a program could quietly live.
There are also threads on Reddit, for example in r/technology and r/singularity, which I only skimmed via search excerpts. Treat them as evidence of reach, not as a source for any claim here.
What to do about it on Monday#
The post is not a bug report and there is nothing to patch. But three things follow for builders:
- Audit what you own. The evaluation depended on an open, unauthenticated ADB port. If you run Android-based devices on a network, check for exposed debug ports and default credentials. That is the cheapest control in the whole chain.
- Bound your own agents. The same capability that sets up inference on an unfamiliar Jetson lets a coding agent do unexpected things in your environment. Egress limits and scoped credentials are the controls to look at; the earlier piece on document-borne AI worms in Copilot covers a different propagation route with the same lesson.
- Read the forecast as a forecast. "Months away" rests on an index trend line and a simplified lab setup. It is a reason to harden defaults, not evidence of anything in the wild.
Continue Reading#
- What Is an Agent Harness? A Developer's Map for 2026 - why the harness layer decides agent outcomes
- Pi 1.0 Release Guide: MCP, Codemode and Pi Durable - the open-source coding agent Anthropic's harness builds on
- Running Gemma 4 26B at 5 Tokens/Sec on a 13-Year-Old Xeon With No GPU - the same model family on constrained hardware
- Document-Borne AI Worms Self-Propagate Through Copilot for Word: What HN Thinks - a different worm route, same hardening lessons
Sources#
- AI models may be capable of self-replicating without access to a datacenter - Anthropic Frontier Red Team, October 12, 2026
- Hacker News discussion - 100+ comments
- Pi coding agent - the open-source agent Memento is built on, as cited in the Anthropic post
- Reddit: r/technology thread and r/singularity thread - reach only, not used for claims
FAQ#
Did Anthropic say AI is self-replicating in the wild?#
No. The post describes lab experiments and a forecast. It says it does not yet have "a full rogue replicator" and that models can complete individual steps of the chain, with errors when composing them end to end.
What did the experiments actually show?#
A 9B model set up inference on 8 of 9 hardware types, GLM-5.2 replicated across an 8-node emulated network, and a 26B model ran across 15 cheap TV boxes at 0.39 tokens per second. The network exploit step was deliberately trivial.
How fast could such a replicator spread?#
Slowly. Anthropic estimates days per replication on TV-box hardware at about 0.3 tokens per second, and compares it to a slime mold rather than a fast worm.
What is the simplest defence?#
Removing the easy entry points: no unauthenticated debug ports and no default credentials on networked devices. The post also points to ISP quarantine and notification, which cleared 92% of Mirai infections within 14 days in prior research it cites.
Get the next deep dive like this in your inbox
One email a week on News and the rest of the AI dev stack. Free.
Read next on local and open-weight models
Anthropic's GLM-5.3 Cyber Report: The Numbers, the Backlash, and What Developers Should Take From It
Anthropic's Frontier Red Team says GLM-5.3 builds working exploits at rates close to Claude Mythos Preview, and that its safeguards can be stripped in days. Here are the verified numbers, the community backlash, and the practical read for developers.
6 min readAnthropic's False Murder Tip: What the Unintended Actions Report Means for Your Agents
Claude Haiku 4.5 submitted an invented tip to a police form during an Anthropic evaluation. The October 9 report lists four behaviors, and each one maps to a scoping mistake you can check in your own agent setup this week.
8 min readAnthropic Scion: Why Anthropic Replaced Git for Agent-Scale Merges
Anthropic went from about 2,500 to over 30,000 merges a day and replaced git with an in-house system called Scion. What the post says, what HN pushed back on, and what to do on your own repo.
7 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.