7 min read
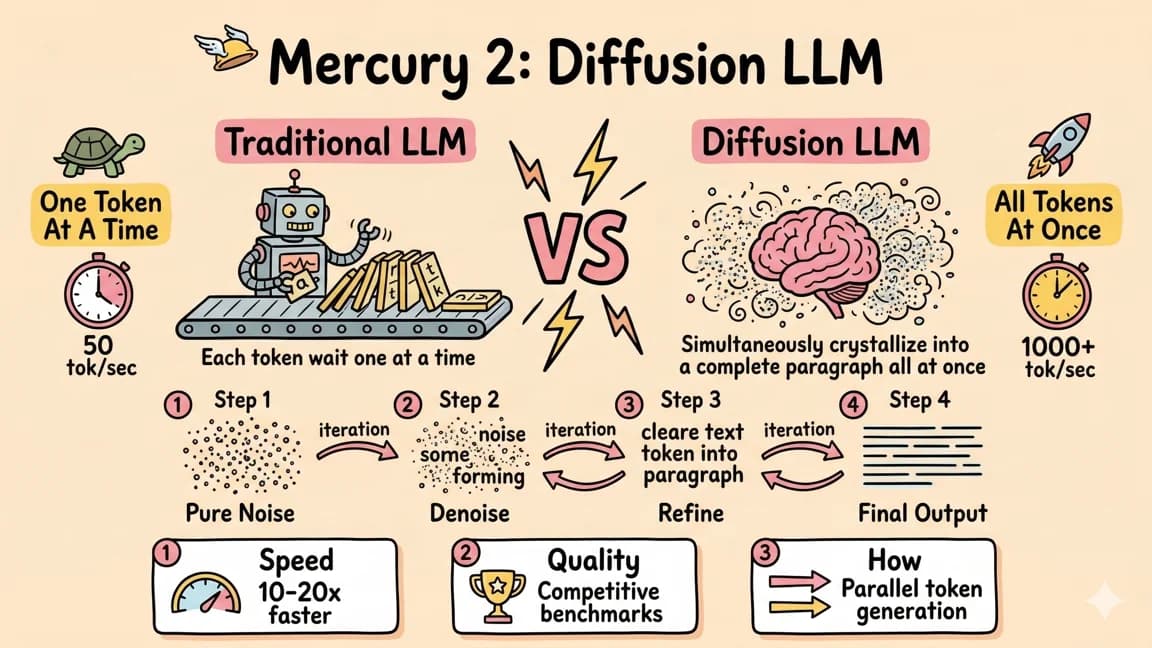
Diffusion Language Models: How Mercury Changed the LLM Speed Game
Diffusion language models like Inception Labs' Mercury draft a whole response and refine it instead of going token by token. See why that makes them so fast.
Read more
2 articles
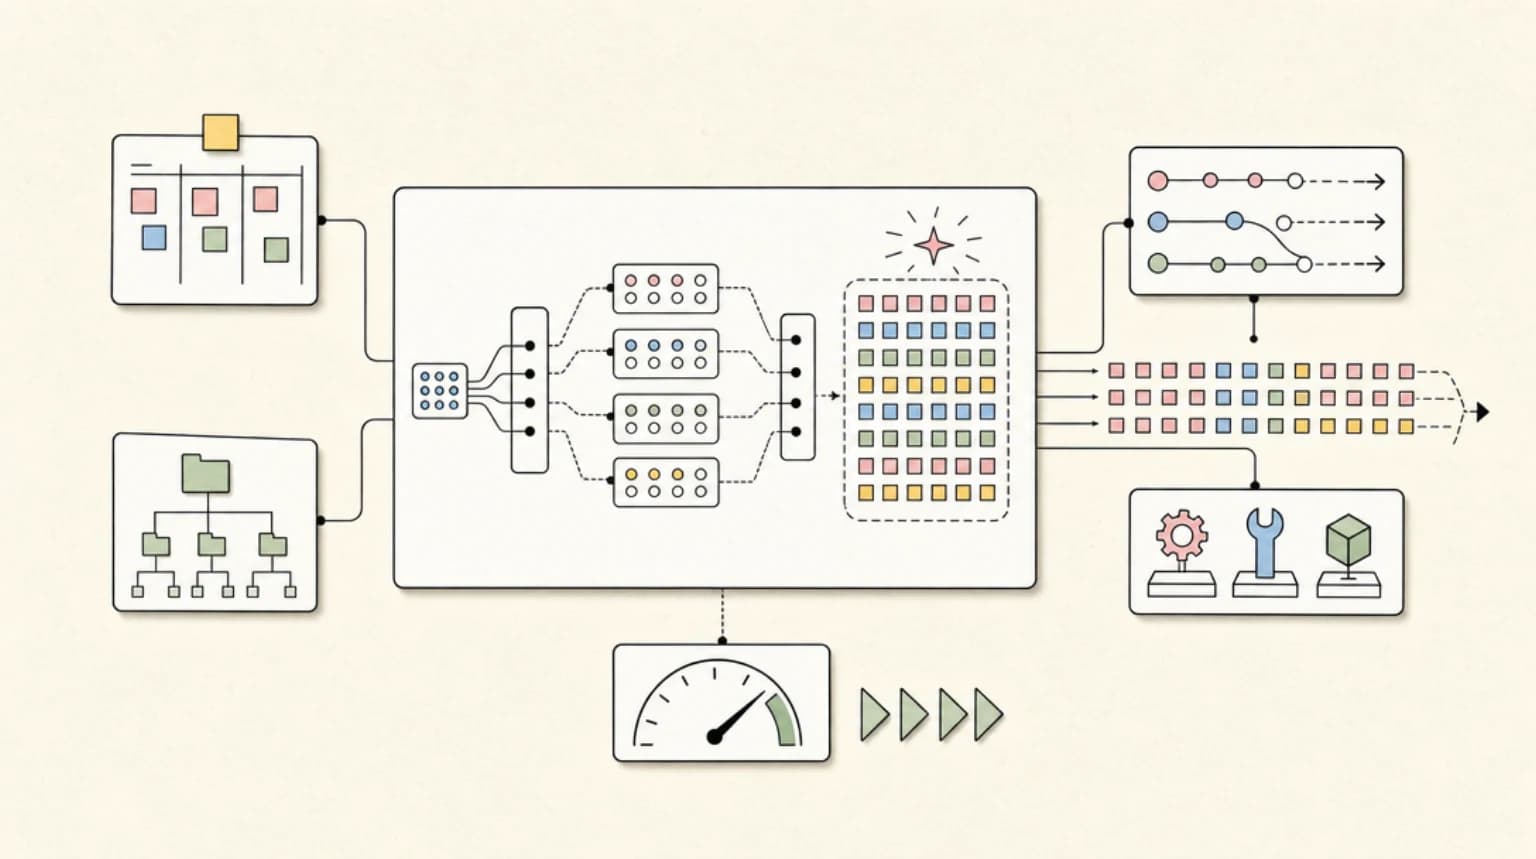
DiffusionGemma is Google's 26B MoE open model that generates 256-token blocks in parallel. What diffusion generation means for latency and local inference.
Diffusion language models like Inception Labs' Mercury draft a whole response and refine it instead of going token by token. See why that makes them so fast.
Showing 1 of 1 articles

New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
Explore 840 topics
Browse All Topics