Prompt Injection Is Really Role Confusion
TL;DR
Prompt injection is role confusion: models do not reliably tell instructions from tool output, user content or their own reasoning, so better prompts fail.
Simon Willison linked a new paper writeup today that gives prompt injection a better name: role confusion.
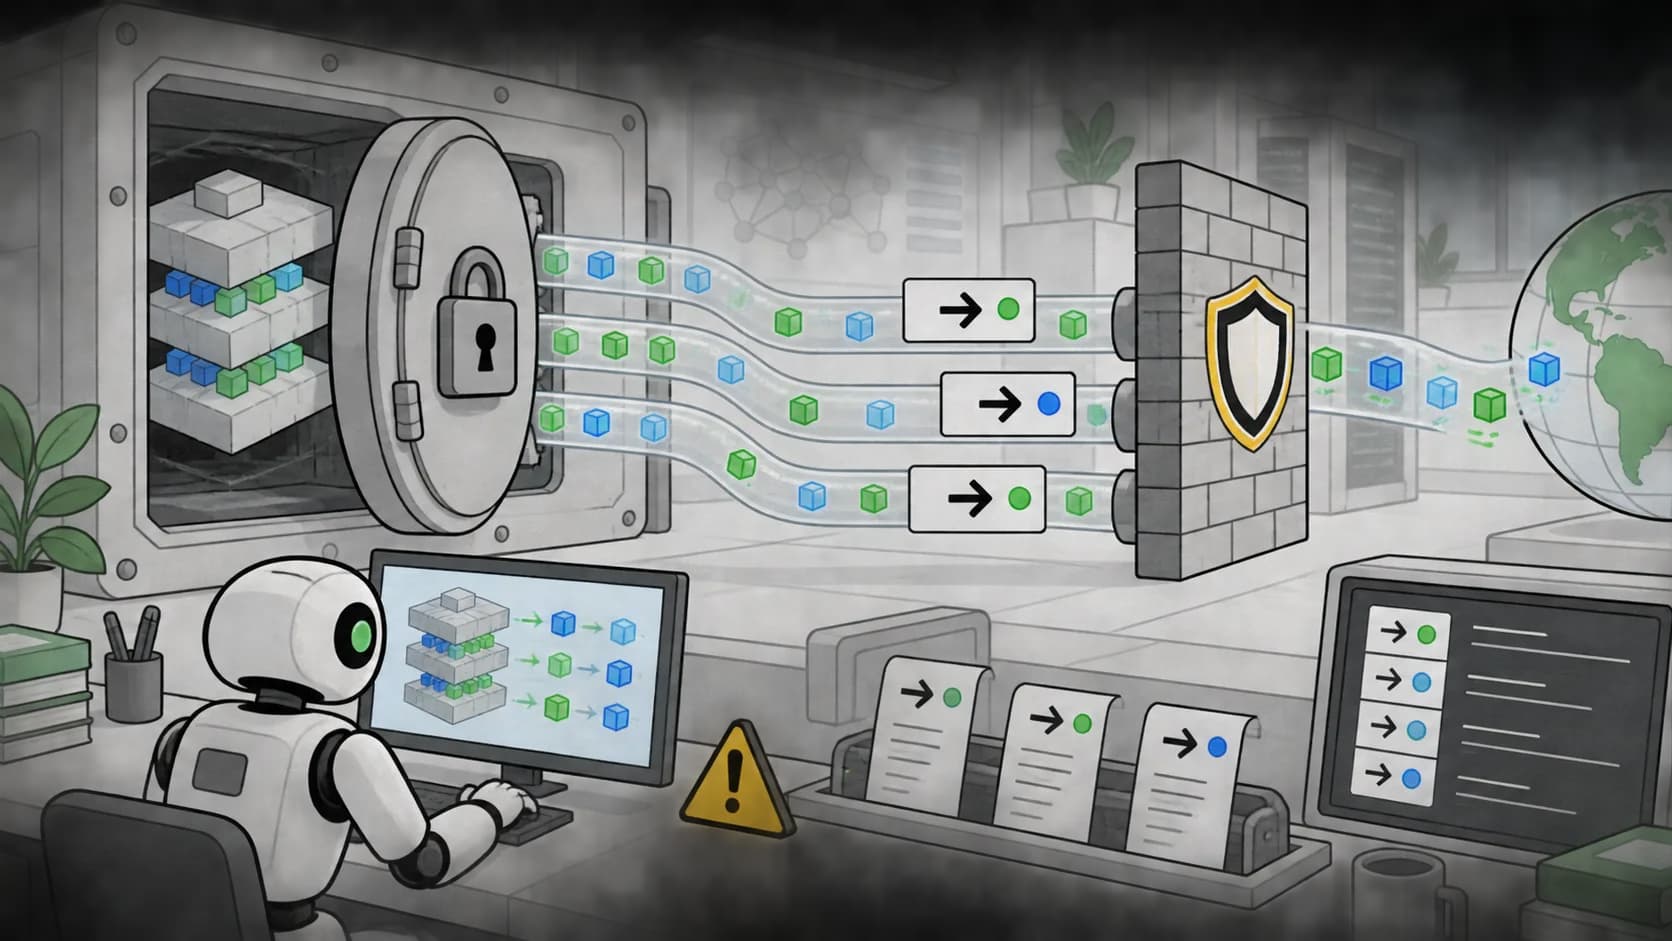
That framing is useful because it moves the problem out of the vague "LLMs are gullible" bucket and into a concrete systems problem. An agent receives system instructions, developer messages, user prompts, tool outputs, retrieved webpages, previous assistant messages, and sometimes reasoning traces as one long stream of tokens. Humans see separate boxes. The model sees text with role labels.
If the model cannot reliably perceive those role boundaries, prompt injection is not a weird edge case. It is an expected failure mode.
Last updated: June 23, 2026
The research site, Prompt Injection as Role Confusion, makes the core point cleanly: roles are how LLMs recover structure from a "token soup." The model is supposed to treat system text differently from user text, tool output differently from instructions, and its own reasoning differently from untrusted content.
That works until it does not.
The Core Idea#
The role-confusion writeup describes roles as an attempted type system for language.
That is exactly the right phrase.
In software, types tell the runtime what a value is allowed to mean. A string can be user input, HTML, SQL, a shell command, JSON, or a file path. Treating all strings the same is how you get injection bugs.
LLM agents have a similar problem:
| Text Source | What It Should Mean |
|---|---|
| system | high-priority operating rules |
| developer | product and integration instructions |
| user | the human's requested task |
| tool | external data, not instructions |
| assistant | previous model output |
| reasoning | private intermediate inference, when exposed to the model runtime |
Prompt injection happens when low-authority text gets interpreted as high-authority text.
A webpage should be data. A malicious line inside that webpage should not become an instruction. A PDF should be evidence. A hidden paragraph inside that PDF should not be allowed to rewrite the task. A Slack message should be conversation context. It should not be able to exfiltrate connected data.
The problem is that roles are represented in the same medium as everything else: tokens.
Why Better Warnings Are Not Enough#
The paper writeup and Simon's summary highlight a disturbing finding: models can respond more to style than to the explicit role label.
The authors describe "destyling" attacks: rewrite injected text so it no longer resembles privileged reasoning or instruction text, and attack success changes dramatically. Simon quoted their result that destyling reduced average attack success in one dataset from 61% to 10%.
That is not just a jailbreak trick. It suggests the model is not reading role boundaries like a compiler reads types. It is inferring them from patterns, style, position, and learned associations.
This explains why prompt injection defenses often feel like whack-a-mole:
- "Ignore previous instructions" gets memorized as suspicious.
- The attacker rephrases it.
- The model sees a style that resembles a legitimate instruction.
- The boundary blurs again.
Attack memorization is brittle. Role perception is the thing we actually need.
For developers, that means stronger system prompts help, but they are not a complete security boundary. If your safety model is "we told the agent not to follow tool-output instructions," you do not have a boundary. You have a preference.
The Agent Design Implication#
The dangerous version of prompt injection is not a chatbot saying something weird.
The dangerous version is an agent with tools:
- browser access
- Slack access
- email access
- file access
- database access
- issue tracker access
- payment or deployment access
Once the agent can act, role confusion becomes capability confusion. The model may confuse a webpage instruction with the user's request, then use real tools to satisfy it.
That is why prompt injection belongs next to capability design, not just prompt engineering. We covered the practical version in prompt injection for agent apps, but this research gives the deeper reason: the model's internal role perception is not discrete enough to carry the whole security model.
The architecture should assume untrusted content can sound like instructions.
Practical Defenses#
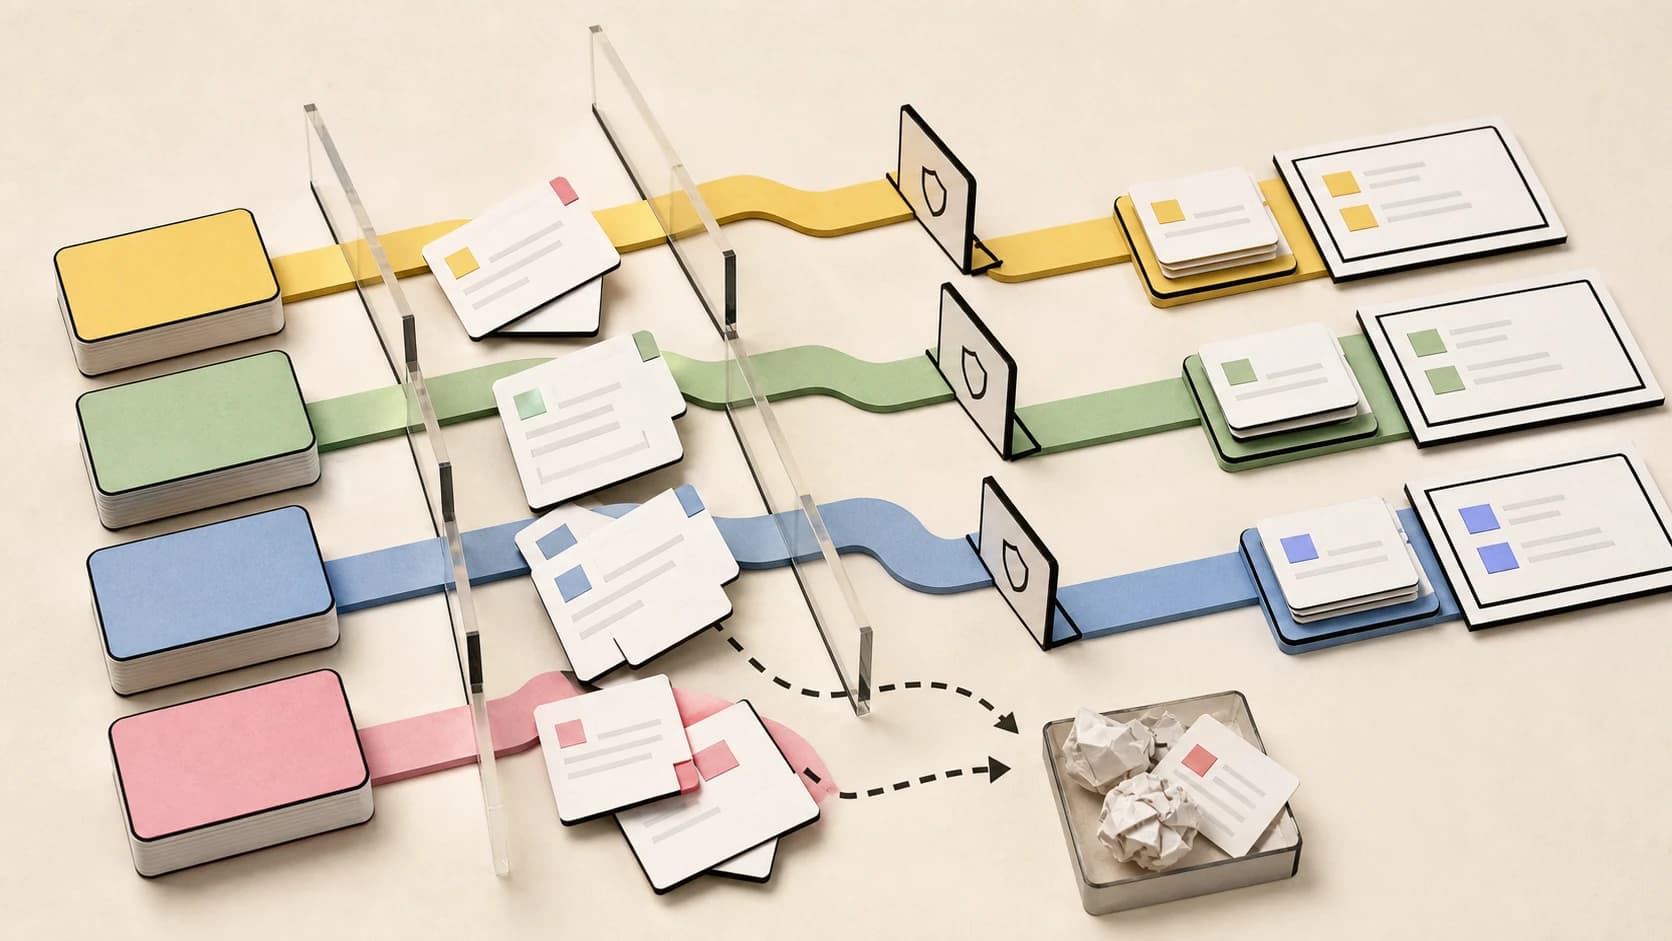
The right response is layered isolation.
1. Preserve Provenance#
Every chunk passed to the model should carry a source label that the rest of the system also understands.
Do not only wrap text in a prose warning. Store provenance in your application state:
- source URL
- tool name
- user who supplied it
- timestamp
- permission scope
- trust level
- whether it is allowed to contain instructions
The model can use the label, but your code should enforce the policy.
2. Separate Evidence From Commands#
Treat tool output as evidence, not as executable instruction.
A good agent loop distinguishes:
- "The webpage says X"
- "The user asked me to do Y"
- "The policy allows action Z"
Those should not be collapsed into one blob of context.
3. Require User Approval At Authority Boundaries#
If untrusted content causes the agent to send a message, modify a file, hit an external API, change permissions, spend money, or reveal private data, require approval.
The approval prompt should identify the source of the request. "This webpage appears to be asking me to email your token" is very different from "Do you want me to continue?"
4. Constrain Tools By Default#
The easiest injection to survive is the one that cannot reach a dangerous tool.
Use scoped credentials, read-only modes, limited file roots, allowlisted domains, dry runs, and separate agents for separate trust zones. If a research agent only needs public browsing and note writing, do not give it GitHub write access or Slack posting rights.
This is the same principle behind an agent containment capability ledger: list what the agent can touch before you worry about how clever the prompt is.
5. Make Retrieval Output Visibly Untrusted#
For UI agents and internal tools, show users where retrieved text came from. Make it easy to inspect the source, page, thread, or file that influenced an answer.
This does not solve model perception, but it improves human review. The reviewer can see whether the agent treated a source as evidence or as an instruction.
The Bigger Lesson#
Role confusion is not only a security bug. It is a design constraint for every agent product.
Agents need roles, but roles are currently soft. They are represented through tokens and training, not enforced like process isolation or type checking. That means the surrounding application has to provide the hard edges:
- permissions
- sandboxing
- source metadata
- tool gating
- user approvals
- logs
- replayable traces
MCP servers, browser agents, file-editing agents, and Slack agents all face the same issue. The model may be good at following roles most of the time. Security architecture has to care about the times it fails.
That is why I like the role-confusion framing. It makes prompt injection feel less mystical.
It is not that the model has a tiny villain inside it. It is that the model is asked to infer authority from text style and role markers inside one continuous stream. Sometimes it infers wrong.
My Take#
The next generation of agent security will look less like clever prompt wording and more like boring systems engineering.
Treat roles as hints to the model, not as the enforcement layer. Put enforcement in the harness:
- code decides which tools are available
- code decides which sources are trusted
- code decides when approval is required
- code logs why an action happened
- code preserves provenance
The model can still reason over messy text. It just should not be the only thing deciding whether messy text has authority.
Prompt injection is role confusion. The fix is not one perfect warning. The fix is making role boundaries visible, reviewable, and enforceable outside the model.
FAQ#
What is role confusion in prompt injection?#
Role confusion is when an LLM misperceives which role a piece of text belongs to. For example, it may treat untrusted tool output as if it were a user instruction or privileged reasoning.
Why does role confusion matter for agents?#
Agents can take actions. If an agent confuses untrusted content for authorized instructions, it may use tools, send messages, edit files, or expose data in ways the user never requested.
Can system prompts prevent prompt injection?#
System prompts help, but they are not a complete security boundary. The surrounding application still needs tool gating, provenance tracking, sandboxing, and approval flows.
What is the difference between attack memorization and role perception?#
Attack memorization means the model recognizes known injection phrases and refuses them. Role perception means the model understands that text from a low-authority source lacks permission to issue commands, even when the attack is rephrased.
What should developers do first?#
Start by inventorying capabilities. List every tool the agent can use, which sources can influence it, and which actions require approval. Then make untrusted content visibly separate from user instructions in both the model context and the application state.
Continue Reading#
Sources#
Fetched June 23, 2026.
Get the next deep dive like this in your inbox
One email a week on Prompt Injection and the rest of the AI dev stack. Free.
Read next on AI coding tools
Prompt Injection in Agent Apps: The Practical Version
Prompt injection in agent apps is an architecture problem. Practical defenses: data boundaries, structured handoffs, tool guardrails, and approval gates.
8 min readThe Agent Security Checklist I Use Before Connecting Tools
Before an AI agent gets tools, files, APIs, MCP servers, or deployment access, decide what it can read, write, call, log, and roll back.
8 min readAI Agent Containment Needs a Capability Ledger
Anthropic's Claude containment writeup points to the next security layer for coding agents: deterministic capability ledgers, not another approval prompt.
9 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.