Agent Evals Need Baseline Receipts
TL;DR
Agent evals need baseline receipts: Hex's data-agent lab compares candidates against stable production baselines, keeps evidence and judges changes by behavior.
Official Sources#
| Resource | Link |
|---|---|
| Hex agent eval writeup | hex.tech/blog/evaluate-data-agents |
| OpenAI Evals guide | platform.openai.com/docs/guides/evals |
| Anthropic output consistency | docs.anthropic.com/en/docs/test-and-evaluate/strengthen-guardrails/increase-consistency |
| LangSmith evaluation docs | docs.smith.langchain.com/evaluation |
| Braintrust AI evals | braintrustdata.com/docs/guides/evals |
Hex's writeup on evaluating data agents is the most useful AI developer post on the wire today because it skips the usual benchmark theater.
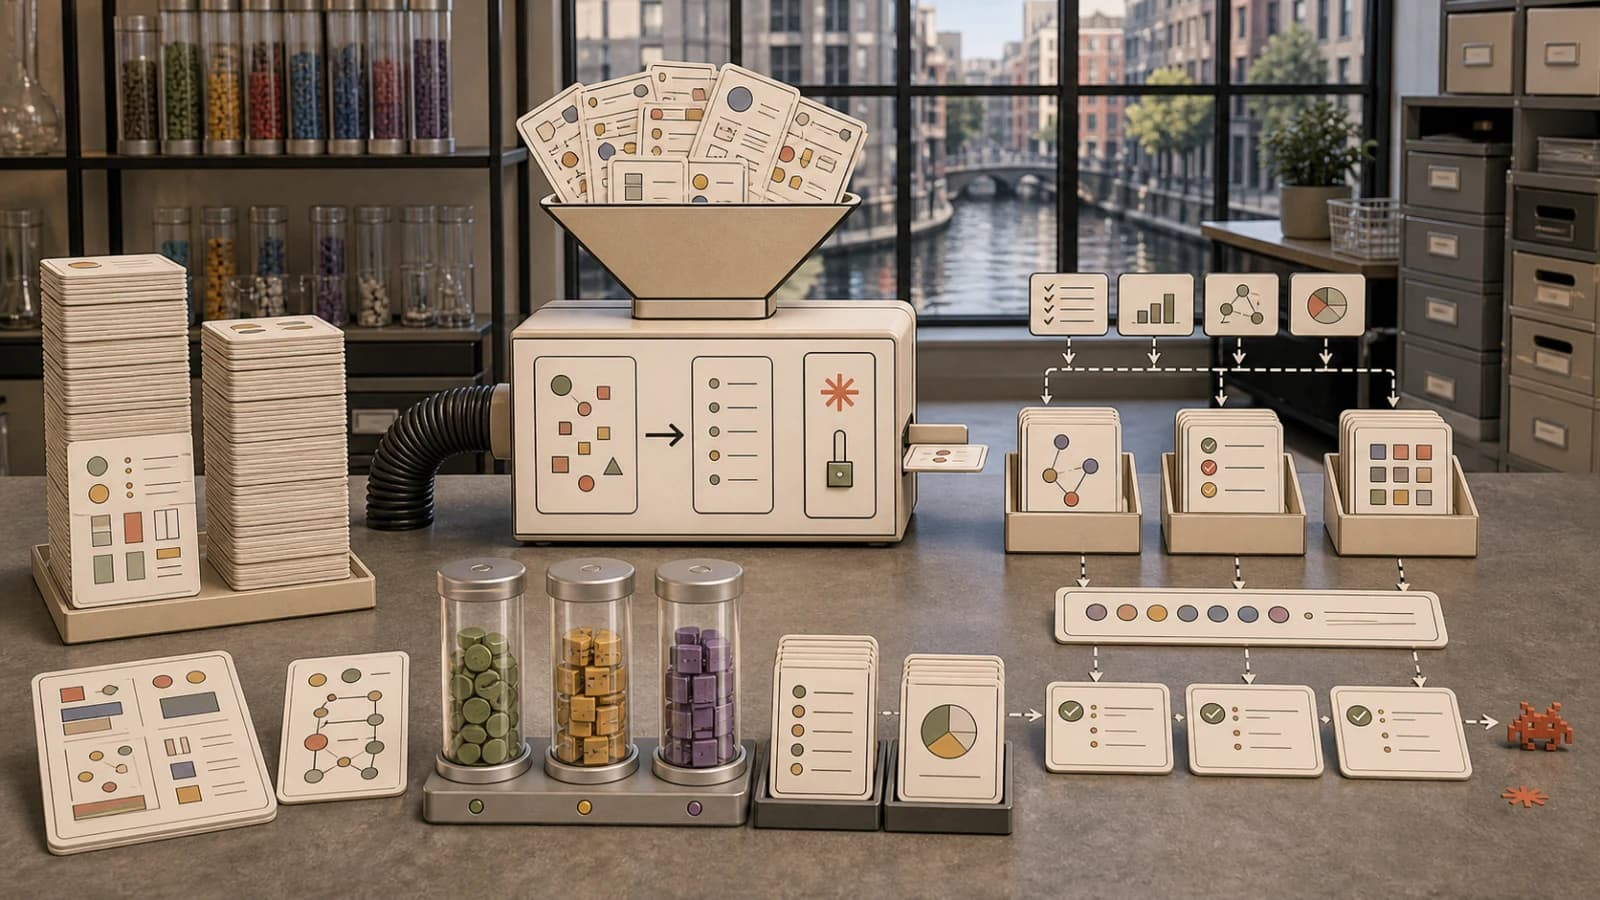
The interesting part is not that Hex built an eval tool. Everyone is building eval tools. The interesting part is the shape of the tool: a lab bench for pairwise experiments, stable production baselines, locally executed candidate runs, custom rubrics, side-by-side trajectories, and a fake business with realistic data.
That is the right direction for agent products.
Last updated: June 30, 2026
Agents do not fail like autocomplete models. They fail across a run: a bad assumption in step two, a missed join in step four, an overconfident final chart, a useful tool call made too late, or a correct answer that cost 10x too much. A single score at the end loses most of the evidence.
If you are building coding agents, data agents, browser agents, or internal operators, the durable primitive is not "run more benchmarks." It is baseline receipts.
Why Data Agents Expose the Problem First#
Hex describes analytics as a difficult domain for agents because easy questions can look hard, hard questions can look easy, warehouse context is private and out of distribution, and wrong answers can still sound plausible. That maps almost perfectly to software work.
A coding agent can pass a unit test while choosing the wrong abstraction. A data agent can produce a clean chart from the wrong grain. A support agent can cite the right document but apply it to the wrong customer state. A browser agent can finish the happy path while missing the broken edge state.
This is why context reduction, agent memory contracts, and long-running harnesses keep showing up as the same conversation. The model is only one part of the system. The context stores, retrieval layer, tool choices, planner, permissions, UI state, and final judge all change the result.
Hex makes that explicit. Their post says agent performance is increasingly a function of the rich context stores an agent can access, not just the model or system prompt. That is the sentence to steal for your own roadmap.
An agent eval that only compares model A to model B is under-instrumented. A useful eval compares the whole candidate system to the whole baseline system and keeps enough evidence to explain the delta.
The Baseline Is a Product Feature#
The most practical detail in Hex's setup is the hybrid workflow: local candidate runs compared against shared remote production baselines.
That sounds boring. It is not.
Most agent teams drift into a messy eval loop:
- Someone changes a prompt.
- Someone else changes a retrieval setting.
- A third person upgrades the model.
- The eval set changes quietly.
- A dashboard says the number moved.
Nobody knows whether the agent improved or whether the measurement surface moved underneath it.
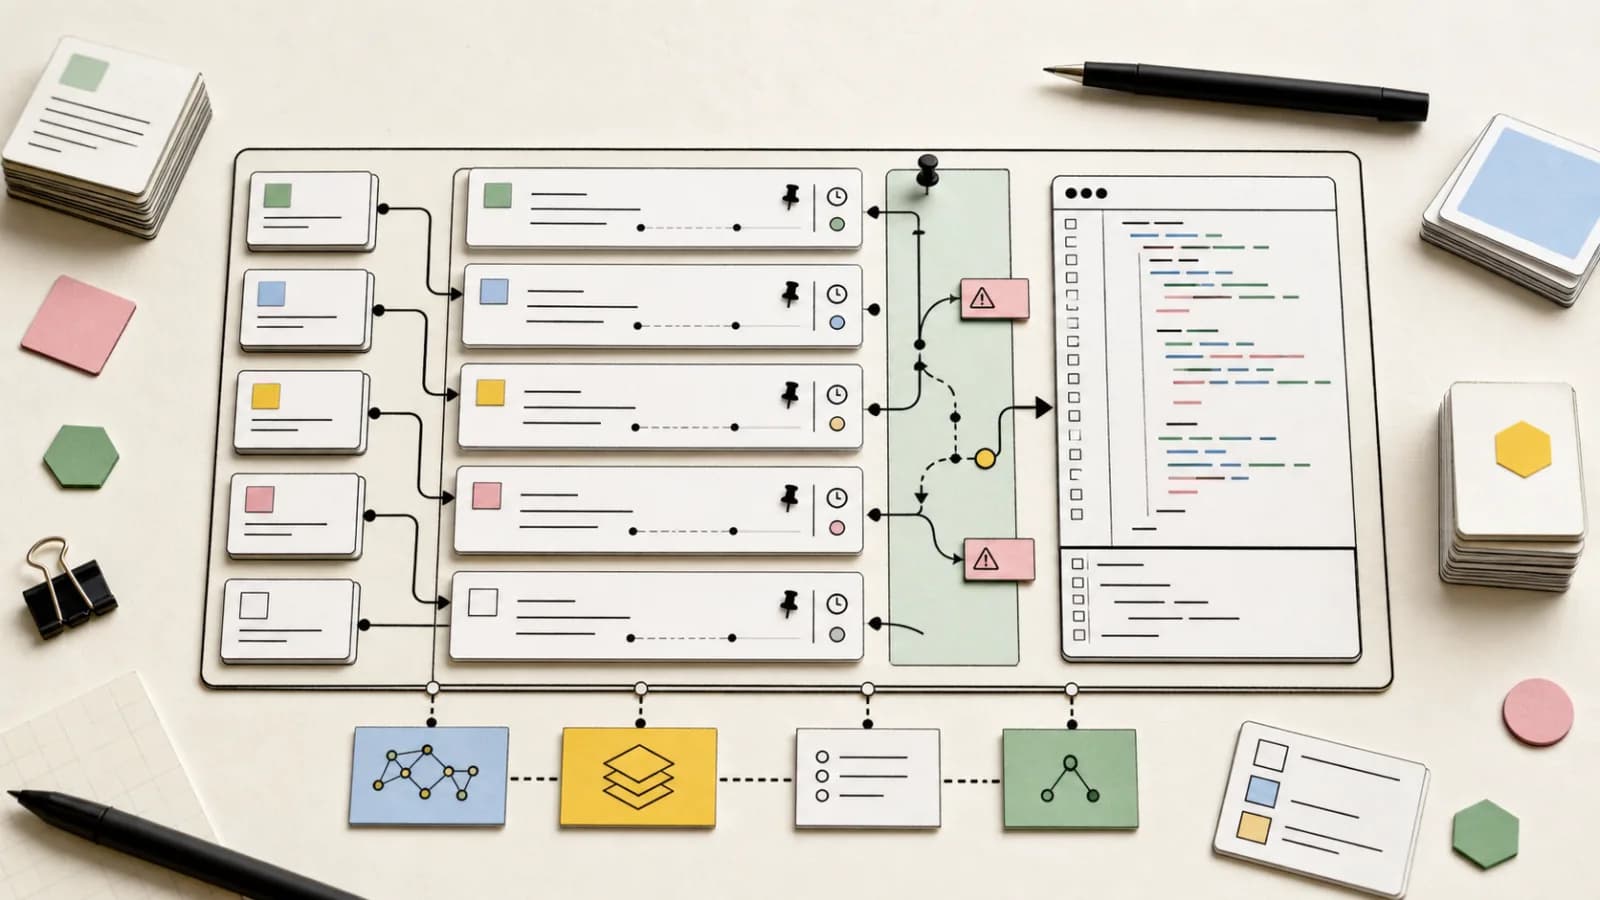
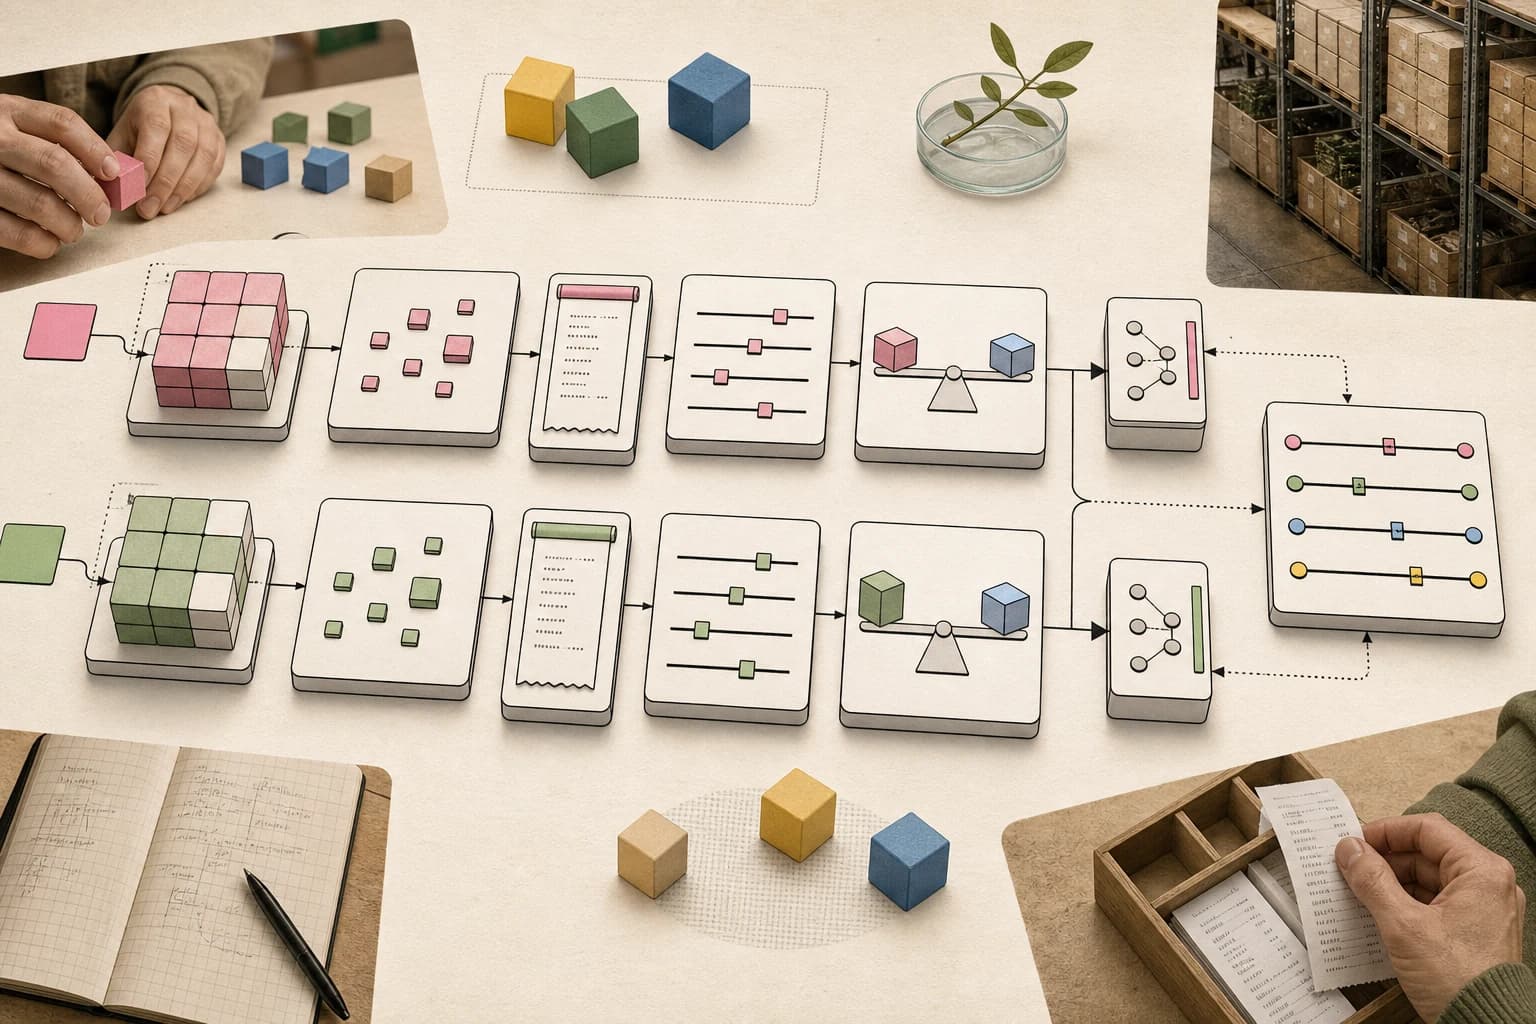
A stable baseline fixes that. It gives every experiment a reference point that does not depend on the developer's laptop, branch, cached data, or current prompt edits. It also changes the conversation from "this run scored 82" to "this candidate beat the production baseline on these cases, lost on these cases, cost this much more, and changed these behaviors."
That is the same operational instinct behind token-budget ledgers. You do not just ask whether the agent finished. You ask what it spent, what it touched, which path it took, and whether the new path is worth shipping.
For a coding-agent team, a baseline receipt should include:
| Receipt field | Why it matters |
|---|---|
| Baseline version | Prevents comparing against a moving target |
| Candidate version | Ties behavior to a branch, prompt, model, tool config, or memory change |
| Task fixture | Captures the repo, issue, database state, browser state, or document set |
| Trajectory summary | Shows tool calls, files touched, retries, and major decisions |
| Rubric results | Separates correctness, efficiency, safety, style, and user-fit |
| Cost and latency | Makes expensive wins visible before they become defaults |
| Human review note | Preserves the examples that aggregate scores flatten |
The key is not to make every receipt huge. The key is to make it stable enough that a reviewer can replay the important claim.
Pairwise Beats Absolute Scores#
Absolute eval scores are comforting because they look like grades. Pairwise evals are useful because they look like engineering.
Hex's writeup describes candidate and baseline runs as the default mental model. That one choice prevents a lot of bad dashboard behavior. You are not arguing about whether a synthetic benchmark number is impressive. You are asking whether the candidate made the real workflow better than the thing users currently have.
This matters even more as agent systems add model panels and judges. In the OpenRouter Fusion post, the right lesson was that multi-model panels should be escalation lanes, not autopilot defaults. The same applies to eval judges. A judge is useful when it has a concrete comparison, a task-specific rubric, and access to the run evidence. A judge is weaker when it scores a final answer in isolation.
The pairwise question is sharper:
Given the same task fixture, did candidate run B improve on baseline run A?

Evaluate:
- correctness
- evidence use
- unnecessary tool calls
- cost and latency
- policy violations
- final user usefulness
That framing makes it harder for a model to reward fluent nonsense. It also makes the failures legible. Maybe the candidate solved more tasks but stopped using the semantic layer. Maybe it was more accurate but doubled warehouse queries. Maybe it followed the workspace guide better but got slower. Those are product decisions, not benchmark trivia.
The Fake Business Is the Secret Ingredient#
Hex also built Shorelane Commerce, a fake business with realistic data. That is the part more teams should copy.
Public benchmarks are useful for broad model selection, but they rarely match your operating environment. Internal production data is realistic, but it is private, messy, permissioned, and hard to share across dev, CI, vendors, and external reviewers. A synthetic-but-realistic fixture gives you the missing middle.
For developer tools, the equivalent could be:
- a fake SaaS repo with auth, billing, migrations, flaky tests, and incidents;
- a fake support workspace with realistic customer plans, tickets, docs, and contradictory history;
- a fake analytics warehouse with dimensional models, bad joins, stale tables, and business definitions;
- a fake browser app with logged-in state, feature flags, permissions, and broken responsive views.
The goal is not to trick the model. The goal is to give the agent a world where the right answer depends on context, not trivia.
This is also where opposing opinions matter. The Hacker News thread for Hex's post had not developed much discussion when I checked it, but recent HN skepticism around AI testing agents is relevant: developers asked why they should pay token costs for nondeterministic test agents when LLMs can already write deterministic end-to-end tests. That pushback is fair.
The answer is not "replace tests with agents." The answer is "use deterministic tests for known invariants and agent evals for exploratory workflows where the path matters." A browser checkout test should be deterministic. A release-readiness agent that investigates a suspicious analytics drop needs trajectory evaluation.
What To Build Before Buying an Eval Platform#
Do not start with a giant eval platform. Start with one receipt format and one shared baseline.
For a small agent team, the first useful loop is:
- Pick 20 representative tasks.
- Freeze the fixture for each task.
- Run the current production agent and save baseline receipts.
- Run candidate changes locally against those fixtures.
- Compare candidate receipts against baseline receipts with a rubric.
- Review the biggest wins and losses by hand.
- Promote a new baseline only after the team agrees the tradeoff is worth it.
This is enough to catch most prompt, retrieval, memory, and tool-routing regressions. It also creates the habit that matters: every agent change has to explain what it improved against the current product.
OpenAI's eval docs frame evals as structured tests for model and application behavior. Anthropic's testing docs emphasize defining success, improving consistency, and using stricter output controls when you need schema conformance. Hex's contribution is the product-engineering layer between those ideas: shared baselines, pairwise runs, rich trajectories, and realistic fixtures.
That is the pattern to copy.
The Takeaway#
Agent evals should feel less like leaderboard watching and more like code review.
A good code review asks what changed, why it changed, what evidence supports it, what risk remains, and whether the tradeoff is worth merging. A good agent eval should do the same.
The next time a prompt, model, tool, memory layer, or context store makes an agent "feel better," ask for the baseline receipt. If the team cannot show the candidate run next to the production run, with the task fixture, trajectory, rubric, cost, and reviewer note, it does not have an eval yet. It has an anecdote.
FAQ#
What is a baseline receipt for an AI agent?#
A baseline receipt is a compact record of how the current production agent handled a task: the fixture, agent version, tool calls, trajectory, costs, rubric results, and reviewer notes. Candidate changes are compared against that receipt so teams can see what actually improved or regressed.
Why are pairwise evals better than benchmark scores for agents?#
Pairwise evals compare a candidate run against a known baseline on the same task. That makes regressions easier to spot and keeps the discussion tied to product behavior. Benchmark scores are still useful for model selection, but they usually hide the trajectory details that matter in agent systems.
Should agent evals replace deterministic tests?#
No. Deterministic tests should cover known invariants, API contracts, schema rules, browser flows, and safety gates. Agent evals are better for exploratory tasks where the path, evidence use, tool efficiency, and final judgment all matter.
What should teams evaluate besides correctness?#
Evaluate evidence use, unnecessary tool calls, cost, latency, policy violations, context-store behavior, memory use, final answer usefulness, and whether the candidate changed the action compared with the baseline.
Continue Reading#
- Harness Handbook Shows the Missing Map for Coding Agents
- Image Token Compression Is a Real Agent Cost Lever
- Interaction Models Are the Next AI Developer Tool Interface
- Oak: A New Version Control System Built for AI Agents
- RFC 10008: The New HTTP QUERY Method Explained
- Six Paid Products in a Day: DD's Bet on Agent Infra for Small Teams
- How to Evaluate AI Agents in Practice: Trajectories, Tool Calls and Judges
Sources#
- Hex: How we built a lab to evaluate data agents - fetched June 20, 2026.
- Hacker News: We built a lab to evaluate data agents - checked June 20, 2026.
- Hacker News: Launch HN: TesterArmy - Agents that test web and mobile apps - used for opposing developer pushback, checked June 20, 2026.
- Ian Barber: LLMs are complicated now - used as adjacent evidence that modern model systems need composable, verifiable baselines.
- OpenAI Docs: Working with evals - fetched June 20, 2026.
- Anthropic Docs: Increase output consistency - fetched June 20, 2026.
Get the next deep dive like this in your inbox
One email a week on AI Agents and the rest of the AI dev stack. Free.
Read next on AI coding tools
The 98% Context Reduction Pattern
The agent context reduction pattern: keep intermediate state in code, files and execution environments, and return compact summaries and receipts to the model.
8 min readAgent Memory Benchmarks Are Not Enough
Agent memory benchmarks are not enough. Coding-agent memory has to prove recall, freshness, deletion and rollback under real development pressure.
9 min readLong-Running Agents Need Harnesses, Not Hope
Long-running coding agents need a harness: task contracts, scoped workspaces, logs, checkpoints, verification gates, and cost limits to recover from failure.
9 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.