Topic
GPU
All blog posts, tools, and guides about GPU from Developers Digest.
10 resources - 4 posts, 6 tools
Blog Posts
View in blog →
Distilling an LLM on One GPU: Offline Top-K Logits and a Fused Chunked KL Loss
LLM distillation on one GPU: cache the teacher's top-100 logits offline and use a fused chunked KL loss to cut a GPT-OSS 20B run from four nodes to one.
7 min read
AMD MI355X vs NVIDIA B200 vs B300 for Open-Weight Serving
AMD MI355X vs NVIDIA B200 vs B300 for serving Kimi K3's about 1.5TB of open weights: verified specs, the Wafer benchmark, and cost per token for each.
9 min read
ZLUDA 6: Running CUDA on AMD GPUs Is Now a Hobby Project
ZLUDA 6 runs unmodified CUDA apps on AMD GPUs and adds PhysX and Blender textures. How it compares to ROCm and HIP, and why hobby status matters.
5 min read
Self-Hosting Open-Weights Models: The Real Break-Even Math
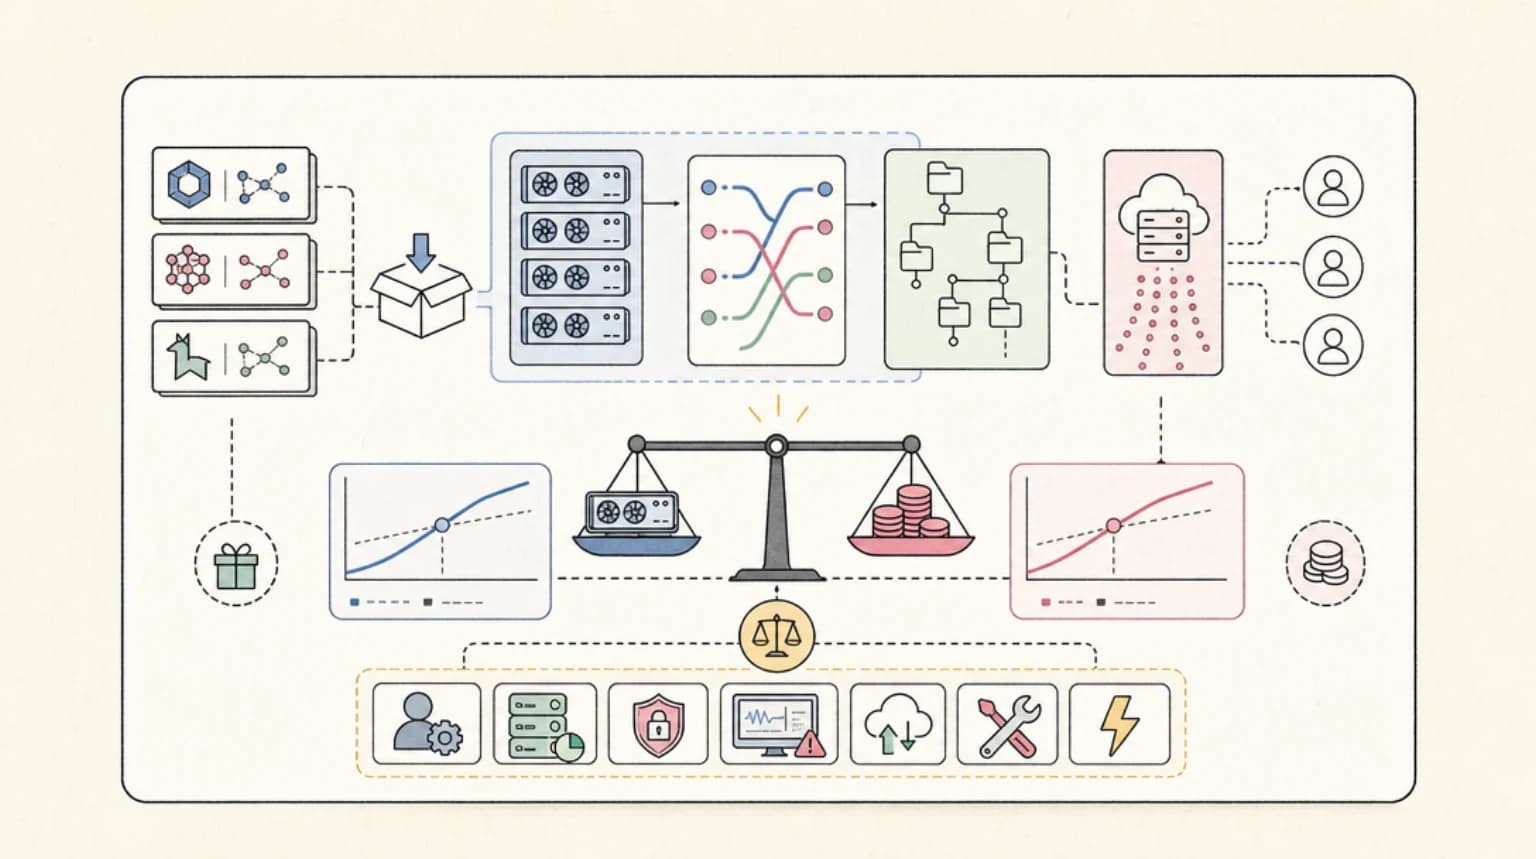
Self-hosting open-weights models like GLM-5.2, DeepSeek V4 or Llama: the break-even math against per-token API prices, with GPU costs and the hidden ops bill.
11 min read
Related Tools
All tools →Modal
Serverless cloud for AI/ML workloads. Write Python with decorators, Modal handles GPU provisioning and scaling. Sub-second cold starts. Scales to zero. $30/mo free compute.
InfrastructureReplicate
Run 50,000+ ML models with a simple API. No infrastructure management. Pay-per-second billing. Deploy custom models with Cog. Popular for image generation and audio.
InfrastructureTogether AI
Fastest inference for open-source models. 200+ models via unified API. Ranks #1 on speed benchmarks for DeepSeek, Qwen, Kimi, and Llama. Serverless pay-per-token pricing.
InfrastructureWarp
AI-powered terminal built in Rust with GPU rendering. Block-based output, natural language commands, Agent Mode for autonomous tasks. 700K+ developers. Free tier available.
ProductivityGhostty
Terminal emulator built in Zig with platform-native UI and GPU acceleration. 2ms key-to-screen latency. Metal on macOS, Vulkan/OpenGL on Linux. By the co-founder of HashiCorp.
ProductivityvLLM
High-throughput inference server for LLMs. PagedAttention memory management. The go-to for serious local or self-hosted serving.
Local AIKeep exploring
More on GPU
- - Modal - recommended GPU tool from the Developers Digest directory
- - Compare Tools - dive deeper across the Developers Digest knowledge base
- - All GPU articles in the blog archive
- - Developers Digest on YouTube - video tutorials covering GPU and more
Get Smarter About AI Dev
New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
One email per weekReal code, not theoryFree forever
Explore 844 topics
Browse All Topics