NVIDIA's Nemotron 3 Super in 6 Minutes
TL;DR
NVIDIA Nemotron 3 Super combines latent mixture of experts with hybrid Mamba layers - 120B total parameters, 12B active per token, 1M context and open weights.
Last updated: June 6, 2026
| Official Sources | |
|---|---|
| NVIDIA Nemotron Models | Official Nemotron model overview and access |
| HuggingFace Nemotron Collection | Model weights and deployment documentation |
| NVIDIA NIM | Managed inference for Nemotron models |
| NVIDIA AI Enterprise | Enterprise deployment and support |
| Mamba Architecture Paper | State space model architecture reference |
| NVIDIA Technical Blog | Architecture deep dives and benchmarks |
A New Take on Mixture of Experts#
NVIDIA released Nemotron 3 Super, and the architecture is worth paying attention to. It is a 120B parameter mixture-of-experts model, but only about 12B parameters are active per token. That ratio alone makes it interesting for inference costs. What makes it different from standard MoE is the "latent" approach - instead of routing raw tokens to experts, the model compresses tokens into a smaller representation before routing. Experts process these compressed inputs, which means you can run up to four times more experts at the same computational cost as a traditional MoE setup.
For model-selection context, compare this with Claude vs GPT for Coding: Which Model Writes Better TypeScript? and OpenAI vs Anthropic in 2026 - Models, Tools, and Developer Experience; the useful question is not only benchmark quality, but where the model fits in a real developer workflow.
The other architectural piece is the hybrid Mamba integration. NVIDIA blends transformer attention layers with Mamba state-space layers, getting transformer-quality reasoning with Mamba's linear scaling on long sequences. The result is a model that handles its full 1M token context window efficiently, especially in multi-user serving scenarios where throughput matters more than single-request latency.
Openness Done Right#
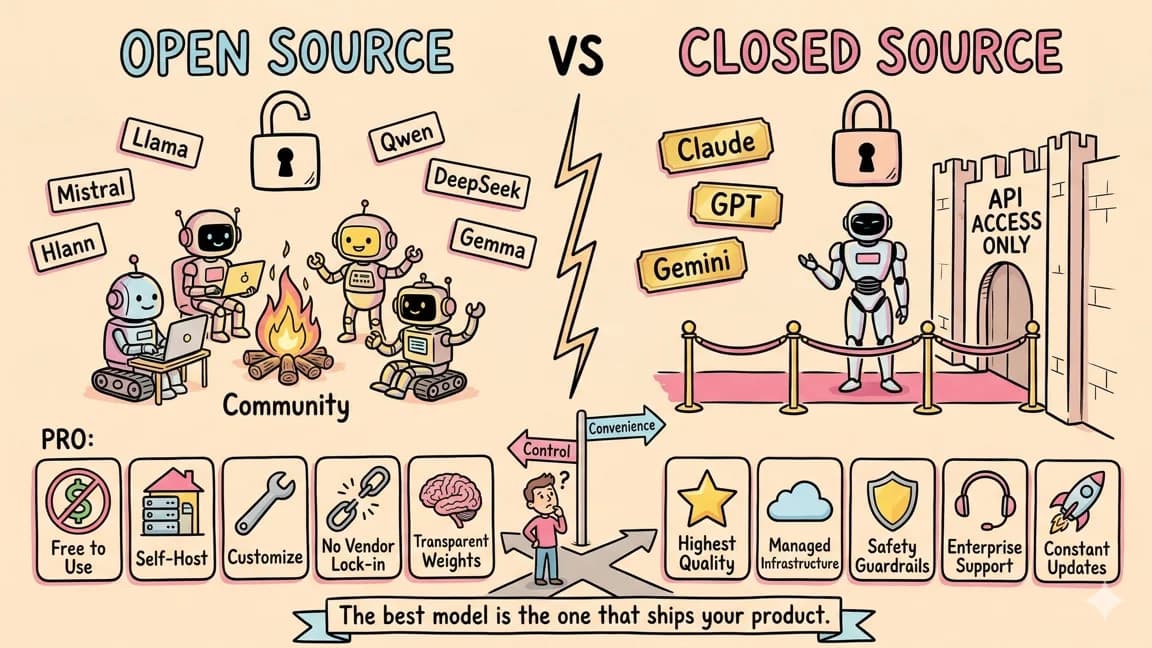
One of the more notable aspects of Nemotron 3 Super is how NVIDIA handled the release. You can download the weights, self-host, fine-tune, and commercialize. The training documentation is published. This is the kind of openness that actually matters for developers - not just a model card and an API endpoint, but the full package that lets you build on top of it.
NVIDIA positions this as a balance between openness and capability. Many open models sacrifice intelligence for permissive licensing, or gate the best checkpoints behind restrictive terms. Nemotron 3 Super ships competitive benchmarks alongside genuinely permissive access. For teams evaluating sub-250B models for production use, that combination narrows the field significantly.
Where to Run It#
The model is available today through several channels. Perplexity has it integrated. Hugging Face hosts the weights for self-hosting. Major cloud providers offer managed inference. NVIDIA's own developer tools and build platform provide direct access for testing before you commit to infrastructure.
Benchmark results show improved throughput and coding performance versus prior Nemotron releases and other models in the sub-250B class. The latent MoE architecture pays off most visibly in multi-user scenarios - the compressed expert routing means you serve more concurrent requests before hitting memory or compute ceilings. For teams running inference at scale, the 12B active parameter footprint per token translates directly to lower cost per query while maintaining the quality of a much larger model.
Check out the full breakdown in the video above, or grab the weights from Hugging Face and try it yourself.
FAQ#
What is Nemotron 3 Super?#
Nemotron 3 Super is NVIDIA's 120B parameter mixture-of-experts model with only 12B parameters active per token. It uses a latent MoE architecture that compresses tokens before routing to experts, allowing up to 4x more experts at the same computational cost as traditional MoE designs. The model also integrates a hybrid Mamba architecture, combining transformer attention with state-space layers for efficient handling of its 1M token context window.
How does latent mixture of experts differ from standard MoE?#
In standard MoE, raw tokens are routed directly to expert networks. Latent MoE compresses tokens into a smaller representation before routing. Experts process these compressed inputs, which reduces computational overhead per expert. This architectural change means you can run more experts for the same cost - NVIDIA claims up to 4x more experts at equivalent compute - while maintaining output quality.
What is the Mamba hybrid architecture?#
NVIDIA blends transformer attention layers with Mamba state-space layers. Transformers provide strong reasoning capabilities but scale quadratically with sequence length. Mamba layers scale linearly, making them efficient for long contexts. The hybrid approach gives Nemotron 3 Super transformer-quality reasoning with efficient handling of sequences up to 1M tokens, particularly useful in multi-user serving scenarios.
Is Nemotron 3 Super open source?#
Yes. NVIDIA released the weights with permissive terms that allow downloading, self-hosting, fine-tuning, and commercial use. The training documentation is also published. This level of openness - not just an API endpoint but the full model package - differentiates it from many other frontier models that gate their best checkpoints behind restrictive licenses.
What are the hardware requirements for Nemotron 3 Super?#
While the full 120B model requires significant GPU memory for self-hosting, the 12B active parameter footprint per token makes inference more efficient than the total parameter count suggests. For production deployments, NVIDIA NIM provides managed inference. HuggingFace hosts the weights for teams with their own infrastructure. Cloud providers also offer managed endpoints.
How does Nemotron 3 Super compare to other open models?#
Nemotron 3 Super targets the sub-250B open model segment with competitive benchmarks, particularly for coding and throughput. The latent MoE architecture provides better cost-per-query than dense models of equivalent quality. For teams evaluating Llama, Qwen, or DeepSeek alternatives, the combination of permissive licensing and inference efficiency makes Nemotron 3 Super worth benchmarking against your specific workloads.
Watch the Video#
Continue Reading#
- NVIDIA Nemotron 3 Super: A Developer's Guide to the 120B Hybrid MoE
- NVIDIA Nemotron Nano 2 VL: Open Source Vision-Language Model
- NVIDIA Nemotron Nano 9B V2: Local AI That Punches Up
- Tencent Hy3: A 295B Open MoE That Punches Above Its Weight
Sources#
Get the next deep dive like this in your inbox
One email a week on NVIDIA and the rest of the AI dev stack. Free.
Read next
NVIDIA Nemotron Nano 9B V2: Local AI That Punches Up
NVIDIA Nemotron Nano 9B V2 is a hybrid Mamba-transformer small model that runs on consumer GPUs. See how its reasoning controls, open data and tool use work.
7 min readLlama 4: The Complete Developer's Guide to Meta's Open Source Models
Llama 4 developer guide to Scout and Maverick, the open mixture-of-experts models from Meta: run them locally, call them via APIs and know when to pick them.
10 min readDeepSeek R1 and V3: The Developer's Guide to Open-Source AI
DeepSeek R1 and V3 developer guide: use the MIT-licensed models through the API, run them locally with Ollama and decide when they beat closed-source models.
9 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.