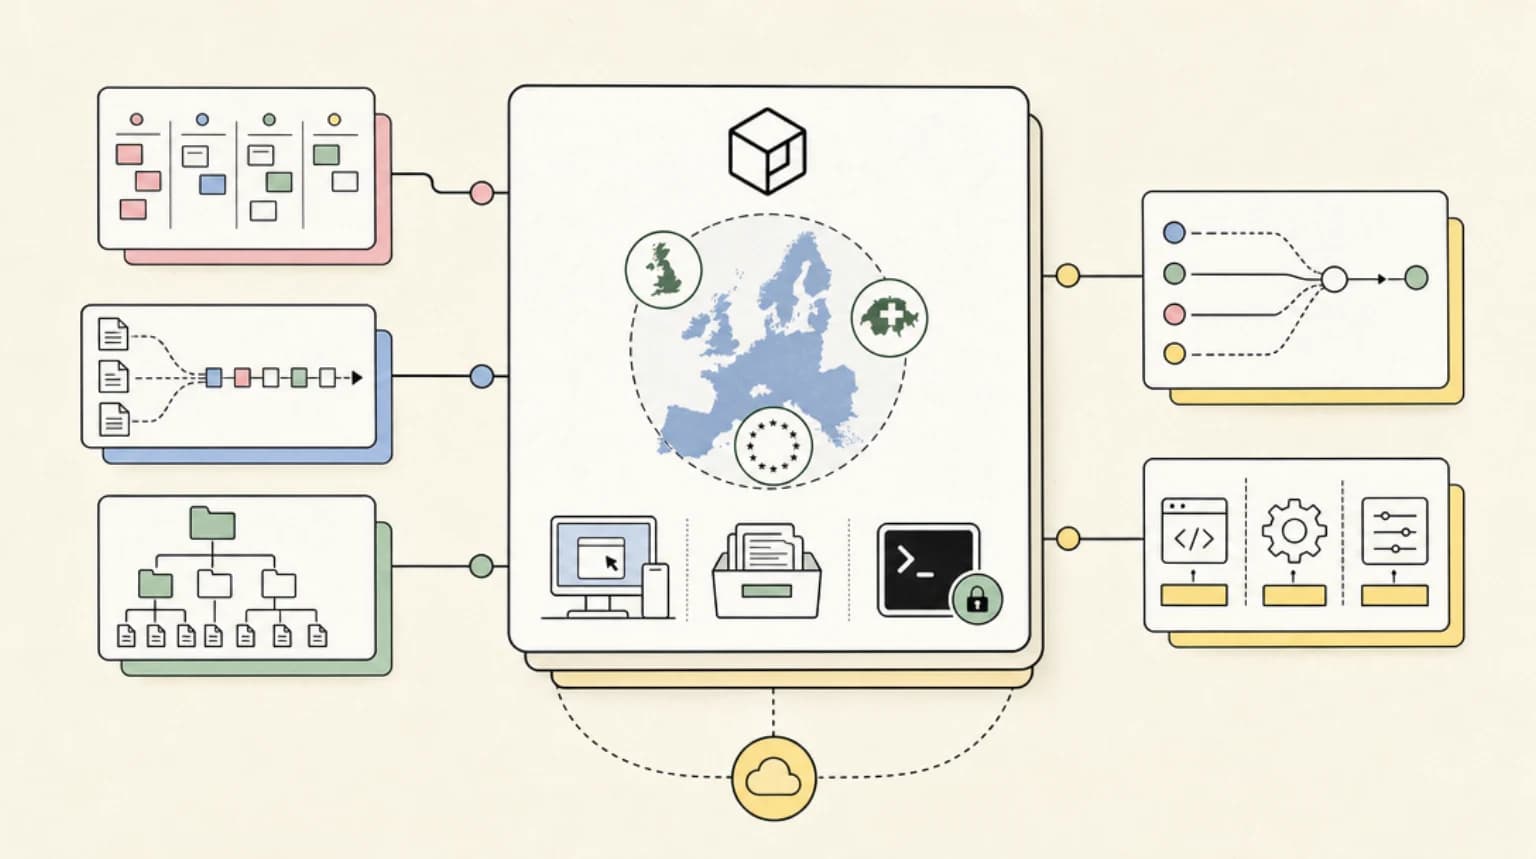
OpenAI Agents API Computer Use: Sessions, Approvals, Sign-in
TL;DR
OpenAI's Agents API can now operate web apps in a hosted session. Enable computer_use, approve each origin and handle sign-in in a five-minute window.
Last updated: October 17, 2026
Since September 29, 2026, the OpenAI Agents API (public beta) can give an agent a browser that OpenAI hosts. You turn it on with one tool entry, { "type": "computer_use" }, plus environment.desktop.enabled: true, and your app approves every new website origin and collects any sign-in details through a dedicated event that keeps credentials out of the model's input. Verdict: it is the fastest way to give a managed agent a real browser for testing flows and operating web apps through their UI, but origin approval is not per-action confirmation, Zero Data Retention is not supported, and passkey or QR-code sign-in does not work - so anything with irreversible actions still belongs in a browser you control.
A note on verification: the TypeScript below was type-checked with tsc --noEmit (strict, moduleResolution: bundler) against openai@7.36.0. No API key was available, so the examples were not executed against the live API.
What shipped and where it fits#
OpenAI's changelog entry for September 29 reads: "Agents can complete tasks in an OpenAI-hosted browser, with website access approvals and sign-in handled by your application." It lands on top of the Agents API, which went to public beta on September 10 as a way to "build agents with a managed Codex harness while OpenAI handles session orchestration, context compaction, and recovery." Sessions are durable server-side objects; you post input events to them and follow a stream of output events. Two constraints apply to the whole API, not only the browser: it currently supports data residency only in the United States, and it does not support Zero Data Retention (ZDR), even if you pick a self-hosted sandbox.
If you are still deciding between the managed Agents API and the code-first Agents SDK, read the September section of our OpenAI Agents SDK TypeScript guide first. The DevDay recap linked under Continue Reading covers everything else that launched alongside it.
OpenAI's guide breaks a browser task into five steps, and the Step sections below follow them one to one:
| Step | What your app does |
|---|---|
| 1. Create a session | Enable computer_use and a hosted desktop, save the session ID |
| 2. Stream events and send the task | Open the event stream, then post the user message |
| 3. Handle requests | Answer each origin access request, and any sign-in request |
| 4. Wait and verify | Wait for the main agent's turn to end and check the result |
| 5. Review and clean up | Read browser activity, then delete the session |
%% title: Agents API computer use architecture
flowchart LR
  App[Your app] -->|create session| API[Agents API]
  API --> Harness[Codex harness + gpt-6-astra]
  Harness --> Browser[OpenAI-hosted browser]
  Browser -->|origin or sign-in request| API
  API -->|requires_action| App
  App -->|approval event| API
The key design point: the browser never decides on its own to visit a new site or type a password. Both become required_actions on the session, and your application answers them.
Step 1: Create a browser session#
Prerequisites, per OpenAI's guide:
- An API key exported as
OPENAI_API_KEY. - The official SDK. The JavaScript examples here use the
openainpm package (type-checked against 7.36.0, which exposesclient.beta.agents.sessions). - For raw REST calls, the header
OpenAI-Beta: agents=v1on every request.
Three pieces turn a session into a browser session:
{ "type": "computer_use" }inagent.tools.environment.typeset to"openai_hosted".environment.desktop.enabledset totrue.
The tool also takes include_screenshots. It defaults to false, which only controls whether screenshots appear in API output - the agent observes the screen either way. Turn it on if you want to show progress in your UI.
Here is the create call from OpenAI's guide, with the agent instructions changed to a UI test:
# Requires Bash and jq. Keep the session ID for follow-up requests.
set -o pipefail
if ! session_id=$(curl --silent --show-error --fail https://api.openai.com/v1/agents/sessions \
  -H "OpenAI-Beta: agents=v1" \
  -H "Authorization: Bearer $OPENAI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "agent": {
      "model": "gpt-6-astra",
      "instructions": "Use the browser to test a web app's UI. Do not sign in or change any website data. Report each control you tried and whether it worked.",
      "tools": [{ "type": "computer_use", "include_screenshots": true }]
    },
    "environment": {
      "type": "openai_hosted",
      "desktop": { "enabled": true },
      "network": { "access": "enabled" }
    }
  }' | jq --exit-status --raw-output '.id // empty'); then
  echo "Session creation failed or its outcome is unknown. Do not retry automatically." >&2
  exit 1
fi
printf 'Session ID: %s\n' "$session_id"
Creating the session does not start a task. Nothing happens in the browser until you send a message. The TypeScript version in Step 2 sends a full UI test task, which is what this feature is best suited for: testing flows and operating web apps through their interface.
Lock down the network before you ship#
The example uses "access": "enabled", which is the default. For anything beyond a demo, use restricted. The hosted environment's network setting controls outbound access for both the browser and any code running in the sandbox:
network.access | Behavior |
|---|---|
enabled | Outbound access allowed (default) |
disabled | Outbound access blocked |
restricted | Only hosts in allowed_domains |
Restricted mode accepts 1 to 100 exact host names, such as api.example.com. No wildcards, protocols, paths or ports. Subdomains and redirect destinations need their own entries, which is the most common reason a restricted browser task stalls on a login redirect or a CDN-hosted asset.
Network policy and origin approval are separate layers. An origin your user approves is still blocked if the network policy does not allow it, and a host the network allows still needs origin approval. Think of the network policy as the ceiling you set at deploy time and origin approval as the consent your user gives at run time.
You can also set environment.container_size to small (1 vCPU, 1 GB), medium (2 vCPU, 4 GB, the default) or large (4 vCPU, 16 GB).
Step 2: Stream events and send the task#
Open the event stream first, then post the user message. The script below runs a whole UI test end to end, and Steps 3 to 5 unpack the request handling, end-of-turn checks and cleanup it performs. It creates a session with a restricted network, opens the event stream before sending the task so no events are missed, auto-approves only allowlisted origins and denies the rest, cancels any sign-in request (this UI test never signs in), logs browser activity, keeps the last screenshot, treats a failed or cancelled root turn as an error, and deletes the session only after a clean completion.
// browser-task.ts - type-checked against openai@7.36.0
import OpenAI from "openai";
import { writeFile } from "node:fs/promises";

const client = new OpenAI();

// Origins this app will approve without asking a human.
const ALLOWED_ORIGINS = new Set(["https://developers.openai.com"]);

const session = await client.beta.agents.sessions.create({
  agent: {
    model: "gpt-6-astra",
    instructions:
      "Use the browser to test a web app's UI. Do not sign in, submit forms or change any website data. Report each control you tried and whether it worked.",
    tools: [{ type: "computer_use", include_screenshots: true }],
  },
  environment: {
    type: "openai_hosted",
    desktop: { enabled: true },
    network: { access: "restricted", allowed_domains: ["developers.openai.com"] },
  },
});
console.log("Session ID:", session.id);

let completed = false;
let lastScreenshot: Buffer | undefined;
const handled = new Set<string>();

const events = await client.beta.agents.sessions.events.stream(session.id);
try {
  await client.beta.agents.sessions.events.create(session.id, {
    events: [
      {
        type: "agent.session.input.message",
        input: [
          {
            role: "user",
            content: [
              {
                type: "input_text",
                text: "Open https://developers.openai.com in the browser. Go to the Agents API quickstart, click the Copy button on the first code sample, use the page navigation to reach the next page, and report whether each control worked.",
              },
            ],
          },
        ],
      },
    ],
  });

  for await (const event of events) {
    switch (event.type) {
      case "agent.session.requires_action": {
        const current = await client.beta.agents.sessions.retrieve(session.id);
        for (const action of current.required_actions) {
          if (action.type !== "computer_use_approval_request") continue;
          if (handled.has(action.request_id)) continue;
          const request = action.request;
          if (request.type === "browser_origin_access") {
            const decision = ALLOWED_ORIGINS.has(request.origin) ? "approve" : "deny";
            console.log(`Origin ${request.origin}: ${decision}`);
            await client.beta.agents.sessions.events.create(session.id, {
              events: [
                {
                  type: "agent.session.input.computer_use_approval_request_result",
                  request_id: action.request_id,
                  response: { type: "browser_origin_access", decision },
                },
              ],
            });
          } else {
            // This test never signs in, so refuse any sign-in request.
            await client.beta.agents.sessions.events.create(
              session.id,
              {
                events: [
                  {
                    type: "agent.session.input.computer_use_approval_request_result",
                    request_id: action.request_id,
                    response: { type: "browser_authentication", action: "cancel" },
                  },
                ],
              },
              { maxRetries: 0 },
            );
          }
          handled.add(action.request_id);
        }
        break;
      }
      case "agent.session.turn.item.done": {
        const item = event.item;
        if (item.type === "computer_use_call") {
          console.log(item.title ?? "Browser activity", item.status);
          const output = item.output;
          if (output?.type === "computer_screenshot" && output.image_url.startsWith("data:image/jpeg;base64,")) {
            lastScreenshot = Buffer.from(output.image_url.split(",", 2)[1]!, "base64");
          }
        }
        break;
      }
      case "agent.session.turn.output_text.done":
        console.log(event.text);
        break;
      case "error":
        throw new Error(event.error.message);
      case "agent.session.failed":
      case "agent.session.environment.failed":
        throw new Error(`Agent lifecycle failure: ${event.type}`);
      case "agent.session.turn.failed":
        if (event.turn.subagent_id === null) throw new Error("Browser task failed");
        break;
      case "agent.session.turn.cancelled":
        if (event.turn.subagent_id === null) throw new Error("Browser task was cancelled");
        break;
      case "agent.session.turn.completed":
        if (event.turn.subagent_id === null) completed = true;
        break;
    }
    if (completed) break;
  }
} finally {
  events.controller.abort();
}

if (lastScreenshot) await writeFile("browser-screenshot.jpg", lastScreenshot, { mode: 0o600 });
if (completed) await client.beta.agents.sessions.delete(session.id);
A few details worth calling out:
- Stream first, then send. The stream is opened before
events.createposts the task, so the firstrequires_actioncannot slip past. - Root turn only. Turn events carry
turn.subagent_id. The check fornullmeans the script reacts to the main agent's turn, not a subagent's. - The
handledset stops the script from answering the samerequest_idtwice when severalrequires_actionevents arrive while a request is still listed.
Step 3: Handle origin and sign-in requests#
Both kinds of request arrive the same way: an agent.session.requires_action event, then a computer_use_approval_request entry in the session's required_actions. The request.type tells you which one it is: browser_origin_access or browser_authentication.
Approve each website origin#
The browser needs the user's approval before it accesses each new website origin, including public websites. Enabling network access does not approve these requests. The flow:
- On
agent.session.requires_action, retrieve the session. - In
required_actions, findcomputer_use_approval_requestentries whoserequest.typeisbrowser_origin_access. - Show
request.originandrequest.reason(which can benull), collect a decision, and post anagent.session.input.computer_use_approval_request_resultevent with the samerequest_idand aresponseof{ type: "browser_origin_access", decision }, wheredecisionisapprove,denyorcancel.
The allowlist in the Step 2 script is a stand-in. In a product, render request.origin and request.reason and let the user decide. Our post on approval fatigue covers how to keep those prompts meaningful so people do not click through every one.
%% title: Origin approval loop
sequenceDiagram
  participant App
  participant API as Agents API
  participant Browser as Hosted browser
  Browser->>API: needs new origin
  API-->>App: agent.session.requires_action
  App->>API: GET session (required_actions)
  App->>API: approval_request_result (approve, deny or cancel)
  API->>Browser: proceed or block
  API-->>App: turn.completed
What origin approval does not do#
This is the most important limit in the feature, and OpenAI states it plainly: origin approval does not enforce confirmation before individual actions. Once a user approves https://shop.example.com, the agent can click anything on that origin. If your app must guarantee confirmation before purchases, destructive changes or other consequential actions, OpenAI's guidance is to restrict the hosted browser to resources that cannot perform them, or to use a browser runtime you control. A confirmation function tool is weaker than it looks, because it relies on the agent choosing to call it.
OpenAI also says to treat website content as untrusted: a page cannot grant permission or override the user's instructions.
Handle sign-in without leaking credentials#
Some tasks need an authenticated browser. The Agents API handles this with a second request type, browser_authentication, and a submission path that keeps credentials away from the model.
Ground rules from the guide:
- Only the main agent can request browser authentication. Subagents cannot.
- Supported: email addresses, passwords and verification codes. Not supported: passkeys and QR-code sign-in. Sites that require those cannot complete sign-in through this flow.
A browser_authentication request carries:
| Field | Use |
|---|---|
reason | Why input is needed. Can be null. |
credential_origin | The destination the credentials are for. Can be null. |
fields | Inputs to render: id, label, type, required. Can be empty. |
options | Login methods: id, label, and field_ids naming the inputs each method needs. |
Sign-in is often several requests in a row. OpenAI's example is a site that first asks the user to choose between "Email me a code" and "Use a password" with no fields, then asks for an email address, then asks for the code. Each request has its own request_id and field IDs, so render each one fresh. If credential_origin is missing or unfamiliar and the user cannot verify it independently, OpenAI says to cancel.
To submit, post the same event type with a browser_authentication response, action: "submit", the field values, and selected_option when the request offers options. Disable automatic retries:
// sign-in.ts - type-checked against openai@7.36.0
import OpenAI from "openai";

const client = new OpenAI();

// Values come from your own masked sign-in form, never from a chat message.
export async function submitSignIn(
  sessionId: string,
  requestId: string,
  fields: { field_id: string; value: string }[],
  selectedOption?: string,
): Promise<void> {
  await client.beta.agents.sessions.events.create(
    sessionId,
    {
      events: [
        {
          type: "agent.session.input.computer_use_approval_request_result",
          request_id: requestId,
          response: {
            type: "browser_authentication",
            action: "submit",
            fields,
            ...(selectedOption ? { selected_option: selectedOption } : {}),
          },
        },
      ],
    },
    { maxRetries: 0 }, // never auto-retry credential submissions
  );
}
When the user chooses a method that has no inputs, call it with an empty fields array and the option ID. If the user declines, cancel with no fields and no selected_option:
{
  "events": [
    {
      "type": "agent.session.input.computer_use_approval_request_result",
      "request_id": "REQUEST_ID",
      "response": { "type": "browser_authentication", "action": "cancel" }
    }
  ]
}
Cancelling the request does not stop the task. To stop the task, cancel the turn.
The rules that matter in production:
- Values never reach the model. Submitted values stay outside the agent's model input and are left out of authentication response items in session history. That only holds if you use this event. Function-tool results are visible to the model and saved in history, so never route a password or code through a message or a function tool.
- Treat every value as sensitive, including email addresses. OpenAI says to mask inputs, keep values out of logs, analytics and saved UI state, and clear the form after submission.
- A
202is not a login. A202with an empty body means the submission was accepted, not that sign-in succeeded. Keep following events and check the task's result. - Five-minute expiry. Authentication requests expire after five minutes, and the owning turn can end while the user is still typing. Refresh the session before restoring a form.
- Retries are idempotent, edits are not. An identical retry with the same
request_iddoes not fill the form again. Changing values after acceptance returns409, and a new attempt needs a new request from the agent. - Size limits. Up to six field values per submission, each field once, up to 16,384 characters per value, and the serialized values plus selected option must fit within 120 KiB.
- Omit
turn_idfrom the submission event.
%% title: Browser sign-in handoff
sequenceDiagram
  participant User
  participant App
  participant API as Agents API
  participant Browser as Hosted browser
  Browser->>API: sign-in form needed
  API-->>App: requires_action (browser_authentication)
  App->>User: masked form + credential_origin
  User->>App: values
  App->>API: submit (maxRetries 0)
  API->>Browser: fills form, values not sent to model
  API-->>App: 202 accepted
  Note over App: keep streaming, verify result
Before you let any agent sign in as a user, run through our security checklist for connecting agent tools to decide what that account should be able to read, write and reach.
Step 4: Wait, verify and recover#
The task is finished when the main agent's turn ends: agent.session.turn.completed with a turn.subagent_id of null. The Step 2 script treats agent.session.turn.failed or agent.session.turn.cancelled on that root turn as an error, and stops on session or environment failure events. A completed turn still only means the agent stopped working, so check the reported result itself - for a UI test, that each control behaved as expected - before you act on it.
Recovery#
If your app disconnects or a response fails, retrieve the session and rebuild UI only for requests still in required_actions. Reconnecting must not automatically resend the task or an approval. The guide's status table:
| Result | What to do |
|---|---|
202 | Clear submitted values, follow events for the outcome |
400 | Check response type, selected option, field IDs and required values |
404 | Check session ID, request ID and response type, then retrieve the session again |
409 | Refresh the session: the request may have expired, the turn may have ended, or another response was accepted |
| Connection lost before acknowledgement | Treat acceptance as unknown, reconnect and retrieve the session before retrying |
Origin requests behave differently from sign-in requests. They stay pending for their owning turn with no five-minute timeout, you can retry the same decision if delivery fails, and changing an accepted decision returns 409. They also have no dedicated history items, so required_actions is the only place to find them.
Asking the user a question#
If the agent needs a choice from the user mid-task, define a function tool in agent.tools (OpenAI's example name is request_user_response). On requires_action, find the pending function_call, show its arguments, and return the answer with an agent.session.input.tool_result event using the action's turn_id and call_id. Remember that this channel is model-visible: questions and answers, never credentials.
Step 5: Review activity and clean up#
Read browser activity and screenshots#
Browser operations appear as computer_use_call items, with the same shape in the stream and in history:
| Field | Meaning |
|---|---|
id | Activity item ID |
turn_id | The turn that produced it |
title | Description of the activity, or null |
status | in_progress, completed, failed or incomplete |
output | Screenshot output, when available |
An activity item describes one tool operation. It is not the agent's final answer, and a completed item does not mean the turn completed. Use turn events for that.
With include_screenshots: true, a completed item's output is { "type": "computer_screenshot", "image_url": "data:image/jpeg;base64,..." }. Some operations return output: null even with screenshots on, so handle items without an image. Capture screenshots from agent.session.turn.item.done events while streaming, because retrieved history (GET /v1/agents/sessions/{id}/items, or client.beta.agents.sessions.items.list in the SDK) can omit image bytes. Screenshots can contain account data, so show them only to authorized users and keep them out of logs. That is why the Step 2 script writes the file with mode 0o600.
Continue or delete the session#
- Reuse the same session for follow-ups that need browser state such as login cookies. Cookies can expire, and recycling the environment clears browser state.
- Closing an event stream does not cancel the task.
- If activity and keep-alives stop for an hour, the sandbox can be deleted. That timeout is not configurable.
- When you are done, delete the session with
DELETE /v1/agents/sessions/{id}(orclient.beta.agents.sessions.delete). If deletion returns409while work finishes, wait and retry with a cap on attempts.
Gotchas and limits#
- No per-action confirmation. Origin approval is per site, not per click. OpenAI's two remedies: restrict the browser to resources that cannot take the consequential action, or run a browser you control.
- Website content is untrusted. Pages cannot grant permission or override instructions, but they can still try. Keep the network allowlist tight.
- No ZDR, US-only residency. This applies to the entire Agents API during the beta, including self-hosted sandboxes.
- No passkeys or QR sign-in. Sites that require them cannot be signed into through this flow.
- Subagents cannot sign in. Only the main agent can raise a
browser_authenticationrequest. - Five-minute sign-in window. Design your form for it, and refresh before restoring a half-filled form.
- Restricted networks need every hop. Login redirects, subdomains and asset hosts each need an
allowed_domainsentry. - Screenshots are off by default in API output and can be
nullwhen on. - Cost is containers plus tokens. OpenAI-hosted sandboxes use standard container rates, and model usage is billed separately. The pricing page lists containers at $0.03 (1 GB), $0.12 (4 GB), $0.48 (16 GB) and $1.92 (64 GB) per 20-minute session per container. The default
mediumsize has 4 GB of memory, so $0.12 per 20 minutes is the likely rate, but that mapping is our inference: the computer use guide lists no separate computer-use fee, so confirm on the pricing page before you budget. Token rates forgpt-6-astraare on the same pricing page.
Hosted browser vs your own browser#
OpenAI's main computer use guide has a routing table that makes the alternative explicit. Screenshots plus mouse and keyboard in your own browser or desktop means ComputerToolset with the Responses computer tool. Using page controls and tabs in your own browser means BrowserToolset. "Run a browser hosted by OpenAI" points to the Agents API guide covered here.
| Agents API hosted browser | Responses + your browser (ComputerToolset) | |
|---|---|---|
| Who runs the browser | OpenAI, inside the session's hosted sandbox | You, through a driver such as Playwright |
| Control granularity | Approve or deny per origin | beforeAction callback on every action, plus maxSteps |
| Credentials | Dedicated sign-in event, values kept out of model input and history | Handled by your own runtime |
| State | Durable session, cookies kept until the environment is recycled | Whatever your runtime keeps |
| Setup | One tool entry and a hosted environment | openai@7.33.0 and playwright@1.61.1 (Node 22.6+), or openai==3.31.0 and playwright==1.61.0 (Python 3.11+) |
| Orchestration | OpenAI handles sessions, compaction and recovery | Your application owns the loop, permissions and cleanup |
| Data | No ZDR, US-only residency during the beta | Examples set store: false; /v1/responses is ZDR-eligible with documented limitations |
| Model notes | Examples use gpt-6-astra | For GPT-6 Astra, OpenAI recommends code execution (the model writes Playwright or PyAutoGUI code) over the structured computer tool, which remains supported |
Each path is good at something different. The hosted browser removes the infrastructure you would otherwise build: no browser fleet, no session store, no compaction logic, and a sign-in protocol that keeps secrets out of the transcript without extra work. The Responses path trades that convenience for control. Because ComputerToolset.run hands every proposed action to your beforeAction callback, you can block a click on a Buy button deterministically instead of hoping the agent asks first.
OpenAI's "run safely" guidance for the Responses path is a useful checklist for either option: restrict the environment, treat screen content as untrusted, confirm consequential actions (typing sensitive information into a form counts as transmitting it), and bound the run with step, time or cost limits.
The decision rule: use the hosted browser when you want OpenAI to run the harness and the browser, and per-origin consent is a sufficient control. Use your own runtime when you must gate individual consequential actions, need a sign-in method the hosted flow does not support, or need ZDR. On that last point, OpenAI's data controls page lists /v1/agents as not ZDR-eligible and /v1/responses as ZDR-eligible with documented limitations, so confirm your tool mix qualifies before you rely on it.
%% title: Which computer use path
flowchart TD
  Start[Browser task] --> Q1{Need per-action confirmation?}
  Q1 -->|yes| Own[Responses + your browser]
  Q1 -->|no| Q2{Need ZDR?}
  Q2 -->|yes, check limits| Own
  Q2 -->|no| Q3{Need passkey or QR login?}
  Q3 -->|yes| Own
  Q3 -->|no| Hosted[Agents API hosted browser]
If you are comparing providers, Anthropic's computer use tool works like the Responses path: per Anthropic's documentation, it is a client toolset and "your application runs every call in an environment you control." Our Claude computer use guide walks through it, and the computer use toolset GA guide covers the current API version. And if you are choosing between pixels and code, the StateAct research write-up explains why program state often beats screenshots, which lines up with OpenAI recommending code execution for Astra on the Responses side.
FAQ#
Do I need to approve public websites too?#
Yes. The hosted browser needs approval before it accesses each new website origin, including public ones. Setting network.access to enabled does not approve anything; it only allows the traffic once an origin is approved.
Does the model see the passwords my users type?#
Not if you use the dedicated event. Per OpenAI, values submitted through a browser_authentication response stay outside the agent's model input and are left out of authentication response items in history. Messages and function-tool results are model-visible and stored, so never send credentials through them.
Can I make the agent ask before it clicks Buy?#
Not through origin approval, which is per site. OpenAI's options are to restrict the hosted browser to resources that cannot make the purchase, or to run your own browser, where the Responses ComputerToolset gives you a beforeAction gate on every action. A confirmation function tool works only if the agent decides to call it.
What does it cost?#
Container time plus model tokens. OpenAI-hosted sandboxes use standard container rates (the pricing page lists $0.12 per 20-minute session for a 4 GB container, the memory of the default medium size), and model usage is billed separately. The docs list no separate computer-use line item, so check the pricing page for current rates.
Is it production ready?#
The Agents API is a public beta, with US-only data residency and no ZDR. Our read: it is a reasonable fit today for internal tools and UI test flows, such as checking that a staging app's buttons, navigation and forms behave as expected. For regulated data or irreversible actions, the beta constraints and the lack of per-action confirmation point to your own runtime.
Sources#
- OpenAI: Agents API computer use guide
- OpenAI API changelog
- OpenAI: Agents API overview
- OpenAI: OpenAI-hosted sandboxes
- OpenAI: Computer use (Responses API)
- OpenAI API pricing
- OpenAI: Data controls in the OpenAI platform
- Anthropic: Computer use tool
- openai on npm (7.36.0)
Continue Reading#
- OpenAI Agents SDK in TypeScript - when to pick the managed Agents API over the code-first SDK.
- OpenAI DevDay 2026 recap - everything else that launched alongside the Agents API.
- Claude computer use - how Anthropic's approach differs when you run the screen yourself.
Get the next deep dive like this in your inbox
One email a week on ai-agents and the rest of the AI dev stack. Free.
Read next on AI coding tools
OpenAI DevDay 2026 Recap: What Shipped and What to Test
Everything OpenAI announced at DevDay 2026: GPT-6.1 Sol at $2/$10, Ultrafast, Decisions API, Agents API, cloud Codex, and what to test first.
8 min readOpenAI Agents SDK for TypeScript: A Practical Guide
OpenAI Agents SDK for TypeScript, explained with code: agents, Zod tools, structured outputs, multi-agent handoffs, streaming and human approval steps.
10 min readClaude Computer Use: AI That Controls Your Desktop
Anthropic's computer use feature lets Claude see your screen, move the cursor, click, and type. Here is how it works, when to use it, and how to set it up.
6 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.