OpenAI's June API Updates Are Really a Control-Plane Upgrade
TL;DR
OpenAI June 2026 API updates as an agent control plane: workload identity, Admin APIs, Secure MCP Tunnel, moderation scores, billing and cache retention.
OpenAI's June API changelog is easy to read as a pile of unrelated entries.
Moderation scores landed in the Responses API. Container sessions moved to per-minute billing. OpenAI models showed up behind an OpenAI-compatible Responses endpoint on Amazon Bedrock. Prompt cache retention changed. Admin APIs got spend, model, retention, hosted-tool, and billing controls. Workload identity federation removed another reason to park long-lived API keys in production. Secure MCP Tunnel gave enterprise teams a way to connect private tools without putting them on the public internet.
That is not random plumbing. It is the shape of an agent control plane.
Last updated: June 28, 2026
The model news will always get more attention, but production teams do not fail because they forgot to name the newest model. They fail because nobody can answer boring questions cleanly:
- Which workload called the model?
- Which tools could it reach?
- Which models were allowed?
- What did the run cost?
- Was input and output moderated?
- Did a private MCP server need public exposure?
- How long did prompt cache data stick around?
- Did hosted containers bill like a fixed block or an actual job?
OpenAI's late-May and early-June platform updates start answering those questions. That matters for anyone building on the Responses API, running Codex, comparing OpenAI versus Anthropic, or trying to make agent infrastructure boring enough for a real platform team.
The Useful Pattern: More Knobs Before More Autonomy#
The agent market loves autonomy language. The platform work that makes autonomy usable is less glamorous: identity, spend controls, allowlists, moderation, private networking, billing granularity, and audit surfaces.
That is the frame for these updates:
| Update | What it controls | Why agent teams should care |
|---|---|---|
| Workload identity federation | Authentication | Replace long-lived keys with short-lived workload tokens |
| Admin API expansion | Org policy | Manage spend alerts, model allowlists, retention, hosted-tool permissions, and billing lines |
| Secure MCP Tunnel | Private tools | Connect private MCP servers without exposing them publicly |
| Moderation scores | Safety gates | See input and output moderation results in the generation response |
| Container per-minute billing | Runtime cost | Align hosted tool cost with shorter tasks |
| 24h prompt cache retention default | Latency and cost | Improve reuse for non-ZDR orgs, with a data-retention tradeoff |
| Bedrock Responses endpoint | Enterprise routing | Let AWS-centered teams use OpenAI models through Bedrock patterns |
None of these replaces an application architecture. Together, they move OpenAI's API surface closer to the operational layer teams already expect from cloud infrastructure.
That is the difference between "we can call a model" and "we can let an agent act inside a governed system."
Workload Identity Is the Key-Rotation Story#
The most obviously enterprise-shaped update is workload identity federation. OpenAI describes it as a way for trusted workloads to exchange externally issued identity tokens for short-lived OpenAI access tokens.
That sounds like identity plumbing because it is. It is also exactly the kind of plumbing that makes agent workloads easier to approve.
The older pattern is familiar:
- Create an API key.
- Store it in a secret manager.
- Inject it into jobs, containers, CI, or serverless functions.
- Rotate it on a calendar, after an incident, or not often enough.
Workload identity changes the ownership model. A workload running in a cloud or Kubernetes environment can prove what it is using its native identity layer, then receive a short-lived OpenAI credential. The application no longer needs to carry a standing secret for every call.
This is not a flashy developer-experience feature. It is a procurement feature, a security-review feature, and a blast-radius feature.
For agents, the blast-radius angle is the important one. A long-running tool-using agent should not inherit a permanent organization credential just because it needs to call a model. Short-lived workload credentials make it easier to scope, revoke, and reason about the execution environment.
That connects directly to the argument in AI agent containment needs a capability ledger: the hard part is not only sandboxing. It is proving which actor had which capability at the moment it acted.
Admin APIs Turn Policy Into Something Agents Can Obey#
OpenAI's May 26 changelog entry says the Admin API gained capabilities for spend alerts, model allowlists, data retention settings, hosted tool permissions, and granular billing line items.
That list is easy to skim past. It is also the list platform owners need before they let agent workloads spread.
Spend alerts matter because agent loops can turn a mistake into a bill. Model allowlists matter because not every workload should be free to pick the most expensive or least-reviewed model. Data retention settings matter because agent prompts often include private code, customer context, logs, or business data. Hosted tool permissions matter because a model call with shell, code execution, file search, or web search is not the same risk as a plain text completion. Billing line items matter because aggregate spend is not enough when multiple products, teams, and automated jobs share one provider.
That is why this update is more interesting than a dashboard screenshot. API-controlled policy can be wired into platform workflows:
- pre-production checks that confirm a project has the right model allowlist
- deployment gates that fail if hosted tools are broader than expected
- daily spend anomaly jobs that watch agent projects separately from human chat usage
- quarterly retention reviews that can be checked in code
- per-product cost attribution that does not depend on humans tagging every run manually
The same theme shows up in frontier model API pricing: price tables are not enough. Teams need budget controls that match the way agents actually run.
Secure MCP Tunnel Is the Private-Tools Story#
MCP has the right developer shape: tools live behind a protocol instead of inside every prompt. The enterprise objection is just as obvious: many useful tools are private.
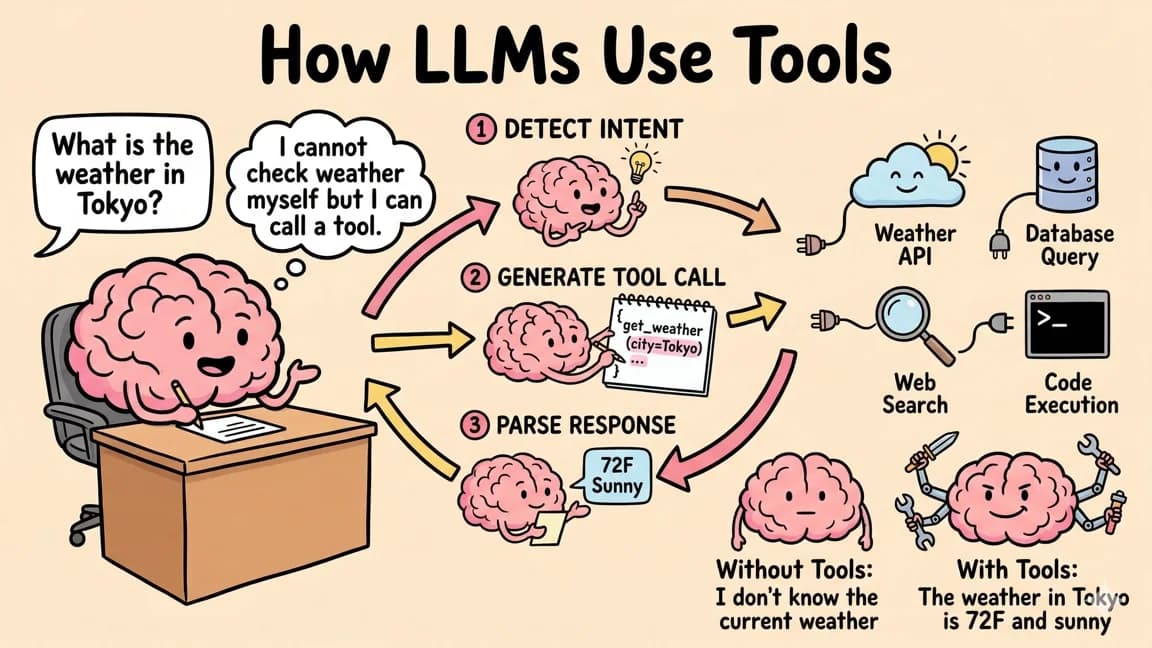
OpenAI's Secure MCP Tunnel addresses that gap for enterprise customers by using a customer-hosted tunnel client. The pitch is straightforward: supported OpenAI products can connect to private or on-prem MCP servers without the customer exposing those servers to the public internet.
This is the practical version of a problem we covered in zero-touch OAuth for MCP. Tool access is not only a protocol problem. It is a network, identity, authorization, and audit problem.
The strongest argument for the tunnel is not convenience. It is separation of concerns:
- OpenAI-hosted products do not need direct public access to internal tools.
- The customer keeps a controlled tunnel endpoint in their environment.
- MCP servers can remain inside private networks.
- Platform teams can review one connection pattern instead of many one-off public exposures.
There is a tradeoff. A vendor-specific tunnel is not the same thing as a portable MCP deployment story. Teams that want provider-neutral agent infrastructure still need to ask how this compares with direct MCP server hosting, private gateways, and client-side agent runtimes.
But for companies already standardizing on OpenAI products, Secure MCP Tunnel answers a real blocker: "How do we let the agent use internal tools without publishing the tools?"
Moderation Scores Move Safety Into the Response Path#
On June 4, OpenAI added moderation scores to both the Responses API and Chat Completions API. The changelog says developers can pass a moderation object and receive moderation results for both model input and generated output in the same response.
That is a small API shape with a large product implication.
Many agent systems treat safety as a separate pre-flight or post-flight call. That can work, but it often creates awkward plumbing: one call for input moderation, one generation call, another moderation call, then an application-specific decision about whether to show, store, retry, escalate, or block.
Putting moderation results into the response path makes the safety signal easier to attach to the run record. That matters for:
- customer-support agents that need output review
- code agents touching security-sensitive repositories
- internal assistants that summarize private documents
- tool-using agents that should escalate risky turns
- evaluation pipelines that need to compare safety behavior across model and prompt changes
The key is not to treat the score as a magic permission slip. It is a signal. The application still needs policy: what thresholds block output, what thresholds route to a human, what gets logged, and what gets dropped.
This is the same reason agent evals need baseline receipts. A system is only governable if the decision points leave evidence.
Container Billing Finally Matches Short Jobs Better#
The June 2 pricing change is easy to underrate. OpenAI says eligible container sessions now bill per minute with a five-minute minimum instead of the full 20-minute session rate. The underlying per-minute rate stays the same.
For hosted tool and agent workflows, that changes the cost shape.
Many agent jobs are bursty. They need a shell, a code interpreter, or a short-lived execution environment for a few minutes, not a 20-minute block. Fixed session billing punishes short tasks and encourages awkward batching. Per-minute billing with a five-minute floor is still not free, but it is closer to how these jobs actually run.
The practical takeaway is simple: revisit the economics of short hosted-tool workflows before assuming a self-hosted sandbox is always cheaper.
This does not remove the need for cost controls. If anything, it makes them more important because shorter jobs become easier to justify. Pair the pricing change with the Admin API's spend and billing controls, then decide which tasks belong in hosted containers and which belong in your own runtime.
Prompt Cache Retention Is a Cost Win With a Governance Footnote#
On May 29, OpenAI changed prompt_cache_retention so that organizations without zero data retention enabled default to 24h instead of in_memory. The reason is clear: longer cache retention can improve reuse, latency, and effective cost for repeated prompts.
For agent teams, that is useful. Agents often reuse the same system instructions, tool definitions, rubric blocks, repository context, or policy preambles. Better cache reuse can make repeated runs cheaper and faster.
But the default deserves a governance note. Longer retention is not only an optimization. It is a data-handling choice.
If your organization is not on ZDR, ask:
- Which prompts are cacheable?
- Do system prompts include private policy or customer data?
- Are repository summaries, logs, or traces being reused?
- Does the retention behavior match your internal data classification?
- Should sensitive workflows override defaults?
The tradeoff is not scary by itself. It just needs to be deliberate. Cost and latency improvements should not sneak in as unreviewed retention policy.
The Bedrock Piece Is About Procurement, Not Just Models#
OpenAI's June 1 changelog says OpenAI models are available in Amazon Bedrock through an OpenAI-compatible Responses API endpoint, with supported models and features varying by AWS Region.
That is not just a routing option. For some teams, it changes the buying path.
AWS-centered organizations often care less about whether an API call is aesthetically pure and more about whether it fits existing identity, billing, procurement, networking, and compliance workflows. Bedrock can make the OpenAI conversation easier for teams already operating inside AWS controls.
This also sharpens the competition with Anthropic. We have covered cases where Bedrock routing creates real boundary questions for Claude's newer models, especially around data retention and regulated workloads. OpenAI's Bedrock path should be evaluated on its own exact feature and region limits, but the direction is clear: model providers are fighting for the enterprise control plane, not only the benchmark chart.
What To Do With This If You Build Agents#
If your team is already on OpenAI, do not treat these updates as changelog trivia. Turn them into a platform checklist:
- Replace standing API keys in production agents with workload identity where available.
- Split human, CI, batch, and autonomous-agent projects so billing and policy are visible.
- Use model allowlists instead of letting every workload choose every model.
- Review hosted tool permissions separately from model permissions.
- Decide whether 24-hour prompt cache retention is acceptable for each workload class.
- Attach moderation scores to run records where safety review matters.
- Put private MCP servers behind a governed tunnel or gateway, not a public quick fix.
- Recalculate hosted container costs for short jobs under the new five-minute floor.
That checklist is the story. The more autonomy you give an agent, the more boring the surrounding platform needs to become.
FAQ#
What changed in OpenAI's June 2026 API updates?#
OpenAI added moderation scores to generation responses, changed eligible container sessions to per-minute billing with a five-minute minimum, made OpenAI models available through an Amazon Bedrock Responses endpoint, and recently added workload identity federation, expanded Admin APIs, Secure MCP Tunnel, IP allowlist management, and longer prompt-cache retention defaults.
Why do these updates matter for AI agents?#
Agents need more than model quality. They need identity, scoped tool access, cost controls, model allowlists, moderation signals, private-network access, retention policy, and billing attribution. These updates add pieces of that operational layer.
Is Secure MCP Tunnel the same as self-hosting MCP servers?#
No. Secure MCP Tunnel is an OpenAI enterprise connection pattern that lets supported OpenAI products reach private MCP servers through a customer-hosted tunnel client. Self-hosting MCP servers is broader and may be more portable across providers, but it requires your own gateway, identity, and network design.
Should every team use 24-hour prompt cache retention?#
No. Longer cache retention can improve cost and latency, but it is also a data-handling decision. Teams should review whether cached prompt content includes sensitive code, customer data, internal policy, or logs before relying on the default.
Continue Reading#
Sources#
Get the next deep dive like this in your inbox
One email a week on OpenAI and the rest of the AI dev stack. Free.
Read next on AI coding tools
Assistants to Responses API: A Migration Field Guide
Migrate from the OpenAI Assistants API to the Responses API: a tested plan covering code, state, threads, tool-use parity, and an eval-gated cutover.
13 min readOpenAI Codex, Managed Agents, and AWS: What Developers Should Watch
OpenAI is moving Codex from a coding assistant into an enterprise agent platform. Here is what changed with Codex, Managed Agents, AWS, and the Responses API.
8 min readOpenAI vs Anthropic in 2026 - Models, Tools, and Developer Experience
A developer's comparison of OpenAI and Anthropic ecosystems - models, coding tools, APIs, pricing, and which to choose for different use cases.
18 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.