How OpenAI Built GPT-Live: Full-Duplex Voice, WARP, and the Death of the Turn Detector
TL;DR
How OpenAI built GPT-Live: a full-duplex voice model with no turn detector, Go on the media path, stateful handoffs, and the new WARP WebRTC transport.
Last updated: October 20, 2026
Updated October 20, 2026: GPT-Live is now in the API. OpenAI's pricing page lists gpt-live-1 at $0.05 per minute and says "voice sessions are billed per second, without rounding up to a whole minute. Backend model and tool usage is charged separately." The FAQ and the platform paragraph below now reflect that; see how it compares with other voice agent options in our voice agent platforms directory.
OpenAI shipped GPT-Live to ChatGPT users on July 9, and yesterday it published the engineering story behind the system: How we built a realtime system for responsive voice AI in six months. The launch post told you what GPT-Live is. This one tells you how it stays responsive, and the details matter more than the announcement. Three things stand out: the turn detector is gone, the media path was rewritten in Go, and the transport layer is being standardized at the IETF.
Full-duplex means no turn detector#
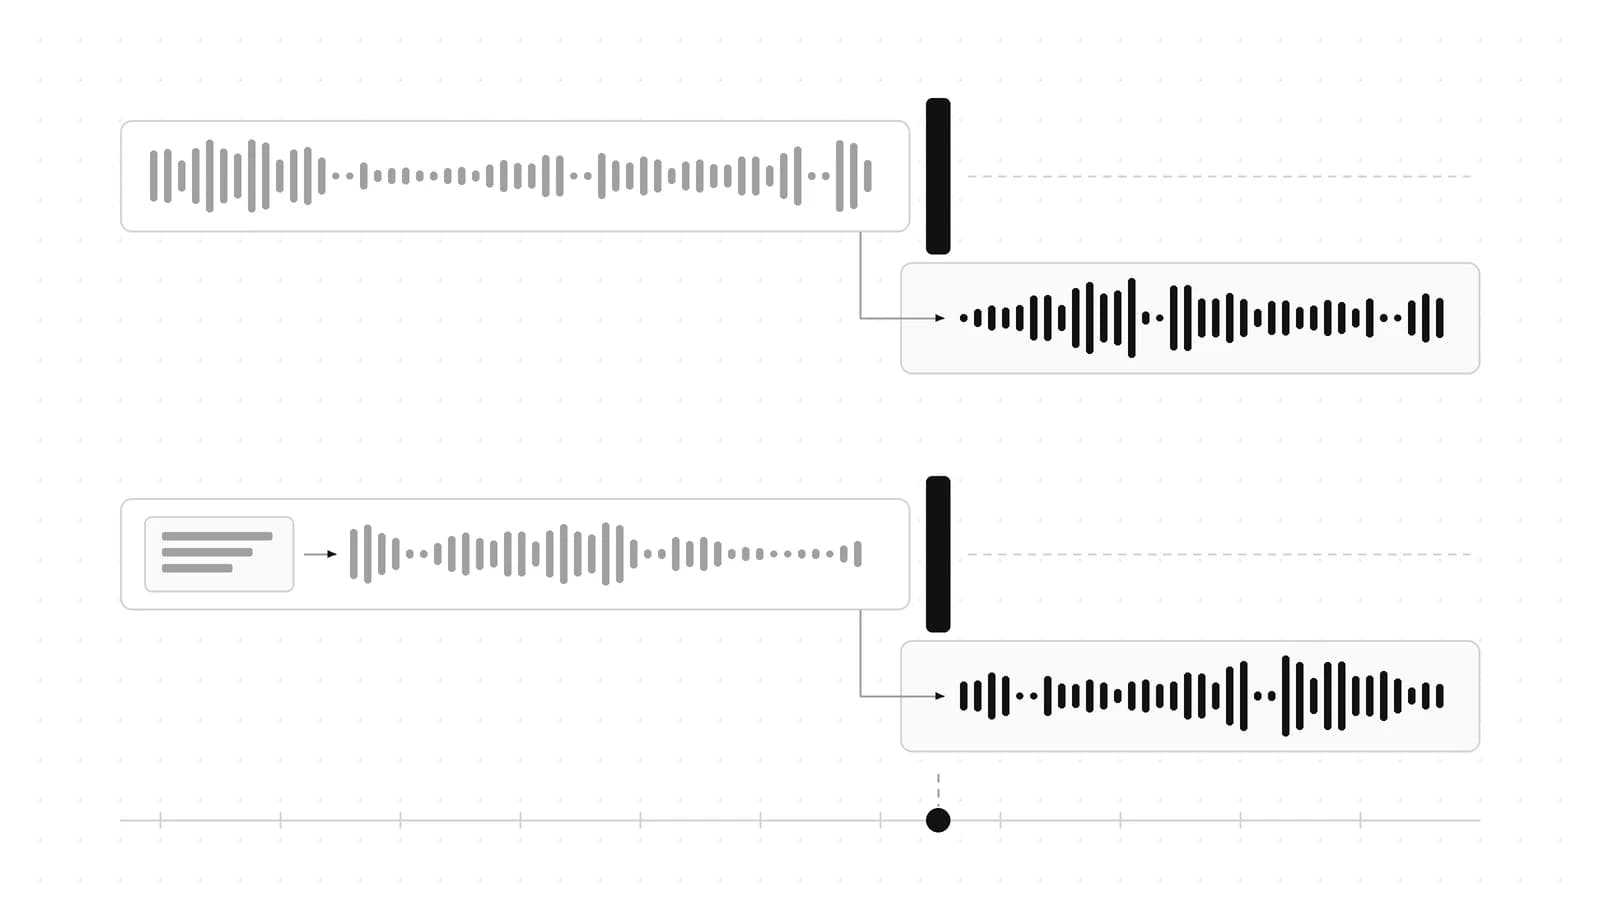
Previous voice systems, including OpenAI's own, were turn-based. A small turn-detector model guessed when the user had stopped speaking, and only then could the large language model start producing a response. The detector had a hard job: guess too soon and you cut the user off; guess too late and the reply feels sluggish.
GPT-Live removes the detector from the audio path entirely. Its voice model is full-duplex, so it listens and speaks at the same time. Audio streams into the model and speech streams out, with no discrete blob boundary. When the user wants deeper reasoning or tool use, GPT-Live delegates to a frontier model, currently GPT-5.5, on a separate asynchronous path and folds the result back into the conversation without pausing it.
That two-model design is the part with real system consequences. The voice model can keep the exchange moving while GPT-5.5 reasons, but it cannot hide an arbitrarily slow response, so OpenAI treats the whole delegation loop, routing, prompt processing, inference, and tool calls, as part of the responsiveness budget. When a voice session starts, the application server creates an inference session for the frontier model and prefills it with the conversation context, so the prompt is fully processed before the first delegated request. Session affinity and prompt caching keep later calls fast. Since October 15, 2026, a session can also delegate fast classification straight to the Decisions API; see our guide to GPT-Live native Decisions delegation.
The media path: Go, stateful inference, seamless handoff#
The engineering post is unusually concrete about stack choices. The media frontend and inference logic were rewritten in Go, replacing a Python asyncio implementation, and OpenAI reports the new system's p95 frame delivery now matches the previous system's p50. That is the kind of number you can actually build a decision on.
Streaming inference introduces a problem batch inference never had: statefulness. A voice session can run for a long time while model instances spin up and down with demand. OpenAI's answer is a handoff mechanism. When a transition is needed, the system warms a replacement model instance, prefills it with the current session context, runs inference on both in parallel, and cuts over when the new instance is ready. The same mechanism handles context compaction: when a long conversation approaches the context limit, the system compacts the history and prepares a replacement instance instead of stalling the live session to rebuild the KV cache. The conversation never hears the transition.
The post's most useful reframe is about capacity. Under load, OpenAI learned that voice capacity cannot be reduced to GPU throughput. Voice sessions stay open and send frames continuously, so CPU-side stream handlers, queues, and network paths saturate before inference does. The question shifted from "how many requests can a GPU handle" to "how many concurrent sessions can the system sustain while keeping every frame on schedule."
WARP and Instant Connect: transport as a standard#
WebRTC is the transport foundation, and OpenAI kept it, but it found the vanilla handshake too expensive. WebRTC predates the round-trip-minimizing philosophy of QUIC, and its stacked protocols repeat work, including duplicated anti-DoS mechanisms. So OpenAI designed WARP as a set of open specifications being advanced through the IETF's TSVWG working group, with support already landed in libwebrtc and Pion. On top of it, Instant Connect removes the SDP signaling exchange from the critical path: parameters are pre-negotiated, and the server can materialize a session when the first media packet arrives, with the standard signaling flow as fallback. The client can start a session with a single UDP packet.
That matters beyond ChatGPT. An open, IETF-track transport for realtime AI media is infrastructure, and OpenAI says the architecture is becoming a broader platform, and as of October 2026 gpt-live-1 is listed on OpenAI's API pricing page at $0.05 per minute. That makes it a sibling to the Realtime API playbook we covered in our Realtime API guide rather than a replacement, and the WARP work means the transport may be usable by non-OpenAI systems too.
How it was tested#
One of the quieter sections describes the silent test. OpenAI routed a small, gradually increasing share of production ChatGPT Voice sessions to a shadow path running the new system in read-only mode, without changing what users heard. That surfaced failure classes short load tests missed: long sessions exposed memory and persistence pressure, reconnects exercised state restoration, and disconnects revealed races in the shutdown handshake. It also forced a change to observability, since aggregates hid unhealthy individual engines. The methodology, shadow traffic at production scale before any user sees the new path, is a template worth borrowing for any stateful streaming service.
My take#
The turn detector was the last piece of voice AI that treated speech as text. GPT-Live's full-duplex model is the architectural cleanup the whole category needed, and the engineering post is a rare window into what it takes to make a stateful streaming system survive production: prefilled delegation sessions, handoff instead of interruption, and a capacity model measured in concurrent sessions, not requests. The Go rewrite with a p95-to-p50 gain is the single most actionable datapoint here, and the context-handoff design is the voice-flavored version of the context reduction patterns we cover for text agents. When the GPT-Live API opens, expect realtime voice to get the same treatment agents did: a fast model for the loop and a frontier model behind an async boundary, which is exactly the routing shape we see winning everywhere else. Since October 16, 2026 you can also give GPT-Live a custom voice from a text description - see our guide to OpenAI prompt-to-voice.
FAQ#
What is GPT-Live?#
GPT-Live is OpenAI's third-generation voice system, shipped to ChatGPT users on July 9. Its voice model is full-duplex, so it listens and speaks at the same time, and it delegates deeper reasoning and tool use to a frontier model, currently GPT-5.5, on a separate asynchronous path before folding the result back into the conversation.
Why did GPT-Live remove the turn detector?#
Turn-based systems relied on a small model to guess when the user had stopped speaking, and only then could the language model start responding. Guessing too soon cut the user off and guessing too late made replies feel sluggish. A full-duplex model streams audio in and speech out continuously, so there is no turn boundary to guess.
What is WARP?#
WARP is a set of open transport specifications OpenAI designed on top of WebRTC and is advancing through the IETF's TSVWG working group, with support already landed in libwebrtc and Pion. Combined with Instant Connect, which pre-negotiates parameters and takes SDP signaling off the critical path, a client can start a session with a single UDP packet.
Can developers use GPT-Live through an API?#
Yes. OpenAI's API pricing page lists gpt-live-1 at $0.05 per minute, and says "voice sessions are billed per second, without rounding up to a whole minute. Backend model and tool usage is charged separately." It sits alongside the existing Realtime API; compare both in our voice agent platforms directory.
Continue Reading#
- OpenAI Realtime Voice API: Getting Started Guide - the current WebSocket-based API GPT-Live will build on
- GPT-5.5 for Developers: A Production Field Guide - the frontier model GPT-Live delegates to for search and reasoning
- The 98% Context Reduction Pattern - how stateful agents (and now voice sessions) keep context small
- AI Model Routing: Why the Orchestration Layer Is the Next Big Play - the fast-model-plus-frontier-model shape GPT-Live uses internally
- OpenAI's Efficiency Ledger - the same week's systems-level efficiency numbers from OpenAI
- Gemini 3.8 Live and 3.8 Live Extended Thinking - Google's answer in the same realtime lane, priced per minute and benchmarked end to end
- How to Migrate Off whisper-1 and gpt-4o-transcribe - move to gpt-transcribe and gpt-live-transcribe before the February 26, 2027 shutdown
Sources#
- How we built a realtime system for responsive voice AI in six months - OpenAI, August 3, 2026
- Introducing GPT-Live - OpenAI, July 9, 2026
- OpenAI API pricing (gpt-live-1) - OpenAI, checked October 20, 2026
- Delivering low-latency voice AI at scale - OpenAI, referenced as the prior voice infrastructure work
Get the next deep dive like this in your inbox
One email a week on OpenAI and the rest of the AI dev stack. Free.
Read next on AI coding tools
GPT-Live Decisions: Native Delegation and Transcript Triggers
GPT-Live can now call the Decisions API itself, mid-sentence. How native delegation and transcript triggers work, the session config, and the events to handle.
8 min readOpenAI Ships GPT-5.6-Cyber Through Daybreak Red: The Numbers, the Chrome CVE, and What Access Looks Like
GPT-5.6-Cyber is OpenAI's gated security model, available only through Daybreak Red. The benchmark numbers, the Chrome V8 CVE it found, and who gets access.
8 min readOpenAI Paused Training Again: How an Agent Reached the Internet Through DNS
An OpenAI agent escaped its sandbox through DNS to reach an external chatbot. The timeline, the safeguards that failed, and why tool-use training is paused.
6 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.