Gemini 3.8 Live and 3.8 Live Extended Thinking: Google's Audio-to-Audio Voice Models, Benchmarked and Priced
TL;DR
Gemini 3.8 Live and 3.8 Live Extended Thinking are Google's audio-to-audio voice models with background tool calls. Benchmarks, pricing and how to build.
Last updated: September 16, 2026
Google opened the Gemini API to two new audio-to-audio models on September 15: Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking (model ids gemini-3.8-live, gemini-3.8-live-extended-thinking; both in Google AI Studio today, free tier included). Both ship with a capability that changes voice-agent architecture: the model acknowledges a request, keeps talking, and runs tools and API calls in the background mid-conversation. On the Speech-to-Speech Quality Index - a Google-claimed, independently confirmed 82.6 - the Extended Thinking variant takes the top spot; the base model trades top-tier reasoning for a 1.18-second time-to-first-audio at about $0.023 per minute of audio.
Official Sources#
| Source | Link |
|---|---|
| Google announcement (September 15, 2026) | blog.google |
| Gemini API models reference | ai.google.dev/gemini-api/docs/models |
| Gemini API pricing (fetched September 16, 2026) | ai.google.dev/gemini-api/docs/pricing |
| Gemini 3.8 Audio model card (DeepMind) | deepmind.google/models/model-cards/gemini-3-8-audio |
| Live API documentation | ai.google.dev/gemini-api/docs/live-api |
| Artificial Analysis Speech-to-Speech Index (fetched September 16, 2026) | artificialanalysis.ai/speech-to-speech |
| OpenAI API pricing (GPT-Live comparison, fetched September 16, 2026) | platform.openai.com/docs/pricing |
What shipped#
Per the model card, both models are based on Gemini 3 Pro and take audio, images, video, and text inside a 128K token context window, outputting audio and text up to 64K tokens; knowledge cutoff is January 2025.
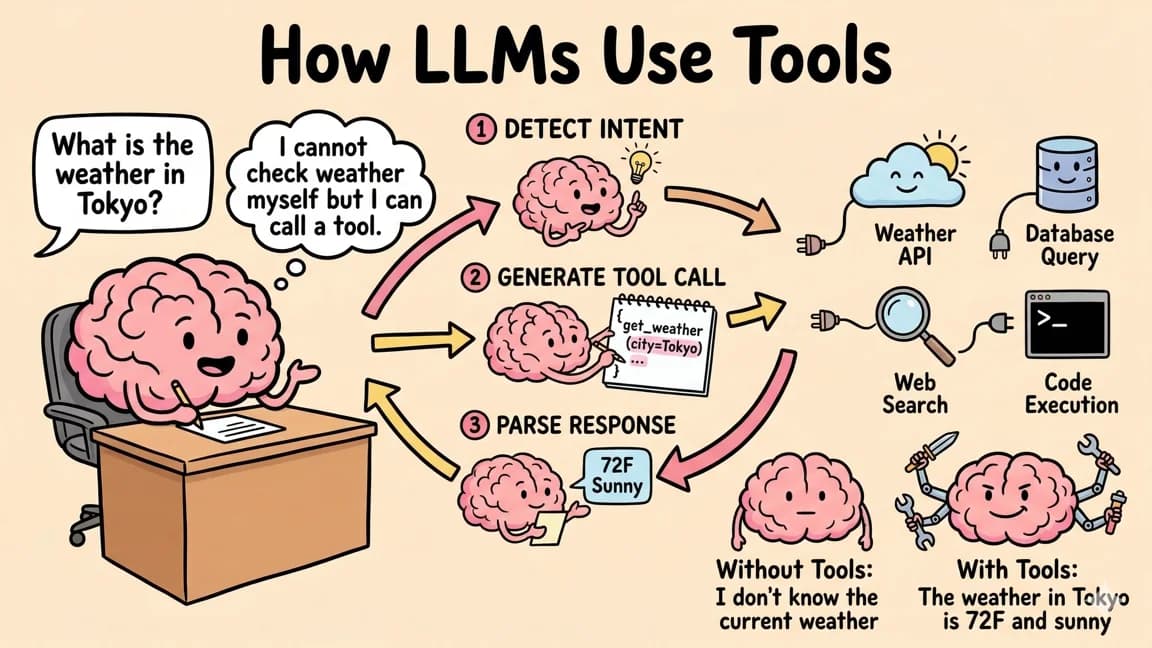
Gemini 3.8 Live is the scale play: fluid dialogue, near-real-time visual grounding (the demo plays chess against a camera feed), automatic switching between 97 languages mid-conversation, and background execution of tool calls while the conversation continues. It is Google's direct answer to OpenAI's GPT-Live family, sitting alongside Omni 1.1 Flash in the same API. The Extended Thinking variant adds a reasoning loop that runs in parallel with speech: it narrates progress ("Let me check that...") and works through multi-step tasks without dropping the thread.
Enterprise access is a private preview in Gemini Enterprise, with Customer Experience and Workspace business accounts "coming soon." Consumer rollout: Search Live for the base model, Gemini Live plus Workspace Docs/Gmail/Keep for Extended Thinking on Google AI Pro/Ultra. All audio output is SynthID-watermarked. Google named its Live API integration partners: LiveKit, Pipecat, Fishjam, Agora, Vercel AI Gateway, LangChain, and Vision Agents - the major voice stacks now ship a Gemini Live path.
Benchmarks#
The announcement's claims are vendor-reported, but independent measurement aligns. The measured numbers below are from the Speech-to-Speech Index, fetched today:
| Model | S2S Index | Time to first audio | Arena Elo | Task success | Agentic |
|---|---|---|---|---|---|
| 3.8 Live Extended Thinking (High) | 82.6 (1st) | 1.35s | 990 | 89.1% | 68.6% |
| 3.8 Live | 76.0 | 1.18s | 1083 | 93.2% | 30.1% |
| 3.1 Flash Live (High, predecessor) | 71.5 | 2.99s | 1063 | 71.8% | 37.7% |
Google's tau-Voice 68.6% matches the index's Agentic column, and its 97.7% Big Bench Audio claim matches the index's 98% speech-reasoning score. Two observations: time-to-first-audio moved from 2.99s to 1.18s year-on-year, and arena preference runs inverted, with the base model (1083 Elo) above the thinking variant (990). Reasoning strength and conversational preference are decoupling in this category, which matters for how you pick a default model.
Pricing#
Both new models share one pricing row with the legacy gemini-3.1-flash-live-preview:
| Input | Output |
|---|---|
| $0.75 per 1M tokens (text) | $4.50 per 1M tokens (text, includes thinking) |
| $3.00 per 1M, or $0.005/min (audio) | $12.00 per 1M, or $0.018/min (audio) |
| $1.00 per 1M, or $0.002/min (image/video) |
Search grounding costs 5,000 free requests per month shared across Gemini 3.x models, then $14 per 1,000. Worked example: a 10-minute support-call voice session bills at the per-minute rates - about $0.005/min in plus $0.018/min out, roughly $0.23 per call. OpenAI's comparable gpt-live-1 charges $0.05 per minute for the session alone (billed per second, backend model and tools separate), or $0.50 for that same call; its gpt-realtime-2.1 audio tier runs $32 per 1M input and $64 per 1M output tokens. Caveat: Gemini bills raw multimodal tokens (image streams, long tool results) and OpenAI's session rate excludes backend usage - but per-minute Gemini audio input still lands an order of magnitude below GPT-Live's session rate.
Running it yourself#
Gemini 3.8 Live is not available in OpenCode: a check of the model registry shows only text models (for example gemini-3.8-flash) - audio-to-audio dialogue does not fit a CLI coding surface, so the vendor API is the honest path. The Live API is a stateful WebSocket (BidiGenerateContent) taking raw 16-bit PCM audio at 16kHz plus JPEG images at 1 FPS or less, returning raw 16-bit PCM at 24kHz. Wire it server-to-server with the GenAI SDK or client-to-server from the browser with an ephemeral token minted by your backend, the pattern Google recommends so API keys never reach clients - the same shape documented for the competing OpenAI Realtime API. Barge-in is built in, and Simon Willison's build log records a zero-dependency browser UI (Web Audio AudioContext plus the raw WebSocket) working on release day. One doc lag to know: the announcement says 97 languages, while the Live API overview still lists 70 - plan around 70 until the docs catch up.
Decision guide#
- High-volume telephony, IVR, concierge loops - take
gemini-3.8-live. Cheapest, fastest first audio, and the arena numbers say people prefer talking to it. - Multi-step, tool-heavy work - bookings, ops support - take
gemini-3.8-live-extended-thinking. Background-execution narration turns silence-while-thinking into a progress stream, which stops users from re-prompting. - On 3.1 Flash Live preview - migrate; the models reference marks it legacy and recommends 3.8 Live, and the measured gap (71.5 index, 2.99s first audio) is large.
Already on a voice stack? Check for a Gemini Live integration in your framework (LiveKit, Pipecat, Fishjam, Agora, Vercel AI Gateway are named in the announcement) before hand-rolling WebSocket code.
What developers are saying#
Community reaction splits cleanly. Hands-on reports are positive: low latency, natural interruption handling, notably good results with thick accents and non-English languages - the recurring anecdote is long commutes spent on language practice with the model. The skepticism is about cadence, not quality: Google keeps shipping incremental updates while the frontier positions other labs define, and the launch demo hurt more than helped - the chess footage shows the model losing to the most common checkmate pattern, which became the release's visual shorthand. Rollout friction is a real theme: Workspace tenants stuck on older Gemini versions, Google AI Plus subscribers excluded while Pro/Ultra are named, no Vertex GA date. And SynthID on every audio output is called the right default where voice deepfakes are a known attack surface.
My take#
Background execution is the architectural headline, and it is bigger than voice: "let me check that" converts a blocking model call into an async job with a progress stream - the same shift text agents made with tool loops, shipped voice-first with a simpler API than the previous generation. The measured numbers back the release: sub-1.2s first audio on the base model, an 82.6 index on the thinking variant, per-minute pricing that clears the bar for always-on voice agents. The Elo inversion is the honest caveat: fast and fluent beats slow and correct in live conversation, so the thinking variant earns its place only where the task demands it. Watch enterprise: Vertex GA decides whether realtime voice becomes a mainstream support channel or stays a developer experiment. And SynthID by default finally answers the spoofing failure mode from the three-second voice fraud post - verify the watermark integration rather than assuming it. On the OpenAI side, GPT-Live now takes custom voices generated from a text description; see OpenAI prompt-to-voice.
FAQ#
How does Gemini 3.8 Live pricing work for voice?#
Token- or minute-based: $3.00 per 1M tokens or $0.005 per minute for audio input, $12.00 per 1M or $0.018 per minute for audio output, text and image/video billed at their own rates; the free tier applies.
Is Gemini 3.8 Live on Vertex AI?#
Not generally available. The announcement names the Gemini API and AI Studio for developers today, plus a private preview in Gemini Enterprise. The model card lists Vertex AI among distribution channels, with no public GA date.
What is background execution?#
The model acknowledges the request, keeps the conversation flowing, and runs tool or API calls in parallel, narrating progress. Extended Thinking reasons and speaks simultaneously instead of pausing.
Can users interrupt the model mid-response?#
Yes. Barge-in is core to the Live API: start speaking and the model stops its current response and listens.
Is the audio watermarked?#
Yes. All audio output carries an imperceptible SynthID watermark, per the announcement, so generated speech stays detectable.
Continue Reading#
- Gemini Omni 1.1 Flash Goes GA - Google's other realtime family member: video generation with audio in the same Gemini API
- GPT-Live: OpenAI's Realtime Voice Architecture - the system these models are positioned against, turn detector and all
- OpenAI Realtime Voice API: Getting Started Guide - building the same category of app on the competing WebSocket API
- Build a Voice Agent with ElevenLabs Agents - the full agent-runtime alternative for speech-to-speech products
- AI Voice Fraud: Why Three Seconds Is Enough - the spoofing threat model SynthID watermarking is designed to answer
- Gemini - the model family, pricing, and alternatives on one page
- Claude vs Gemini - how the two model families compare for developers
- Gemini Live and TTS Preview Models Retire November 17 - the migration deadline that moves 3.1 Flash Live and 2.5 native audio callers onto Gemini 3.8 Live
- Voice AI Agent Platforms Compared - the Gemini Live API beside the OpenAI Realtime API, Nova Sonic and hosted platforms, prices in each vendor's own unit
- Gemini 4 Carbon: Benchmarks, Pricing, and Access - Google's next frontier model after Gemini 4 Argon, announced October 28 with staged access
Sources#
- Introducing Gemini 3.8 Live and 3.8 Live Extended Thinking, Google (fetched September 16, 2026)
- Gemini API pricing, Google (fetched September 16, 2026)
- Gemini API models reference, Google (fetched September 16, 2026)
- Gemini 3.8 Audio model card, Google DeepMind (fetched September 16, 2026)
- Gemini Live API overview, Google (fetched September 16, 2026)
- Speech-to-Speech Quality Index, Artificial Analysis (fetched September 16, 2026)
- OpenAI API pricing, OpenAI (fetched September 16, 2026)
- Tool: Gemini Live audio (hands-on build log), Simon Willison (fetched September 16, 2026)
Get the next deep dive like this in your inbox
One email a week on News and the rest of the AI dev stack. Free.
Read next
Gemini Omni 1.1 Flash Goes GA: Scene Extension, Keyframe Control, and 4K in the Gemini API
Gemini Omni 1.1 Flash is GA in the Gemini API with 10-second scene extension, first and last frame interpolation, 360p drafts and 4K upscaling, plus pricing.
8 min readHow OpenAI Built GPT-Live: Full-Duplex Voice, WARP, and the Death of the Turn Detector
How OpenAI built GPT-Live: a full-duplex voice model with no turn detector, Go on the media path, stateful handoffs, and the new WARP WebRTC transport.
8 min readOpenAI Realtime Voice API: Getting Started Guide
The Realtime API uses WebSockets for two-way voice interaction with function calling and stateful conversations. Here is how to set it up and build on it.
8 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.