Gemini's Agentic Video Understanding Cuts Video Tokens by 88%: How It Works and What Breaks
TL;DR
Google shipped agentic video understanding on Gemini 3.7 Flash, 3.6 Flash, and 3.5 Flash-Lite: the model decides which frames, audio, and transcripts to inspect instead of swallowing video at a fixed frame rate. Verified numbers: up to 88% fewer tokens, up to 66% lower cost, and up to 7% better accuracy on video benchmarks.
On September 1, Google launched agentic video understanding across Gemini 3.7 Flash, 3.6 Flash, and 3.5 Flash-Lite. The feature makes the model decide what to watch in a video instead of ingesting every frame: it scans video segments dynamically across visual frames, audio, and transcripts, using its native video tools to load only the parts relevant to the query. Google reports up to 88% lower token consumption, up to 66% lower cost, and up to 7% better accuracy on standard video benchmarks, with the largest wins on long-form video.
This is the video version of agentic vision, which Google shipped for Gemini 3 Flash earlier this year: instead of static processing, the model runs a reasoning loop over the media with tools. The shift is small in code and large in economics, and it changes what building a video-RAG or a video-analysis pipeline costs.
What shipped#
Agentic video understanding is available today for video uploads and YouTube videos through the Gemini API in Google AI Studio and the Gemini Enterprise Agent Platform, across the three Flash-tier models. It uses standard Gemini API token pricing with no additional feature fee. You enable it by setting processing to "agentic" in the video input:
from google import genai

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-3.7-flash",
    input=[
        {
            "type": "video",
            "uri": "https://youtu.be/7Z5Vy9JBANs",
            "processing": "agentic"
        },
        {
            "type": "text",
            "text": "What are the 3 most important announcements in this keynote?",
        },
    ],
)

print(interaction.output_text)
That is the entire migration surface. The API shape is the same as the static path; the processing flag changes the runtime behavior. Google positions this as the natural pairing of the model's reasoning with its native video tools, and says activating it drops token consumption by up to 88% while boosting accuracy by up to 7% on Gemini 3.7 Flash.
The headline gains come from reporting on LongVideoBench, a long-form video understanding benchmark. Two of the demo claims are worth taking literally as engineering targets: sub-second moment retrieval (pinpointing split-second cut boundaries that 1 FPS sampling misses) and needle-in-a-haystack search across multi-hour video without consuming millions of tokens.
Why the 88% number is real and not free#
The efficiency figure is plausible for a specific, mechanical reason. Static video processing defaults to 1 FPS: a 60-minute video becomes 3,600 frames fed into the model as input, whether the query needs two of them or all of them. A 90-minute lecture at 1 FPS is over 5,000 frames of context on every single question. Long video makes static processing choose between a token bill that looks like a bill or aggressive downsampling that drops exactly the detail the query is about.
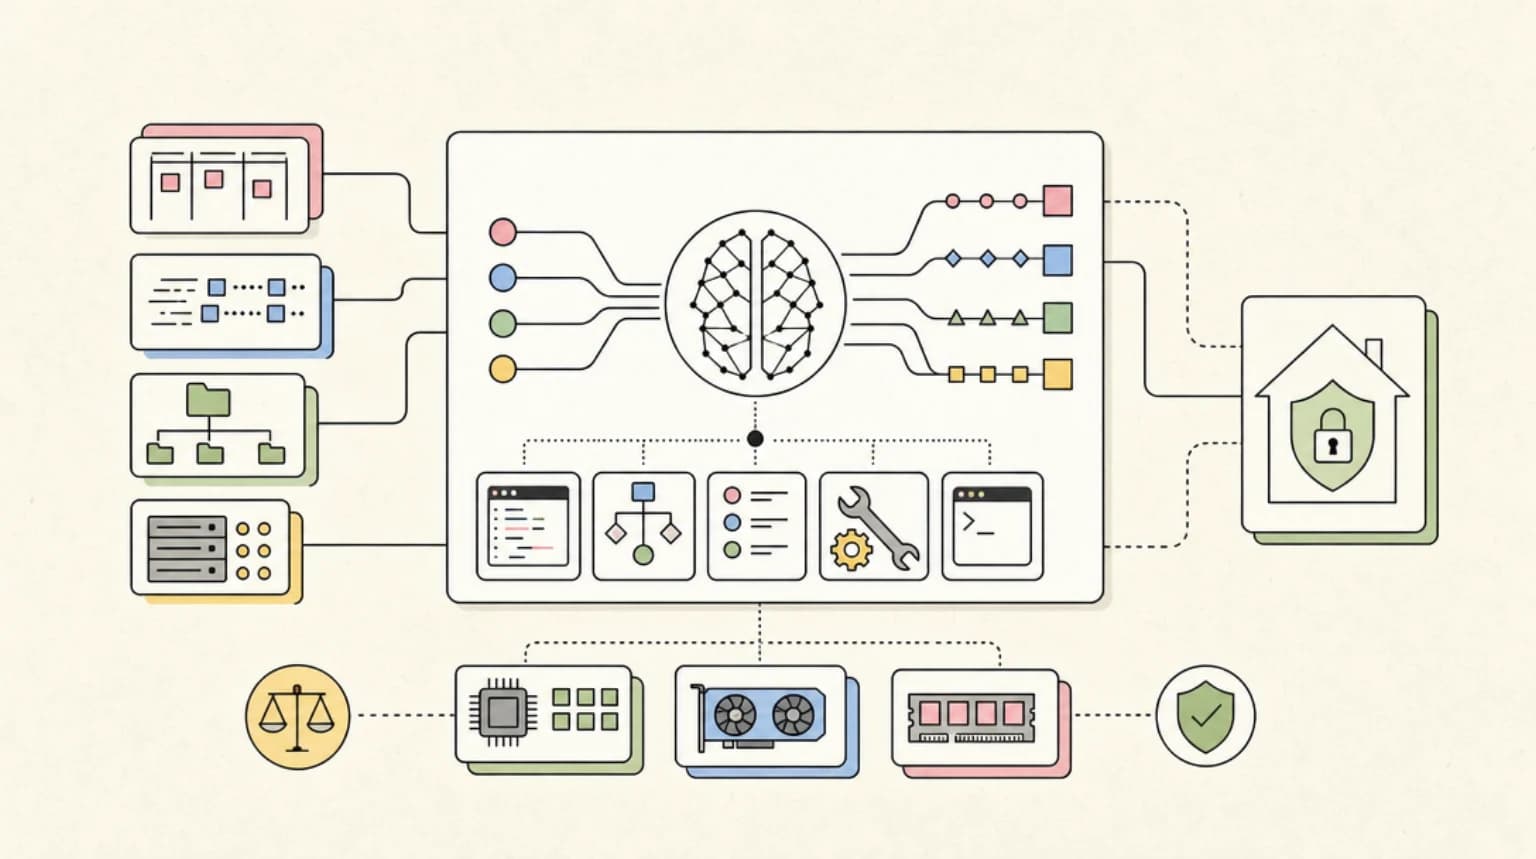
Agentic video understanding inverts the flow: the model decides what to watch, at what speed, and through which modality, then fetches only those segments through an internal tool call. Queries about a single moment reach only the frames around it. The efficiency ratio widens with video length, which is precisely the regime where the old approach was unusable.
The important caveat is that this is a routing claim, not a compression claim. The cost reduction depends on the query targeting a fraction of the footage. A query that needs to inspect the whole video - "summarize every segment" - gets far less benefit, because the agentic loop correctly decides to look at everything. The 7% accuracy gain, meanwhile, is directionally believable because selective resampling at higher FPS on interesting windows (anomaly detection, fast motion, action counting) beats a uniform 1 FPS pass on tasks that live in short time windows. Google explicitly lists dynamic frame-rate resampling for anomaly detection among the capabilities.
What it means for developers#
This matters for two kinds of builders. The first is anyone doing video analysis at scale - meeting transcription, lecture processing, content moderation, sports or security footage analytics - where the per-video token bill was the bottleneck. Cutting the cost of the analysis run changes the product math: a feature that was too expensive to run on every video becomes a default rather than a premium. Google is also rolling the capability into the Gemini app and, in the coming months, YouTube's Ask YouTube feature, which is the same underlying economics applied to consumer surfaces.
The second group is anyone building agent pipelines over multimodal data. The underlying pattern - a model with a retrieval tool over a media file instead of a model that ingests the whole file - is the same shape our coverage of agent context reduction and video pipelines has pointed at repeatedly. The tool call over the file replaces the bulk context load, and the search cost replaces the token cost of indiscriminate ingestion. That is the architecture of every cost-efficient media agent, and Google shipping it as a flag rather than a pattern you assemble yourself is a meaningful save in development time.
The honest caveats#
Three limits are worth noting. First, agentic video understanding is available on the Flash tier only; the reasoning-class models do not get the flag in today's announcement. Second, accuracy gains are benchmark-level and the largest on tasks where selective resampling genuinely wins - counting, anomaly detection, moment retrieval - so results on your own footage need your own evals. Third, the feature is a tool-calling loop, which means it inherits the latency and reliability characteristics of any multi-step agent: more potential failure points than a single static pass, and a cost profile that depends on what the model decides to fetch. The agentic vision documentation is the right place to check the interaction model before designing around it.
For teams already on the Gemini API, the upgrade is one flag and a re-run of your eval set. For teams evaluating Google vs the omni-modal field, this is the strongest cost argument Google has shipped for video understanding this year.
Continue Reading#
- Gemini Omni 1.1 Flash Goes GA: Scene Extension, Keyframe Control, 4K - the generation side of the Gemini video stack at the same price per second as Veo 3.1 Fast
- OpenMontage: The Real Future of AI Video Is Agents, Not Editors - video production as a repo-shaped agent workflow, which agentic video understanding slots into
- MiniMax H3: Omni-Modal Video Model With Native Audio - the open-weights competitor in the video generation band
- SAM 3.1: Realtime Video Segmentation in Apps - segmentation models doing the frame-level work the agentic loop decides to fetch
- Claude's Vision API in Production - the cost discipline checklist for production vision workloads
Sources#
- Google: Introducing agentic video understanding with Gemini - Sep 1, 2026, primary announcement with benchmark figures
- Google: Agentic vision with Gemini 3 Flash - the predecessor pattern
- Gemini API docs: video understanding - API shape and the
processing: agenticconfiguration - LongVideoBench paper - benchmark cited for long-form results
Get the next deep dive like this in your inbox
One email a week on News and the rest of the AI dev stack. Free.
Read next
Gemini Omni 1.1 Flash Goes GA: Scene Extension, Keyframe Control, and 4K in the Gemini API
Google made Gemini Omni 1.1 Flash generally available today: 10-second scene-extension context, first and last frame interpolation, 360p drafts at a third of the cost, and 4K upscaling. Verified pricing: about $0.10 per second of 720p video.
8 min readOpenMontage Shows the Real Future of AI Video: Agents, Not Editors
OpenMontage is trending because it treats video production like a repo-shaped agent workflow: scripts, assets, render pipelines, review loops, and coding agents working across the whole process.
7 min readMiniMax H3: An Omni-Modal Video Model With Native Audio, 2K Output, and Open Weights Coming
MiniMax launched H3, an omni-modal generation model that takes text, image, video, and audio input and outputs 2K video with native stereo sound at 0.80 CNY per second. Open weights are promised in the coming days.
8 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.