Topic
PROMPT CACHING
All blog posts, tools, and guides about Prompt Caching from Developers Digest.
10 resources - 9 posts, 1 guide
Blog Posts
View in blog →
How to Cut Your LLM API Bill in 2026: Prompt Caching, Batch and Flex Tiers Compared Across 15 Providers
Caching a shared prompt cut our worked example by about 78-80% on four models; batch takes 50% off at most providers but 40% at Moonshot and 20% at xAI. Only Anthropic, Fireworks and xAI say the two stack. The math, the assumptions and the quotes.
12 min read
Prompt Caching Across AI Providers: Prices, TTLs and Setup
Prompt caching across OpenAI, Anthropic, Gemini, DeepSeek, Mistral, xAI and Qwen: prices, TTLs, setup code. A reused 100K prefix costs 71-93% less.
13 min read
Claude API Inline Tool Definitions: Add Tools Mid-Conversation
Claude API inline tools beta: define, reshape or upgrade a tool mid-conversation with one system message and keep the prompt cache. Code included.
11 min read
Claude Code Idle Compaction: What It Does and How to Turn It Off
Claude Code 2.1.299 compacts sessions over 200K tokens after about 54 idle minutes. How the cache math works, the setting to turn it off, and when to keep it.
8 min read
Claude Code Prompt Cache: Read the Hit Ratio, Set 5m or 1h TTLs
Claude Code now reports prompt cache hit ratio and miss causes in /usage. How to read it, script a status line, and set 5m or 1h TTLs.
9 min read
Claude Fable 5.1 and Mythos 5.1: The Developer Migration Guide
Claude Fable 5.1 keeps $10/$50 pricing but cuts cache reads to $0.25/MTok. The three breaking API changes, new betas, and when Opus 5.5 is enough.
16 min read
Context Engineering for Agents: Caching, Compaction, Subagents
Context engineering for agents, explained: caching, compaction, tool-result clearing, retrieval and subagents, with the exact Anthropic and OpenAI API knobs.
15 min read
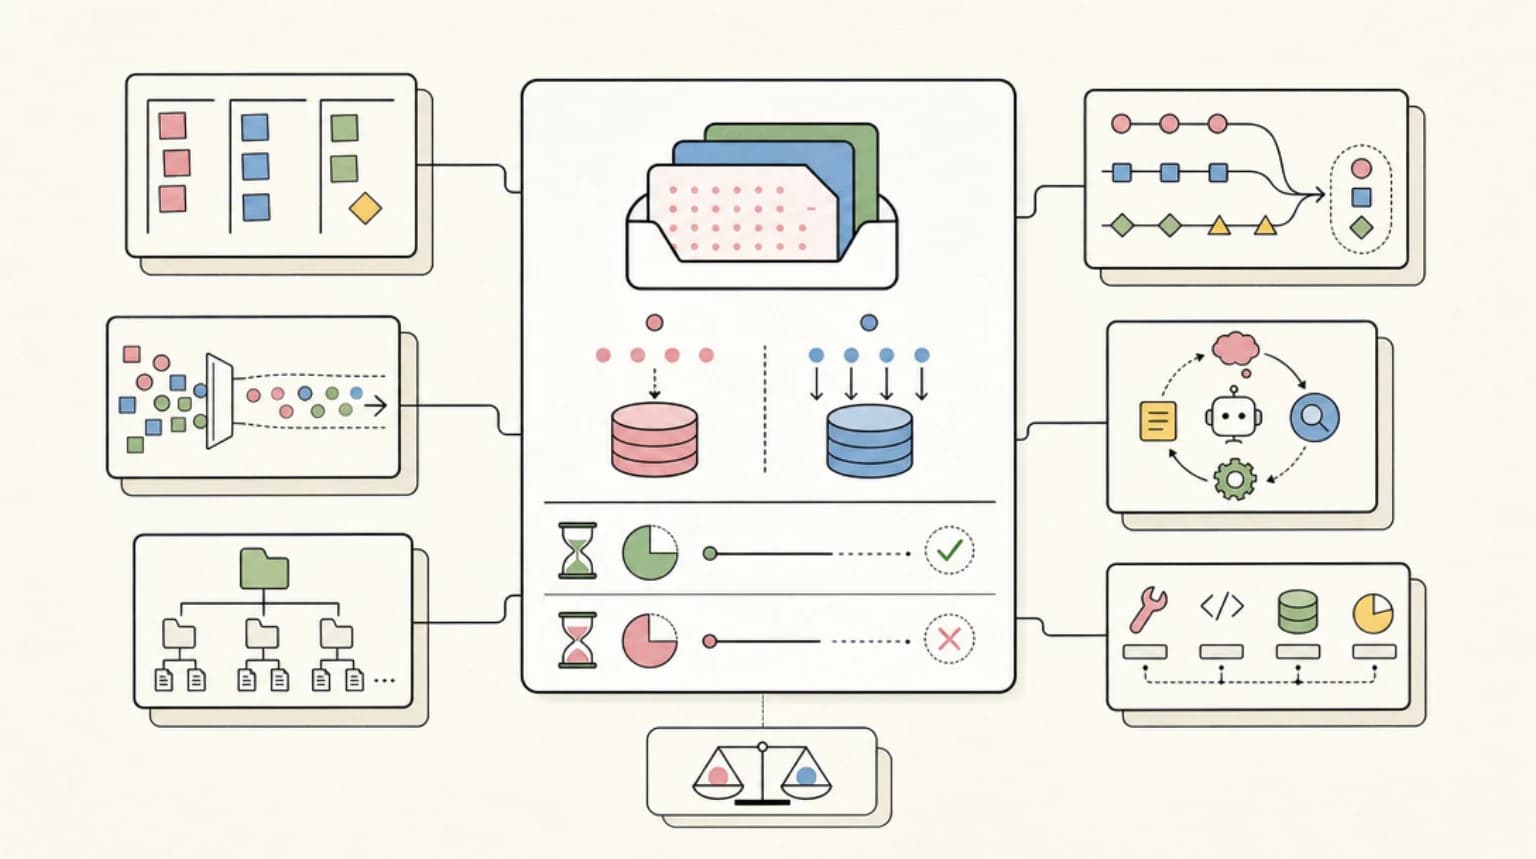
Prompt Caching Economics on Fable 5: When the 5-Minute TTL Pays
Fable 5 prompt caching economics: cache-write vs cache-read pricing, 5-minute vs 1-hour TTL break-even math, and worked agent-loop examples.
10 min read
Prompt Caching in the Claude API: A Production Guide
Cut Claude API spend by up to 90% with prompt caching. Real numbers, TypeScript SDK code, and the gotchas Anthropic's docs gloss over.
11 min read
Keep exploring
More on Prompt Caching
- - Tools Directory - dive deeper across the Developers Digest knowledge base
- - All Prompt Caching articles in the blog archive
- - Developers Digest on YouTube - video tutorials covering Prompt Caching and more

Get Smarter About AI Dev
New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
One email per weekReal code, not theoryFree forever
Explore 844 topics
Browse All Topics