Agent Memory Is Moving Into the Model
TL;DR
Agent memory is moving into the model: in-backbone memory, parametric memory, reconstruction and transactional writes challenge external stores. What to do now.
Last updated: July 31, 2026
Where we stood#
This site has argued a consistent line on agent memory all year. In June we argued that memory without structure is just another place for hallucinations to hide, and that the useful version is a context ledger: source-linked, scoped, expiring, auditable (AI Agent Memory Needs a Context Ledger). In early July we compared the four memory products developers actually reach for - Mem0, Zep, Letta, and Cloudflare - and concluded there is no single best provider, only a best fit for your access pattern (Best AI Agent Memory Providers in 2026). In May we warned that memory benchmark numbers are not comparable across vendors at all (Why Agent Memory Benchmarks Are Not Enough).
Every one of those pieces shared one assumption: memory is an external store bolted next to the model. A vector database, a knowledge graph, a self-editing file tree, or a Durable Object. The model stays frozen; the store grows.
That assumption is now under direct attack. In the last two days, five papers landed that each take a different swing at the same claim: memory is becoming a model-native capability, and the external store's job is shrinking from "the memory" to "the curated part."
What changed in one week#
Memory inside the backbone. Metis (arXiv:2607.26760) is the first memory foundation model, and it is the first paper to state the target plainly: agent memory is still implemented as external modules, and that is an accident of history, not a design. Metis keeps a persistent memory state inside the model's backbone. Historical information is compressed into that state and read back through memory attention. The online update is gradient-free: a single forward pass, with all learned weights frozen. That is a fundamentally different cost profile from stuffing history into context or re-embedding documents.
Memory as a scaling axis. Memory Decoder at Scale (arXiv:2607.27919) scales a parametric long-term memory module to 6.9B parameters pretrained on 300B tokens. The result is a scaling law, not a demo: a 410M base model plus a 6.9B memory module beats a 12B base model outright (37.34 vs 37.24 average across 17 benchmarks) with 39% fewer total parameters, and a 1.7B domain memory adds more than 9 points to Qwen3 bases from 0.6B to 14B. "Add memory, not parameters" went from a slogan to a measured tradeoff.
Memory is reconstructed, not replayed. MemHarness (arXiv:2607.28272) diagnoses why memory injection so often hurts: stored experience is abstract, decision-time state is concrete, and replaying the blob verbatim causes negative transfer. Its fix is a unified policy model, trained with GRPO, that critiques and reconstructs each retrieved memory against the current state before acting. It beats pure-RL and static-memory baselines on ALFWorld and WebShop and holds up out of distribution. The design consequence: a reconstruct step between retrieval and context injection becomes the default shape of memory-augmented agents.
Memory writes become transactional. MemTxn (arXiv:2607.27834) points out that agents persist claims with no check that the source supports them and no way to roll back a bad write. It adds a governance layer outside the answer model: Ordered PatchTest validates writes against their source, a Temporal Resolver picks the visible version when facts conflict, and a durable snapshot journal restores state after faults. On an item-disjoint audit it rejects all 179 hard-negative writes, and it beats the Dense baseline by 17-24 points on MemoryAgentBench FactConsolidation. This is the ACID boundary our June context-ledger post asked for, formalized as a research contribution.
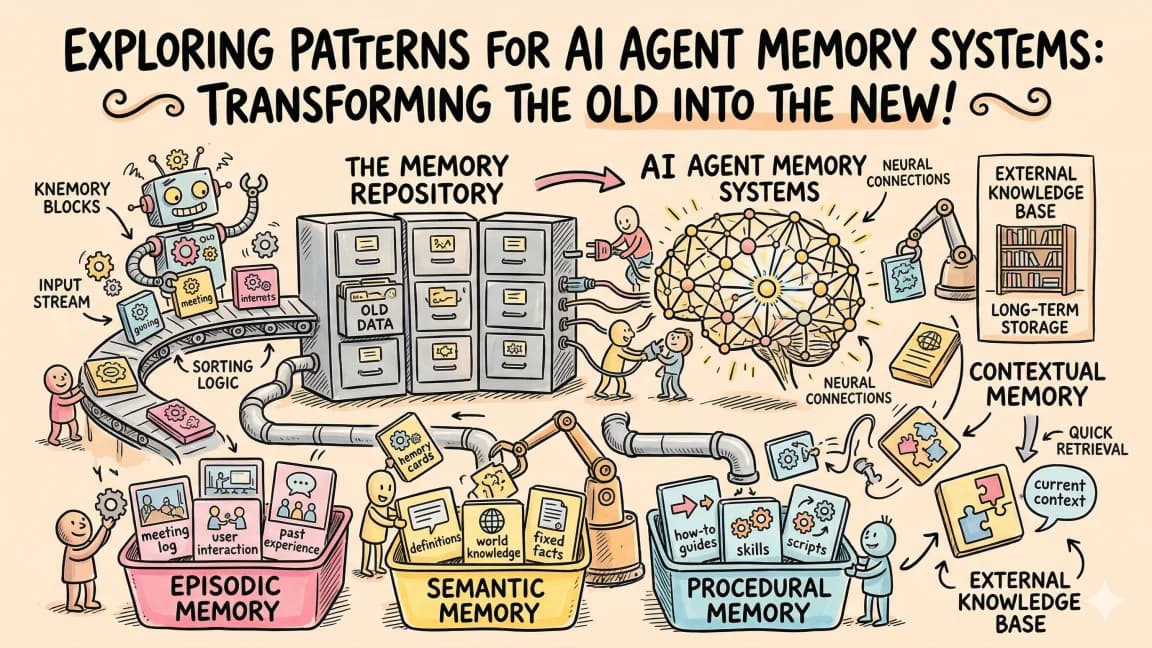
The default store is failing. The most damning paper for the status quo is the first systematic study of filesystem-based memory (arXiv:2607.26637): the markdown-file-tree memory that deployed agents actually use, which is exactly the AGENTS.md and skills pattern this site runs on. Organization roughly halves retrieval cost at scale, but in growth studies organization erodes for all but the strongest management agent, no agent converts organization into better answers, and swapping the tool set reshapes the store as strongly as swapping the model. The default memory medium of the agent era is an assumption, not a design, and current agents cannot sustainably curate their own memory. Today's null result on context files (AGENTS.md Files Don't Move Coding Agent Correctness) is the same story from the other side: agents fail on implementation skill, not on missing repository memory.
The synthesis#
Read together, the five papers say something none of them says alone.
First: memory becomes a third context option. In-backbone memory (Metis) plus pretrained parametric memory (Memory Decoder) gives long-running agents something that is neither stuffing tokens nor retrieving documents: state that lives in the model and costs a forward pass to update. By late 2027 we expect at least one frontier agent API to expose a native-memory capability and at least one open model family to ship memory-pretrained weights, because the parameter-efficiency evidence is published and the inference economics are favorable.
Second: the external store survives by moving up the stack. The store does not die, it gets redefined. Retrieval is not the hard problem anymore; verification, hygiene, and write discipline are. MemTxn turns memory writes into transactions, the filesystem study shows store health is a real operational axis, and MemHarness makes memory use a transformation rather than a lookup. The external providers' market position shifts from "we are your agent's memory" to "we are the governed layer around it." If you are choosing a memory product today, the decision criteria from our July comparison still hold, but add two columns: how writes are validated, and how store health is measured.
Third: the reconstruct step is the new RAG adapter. Whatever the memory medium, the retrieval-to-context pipeline gains a critique-and-adapt step between the lookup and the injection. That is a modest change for builders and a significant one for framework vendors, because it turns memory from a data problem into a training problem, and it is the same execution-grounded-RL pattern that is beating model size elsewhere in agent research.
The counter-case#
Be honest about what these papers are not. Metis is one prototype from one lab; gradient-free updates are unproven on multi-day production runs. Memory Decoder at Scale is a pretraining-scale result, expensive to reproduce, not an inference-time patch. All five papers landed in the same two-day window, which makes them one research wave, not a settled direction, and our own benchmark skepticism applies to them too. Context windows are still growing, with million-token models already here, which softens the need for memory compression at the margin. And the external ecosystem is not standing still: the vendors we compared in July ship faster than any research lab.
The falsifiable version of this bet is narrower than the hype: by late 2027, a frontier agent API ships a native memory state that survives sessions without external tooling, and production agent memory stacks include write validation and reconstruction. If every long-lived agent still stores markdown and vectors with no native-memory option in sight, the bet is wrong, and the external-store paradigm wins on inertia.
What developers should do about it#
- Keep the ledger discipline. Everything we argued in June survives this week: source-linked, scoped, expiring memory is still the right shape for the curated layer, because the filesystem study confirms uncurated stores rot.
- Treat memory writes like writes. Before persisting a fact, check the source supports it; when facts conflict, pick a visible winner; keep a journal you can restore from. That is MemTxn's contribution, and it costs nothing to adopt today.
- Insert a reconstruction step. When a memory or skill is retrieved, have the model restate it against the current task before acting on it, instead of injecting it verbatim. This also doubles as a defense against stale or planted memories.
- Audit your store health. Your AGENTS.md and skill files are a memory medium with the failure modes the filesystem study measured: organization erosion, stale facts, silent growth. Schedule a hygiene pass the way you schedule dependency upgrades.
- Re-check before you buy. Add write validation and store-health metrics to your memory provider scorecard, because that is where the products are about to compete.
The gradeable bet#
This is the thesis in one line: by late 2027, agent memory in production is a model-native capability plus a governed external layer, and the external layer wins or loses on write discipline, not retrieval cleverness. We will grade it against model releases, vendor changelogs, and the long-horizon evals that are starting to matter more than static suites.
FAQ#
What does it mean for agent memory to move into the model?#
Instead of an external store bolted next to a frozen model, memory lives in the model itself. Metis (arXiv:2607.26760) keeps a persistent memory state inside the backbone, read back through memory attention and updated gradient-free in a single forward pass. Memory Decoder at Scale (arXiv:2607.27919) adds a pretrained parametric memory module, where a 410M base plus a 6.9B memory module beats a 12B base with 39% fewer total parameters.
Do external memory stores like vector databases go away?#
The post argues they survive by moving up the stack. Retrieval is no longer the hard problem; verification, hygiene, and write discipline are. The external providers' position shifts from "we are your agent's memory" to "we are the governed layer around it," so memory product scorecards should add how writes are validated and how store health is measured.
How should developers make agent memory writes safer today?#
Treat memory writes like writes: check the source supports a fact before persisting it, pick a visible winner when facts conflict, and keep a journal you can restore from. That is the MemTxn (arXiv:2607.27834) pattern, which rejected all 179 hard-negative writes on an item-disjoint audit.
Is file-based memory like AGENTS.md and skills files reliable?#
The first systematic study of filesystem-based memory (arXiv:2607.26637) found organization roughly halves retrieval cost at scale, but organization erodes over time for all but the strongest management agent, and no agent converts organization into better answers. The post recommends scheduling a hygiene pass on these files the way you schedule dependency upgrades.
Continue Reading#
- AI Agent Memory Needs a Context Ledger
- Best AI Agent Memory Providers in 2026
- Why Agent Memory Benchmarks Are Not Enough
- AI Agent Memory Patterns
- AGENTS.md Files Don't Move Coding Agent Correctness
Sources#
- Metis: Memory Foundation Model (arXiv:2607.26760)
- Memory Decoder at Scale: A Pretrained, Parametric Long-Term Memory (arXiv:2607.27919)
- MemHarness: Memory Is Reconstructed, Not Replayed (arXiv:2607.28272)
- MemTxn: A Transaction Boundary for Source-Supported Updates and Complete-State Recovery in Agent Memory (arXiv:2607.27834)
- Filesystem-Based Memory for LLM Agents: Organization, Evolution, and Sustainability (arXiv:2607.26637)
Get the next deep dive like this in your inbox
One email a week on Research and the rest of the AI dev stack. Free.
Read next on AI coding tools
AI Agent Memory Needs a Context Ledger
AI agent memory works best as a context ledger: source-linked, scoped, expiring memory that agents can inspect and users can audit, not magic recall.
8 min readBest AI Agent Memory Providers in 2026: Mem0 vs Zep vs Letta vs Cloudflare
Mem0 vs Zep vs Letta vs Cloudflare compared as AI agent memory layers: architecture, pricing, the disputed benchmarks and which one to pick for your agent.
11 min readAgent Memory Benchmarks Are Not Enough
Agent memory benchmarks are not enough. Coding-agent memory has to prove recall, freshness, deletion and rollback under real development pressure.
9 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.