Claude Managed Agents Are Starting to Look Like Backend Jobs
TL;DR
Claude Managed Agents now have multiagent sessions, outcomes, webhooks and auto permissions. Why agent runs need backend job discipline, and how to apply it.
Last updated: September 15, 2026
Anthropic's latest Claude Managed Agents update looks like an agent feature launch on the surface: multiagent sessions, outcomes, dreaming, vault refresh, and webhooks.
The more useful read is that managed agents are turning into a backend job runtime.
That is the angle developers should care about. Once an agent can run for a while, split work across specialized threads, refresh credentials, emit webhooks, ask for permission, and prove an outcome, it stops behaving like a chat tab. It starts behaving like a long-running production process.
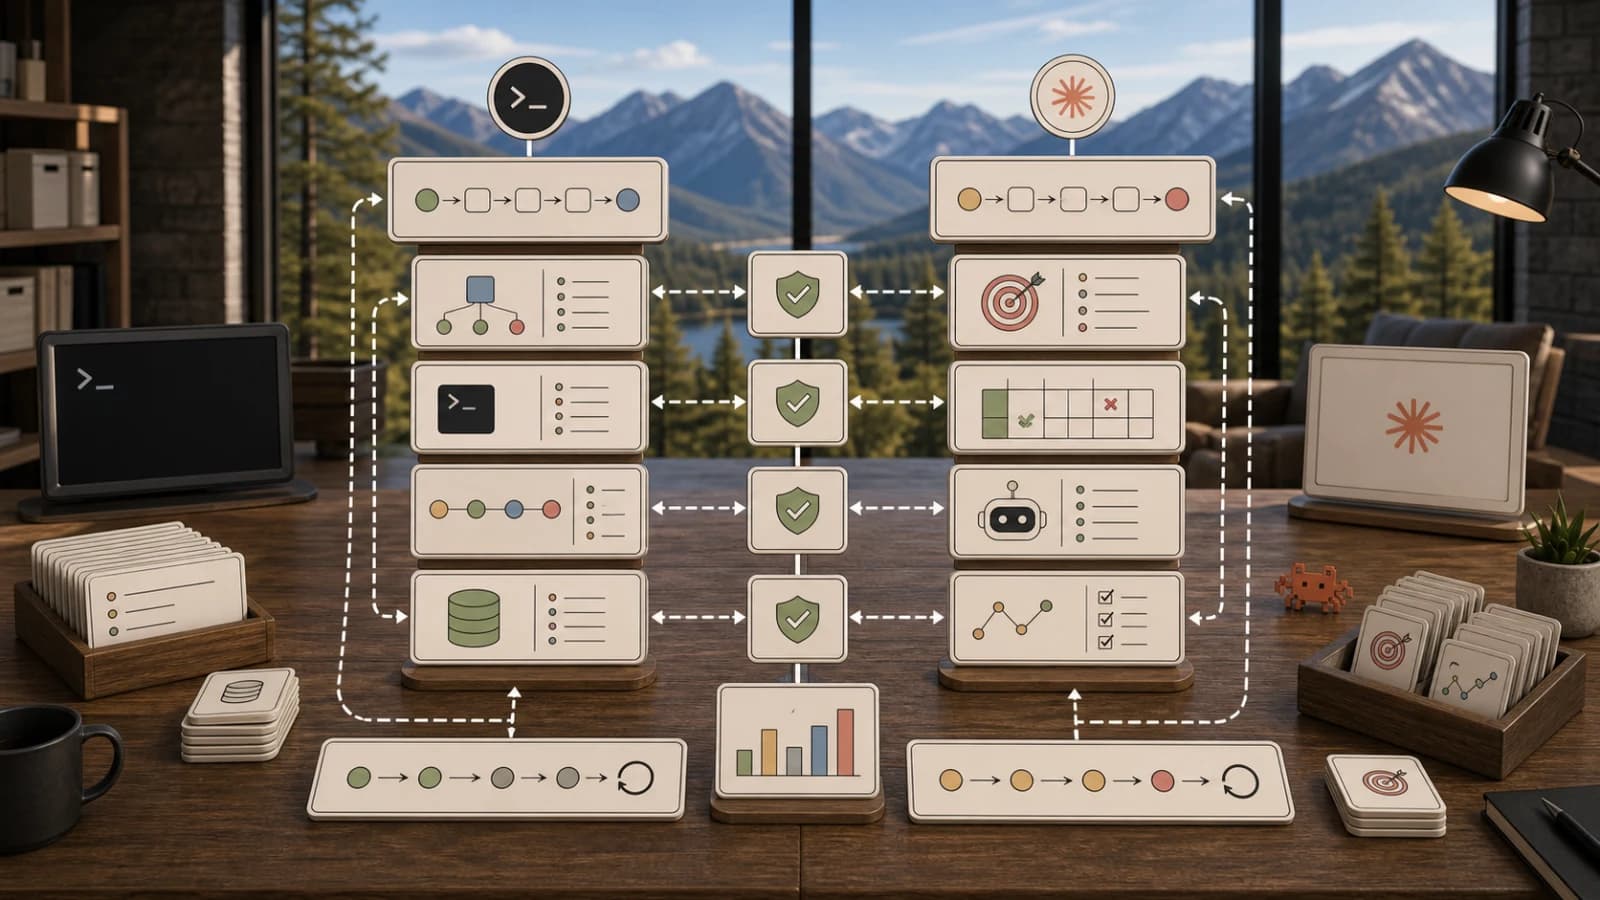
That puts Claude Managed Agents in the same operational lane as Codex goals and Claude managed outcomes, terminal agents as portable runtime surfaces, and long-running agent harnesses. The winning teams will not just prompt these systems better. They will wrap them like jobs: queued, idempotent, observable, interruptible, budgeted, and auditable.
September 2026 Update: Permissions Became Runtime State#
Anthropic's September 10, 2026 platform release adds the missing middle state for hosted agent tools: Claude Managed Agents can now use an auto permission policy. Instead of choosing only between "always run this tool" and "always pause for a human," the server evaluates each agent-tool or MCP-tool call against the tool input and the session context, then returns one of three outcomes: allow, ask, or deny.
That is not just a convenience setting. It changes the operational model. A hosted agent run now has permission decisions that can be observed in its event stream, stored alongside the run record, and audited after the fact. The permission-policy docs say agent.tool_use and agent.mcp_tool_use events expose evaluated_permission, and usually an evaluation object that names whether the result came from always_allow, always_ask, or auto.
The caveat is important: auto is not a human checkpoint. If the server decides a call is safe, the tool runs before a person reviews it. If a human must inspect a tool call first, the policy should stay always_ask. That puts auto in the same family as Claude Code auto mode: useful for reducing approval fatigue, but only inside a permission design that still has hard stops for irreversible or business-critical actions.
The other September 10 change makes the human handoff cleaner. The ant CLI now includes ant beta:sessions connect, which attaches a terminal to an existing Managed Agents session so an operator can follow the run, send messages, and resolve permission requests without building a custom console. For teams already treating agent sessions like jobs, that is the operator shell the runtime was missing.
The practical pattern is simple:
- Put low-risk, reversible tools under
auto. - Keep dangerous or customer-visible tools under
always_ask. - Store
evaluated_permissionandevaluation.reason_codein your own audit table. - Alert humans only when a session pauses, hits a budget, or denies a needed action.
- Review the completed artifact separately from the permission log.
Google Trends did not show durable search demand for the exact "Claude Managed Agents" or "agent permissions" phrases in the September 15 US 90-day sample. Broad "Claude Code" and "Codex" demand was far steadier. So the right SEO move is a refresh of this canonical Managed Agents architecture guide, not a second narrow news post.
What Changed#
Anthropic's announcement says managed agents now include multiagent orchestration, outcomes, dreaming, vault refresh, and webhooks (Anthropic announcement). The September platform release adds server-evaluated permission policies and a CLI connection path for live sessions.
The docs make the shift clearer.
Multiagent sessions let a coordinator agent delegate to other agents inside a single session. Those agents share a container and filesystem, but each runs in its own context-isolated session thread with its own conversation history. The coordinator sees condensed activity on the primary event stream, while operators can inspect individual session threads when needed.
Outcomes turn "done" into a rubric-driven evaluation loop. Instead of trusting that an agent stopped at the right time, you define success criteria and inspect whether the outcome was satisfied, needs revision, hit max iterations, or failed.
Webhooks notify your system about state changes such as sessions starting, idling, rescheduling, terminating, creating threads, or finishing outcome evaluation. The webhook docs also say payloads include the event type and resource ID, then your app fetches the fresh object by ID.
That last detail matters. It is exactly how serious backend systems avoid stale event payloads, duplicate delivery bugs, and polling loops.
The Take#
The agent platform race is moving from "can the model use tools?" to "can the run be operated like infrastructure?"
A production agent run needs the same boring properties as a background job:
- a durable job identifier
- explicit status transitions
- retry semantics
- duplicate delivery handling
- permission checkpoints
- logs and event streams
- typed completion states
- budget limits
- a way to wake humans up only when needed
Claude Managed Agents is not the only path there. You can build this around Codex, Claude Code, GitHub Actions, a queue, or your own harness. But Anthropic's managed-agent surface is a strong signal about where the category is going.
Agent execution is becoming backend execution.
Webhooks Change the Integration Shape#
Without webhooks, a managed agent is something your app starts and then checks later.
With webhooks, it becomes something your app can subscribe to.
That difference changes the architecture. Your application can now react when an agent idles for a permission approval, when a multiagent thread is created, when a transient error triggers a reschedule, or when an outcome evaluation finishes.
That is the same reason agent-native backends are interesting. The valuable surface is not just the model. It is the control plane around the run.
The webhook docs also include the important production caveats:
- event payloads are small and require a follow-up fetch
- duplicate deliveries can happen
- ordering is not guaranteed
- non-2xx responses trigger retry behavior
- endpoints can be disabled after repeated delivery failures
Those are normal webhook rules, but they are easy to forget when the product category is called "agents." If you wire this like a toy chat callback, it will break like a toy chat callback.
The right shape is boring:
- Verify the signature.
- Deduplicate by event ID.
- Fetch the current session, thread, or outcome object by ID.
- Update your own run record transactionally.
- Trigger the next action only from your stored state.
- Treat ordering as a hint, not a guarantee.
That is not glamorous. It is what keeps an overnight agent from waking up three people for the same stuck approval.
Multiagent Sessions Need Handoff Discipline#
The multiagent docs are also more operational than they first look.
The coordinator can delegate to a roster of agents. Anthropic frames the best use cases as parallelization, specialization, and escalation. That maps directly to how engineering teams already split work: researcher, implementer, reviewer, test writer, security reviewer, docs writer.
But the docs include constraints that should shape your design:
- all agents share the same container and filesystem
- each agent has isolated thread context
- tools and context are not shared
- the coordinator can delegate only one level deep
- the roster can include up to 20 unique agents
- session status aggregates thread activity
- permission requests from worker threads are cross-posted to the primary thread
Those details create a useful boundary.
Do not treat multiagent sessions as a magic swarm. Treat them as a supervised job with worker threads.
Each worker needs a narrow assignment, a completion artifact, and a reason to exist. If your coordinator delegates "improve the codebase" to five agents, you just made five vague agents. If it delegates "review auth policy changes," "write regression tests," and "summarize docs changes," you have an actual workflow.
This is the same practical lesson behind parallel coding agents needing merge discipline. Parallelism is only useful when the handoffs are crisp enough to merge.
Outcomes Are the Stop Condition#
The most important primitive is still outcomes.
Tools let the agent act. Multiagent sessions let it split work. Webhooks let your app react. But outcomes define when the run is allowed to stop.
That is why the existing Codex /goal vs Claude outcomes comparison still matters. A durable loop is not the same thing as a good stopping rule. "Keep going" and "prove it is done" are different product primitives.
For production workflows, outcomes should be written like acceptance criteria:
- what files or artifacts must exist
- what tests or checks must pass
- what source evidence must be cited
- what risk review must be completed
- what business constraint must remain true
- what human handoff note must be left behind
The anti-pattern is using an outcome as a vibe check.
Bad outcome: "Make the report good."
Better outcome: "The report cites three primary sources, lists assumptions, includes a recommendation table, flags unknowns, and has no unsupported pricing claims."
This matters even more as agents start coordinating with other agents. The coordinator can produce a polished summary while a worker missed the actual requirement. Outcomes force the final handoff to be judged against a rubric instead of the coordinator's confidence.
The Opposing Take#
There is a fair skeptical response: isn't this just queue infrastructure with a model attached?
In many ways, yes.
That is the point.
Teams already know how to run jobs, retries, event handlers, dashboards, queues, alerts, and approval workflows. The mistake would be treating agents as a brand-new metaphysical category that needs brand-new operational instincts.
The harder skeptical question is whether managed-agent platforms hide too much. If the provider owns the session runtime, filesystem, thread orchestration, credential vault, and outcome evaluation loop, you get speed but lose some control. You need to understand what can be exported, logged, replayed, interrupted, and governed from your side.
For some teams, a self-hosted harness around Claude Code, Codex, or an open-source agent runtime will be the better answer. For others, a managed runtime is exactly the right tradeoff because the provider handles the painful execution substrate.
The decision should not be ideological. Ask what failure evidence you get back.
The Production Checklist#
Before treating managed agents as production infrastructure, I would require:
- a local run record for every agent session
- webhook signature verification
- idempotent event handling
- duplicate event detection
- explicit state machine transitions
- max runtime and max spend caps
- per-tool permission policy, with
autoonly where immediate execution is acceptable - persisted permission evaluation results for every tool call
- outcome rubrics stored in version control
- thread-level logs or summaries for worker agents
- human escalation rules for idled sessions
- a receipt artifact after completion
- a rollback or replay plan for failed runs
This is also where managed-agent FinOps becomes unavoidable. A long-running agent that can reschedule, fan out, call tools, and revise toward an outcome can produce serious value. It can also burn money in a loop if you do not cap it.
A Concrete Architecture#
If I were adding Claude Managed Agents to a developer platform today, I would not start with a chat UI.
I would start with a job table:
agent_runs
  id
  provider_session_id
  status
  objective
  outcome_rubric_version
  max_runtime_minutes
  max_budget_usd
  created_by
  created_at
  updated_at
  completed_at

agent_events
  id
  provider_event_id
  run_id
  event_type
  provider_resource_id
  received_at
  processed_at
Then I would wire webhooks into that table, not directly into business actions.
The webhook handler should only authenticate, dedupe, fetch current state, and store the event. A separate worker should decide whether to notify a human, resume a session, fetch a thread transcript, or mark the run complete.
That extra hop is what lets you debug the system later. It also makes it easier to swap providers. The same run model can hold Codex automation receipts, Claude Managed Agent sessions, or GitHub Copilot agent tasks.
What To Watch Next#
The next useful features will probably sound boring:
- first-class run budgets
- better thread export
- outcome history diffs
- webhook replay tooling
- built-in dead-letter queues
- per-agent cost attribution
- approval policies as code
- portable receipts across providers
Those are not flashy agent demos. They are the things that make agents safe to use every day.
That is why this Anthropic update matters. It is not just another layer of agent capability. It is another step toward agents being operated like backend systems.
The teams that win will not be the teams with the most dramatic autonomous demo. They will be the teams whose agents can fail quietly, resume cleanly, explain what happened, and hand off a receipt a human can trust.
Continue Reading#
- Claude Managed Agents in a Chrome Extension: ai-newtab Teardown - a client-side Managed Agents session, its cost claim and its security gaps
- Claude Code Auto Mode Explained - how classifier-backed permission review works in the terminal-agent lane
- Codex Goals vs Claude Managed Outcomes - where stop conditions and success criteria differ
- Long-Running Agents Need Harnesses - why durable sessions need queues, receipts, and retries
- The $400 Overnight Bill: Agent FinOps - spend controls for unattended agent runs
- Claude Managed Agents Dynamic Workflows: How to Use Workflow Runs - let an agent write a multi-agent workflow and run it server-side
Sources#
Sources fetched and verified September 15, 2026.
- Anthropic announcement - original Managed Agents orchestration, outcomes, dreaming, vault refresh, and webhook update
- Claude Managed Agents overview - current Managed Agents scope, beta status, toolset, and stateful session model
- Claude Managed Agents permission policies -
always_allow,always_ask,auto, event evaluation fields, and custom-tool boundary - Claude Managed Agents session budgets - hard budget behavior, list-cost enforcement, and
budget_reachedidle state - Claude Managed Agents webhooks - webhook delivery model and production integration rules
- Claude Managed Agents outcomes - rubric-driven completion evaluation
- Claude Platform release notes - September 10, 2026
autopolicy andant beta:sessions connectrelease note - HN Algolia search for Claude Managed Agents - weak recent community signal, used as non-viral demand context
- Google Trends US 90-day cluster, checked September 15, 2026:
Claude Managed Agents,Claude Code,AI coding agent,MCP permissions,agent permissions
FAQ#
What are Claude Managed Agents?#
Claude Managed Agents are Anthropic's hosted infrastructure for running longer-lived Claude agents with managed environments, sessions, tools, files, credentials, tracing, and orchestration features.
Why compare managed agents to backend jobs?#
Because production agent runs need the same mechanics as backend jobs: IDs, states, retries, webhooks, logs, budgets, approvals, and completion criteria. The model is only one part of the runtime.
What are multiagent sessions in Claude Managed Agents?#
Multiagent sessions let a coordinator agent delegate work to other configured agents inside one managed session. Worker agents have isolated context threads while sharing the same container and filesystem.
What are outcomes in Claude Managed Agents?#
Outcomes define what "done" means for an agent run. They use rubric-style criteria so the system can evaluate whether the output is satisfied, needs revision, reached max iterations, or failed.
How should developers handle Claude Managed Agents webhooks?#
Treat them like normal production webhooks. Verify signatures, deduplicate by event ID, fetch current resource state by ID, handle retries, and never assume delivery ordering.
Get the next deep dive like this in your inbox
One email a week on Claude and the rest of the AI dev stack. Free.
Read next on Claude Code
Codex /goal and Claude Managed Outcomes: The New Control Loops
Codex /goal vs Claude Managed Agents outcomes compared: where each control loop fits, the tradeoffs, and when to combine them for long-running tasks.
18 min readTerminal Agents Are the New Developer Runtime
Terminal agents like Claude Code, Codex CLI and OpenCode are converging on one runtime layer: permissions, sandboxing, rollback, receipts and cost controls.
9 min readLong-Running Agents Need Harnesses, Not Hope
Long-running coding agents need a harness: task contracts, scoped workspaces, logs, checkpoints, verification gates, and cost limits to recover from failure.
9 min readTechnical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.