Codex Logging Bug Can Write Terabytes to Your SSD
TL;DR
A Codex CLI SQLite logging bug wrote TRACE logs that could wear out SSDs. What caused it, the merged fixes, and what to check if you run Codex heavily.
Last updated: June 24, 2026
OpenAI's Codex CLI hit a useful local-agent operations lesson: a persistent SQLite feedback log was writing excessive diagnostic data, with one public report extrapolating the churn to hundreds of terabytes of SSD writes per year. The original GitHub issue is still reported as open by GitHub's API at verification time, but OpenAI has merged three related fixes and shipped the first two in Codex 0.142.0.
That changes the framing. This is no longer just "check your SSD right now." It is a case study in what happens when a global TRACE default meets a local database, and why coding agents need explicit resource budgets. If you run Codex heavily, update first, then check whether old log files still need cleanup.
The Bug#
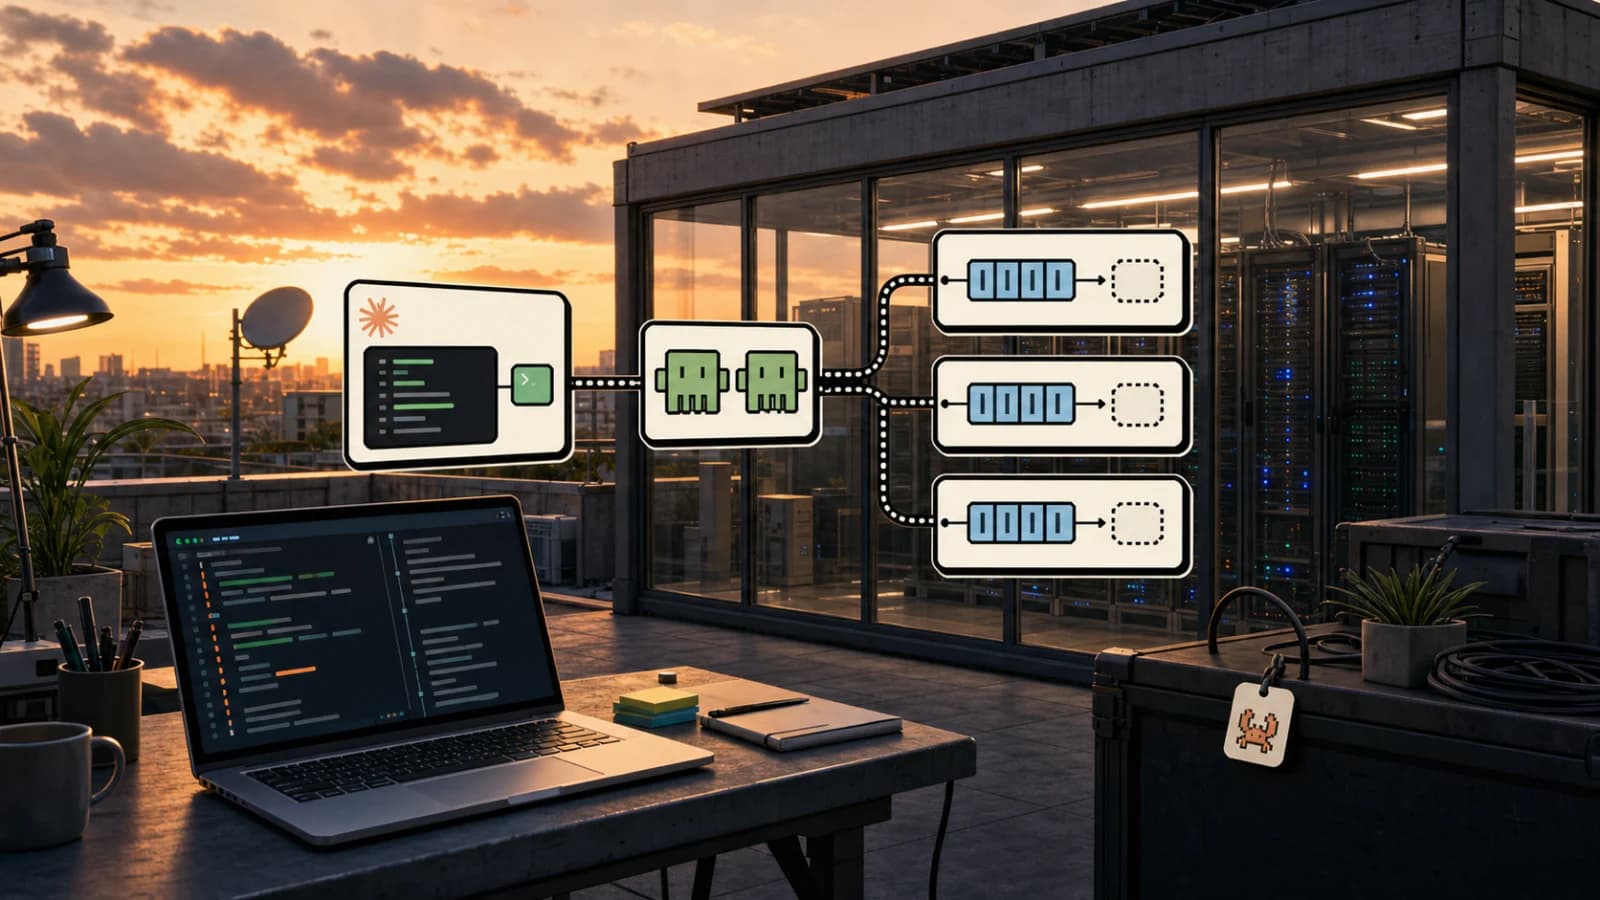
Codex continuously writes trace-level logs to ~/.codex/logs_2.sqlite and its associated WAL/SHM files. The logging is indiscriminate - it captures everything from low-value dependency logs (inotify events, locale lookups) to raw websocket payloads and OpenTelemetry diagnostic events.
By the numbers:
- Extrapolated write rate: ~640 TB/year
- One user reported ~37 TB written after 21 days of uptime
- TRACE-level logs account for approximately 71% of retained log bytes
The problem is compounded by write amplification in the SQLite database. Users report approximately 36,211 rows inserted per 15 seconds while the retained row count remains static - a continuous insert-and-prune cycle that multiplies actual disk writes.
A 1 TB SSD with 600 TBW (terabytes written) endurance rating could theoretically be worn out in less than a year of continuous Codex usage.
What Changed Since Publication#
The issue now has a better ending than the first version of this post suggested. OpenAI engineer jif-oai merged three PRs:
- #29432 stopped logging every Responses WebSocket event.
- #29457 filtered noisy persistent-log targets and duplicated telemetry records.
- #29599 added a follow-up filter for bridged dependency log events that still reached SQLite.
The Codex 0.142.0 release notes explicitly mention reduced persistent-log churn from the first two fixes. The third fix merged into main and is marked by the issue reporter as targeting 0.143.0; an alpha tag for 0.143.0 was already published on June 24, 2026.
The reporter updated the issue body saying those three PRs avoided about 85% of logs in their own Codex measurement. That is still a user-side measurement, not a formal benchmark, but it is enough to change the recommendation: upgrade before applying heavier workarounds.
Root Cause#
The SQLite feedback log sink used a broad TRACE-level persistence path. This meant high-volume log targets could write to disk even when their diagnostic value was low. The merged fixes did not remove logging entirely. They narrowed what gets persisted: raw WebSocket payload events, mirrored telemetry records, and bridged dependency TRACE events no longer belong in the durable SQLite sink.
That is the important design lesson for local agent tools. Telemetry is useful, but persistence needs a budget. Local logs should have level filters, target filters, retention limits, and a clear difference between interactive debugging and always-on background storage.
What HN is Saying#
The Hacker News thread is running hot. A few representative comments:
On quality:
"Codex is one of the most infamous examples of slopware. Just having the window unhidden on my mac will cause it to use 100% of the GPU displaying the spinner message."
"I don't understand how Codex can blunder so badly. I imagine that even if they would be using vibe-coding, surely they must have some good engineers."
On OpenAI's response:
"Shocking. Been open a week and AFAICT just silence from OpenAI. I just find it baffling. You'd think that these vendors would be very sensitive to this sort of issue."
"SQLite + unbounded TRACE logs = firehose in a bathtub. No rotation, no cap, no surprise. The RAISE(IGNORE) fix patches a design flaw. OpenAI's silence is worse than the bug."
Defending the nuance:
"This thread will become a typical 'haha slop company made slop' but I've been bitten by a bug exactly like this before in a (pre-AI, artisan) OSS project."
Fair point. Shipping trace logging to production is a classic blunder that predates AI coding tools by decades. The difference is the volume - modern SSDs are fast enough that the app remains usable while silently burning through drive endurance.
On AI tool quality generally:
"I want to like codex, but the quality is just not very good, especially when compared to Claude."
"OpenAI really snatched defeat from the jaws of victory late last year when Claude Code was a laggy mess. Nowadays Codex has typing latency out of the gate, whereas Claude Code has the odd pause but generally displays my key presses as... you know... I press them."
One commenter noted that Claude Code has similar logging behavior - "writes massive debug logs to ~/.claude/logs" - suggesting the problem may be broader than just Codex.
What To Do Now#
If you use Codex regularly, start with the boring path:
codex --version
If you are below 0.142.0, update before assuming the workaround is still necessary. Then inspect the current log footprint:
du -sh ~/.codex
ls -lh ~/.codex/logs_2.sqlite*
If old log files are still large after upgrading, you have options.
Option 1: Disable logging via SQLite trigger
sqlite3 ~/.codex/logs_2.sqlite "CREATE TRIGGER IF NOT EXISTS block_log_inserts BEFORE INSERT ON logs BEGIN SELECT RAISE(IGNORE); END;"
This blocks new log inserts at the database level. Use it as a temporary local workaround, not as the default team recommendation, because it removes useful diagnostics too.
Option 2: Reclaim space with VACUUM
sqlite3 ~/.codex/logs_2.sqlite "VACUUM;"
SQLite uses VACUUM, not PostgreSQL-style VACUUM FULL. Run it after quitting Codex so the database is not being actively written.
Option 3: Delete the log files
rm ~/.codex/logs_2.sqlite*
The files will be recreated, but you will have bought yourself time.
Option 4: Symlink to tmpfs
For users concerned about SSD wear, symlinking the logs directory to a RAM-backed tmpfs prevents disk writes entirely (at the cost of losing logs on reboot).
The Bigger Picture#
This bug is a reminder that even flagship developer tools from major AI labs can ship mundane systems bugs. Excessive logging is not new. What is new is the shape of the runtime: agent CLIs stay open for hours, stream events constantly, and often sit in the background while developers work elsewhere.
For teams evaluating AI coding assistants, bugs happen. What matters is whether the tool exposes enough local state to diagnose the problem, whether the vendor responds with targeted fixes, and whether your own workflow has resource guardrails. This is the same reason I keep coming back to Codex CLI resource budgets, Claude Code token burn observability, permissions and rollback for AI coding agents, long-running agent harnesses, and terminal agents as portable runtime surfaces.
The better takeaway is not "never trust Codex." It is that local agents need the same operational controls as any other long-running developer service: bounded logs, visible storage use, process lifetime controls, and upgrade discipline.
FAQ#
Is the Codex SQLite logging bug fixed?#
Partially, based on public evidence. OpenAI merged three PRs tied to the issue. The first two shipped in Codex 0.142.0; the third is marked by the reporter as targeting 0.143.0. At verification time, GitHub's API still reported issue 28224 as open, even though the issue body says the reporter intended to close it after the fixes.
Should I delete ~/.codex/logs_2.sqlite?#
If the file is huge, quit Codex first, upgrade, and then either delete the old SQLite/WAL files or run sqlite3 ~/.codex/logs_2.sqlite "VACUUM;". Deleting old logs may remove diagnostic history, but it is reasonable if the files are consuming disk space.
Does this mean Codex is unsafe to run?#
Not categorically. It means Codex, like any long-running local agent, should be monitored. Check version, disk footprint, log churn, and release notes. Teams should treat local agent CLIs as runtime software, not just one-off commands.
Is this only a Codex problem?#
No. The pattern is broader: local AI tools can write logs, caches, transcripts, embeddings, and checkpoints while staying open for long sessions. Codex issue 28224 is useful because the public report included concrete measurements and the fixes are visible.
Sources#
Get the next deep dive like this in your inbox
One email a week on News and the rest of the AI dev stack. Free.
Read next on AI coding tools
Agent-Manager: A Tmux TUI for Running Claude Code, Codex, and OpenCode Side by Side
Agent-Manager wraps tmux into a Go TUI that groups AI coding agents by project, shows live status for each, and lets you answer blocked agents or review their changes without attaching to their terminal.
7 min readOpenAI Open-Sourced Codex Security: What HN Thinks
Codex Security CLI and TypeScript SDK are now open source. What the repo contains and what HN says about scan cost, guardrails and local model support.
7 min readCodex Now Encrypts Multi-Agent Prompts, Breaking Local Auditability
OpenAI's Codex CLI now encrypts inter-agent communications for Sol and Terra models, leaving users unable to inspect what their agents are actually doing.
5 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.