LLMs Resolve Java Merge Conflicts Better Than Structured Tools - Because They Never Give Up
TL;DR
LLM agents resolve real Java merge conflicts more often than structured merge tools in a calibrated ConflictBench study. Their edge is coverage: tools abstain.
Last updated: July 31, 2026
Merge conflicts are the tax every parallel workflow pays, and the structured merge tools built to automate them (JDime, IntelliMerge, AutoMerge, FSTMerge) share a common failure mode: when their heuristics do not apply, they abstain and leave the conflict for a human. A new study from Virginia Tech asks whether an LLM agent can do better, and measures the answer on real Java conflicts with a judge that is calibrated against human labels before it grades anything.
The headline: on true conflicts, the LLM solvers match the developer's own resolution on 55.1% (OpenAI) and 61.7% (Gemini), versus 36.7% for the strongest structured tool. The edge is almost entirely coverage, not accuracy. When a structured tool does fire, it is competitive. It just fires far less often.
What the study did#
The researcher, Bowen Shen, built a harness called ConflictAgent on top of ConflictBench's 180 scenarios: 106 are Java, 93 are reconstructable into complete base/left/right triples, and all 93 were fed to each LLM. The scored population narrows further to 67 scenarios (49 true conflicts, 18 false), where the developer's resolution region can be reliably extracted.
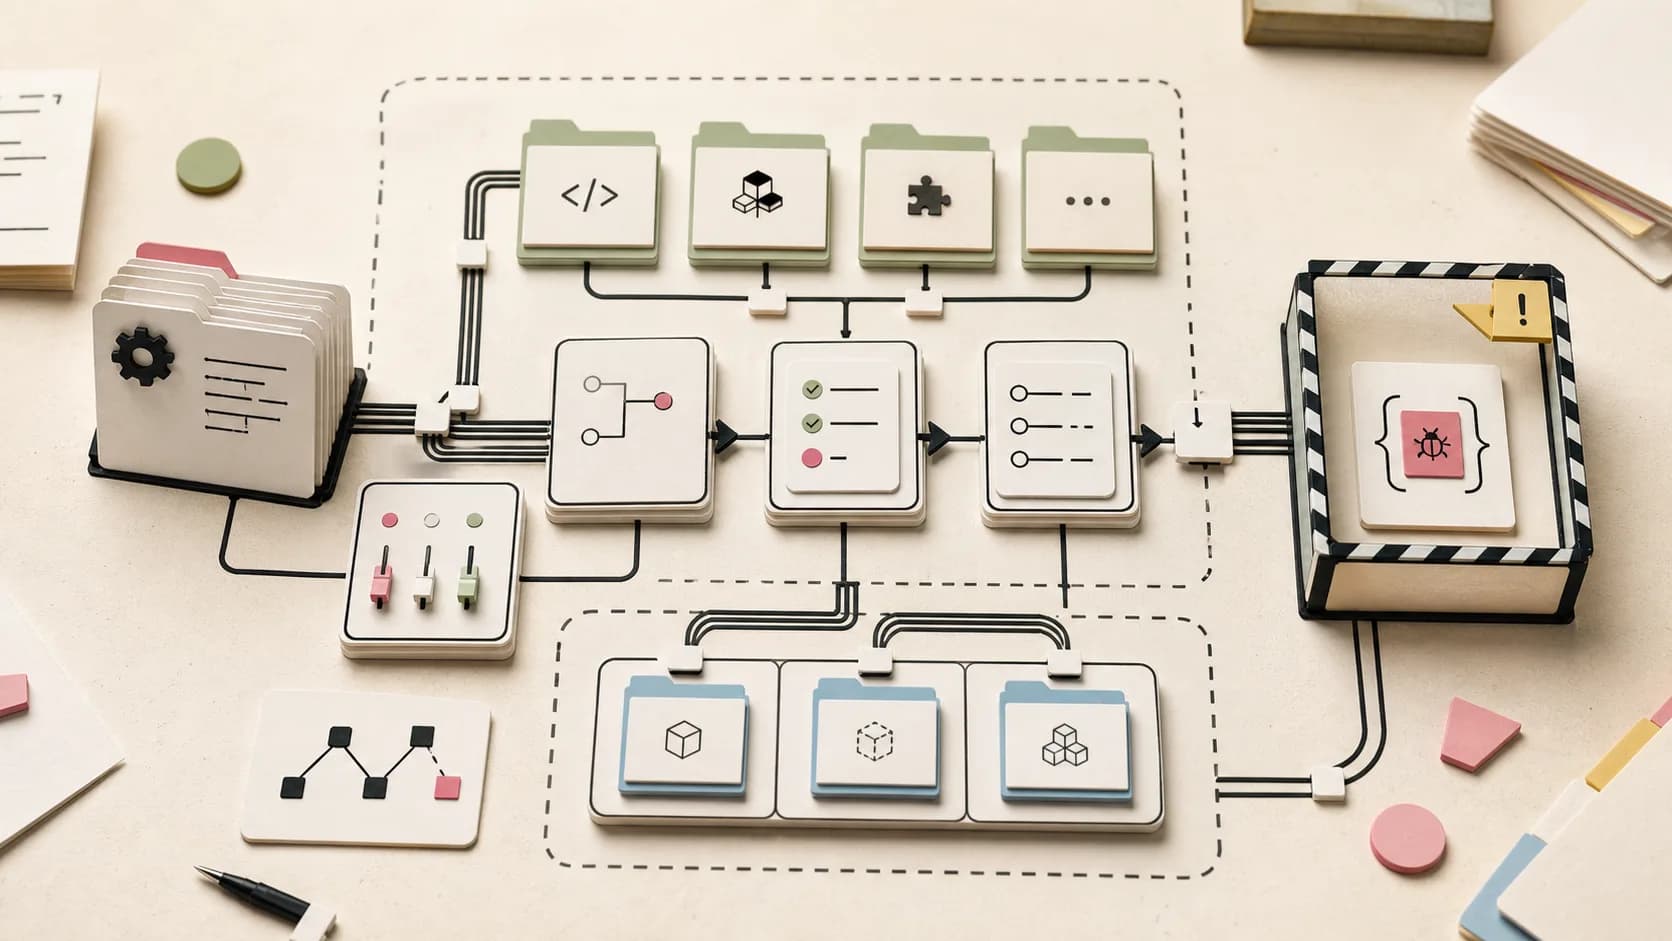
The solver is a generate-validate-retry agent with a strict information diet. It reconstructs the diff3 file with git merge-file --diff3, selects the target conflict block, builds a windowed prompt (the package/import/type skeleton plus the smallest complete brace scope enclosing the block), generates a resolution, and validates it with three inference-time signals only: no leftover conflict markers, a clean javalang parse, and no duplicate declarations. Validation failures feed back into up to four retries. It never sees the developer's answer or any judge verdict.
The two solvers were OpenAI's gpt-5.4-2026-03-05 and Gemini 3.5 Flash. The judge, deliberately, was a different vendor from both: claude-sonnet-4-6 at temperature 0, so no solver gets a self-preference. Before grading anything, the judge was calibrated against 292 human-labeled cases from ConflictBench. The meta-evaluation is the methodological core: 100% precision (zero false accepts) at 64.6% recall, accuracy 78.1%. Zero false accepts means every "acceptable" verdict is trustworthy, and every rate in the paper is a conservative lower bound, since the judge under-credits acceptable alternatives.
The numbers#
Developer-match rates on true conflicts (validated judge, threshold 0.5):
| Solver | Developer-match | Pooled |
|---|---|---|
| OpenAI (gpt-5.4) | 27/49 = 55.1% | 56/96 = 58.3% |
| Gemini (3.5 Flash) | 29/47 = 61.7% | - |
The coverage-fair comparison against the five ConflictBench tools tells the fuller story:
| Resolver | Among-resolved | Overall | Abstentions (of 49) |
|---|---|---|---|
| LLM Gemini | 61.7% | 59.2% | 0 |
| LLM OpenAI | 55.1% | 55.1% | 0 |
| AutoMerge | 47.4% | 36.7% | 10 |
| JDime | 54.8% | 34.7% | 16 |
| IntelliMerge | 48.1% | 26.5% | 22 |
| FSTMerge | 28.6% | 12.2% | 18 |
| KDiff3 | 50.0% | 4.1% | 45 |
When JDime fires, it matches the developer at 54.8%, essentially tied with the LLMs. The tools abstain on 20-90% of conflicts because their structural assumptions do not hold, and every abstention is a human merge. The LLM under forced resolution abstains on none.
The warning sign that matters most#
Structural validity ran as a separate, deterministic check: no leftover markers, parses as Java, no duplicate declarations. LLM resolutions passed 92/96 (95.8%) on true conflicts, and the 4 failures were all retries-exhausted cases. But the paper's most important finding is about the judge: of the 5 resolutions that failed the deterministic structural check, the LLM judge accepted 4. Structural correctness cannot be delegated to an LLM, even one that is otherwise calibrated. That is a finding with a shelf life well beyond merge conflicts.
My take#
Merge automation now has two regimes. Structured tools give you high precision when their heuristics apply, and silence otherwise. LLMs give you a plausible resolution for everything, 55-59% of the time matching what the developer actually did. Those are complementary, not competing: a sane pipeline runs the structured tool first, then lets an LLM take the abstained cases, gated by deterministic checks, never by an LLM's opinion of its own output.
This is the realistic shape of agentic merge handling. Teams already hit merge conflicts constantly when parallel coding agents touch shared files - the exact problem we covered in Git worktrees for parallel Claude agents and Claude Code worktrees. The paper's windowed-prompt trick (skeleton plus smallest complete brace scope, not the whole file) is a good pattern for anyone building that: it keeps the token cost flat and the context tight, which our coverage of context files and agent ablation suggests is exactly where agents behave best.
Reduce the number of conflicts you have to resolve. 55% match is a floor, and the study does not pretend otherwise - the judge's 64.6% recall means it under-credits good alternatives, so the true rate is higher. But no tool makes conflicts fun. GitHub's stacked PRs attack the same cost from the other direction: smaller, ordered, fast-merging PRs produce fewer and smaller conflicts in the first place. The best merge resolution is the one that never happens.
Caveats: Java only, 49 scored true conflicts, one snapshot of three model versions, and the judge is a single model at a single threshold. The harness is released as an open engineering artifact, so the methodology can be rerun as models improve. That matters: if the match rate climbs toward 70-80% with the next model generation, the default position on merge conflicts shifts from "human resolves, tools help" to "agent proposes, human reviews".
FAQ#
Can LLMs resolve merge conflicts better than structured merge tools?#
On the study's 49 scored true Java conflicts from ConflictBench, LLM solvers matched the developer's own resolution on 55.1 percent (OpenAI) and 61.7 percent (Gemini), versus 36.7 percent overall for the strongest structured tool, AutoMerge. The edge is coverage: the tools abstain on 20 to 90 percent of conflicts, while the LLM abstained on none.
Are structured merge tools less accurate than LLMs when they do resolve a conflict?#
Not by much. Among the conflicts it resolved, JDime matched the developer at 54.8 percent, essentially tied with the LLMs. Structured tools are competitive when their heuristics apply; they just fire far less often.
How was the LLM judge in the study validated?#
The judge was claude-sonnet-4-6 at temperature 0, a different vendor from both solvers. It was calibrated against 292 human-labeled ConflictBench cases first, reaching 100 percent precision with zero false accepts at 64.6 percent recall, so the reported match rates are conservative lower bounds.
Can an LLM judge be trusted to check structural correctness?#
No. Of the 5 resolutions that failed the deterministic structural check (leftover markers, Java parse, duplicate declarations), the LLM judge accepted 4. The post recommends running structured tools first, letting an LLM take abstained cases, and gating results with deterministic checks rather than an LLM's opinion.
Continue Reading#
- Git Worktrees and Parallel Claude Agents: A Complete Guide
- GitHub Stacked PRs Hit Public Preview
- Agent PR Governance: What We Learned Running GitHub Copilot Code Review
- SWE-NFI: Studying Coding Agents for Non-Functional Improvements
- Do Context Files Help Coding Agents? A Two-Agent Ablation
Sources#
- Can Large Language Models Resolve Real Java Merge Conflicts? An Evaluation with a Calibrated LLM-as-Judge - arXiv:2607.27674 (abstract)
- Full paper HTML - arXiv:2607.27674v1
- ConflictBench: a benchmark to evaluate software merge tools - Shen & Meng, Journal of Systems and Software 214 (2024), doi:10.1016/j.jss.2024.112084 (the dataset the study builds on)
Get the next deep dive like this in your inbox
One email a week on News and the rest of the AI dev stack. Free.
Read next
Git Worktrees + Claude Code: Run Parallel Agents in 2026
Several Claude Code agents on one repo cause branch collisions and stash chaos. Git worktrees give each agent its own directory on one shared Git history.
7 min readGitHub Stacked PRs Hit Public Preview: Small Reviews for the Agent Era
GitHub stacked pull requests are in public preview: how stacks split one large change into small, reviewable PRs with one-click merge and a gh-stack skill.
7 min readAgent PR Governance: The New Rules for Copilot Reviews
Agent PR governance for Copilot code review: a five-layer policy stack for agent-authored pull requests, from agent validation and review depth to attribution.
8 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.