11 min read
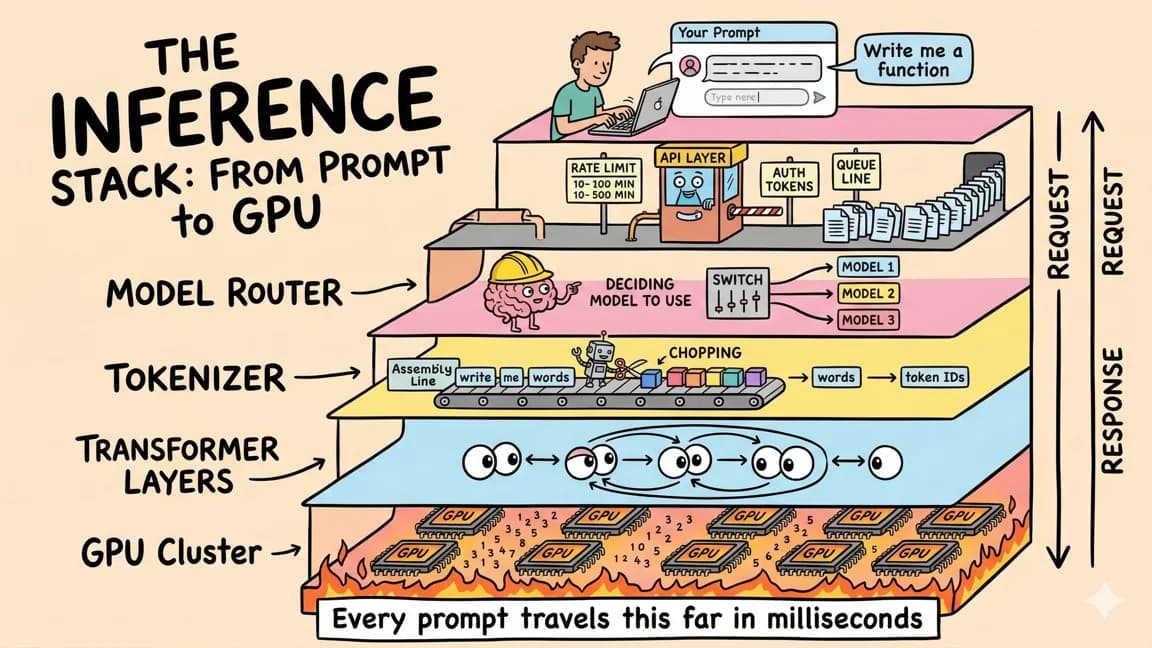
KV Caching: A Practical Guide to Optimizing Transformer Inference
How KV caching speeds up LLM inference - the math, the code, the memory tradeoffs, and when it stops helping. Every dev running local models hits this wall.
Read more
15 articles - page 2 of 2
How KV caching speeds up LLM inference - the math, the code, the memory tradeoffs, and when it stops helping. Every dev running local models hits this wall.
Qwen3.6-27B is the local coding model to benchmark first: what hardware it needs, which jobs it should take over, and where a frontier API still wins.
Showing 13-14 of 14 articles

New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
Explore 840 topics
Browse All Topics