7 min read
PAIChecker: 13.6% of SWE-bench Verified Instances Have Misaligned PR-Issue Pairs
PAIChecker finds 13.6% of SWE-bench Verified instances pair a PR with an issue it does not resolve, penalizing agents that solve the stated problem.
57 articles - page 4 of 5
PAIChecker finds 13.6% of SWE-bench Verified instances pair a PR with an issue it does not resolve, penalizing agents that solve the stated problem.
SIGIL compiles prose SKILL.md files into typed agent harnesses. Prose runs execute 56% of mandated steps; compiled harnesses reach 86% with 0.58x the tokens.
SWE-NFI benchmarks coding agents on 188 behavior-preserving improvement tasks. The best hits 70% correctness, but all lag humans on structural refactors.
What if AI was free tomorrow at today's capabilities? A thought experiment on what changes for developers when price hits zero, and what stays scarce.
A $500 GRPO fine-tune of Qwen 3.5 9B beat GPT-5.6 Sol and Opus 4.8 on catalog review, hitting 97% accuracy at a fraction of the cost per listing.
FLUX 3 from Black Forest Labs is one multimodal model for image, video, audio, and robot actions. What it does, how it works, and how to try it.
Claude Fable 5 found a counterexample to the 87-year-old Jacobian conjecture, and Terence Tao worked through the math. How it works and what HN is saying.
Dockerless, ByteDance's environment-free verifier for coding-agent patches, explained - why it complements CI as a cheaper evidence stage before full test runs.
Ghost Font hides text in video using motion, so humans can read it but frame-by-frame AI models cannot. How it works and how HN commenters broke it.
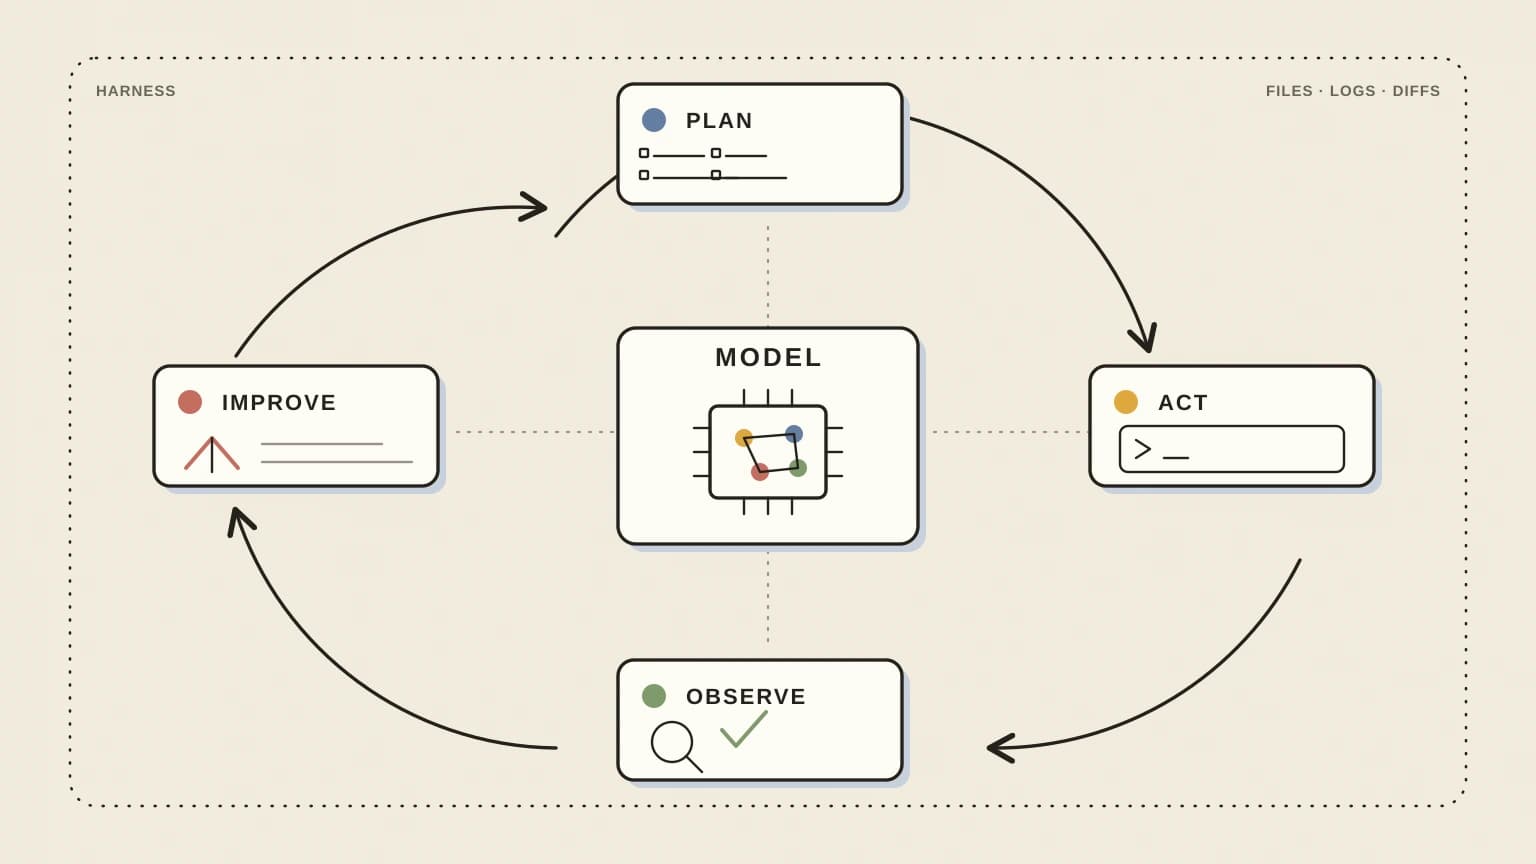
Harness engineering is where self-improving AI starts, Lilian Weng argues, not models rewriting their weights. What that means for developers building agents.
Ilya Sutskever's rumored 30-paper ML reading list, now on 30papers.com. What the papers cover, the compression thesis behind them, and what HN thinks.
A Dartmouth study of an AI tutor in intro statistics links full engagement to a 0.71-1.30 SD exam gain. What it measured, and why selection bias still matters.
Showing 37-48 of 56 articles

New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
Explore 840 topics
Browse All Topics