MCP Apps vs Tool Calling vs Standalone UIs: Interactive Interfaces for Agent Tools Compared
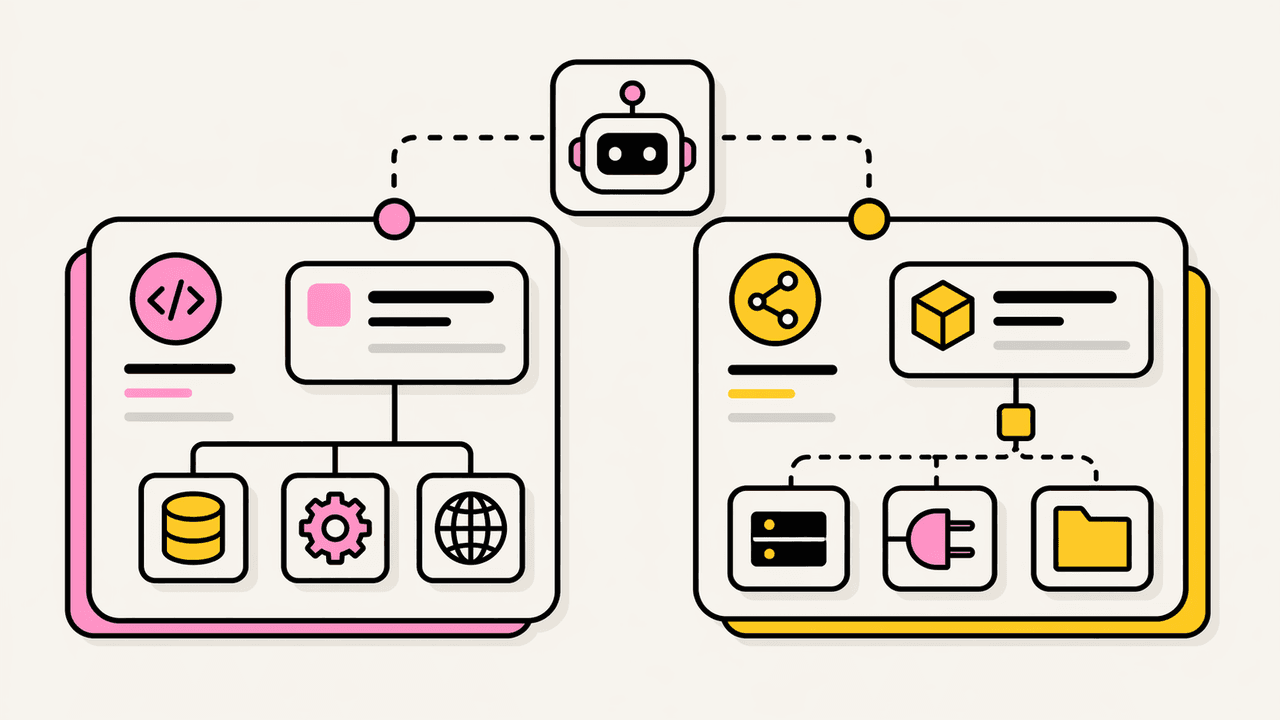
MCP Apps vs tool calling vs standalone web UIs: how sandboxed interactive UIs for MCP servers compare to the other two, and when to use each approach.
Page 37 of 100
Deep dives into AI agents, coding tools, and building with LLMs.
1192 articles844 topics

MCP Apps vs tool calling vs standalone web UIs: how sandboxed interactive UIs for MCP servers compare to the other two, and when to use each approach.

MCP vs Agent Skills: MCP gives agents live access to tools and data, Skills give them packaged procedure. The decision rule for when to use which, or both.

TurboFieldfare runs Google's Gemma 4 26B MoE model in about 2 GB of RAM on any Apple Silicon Mac by streaming experts from SSD. How it works and what HN said.

Wiki skills add the missing graph layer to agent context: skills that link to each other let agents navigate knowledge instead of front-loading it all.

Zig incremental compilation explained from a core team deep dive: file pipeline, semantic analysis, dependency tracking, the custom linker and HN reaction.

A $500 GRPO fine-tune of Qwen 3.5 9B beat GPT-5.6 Sol and Opus 4.8 on catalog review, hitting 97% accuracy at a fraction of the cost per listing.

AI coding agent firewalls compared: Belay, Claude Code hooks, Codex CLI sandboxes and MCP proxies vs destructive commands, secret leaks and prompt injection.

AI coding agent security models compared: how Claude Code, Cursor, Codex, Copilot, Aider and Windsurf handle permissions, sandboxing and prompt injection.

Dario Amodei on open-weights models: export controls, distillation crackdowns and mandatory safety testing, the HN pushback, and what it means for developers.

Opus 5 on SlopCodeBench hit a 24% strict pass rate, beating Opus 4.8 and Sonnet 5, yet code quality still degraded. What it shows about coding agents over time.

Claude Mythos Preview found new weaknesses in the HAWK post-quantum signature scheme and reduced-round AES. What the research shows and how HN reacted.

Kimi Linear explained: Moonshot's KDA hybrid linear attention beat full attention with 75% less KV cache and up to 6x faster decoding at 1M context.
Showing 433-444 of 1192 articles
Deep dives on AI agents, coding tools, and building with LLMs - delivered weekly. No spam.
Free forever. Unsubscribe anytime.

New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.