13.5 Million Copilot Sessions: What Production Coding Agent Traffic Actually Looks Like
TL;DR
Copilot traces from 3.2M users and 761M LLM calls: 87% of calls are agent-initiated, KV cache hits drop at turn boundaries, tool failures multiply compute.
Last updated: August 4, 2026
Every claim you have heard about how coding agents behave under load has been inferred from synthetic benchmarks and small pilots. A new paper from UIUC and Microsoft Azure Research replaces those inferences with production telemetry: 13.5M sessions from 3.2M GitHub Copilot users over one week in June 2026, covering 761M LLM calls, 775M tool invocations, and 95T tokens across 27 models and 45 tools.
The title says it plainly: Agentic Coding in the Wild (arXiv 2608.00101). It is the first production-scale characterization of coding agent workloads, and its findings cut directly against how LLM serving systems are built today.
What the traces show#
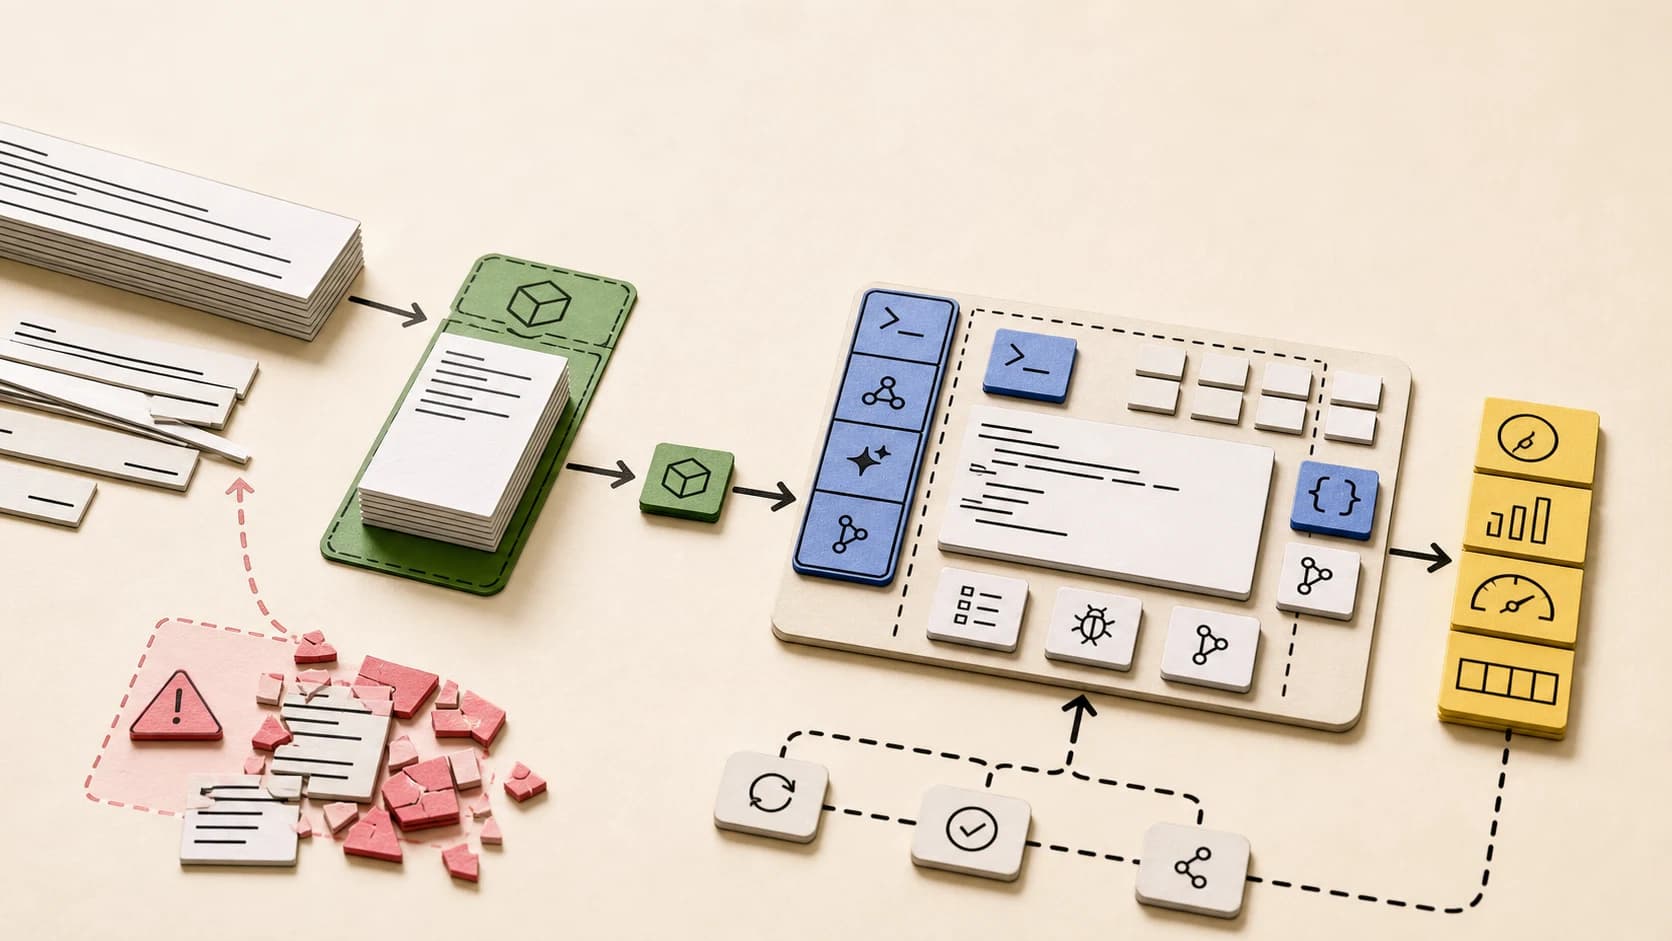
The paper is organized around a single structural fact: a coding agent session is not a stream of independent requests. It is a chain of tightly coupled LLM calls and tool executions, and every serving assumption built for chat workloads sits uneasily against it.
Agents initiate almost everything. 87% of LLM calls are agent-initiated, not user-initiated. The average turn unfolds 6.6 autonomous LLM calls after a single user prompt. LLM calls and tool invocations run at a near-1:1 ratio (median session: 15 LLM calls, 13 tool calls), because most calls produce a tool action and most tool results immediately trigger another call.
Sessions are violently heavy-tailed. The median session is 3 user turns, 15 LLM calls, and 4.2 minutes. The mean is 6.1 turns, 40.6 calls, and 62.6 minutes. The P90 session exceeds 100 LLM calls and 3 hours, and session duration has a 14.9x mean-to-median skew. A small fraction of long sessions dominate serving load, which matters because those are exactly the sessions whose KV cache you are holding in GPU memory.
Calls are input-heavy and output-light. Median prompt: 68K tokens. Median completion: 247 tokens. A 275:1 input-to-output ratio. Conversation history is 48% of prompt tokens and tool-call results another 28%, so the model spends its context re-reading its own actions. This flips the serving bottleneck from generation throughput to KV cache efficiency.
The KV cache lifecycle is the real story#
Prefix caching works beautifully inside a turn. Median cache hit rate is 98%, and the trajectory is predictable: 45% on the cold-start call, 86% by the second call, 92-94% plateau from the third onward.
Then the structure breaks it:
- Turn boundaries drop hit rates 26% on average. Between turns, users pause (median 4.1 minutes of container idle, 2.9 minutes of KV cache idle), and time-based eviction policies reclaim the cache. The paper maps the cliff precisely: hit rates hold above 95% for idle gaps under 2 minutes, collapse to ~70% across the 2-10 minute window, and near zero beyond 10 minutes.
- Model switches are cache destruction. Only 6.4% of sessions switch models, but average cache hit rate after a switch is 8%. Switches are mostly reactive: 36% of sessions that switch had recent errors versus an 8% baseline, driven by rate limiting and throttling. Manual-to-auto switches downgrade 52% of the time; users taking control back upgrade 51% of the time.
- Context compaction is a first-class systems event. 7.8% of sessions compact, but those sessions consume 44.2% of total tokens and 37.1% of LLM calls. A compaction call sits on the critical path for a median 22% of turn execution time, rewrites the prompt (median 72.8% of tokens dropped), and destroys the cached prefix as thoroughly as a model switch, with 21% of events erasing 99%+ of cache hit rate.
Tool failures are the hidden compute multiplier. 9% of turns hit tool failures, and the agent does not give up - it retries. Failure-driven turns average 36 LLM calls versus a median of 4.5, with growing context windows as error output accumulates, amplifying compute up to 4x. In chat, a failed request returns an error. In an agent, it starts a retry loop that cascades into dozens of calls.
Why it matters to anyone building on agents#
Your cost model is wrong if it treats calls as independent. The dominant cost of agentic coding is not generation, it is re-prefilling context that was evicted. The paper quantifies the spread: a cache miss costs a Deep-loop user a median re-prefill of 1.1M tokens versus 23K for a chat-only user, a 50x disparity under a uniform eviction policy. That connects directly to our analysis of why agent API bills balloon: the billing line item you see is mostly re-computed tokens, not new ones.
Turn boundaries are the actionable signal. The paper's practical contribution is a 2MB LightGBM ensemble that predicts, at each turn boundary, how long a session will stay idle. It captures 86-90% of total idle time and evaluates in under 3ms, and it works at the API level: when predicted idle straddles a provider's cache retention window (Claude's default is 300 seconds), issue a cheap keep-alive request before the deadline to avoid a full recompute. Our guide to cache-first coding agent design argued the cache is the product; this paper shows it is the infrastructure too.
Tool reliability is serving efficiency. The 4x compute amplification from retry loops means the cheapest serving optimization is not a better scheduler, it is more reliable tools and agents that verify before acting. If you run agent fleets, instrument tool failure rates before you optimize prompt tokens.
Uniform policies tax your heaviest users. Five user archetypes span a 50x token range, from chat-only users at 23K tokens per turn to Deep-loop users at 1.1M. Readers (41.7% of users) are stateless and cheap to cold-start. Deep-loop users (9.2%) run 20 tools per turn at 1.1M tokens and should never be evicted mid-turn. Serving systems, sandboxes, and billing tiers that treat everyone the same waste money on one end and add latency on the other.
My take#
The paper is the empirical foundation for what agent-native backend design has been claiming: serving systems built for chat - request-level scheduling, LRU eviction, independent batching - are structurally mismatched to agentic coding. The fix is not a patch on vLLM or SGLang; it is session-aware scheduling, retention windows tuned to turn structure, and cache state that survives model routing.
The most useful practical number: 90% of intra-turn traffic is cache hits, and the entire value of that caching evaporates at turn boundaries and model switches. Anything you do to keep sessions on one model, keep idle gaps under two minutes, or keep-alive a cache entry before eviction directly cuts serving cost. The inverse is also true: every tool that fails costs up to 4x more than the equivalent successful call.
We already knew benchmarks lie about production behavior. This is the first time the production behavior itself is the dataset, and it validates the direction more than any SWE-bench run could: the future of LLM serving is agent-shaped, or it is expensive.
FAQ#
How much Copilot traffic did the Agentic Coding in the Wild paper analyze?#
The UIUC and Microsoft Azure Research paper covers 13.5M sessions from 3.2M GitHub Copilot users over one week in June 2026, including 761M LLM calls, 775M tool invocations, and 95T tokens across 27 models and 45 tools.
What share of coding agent LLM calls are agent-initiated?#
87% of LLM calls are agent-initiated rather than user-initiated. An average turn unfolds 6.6 autonomous LLM calls after a single user prompt, and LLM calls and tool invocations run at a near 1:1 ratio.
Why do turn boundaries hurt KV cache hit rates?#
Users pause between turns, and time-based eviction policies reclaim the cache during that idle time. Hit rates drop 26% on average at turn boundaries, holding above 95% for idle gaps under 2 minutes, collapsing to about 70% across the 2-10 minute window, and falling near zero beyond 10 minutes.
How much extra compute do tool failures cost?#
9% of turns hit tool failures, and the agent retries instead of giving up. Failure-driven turns average 36 LLM calls versus a median of 4.5, with context growing as error output accumulates, amplifying compute up to 4x.
What can teams do to reduce agent serving costs based on these findings?#
Keep sessions on one model, keep idle gaps under two minutes, and issue a cheap keep-alive request before a provider's cache retention window expires. The paper's LightGBM idle predictor is built for that keep-alive decision, and more reliable tools cut the retry loops behind the 4x amplification.
Continue Reading#
- DeepSeek V4: Cache-First Architecture for Coding Agents
- Claude Code Token Burn: Cache and Observability
- The $400 Overnight Agent Bill: A Cost Autopsy
- Agent-Native Backends: A New Serving Category
- Your Benchmark Is Lying to You
Sources#
Get the next deep dive like this in your inbox
One email a week on News and the rest of the AI dev stack. Free.
Read next on AI coding tools
Reasonix Shows the Next Coding Agent Fight Is Cache Discipline
Reasonix builds a DeepSeek coding agent loop around prefix caching. When cache discipline keeps long sessions cheap, and when it fights the harness.
7 min readClaude Code Token Burn Is an Observability Problem
Claude Code token burn is an observability problem. Why coding agents need cache-hit telemetry, spend ceilings and repro-grade usage logs, not a quota bar.
8 min readThe $400 Overnight Bill: Why Managed Agents Need FinOps Now
Five managed-agent providers, five pricing models, zero unified cost attribution. If you're running agents overnight, you need FinOps you don't have yet.
13 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.