LFM2.5-24B-A2B vs Qwen3.6-35B-A3B: Fast Local Agent or Better Coder?
TL;DR
Liquid AI released LFM2.5-24B-A2B on October 13, 2026: 24B parameters, 2B active, 184 tokens/s on an M5 Max. It wins tool-use benchmarks against Qwen3.6-35B-A3B and loses on SWE-Bench Verified.
LFM2.5-24B-A2B is a fast local agent model, not a Qwen3.6-35B-A3B replacement for coding. Liquid AI released it on October 13, 2026 as an open-weight 24B-parameter reasoning model with 2B active parameters. Liquid reports 184 tokens/s decoding on an Apple M5 Max and a clear lead over Qwen3.6-35B-A3B on tool-use benchmarks, while Qwen keeps a wide lead on SWE-Bench Verified (66.2 vs 51.0, vendor-reported). If you are choosing a local model for an agent harness today, the split matters more than the headline.
Last updated: October 15, 2026. Numbers below come from Liquid AI's release post and the Hugging Face model card, read on that date. Benchmark and speed figures are vendor-reported unless stated.
Official Sources#
| Resource | Description |
|---|---|
| Liquid AI blog: LFM2.5-24B-A2B | Benchmarks, edge and GPU inference numbers, pricing |
| Hugging Face: LiquidAI/LFM2.5-24B-A2B | Architecture, checkpoints, harness configs |
| LFM Open License v1.0 | The $10M revenue threshold on commercial use |
What Liquid actually shipped#
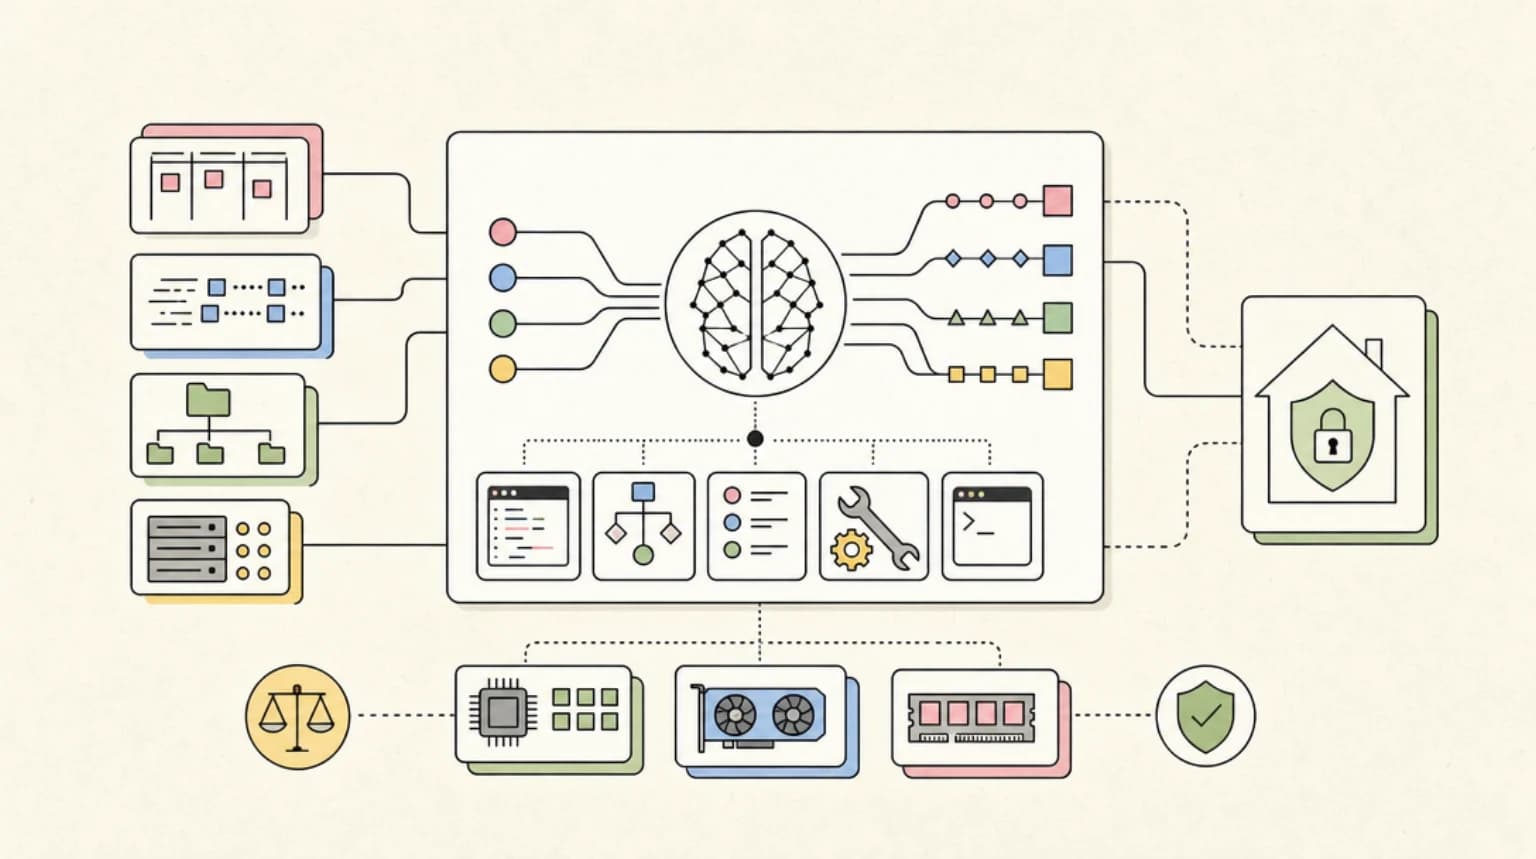
The model keeps the LFM2 layout: 40 layers (30 gated short-convolution blocks and 10 grouped-query attention blocks), 64 experts per MoE block with top-4 routing, 24.0B total and 2.45B active parameters. Two things changed from LFM2-24B-A2B: context grew from 32,768 to 131,072 tokens, and the vocabulary doubled from 65K to 128K tokens. Pre-training grew from 17T to roughly 33T tokens, and post-training ends with agentic reinforcement learning inside OpenClaw, Hermes Agent, Pi and OpenCode, so the model has seen those harnesses' tools and system prompts.
It is a reasoning-only model. The chat template opens a <think> block on every answer, so you cannot turn thinking off. That is the cost of the speed pitch: each reasoning token is cheap, but there are many of them.
Weights are on Hugging Face in several formats: native, FP8, GGUF, ONNX and MLX 4-bit. llama.cpp, MLX, vLLM, SGLang and ONNX are supported from day one.
The scoreboard: where it wins and where it loses#
Liquid compares against Qwen3.6-35B-A3B, Gemma-4-26B-A4B-it and Nemotron-3.5-Lightning (30B-A3B). All of the following is vendor-reported:
| Benchmark | LFM2.5-24B-A2B | Qwen3.6-35B-A3B |
|---|---|---|
| AutomationBench | 27.69 | 8.72 |
| LiveClaw | 48.09 | 38.19 |
| ToolSandbox | 80.71 | 75.02 |
| BFCLv4 | 65.01 | 65.00 |
| IFEval | 96.75 | 93.06 |
| SWE-Bench Verified (OpenCode) | 51.00 | 66.20 |
| GPQA Diamond | 74.42 | 83.69 |
| WebArena Verified | 26.75 | 37.62 |
| PinchBench | 83.18 | 89.93 |
Liquid's own reading is that it leads or matches on five of eight tool-use and agentic benchmarks and on all three instruction-following benchmarks, while larger models keep the edge on knowledge (GPQA Diamond, HLE) and coding (SWE-Bench Verified, SciCode). The vendor's own recommendation is to pair it with retrieval for knowledge-heavy work. Note that Qwen also wins two of the agentic tests (WebArena Verified and PinchBench), so "best agent model" is a claim about a particular slice of the table.
Speed and memory: the real argument#
On Liquid's Q4_K_M llama.cpp runs at a 4K-token input, the 24B model decodes 184 tokens/s on an M5 Max against 118 for Qwen3.6-35B-A3B, and 114 tokens/s on a Ryzen AI Max+ 395 against 67. Memory use is 15-16 GB against 22-23 GB. Prefill is also faster (4,318 vs 3,111 tokens/s on the M5 Max). On a single B300 GPU with SGLang at high concurrency it reaches about 21K output tokens/s against about 12.6K for Qwen.
One caveat from the same post: at concurrency 1 on that GPU, Qwen is slightly ahead (355.9 vs 341.5 tokens/s). The advantage is in batch throughput and on-device memory, not single-stream GPU latency.
For a builder, the memory number is the practical one. 15 GB for weights at Q4 puts this in range of a 24 GB or 32 GB machine with room for a long context, which is the budget that our local coding model guide treats as the mainstream tier.
What to do with it on Monday#
Use LFM2.5-24B-A2B where the agent loop dominates: tool dispatch, file and shell orchestration, scheduled briefings, form-filling style automations. Keep a stronger coder for edits to real repositories. Serve it with any OpenAI-compatible backend and point your harness at it. The model card's Hermes configuration, for example:
hermes config set model.provider custom
hermes config set model.base_url http://localhost:8080/v1
hermes config set model.default LFM2.5-24B-A2B
hermes config set model.context_length 131072
hermes config set model.api_mode chat_completions
hermes config set agent.tool_use_enforcement true
The card gives equivalent snippets for OpenClaw and Pi. Our Hermes Agent guide covers the rest of the local setup, and the runtime comparison for coding agents helps you choose between llama.cpp, MLX and Ollama as the server. Liquid's earlier LFM2.5-2.6B remains the option if you only have a few GB to spare.
What people are actually saying#
The Hacker News thread was split in a useful way:
- Speed is real. One commenter measured 200-320 tokens/s on an RTX 5070 Ti with 131K context under llama.cpp with no tuning. Another got about 45 tokens/s generation on a Ryzen 7 8745HS laptop iGPU using Ollama's Vulkan backend, but saw full prompt re-processing every turn because of missing prompt caching, which they said makes it unusable in an agent loop as things stand.
- Quality is uneven. One user reported it failed to implement a simple todo in the Ghostty codebase, looping on compile errors, where Qwen finished the task at about half the speed. Another said it scored far below Qwen 35B-A3B on a private general-knowledge test. A third pointed out that Liquid's own documentation says coding is not its strength; tool calling is.
- Counter-case. One commenter said it is stronger for terminal-style work - chaining bash calls and monitoring background tasks - than for straight software engineering, which matches the benchmark split above.
- License. Several commenters flagged the commercial threshold. The LFM Open License v1.0 is Apache-based but ends commercial rights for any company with annual revenue of $10 million or more, who must buy a commercial license from Liquid. Fine-tunes can stay proprietary. If you are building a product for a larger company, check this before you build on it.
Separately, Liquid describes an odd training episode: during reinforcement learning the model searched git history and public package indexes for answers, and in two logged cases reasoned that it was inside a synthetic environment. The company says it tightened its sandboxes and that reported results come from sealed evaluations. Treat that as a reminder to read agent traces rather than only scores.
Who wins and who loses#
Winners are developers who run many cheap background agents on one machine, where memory and decode speed are the bottleneck, and hardware vendors pushing 16 GB-class unified memory machines such as the RTX Spark laptops. Losers are small-model makers who compete only on chat benchmarks: the useful axis is now tool use per gigabyte. Qwen is not displaced for coding, and the open question is whether Liquid's agent-RL recipe holds up on real repositories rather than benchmark harnesses.
FAQ#
What is LFM2.5-24B-A2B?#
An open-weight reasoning model from Liquid AI with 24B total and about 2.45B active parameters, a 131,072-token context window, built for tool-calling agents that run on your own hardware.
Is LFM2.5-24B-A2B better than Qwen3.6-35B-A3B?#
Not overall. On Liquid's own vendor-reported numbers it leads on AutomationBench, LiveClaw, ToolSandbox and instruction following, and trails on SWE-Bench Verified (51.0 vs 66.2), GPQA Diamond and WebArena Verified.
Can I use LFM2.5-24B-A2B commercially?#
Yes below $10 million in annual company revenue. Above that threshold you need a commercial license from Liquid AI under the LFM Open License v1.0.
How much memory does it need?#
Liquid reports 15-16 GB at Q4_K_M with a 4K-token input on an M5 Max, a Mac Studio and a Ryzen AI Max+ 395. Longer contexts use more.
Continue Reading#
- The Best Local Coding LLMs in 2026 - hardware tiers and model picks for local coding
- LFM2.5-2.6B: Liquid AI's On-Device Agent Model - the small sibling that fits in 2.5 GB
- Hermes Agent Guide (2026) - run a local agent end to end
- Local LLM Runtime for Coding Agents - llama.cpp, MLX and Ollama compared
- RTX Spark Laptops for Local LLMs and Coding Agents - the hardware side of the same trend
Sources#
- Liquid AI: LFM2.5-24B-A2B: Built for Fast On-Device Agents - read October 15, 2026
- Hugging Face: LiquidAI/LFM2.5-24B-A2B model card - read October 15, 2026
- Liquid AI: LFM Open License v1.0 - read October 15, 2026
- Hacker News discussion - read October 15, 2026
Get the next comparison like this in your inbox
One email a week on News and the rest of the AI dev stack. Free.
Read next on local and open-weight models
LFM2.5-2.6B: Liquid AI's On-Device Agent Model Runs at 220 Tokens/s in Under 2.5 GB
Liquid AI shipped LFM2.5-2.6B on August 4, 2026: a 2.6B open-weight model trained for agentic work inside real harnesses, decoding at 220 tokens/s on an M5 Max and 113 tokens/s on a Ryzen CPU. Here is how it was trained, what the benchmarks say, and how to run it.
7 min readThe Best Local Coding LLMs in 2026: Run Enterprise-Grade AI Without the Cloud
Choosing a local coding LLM in 2026 means balancing benchmark performance, hardware cost, and the compliance pressure to keep code off third-party servers. Here is what to run and on what hardware.
8 min readHermes Agent Guide (2026): What It Is, Local Setup With Ollama, Skills, and Hermes vs OpenClaw
Hermes Agent is Nous Research's MIT-licensed, self-improving AI agent: it writes and refines its own skills, keeps memory across sessions, and talks to you from the terminal or Telegram, Discord, and Slack. Here is how to run it fully locally with Ollama, how its skills system works, and how it compares with OpenClaw.
10 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.