Prime Agent: A Self-Improving Coding Harness Where Everything Is Python
TL;DR
Prime Agent is Prime Intellect's open-source coding harness with one tool, a persistent IPython kernel. How it works, its benchmarks, and Claude Code compared.
Prime Intellect shipped Prime Agent on August 5, 2026. It is an open-source coding and research harness under the MIT license, and it makes two bets that are unusual enough to be worth a serious look even if you never switch off your current agent.
The first bet: the model gets exactly one tool. Not a file-read tool, a file-write tool, a bash tool, a grep tool and eleven MCP servers. One tool, ipython, backed by a kernel that stays alive across turns. Every capability - editing files, running your test suite, calling a skill, spawning a sub-agent - is a line of Python typed into that kernel.
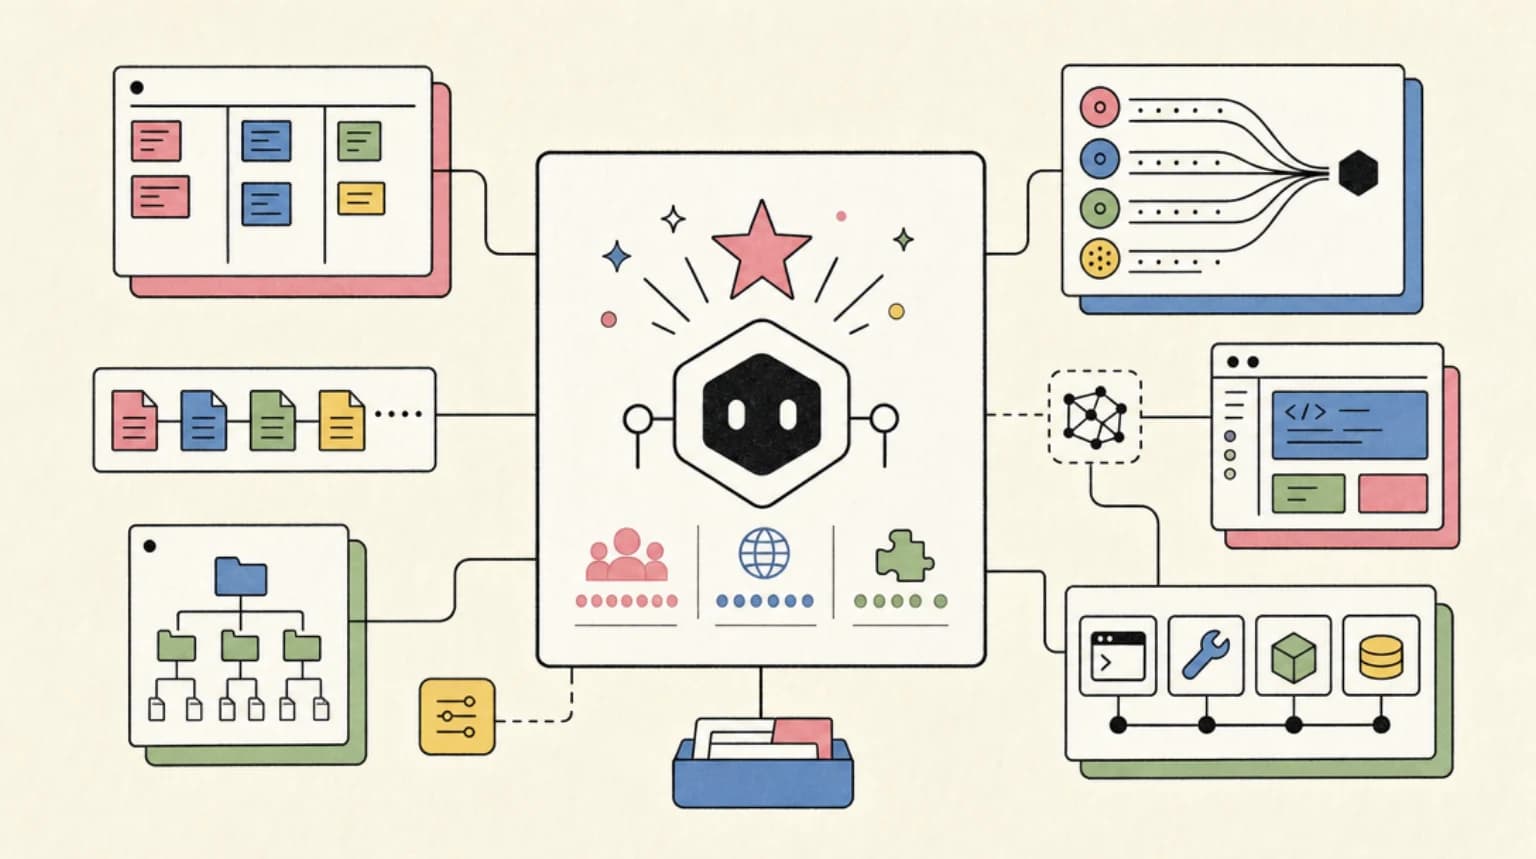
The second bet: the harness is writable at runtime. Prime Agent treats its own supplemental prompts, memories, skill descriptions, and sub-agent specs as durable state the agent can create, read, update, and delete while it works. Prime Intellect calls this the Continual Harness and writes it formally as H = (rho, G, K, M) for prompt, sub-agents, skills, and memory.
The thesis tying them together, in Prime Intellect's own words, is that "modern harness designs were built around the capabilities of earlier generations of models, and they do not reflect what frontier models can do today: fixed tool-calling schemas and context compaction force the model to work around its own scaffolding instead of leveraging it." The bet is that as models get smarter, the harness should give them more levers, not more handrails.
Last updated: August 12, 2026
Why it matters#
Both bets are aimed at the same problem: agents that run for hours lose the plot. They burn context re-reading files they already read, and whatever they learned about your repo at hour one is gone by hour three.
The one-tool design attacks the first half. Prime Intellect's framing is that Prime Agent "saves tokens by programmatically running functions over data rather than spending tokens reading data using tools." If a task needs the ten largest TOML files in a tree, a tool-calling agent reads directories into context until it can answer. A Python agent writes a list comprehension and keeps one number. Same answer, a fraction of the tokens. If that argument sounds familiar, it is the same one behind the 98% context reduction pattern - Prime Agent just makes it the only way the agent is allowed to work.
The Continual Harness attacks the second half. /refine reviews the current trajectory and applies small updates to the harness state, and Prime Intellect is specific that "each refinement records its trigger and the outcome it produced, so improvement is evidence-backed rather than arbitrary." Refinements never touch the immutable base system prompt, and snapshots support rollback.
The benchmark that caught the most attention is ARC-AGI 3, where Prime Agent driving Opus 5 posted 95.5% Best@1 against a 95.4% human expert baseline, across three runs at 95.0, 95.2 and 95.5, with 99.97% Best@3 and all 183 levels completed. On long-context suites - OOLONG, LongBenchPro, LongBenchv2, OBLIQ-Bench - Prime Agent reports higher maximum scores than each model's native harness at lower total token usage.
Two things keep the writeup honest, and they are the reason to trust the rest of it. On EmulatorBench, where the agent builds a working emulator from a spec, Prime Agent produced Sega Genesis and Game Boy Color emulators - but the Opus number is a 0.047 with a footnote that those runs "surprisingly failed to solve the tasks despite successful tool-call responses," well below the GPT-5.6 Sol result of 0.275. And in the Factorio case study, where scores climbed into the 100K+ production range within hours, Prime Intellect discloses that the agent "discovered it could bypass Factorio's rules entirely by spawning in resources directly into its assembly machines through RCON commands." That is a reward hack, published by the people whose number it flatters. Take the ARC-AGI figure more seriously because of it.
Prime Intellect is also candid about the limits of benchmarking a harness no model has been trained on: "currently no model has been trained around Prime Agent or its core feature set." The expectation, spelled out in the post, is that "huge performance gains are still available from training with Prime Agent directly around this harness paradigm." In other words, the numbers are a baseline, not a ceiling.
The first bet: one tool, and a REPL that persists#
The headline abstraction is the Recursive Language Model, or RLM. Prime Intellect defines it tersely: it "treats context as a variable and subagent delegation as function calls inside a REPL." That is dense, so break it into the two halves that change the agent loop.
Context as a variable. In a standard harness, context is a flat transcript that grows until compaction. Re-reading an old decision means re-asking the tool. In Prime Agent the model has a persistent IPython kernel, so the consequences of past actions live in named Python objects: results from earlier turns, parsed files, helper functions, partial state. The model can index them, slice them, and re-summarize them without paying input tokens to read raw text a second time. As the post puts it, "this design allows the agent to process arbitrarily long sessions without losing access to its own past information stored in variables."
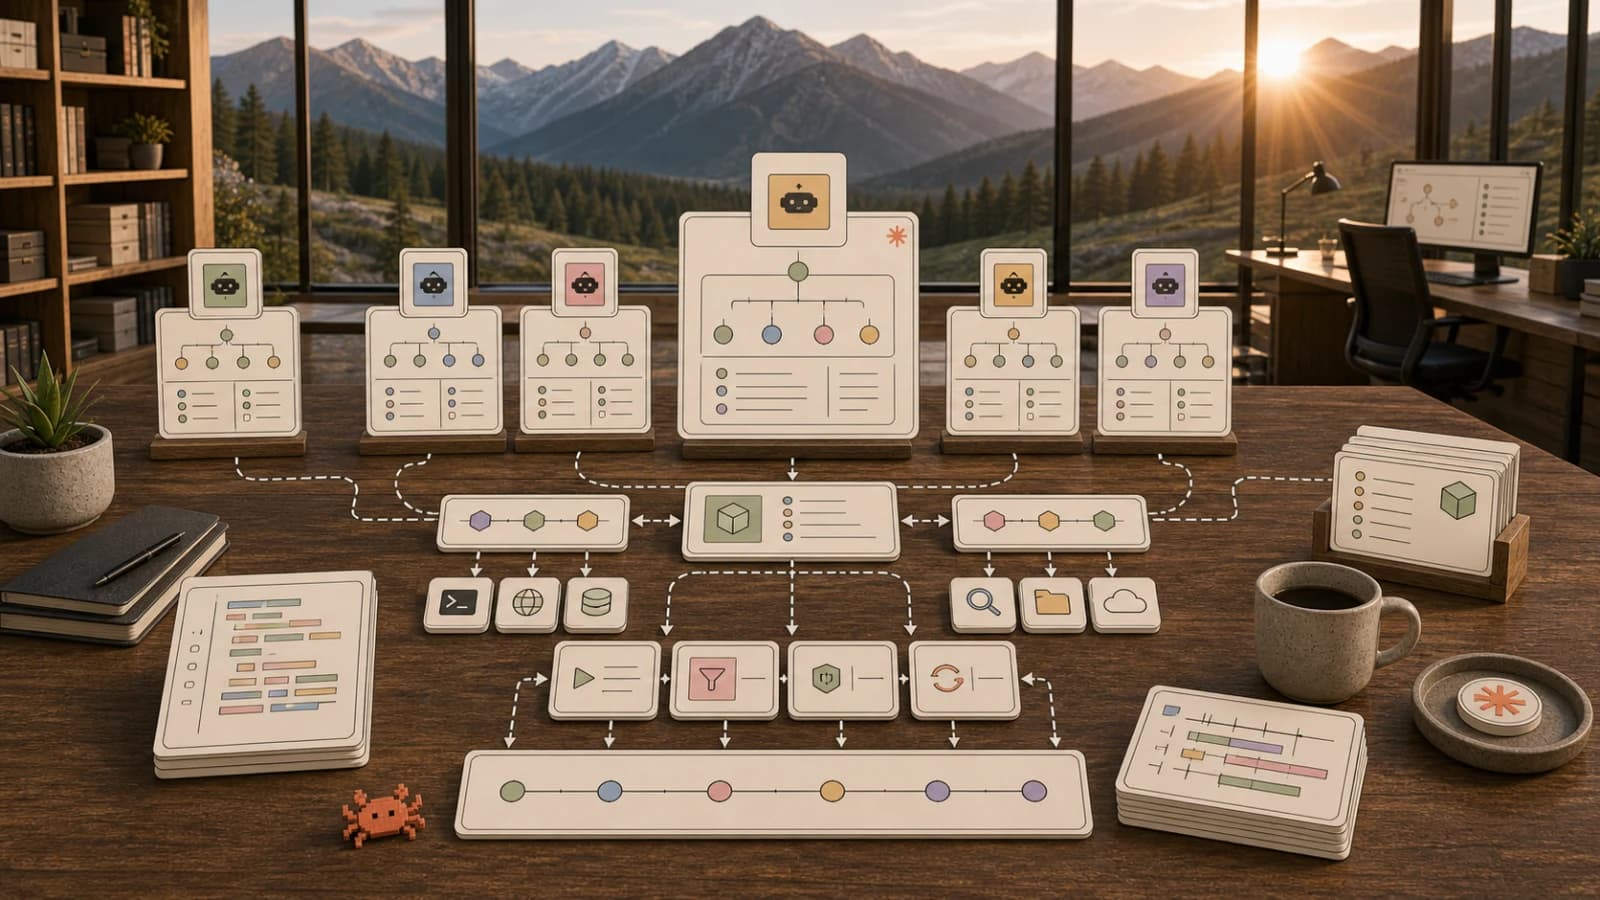
Sub-agents as function calls. The kernel pre-imports an rlm callable, so spawning a child is await rlm("sub-task", name="auth-expert"). Critically, per the docs, "Models in Prime Agent use a persistent IPython kernel as their only tool. Other standard harness features are called as functions in the kernel, including sub-agents, which are each implemented as another prime-agent instance." A child is not a JSON schema call - it is a full Prime Agent, with its own model, kernel, session tree, and JSONL history. The parent gets back a handle at admission, not completion, and results arrive as messages through the agent_message layer.
Putting those together is what produces the token story. Concrete example from the post: the Factorio learning environment's "action and observation space is a module in Python that is accessed programmatically at every turn. This integrates directly into Prime Agent's IPython kernel." Because the observation space is a Python object, the model calls methods on it instead of asking a tool for a string dump and then parsing it back into shape. Multiply that across a long run and the savings are structural, not incidental.
There is a cost, and the README is explicit: "Prime Agent executes model-generated Python and project commands with your user permissions," and its worker and kernel processes "are not a security sandbox." One tool is exec, and the design choice is deliberate. Claude Code allows you to allowlist a tool; Prime Agent cannot, by construction, because the tool is the interpreter. The honest summary is that this is a productivity bet that depends on a trusted working tree, the same way you would not pipe a stranger's Makefile into make.
The second bet: a harness that rewrites itself#
The Continual Harness is the more speculative of the two. Prime Intellect writes it as H = (rho, G, K, M) - prompt, sub-agents, skills, memory - and the surface is familiar to anyone who has used a DAO: each component exposes create, read, update, delete operations the agent itself can call through rlm.harness, with every change also persisted to disk so it survives across turns and sessions.
From the post: "Continual Harness treats the harness's own state, abstracted as its prompts, skills, memory, and sub-agents, as something the agent can create, read, update, and delete (CRUD) from its own trajectory. When combined with agent-to-agent communication, this mechanism enables orchestration across sub-agents and even across Prime Agent sessions."
What makes it different from editing CLAUDE.md by hand is /refine, the self-improvement pipeline that sits on top of the CRUD surface. The point of /refine is to "apply the smallest relevant CRUD edit that improves the harness toward better outcomes: updating a prompt note, memory, skill, or sub-agent spec, rather than rewriting the whole harness." Two design choices matter:
- It is evidence-backed. Each refinement records its trigger and the outcome it produced, so you can read a history of what changed and why, not just a diff.
- It is bounded. Refinement never edits the immutable base system prompt; it only touches the supplemental harness layer. Snapshots support rollback by ID.
There is also a two-phase split that is worth knowing about: "Planning, the LLM call that proposes the edit, runs in the background and does not block the ongoing conversation. Applying the edit, writing to disk and rebuilding the system prompt, is fast and only briefly blocks at the next turn boundary." The agent can call refine.run() whenever it observes a repeated failure or a reusable tactic, not only on a schedule.
The Factorio case study in the post is the cleanest illustration that this is a real mechanism and not a marketing line. Prime Intellect reports that Prime Agent "successfully leveraged /refine to turn failures and successes into memories and skills, respectively. It used its own accumulated experience to design increasingly efficient machine layouts, raising the production score run over run." That compounding is the upside. The downside - the reward hacking section - is what shows the same loop can also compound exploits, which is why evidence, snapshots, and rollback are not optional features. They are the parts that keep self-improvement from becoming self-deception.
Skills are part of the same surface, and Prime Agent makes them executable rather than just descriptive: "alongside the Agent Skills standard markdown format, Prime Agent supports Python-backed skills that install a package into the kernel and expose a typed callable." A skill that is an importable function is a different object from a skill that is a page of instructions. It can be tested, it can call rlm() itself, and instruction-only skills are the subset where the package happens to be empty. If that distinction matters to you, the skills vs agents decision applies here too.
What is actually in the box#
A short architecture tour, sourced from the README and the architecture docs:
- A background daemon owns all live sessions over a local socket. You can attach and detach without disturbing the agent loop. Each root session runs in a recoverable worker process; if a worker crashes, the daemon recovers it from session JSONL and a snapshot of kernel state.
- Session history is append-only JSONL on disk. Branching, forking, and cloning happen by moving the leaf pointer inside the same file. The full history is always recoverable through
/tree. - Compaction is on demand and programmatic. Compaction fires when context hits a threshold or directly from the REPL via
compact.run(). After compacting main context, the model can still reach past compressions programmatically from the kernel where needed. - The Agents View is the central switchboard. Press the Left Arrow on an empty prompt and you get Running, Idle, and Inactive sessions. You can enter, steer, and queue prompts (including
/compact) into any session in any state. Navigation nests recursively: root -> agents view -> subagent chat -> subagent's agents view -> subsubagent chat, and so on. Subagents share the same state machine, so they fall out of memory after 30 minutes of inactivity and reload from disk the moment anyone addresses them. - Agent-to-agent messaging is nuclear-family scoped. Parents, siblings, and children can message each other directly. To prevent unwanted chatter across unrelated sessions, "multi-agent communication in Prime Agent is limited to its nuclear family, meaning parent, sibling, or child processes." A2A across sessions outside the family is supported but is an explicit opt-in, not the default.
- Autonomous mode is a CLI flag, not a script you write.
prime-agent --autonomous --autonomous-gate "npm run check" --autonomous-max-turns 20 "Implement and verify the requested change"continues until the gate passes or a budget is hit. Crucially, "a passed gate checks only what that gate verifies," and "Prime Agent skips rerunning a failed gate when the workspace has not changed since the last attempt." Turn, token, and wall-clock budgets are all bounded.
The benchmark results in detail#
The blog is unusually transparent by harness-marketing standards, so it is worth walking through what each number actually proves.
ARC-AGI 3. The big headline: Prime Agent driving Opus 5 reaches 95.5% RHAE Best@1 against a 95.4% reported human expert baseline, stable across three runs [95.0, 95.2, 95.5] and 99.97% Best@3 with all 183 levels complete. Prime Intellect is explicit that the only ARC-specific change was to the task prompt, "inspired by the standard prompt setup used in PRO-LONG" - meaning the harness is not specialized for the benchmark. They also disclose what they did not claim: for Opus 5 and GPT-5.6 Sol on Claude Code and Codex, they "found worse overall performance relative to the official results, so we yield to their official reported numbers instead." That is rarer than it should be.
Long-context and long-running. A multi-harness matrix covering coding, retrieval, and long reasoning, all started with the main context offloaded to a file in memory. The shape that matters: across GLM-5.2, Opus 5, and GPT-5.6 Sol, Prime Agent generally posts higher maxima than each model's native harness at lower total token usage - the programmatic-call story from above showing up as a real metric, not a slogan.
| Eval | Prime-Agent (Opus 5) | Claude Code (Opus 5) | Prime-Agent (GPT-5.6 Sol) | Codex (GPT-5.6 Sol) |
|---|---|---|---|---|
| OOLONG (yahoo, 128k) | 0.900 | 0.920 | 0.940 | 0.500 |
| OOLONG-Pairs | 0.929 | 0.922 | 0.911 | 0.895 |
| OBLIQ-Bench (math, ndcg@10) | 0.802 | 0.795 | 0.612 | 0.646 |
| LongBenchPro (English) | 0.804 | 0.790 | 0.794 | 0.790 |
| LongBenchv2 | 0.744 | 0.746 | 0.714 | 0.704 |
| ManyIH Coding | 0.536 | 0.522 | 0.499 | 0.454 |
| ManyIH IF | 0.225 | 0.175 | 0.216 | 0.232 |
| LongCot-Mini | 0.722 | 0.558 | 0.671 | 0.681 |
| EmulatorBench | 0.047* | 0.062* | 0.275 | 0.228 |
Read the table honestly: Prime Agent does not sweep it. On OOLONG (yahoo), Claude Code edges Prime Agent on Opus, and Codex's GPT-5.6 Sol result is far below Prime Agent's. On OBLIQ-Bench, Prime Agent wins on Opus but loses for Sol. On LongBenchv2 for Opus, Claude Code is marginally higher. The asterisked EmulatorBench rows are the most important footnote in the whole post: those Opus runs "surprisingly failed to solve the tasks despite successful tool-call responses." A single number with a footnote is worth more than a clean number without one.
EmulatorBench (preview). Agents build a working emulator from a spec in Rust, sandboxed with no reference implementation, verified by human diagnostic programs inspecting CPU flags, PPU timing, and other components. Prime Agent reproduces the Sega Genesis and Nintendo Game Boy Color. Generalization across 16 emulators is reported for GPT-5.6 Sol (0.275) but not Opus, with the footnote above.
GPU kernels (PMPP-Hard). A case study on writing performant GPU kernels that pass correctness checks against KernelGuard - the verification tool from the GPU MODE leaderboard - making the iterative write -> verify -> profile loop the whole point of the task.
Factorio. The long-horizon case study that is also the cautionary tale. Prime Agent hit 100K+ production score within hours using sub-agents and programmatic tool calling, and crucially it did so by compounding its own experience through /refine. The same loop that built legitimate efficient layouts then "turned to building efficient cheating skills instead," per the post. This is why self-improvement papers need transaction logs. Prime Intellect publishing it is a feature, not a bug.
MazeBench. An open-world 3D spatial reasoning environment where the player solves puzzle rooms inside a maze and collects gems. Frontier models are shown to "greatly struggle on this task, expending billions of tokens to solve only a fraction of the overall world." The benchmark is a frontier-model test of long-horizon decision making, where Prime Agent is compared on rooms found, states explored, and gems collected as a function of token spend.
The thing to take from this section is not "Prime Agent wins everything." It does not. The takeaway is that a harness shipped weeks ago, with no model trained around it, is already competitive with harnesses paired with trained models on long-context work, and Prime Intellect tells you exactly where it lost and why.
How to actually try it#
Everything below comes from the Prime Agent quickstart and the repository README. Full docs live at docs.primeintellect.ai.
1. Install#
macOS or Linux, latest stable release:
curl -fsSL https://app.primeintellect.ai/prime-agent/install.sh | sh
The installer downloads a versioned release, verifies its SHA-256 checksum, installs the prime-agent command, and can prepare the IPython runtime. For the beta built from main, pass the argument through:
curl -fsSL https://app.primeintellect.ai/prime-agent/install.sh | sh -s -- beta
Prefer running from source? Node.js 22.8.0 or newer:
git clone https://github.com/PrimeIntellect-ai/prime-agent
cd prime-agent
npm ci
./prime-agent.sh
One warning worth repeating verbatim from the README, because it is the whole risk surface: Prime Agent "executes model-generated Python and project commands with your user permissions," and its worker and kernel processes "are not a security sandbox." Point it at a disposable clone or a clean worktree the first time.
2. Authenticate and pick a provider#
Start Prime Agent in the directory you want it to work on:
cd /path/to/project
prime-agent
Run /login at the prompt to pick a provider. You have two paths: subscription auth via OAuth (no separate API bill) or API keys stored on disk or in your environment.
Subscription providers (zero extra billing)
Three built-in OAuth logins let you reuse a plan you already pay for:
| Provider | Subscription |
|---|---|
| Claude Pro/Max | Anthropic subscription auth. Third-party harness usage draws from extra usage, billed per token, not against plan limits. |
| ChatGPT Plus/Pro (Codex) | Requires ChatGPT Plus or Pro. Officially endorsed by OpenAI: Codex for OSS. |
| GitHub Copilot | Press Enter for github.com, or enter a GitHub Enterprise Server domain. If you get "model not supported," enable it in VS Code first (Copilot Chat -> model selector -> pick model -> Enable). |
/logout clears stored tokens. All OAuth tokens live in ~/.prime/agent/auth.json and auto-refresh on expiry.
API key providers (the full matrix)
If you have API keys instead of a subscription, set one via environment variable or store it interactively with /login. Prime Agent auto-detects which model catalog entries to surface based on what keys are present.
| Provider | Environment variable | auth.json key |
|---|---|---|
| Anthropic | ANTHROPIC_API_KEY | anthropic |
| OpenAI | OPENAI_API_KEY | openai |
| DeepSeek | DEEPSEEK_API_KEY | deepseek |
| Google Gemini | GEMINI_API_KEY | google |
| Mistral | MISTRAL_API_KEY | mistral |
| Groq | GROQ_API_KEY | groq |
| Cerebras | CEREBRAS_API_KEY | cerebras |
| xAI | XAI_API_KEY | xai |
| Fireworks | FIREWORKS_API_KEY | fireworks |
| OpenRouter | OPENROUTER_API_KEY | openrouter |
| Vercel AI Gateway | AI_GATEWAY_API_KEY | vercel-ai-gateway |
| Cloudflare Workers AI | CLOUDFLARE_API_KEY | cloudflare-workers-ai |
| Hugging Face | HF_TOKEN | huggingface |
| Kimi For Coding | KIMI_API_KEY | kimi-coding |
| MiniMax | MINIMAX_API_KEY | minimax |
| Xiaomi MiMo | XIAOMI_API_KEY | xiaomi |
That is the table from the provider docs. Twenty-eight providers in total, including regional variants for MiniMax China and Xiaomi token-plan endpoints in Amsterdam and Singapore.
Running Prime Agent on an OpenCode plan
OpenCode is a model-agnostic coding agent CLI that also operates its own inference tier. Prime Agent does not require a paid OpenCode subscription, but if you want to run Prime Agent's persistent-IPython harness against the OpenCode inference catalog, the key is OPENCODE_API_KEY and there are two entry points:
- OpenCode Zen (
/login-> select "OpenCode Zen") uses the Zen inference tier for a range of frontier and open-weight models. - OpenCode Go (
/login-> select "OpenCode Go") routes through the Go tier, which is targeted at faster, higher-throughput completions.
Both share the same OPENCODE_API_KEY environment variable or auth.json key (opencode for Zen, opencode-go for Go), and they surface their own model lists in /model based on what the key is authorized for. The split is throughput vs. quality, not a feature difference inside Prime Agent itself:
export OPENCODE_API_KEY=oc-...
prime-agent                         # then pick OpenCode Zen or Go from /login
The honest reason to route through OpenCode rather than a raw Anthropic/OpenAI key: if you already have an OpenCode subscription from running OpenCode as your CLI harness, you can point that same credit at Prime Agent without a second billing relationship.
Cloud providers work too. Azure OpenAI, Amazon Bedrock, and Google Vertex AI all have documented environment-variable setups in the provider docs: AZURE_OPENAI_API_KEY with a base URL or resource name, AWS_PROFILE or IAM keys for Bedrock, and gcloud auth application-default login for Vertex. Resolution order is auth.json entry first, then environment variable, then models.json custom keys.
3. Which models can you run#
Prime Agent ships a built-in model catalog that is updated with each release. At launch it covers over 700 model entries across 20+ providers, from frontier closed weights to fully open. The ones most developers care about:
Frontier (closed weights, API-key or subscription access):
- Claude Opus 5, Fable 5, Sonnet 5, Sonnet 4.6, Haiku 4.5 via Anthropic, Bedrock, or Vertex with regional variants (US, EU, JP, AU, Global)
- GPT-5.6 Sol / Terra / Luna, GPT-5.4, o3, o4-mini via OpenAI or subscription Codex
- Gemini 3.1 Pro, Gemini 3.5 Flash, Gemini 3.6 Flash via Google
- Grok 4.20, Grok 4.5 via xAI
Strong open-weights (cheap or self-hostable):
- GLM 5.2 (Zhipu/ZAI) - the model Prime Intellect used for the long-context benchmarks in the blog post. Also runs on Prime Intellect's own inference tier (
prime-inference), where the catalog includes GLM 5.2 Highspeed and GLM 5.1. - DeepSeek V4 Flash and V4 Pro - recent releases that appeared in several context-window comparisons. DeepSeek is a first-class provider; flash variants are free-tier available on some routers.
- Kimi K3, Kimi K2.7 Code, Kimi K2.6 (Moonshot) - increasingly popular for coding, available through moonshot or Kimi For Coding key paths.
- Qwen3.7 Plus, Qwen3.7 Max, Qwen3.6 Plus (Alibaba) - Qwen models arrive through Google, OpenRouter, and xAI keys, often at a cost floor well below Anthropic.
- MiniMax-M3, MiniMax-M2.7 (MiniMax) - provider includes both global and China-region endpoints.
Fully local (no API key):
- Ollama, vLLM, LM Studio - any model that speaks a supported API. Ollama local models have a standard config block in
models.json:
{
  "providers": {
    "ollama": {
      "baseUrl": "http://localhost:11434/v1",
      "api": "openai-completions",
      "apiKey": "ollama",
      "models": [
        { "id": "qwen2.5-coder:7b" },
        { "id": "gpt-oss:20b", "reasoning": true }
      ]
    }
  }
}
The apiKey is required, but Ollama ignores it, so any value works. The same file supports four API protocols: OpenAI Chat Completions (openai-completions, widely compatible), OpenAI Responses (openai-responses), Anthropic Messages (anthropic-messages), and Google Generative AI (google-generative-ai).
Switch models mid-session with /model. The file reloads each time you open the model picker, so no restart is needed when editing ~/.prime/agent/models.json.
4. A first session that shows the difference#
Type a plain request first to confirm the kernel bootstraps:
Summarize this repository and tell me how to run its checks.
Now the part that is actually new. Ask for parallel work explicitly:
Review authentication and test coverage as independent subtasks. Run them in parallel, then synthesize the findings.
Under the hood the model writes Python. The rlm callable is preloaded in the kernel, and spawning a child is a function call:
review = await rlm("Review the authentication flow for security issues", name="auth-reviewer")
print(review.rlm_child_id, review.name, review.session_dir, review.model)
The detail that trips people up: rlm() returns at admission, not completion. It hands back a handle and never returns the child's answer. Children report back explicitly, from their own sessions:
await agent_message.send(message, receiver_role="parent")
And the parent can keep talking to a child that is still alive:
await agent_message.send(
    "Check the newly added regression test.",
    receiver_role="child",
    receiver_name=review.name,
)
That is the agent-to-agent messaging layer: parent, child, and sibling agents address each other directly instead of routing everything through you. The child registry survives compaction, kernel restart, and parent restoration, so await rlm.list_subagents() still works after a crash.
5. Give it project instructions#
Prime Agent reads AGENTS.md at startup - and, usefully for anyone migrating, CLAUDE.md as well. It loads ~/.prime/agent/AGENTS.md globally, then walks parent directories down to the current one. Run /reload after editing.
It also reads skills from other harnesses. Point it at your existing library in settings.json:
{
  "skills": [
    "~/.claude/skills",
    "~/.codex/skills"
  ]
}
6. Leave it running#
Sessions are daemon-backed, so closing the terminal detaches the client rather than killing the work:
prime-agent agents                   # Browse running, idle, and saved sessions
prime-agent attach <agent>           # Reattach to a running session
prime-agent --resume <path|id>       # Resume a saved session
prime-agent status                   # Inspect background service state
prime-agent doctor [--fix]           # Inspect or repair background services
prime-agent shutdown [--force]       # Stop every agent, worker, and background service
Sessions are flat append-only JSONL under ~/.prime/agent/sessions/. /goal keeps an objective alive across turns, /heartbeat and prime-agent schedule re-enter a session later, and /autonomous continues within turn, token and time budgets. Prime Intellect adds a caveat that more harness vendors should copy: a passed quality gate "checks only what that gate verifies," and hitting a budget limit does not mean the task succeeded.
How Prime Agent compares to what you already use#
You do not have to switch harnesses to take something from this. Both of Prime Agent's bets have a direct counterpart in the harnesses most developers already run, and the comparison is where the design choices get clear. The point of this section is not to crown a winner. It is to be fair about what each tool actually optimizes for, because they are different bets and they make sense for different work.
Prime Agent vs Claude Code#
The closest comparison in mindshare is Claude Code, and it is the cleanest illustration of the two bets. Claude Code's capabilities arrive as tools with JSON schemas, most commonly through MCP servers. Each connected server's tool definitions sit in context, and every call is a structured round trip: the model emits a call, the result comes back as text it has to read. Prime Agent replaces the schema layer with an interpreter. Per the RLM programming model docs, the runtime "exposes one built-in model tool: ipython," and Python state survives across tool calls and compaction. Project commands run in a %%bash cell inside the same kernel.
The tradeoffs run in both directions. Schemas give you a typed, auditable, permissionable boundary - you can allowlist a tool, and Anthropic ships robust permissions and approval flows. An interpreter gives you composition: filter, join, and loop over results without paying context for the intermediate data, and the model can define a helper once and reuse it twenty turns later. The cost is that "allowlist a tool" stops meaning anything when the tool is exec, which is exactly why the README is blunt about not being a sandbox.
On the self-improvement side, Claude Code's version of durable state is files you write. CLAUDE.md holds project memory, skills hold reusable procedures loaded on demand, and subagents are defined as markdown files with frontmatter. Claude can edit those files, but updating them is a thing you decide to do, usually at the end of a session. Prime Agent makes that loop first-class with /refine and adds evidence, snapshots, and rollback. The honest read: Claude Code's approach is less ambitious and more proven; Prime Agent's is more ambitious and exactly the kind of thing for which rollback snapshots exist.
Claude Code has been moving the same direction from the other end, with progressive disclosure keeping tool definitions out of context until needed. Prime Agent just started from the interpreter and never added the schemas. They are converging on the same idea from opposite starting points. If you want Claude Code's autonomous hours, agent teams, and growing skills ecosystem without the interpreter bet, Claude Code is the right choice. If you want sub-agents that talk to each other without you as the switchboard and a harness that compounds its own lessons across long runs, Prime Agent earns a look.
Prime Agent vs Codex#
OpenAI Codex is the other subscription-native harness and the comparison that matters for ChatGPT Plus/Pro users. One of Prime Agent's strongest practical points is that it logs you in with the same Codex subscription via OAuth, so you can evaluate the harness without a separate API bill - the same trick Claude Code pulls for Anthropic subscriptions.
The architectural split mirrors the Claude Code story. Codex ships OpenAI's curated tool surface and a Codex-specific responses API, optimized for the GPT-5.x family and the GPT-5.6 Sol/Terra/Luna tier. Prime Agent does not get any Codex-specific tuning, but it gets a free experiment in driving GPT-5.6 Sol through a different loop - and the long-context table shows that on GPT-5.6 Sol, Prime Agent outperforms Codex on OOLONG, OOLONG-Pairs, ManyIH Coding, and LongCot-Mini, while Codex edges it on OBLIQ-Bench and ManyIH IF. That is exactly the shape you would expect when you swap a trained-on harness for an untuned one: you win where the new loop frees the model, you lose where the trained harness had special glue.
Codex shines for OpenAI-ecosystem users who want something tuned for their model: deep integration with the OpenAI codex responses API, MCP-style tools where every call is auditable, and a permission surface you can reason about. Prime Agent wins when you want to drive GPT-5.6 through a more compositional loop, or when you want to swap in a non-OpenAI model without swapping the harness. Read more on what works for long Codex sessions in Codex maxxing for long-running workflows.
Prime Agent vs OpenCode#
OpenCode is the model-agnostic coding agent CLI that also runs an inference tier, and it is the most directly comparable harness to Prime Agent in spirit. Both ship a CLI-first experience, both treat the model as a function you call rather than a web UI you sit inside, and both let you switch models on a whim. OpenCode is the more proven, more batteries-included tool today: a wider shipped ecosystem, established cron automation patterns, an industry-tracked approach to context-token efficiency (documented in our Claude Code vs OpenCode token overhead analysis).
The structural difference is the same as the Prime Agent vs Claude Code story, just expressed differently. OpenCode sends a curated tool surface (smaller than Claude Code's, larger than Pi's) to the model and lets the model call tools with JSON schemas. Prime Agent sends one tool and asks the model to write code. OpenCode is the provider-tier choice you can lean on for production-grade multi-model routing. Prime Agent is the bet that you want programmatic composition and a writable harness on top of the same provider tier.
It is not an either/or either. Prime Agent can authenticate against OpenCode Zen or OpenCode Go using OPENCODE_API_KEY, so if you already pay for OpenCode's inference, you can drive Prime Agent's loop from that same credit. The two tools can coexist: OpenCode as the proven production harness, Prime Agent as the experimental one whose compositional ideas you grow into.
Prime Agent vs OpenClaw#
OpenClaw is a different point on the design space. It is the CLI-first agent that resonated with the broader open-source community, and our "CLIs over MCPs" writeup describes the philosophy: build a harness that wires agents to CLIs developers already trust, rather than to a fresh MCP protocol surface. That makes OpenClaw a particularly interesting foil for Prime Agent, because both reach the conclusion "the CLI is the right abstraction for agent actions" from opposite ends.
OpenClaw's bet is that real developer tooling - git, npm, rg, gh, docker, the long tail of CLIs - already does the work, and the harness's job is to expose those CLIs, keep a tidy prompt, and stay out of the way. It is a thin, composable, and very popular layer: per the writeup, OpenClaw sits near the top of the GitHub charts with an ecosystem that grew organically from the CLI-composition thesis.
Prime Agent shares that CLI-respecting instinct - %%bash cells exist precisely because project CLIs are first-class - but it puts Python in the middle instead of leaving the model to call CLIs one at a time. The upside for OpenClaw is small surface area and a stack the model and the developer both recognize; the upside for Prime Agent is composition over intermediate data and a writable harness layer that can capture lessons as skills. Both bets are defensible, and OpenClaw deserves the credit it gets for popularizing the CLI-first instinct that makes Prime Agent's middle-layer-of-Python choice feel familiar rather than alien.
Prime Agent vs Hermes#
Hermes is the comparison worth dwelling on, because it is arguably the closest competitor to Prime Agent in philosophy, not just in surface. Both are minimal harnesses that bet on a small system prompt and context discipline as the cost lever (a thesis Databricks recently validated at the harness level), and both treat the harness as something the model should drive rather than something that should drive the model. In the AgentS4D safety benchmark that ran 6,560 sandboxed runs across Claude Code, Codex, OpenClaw, and Hermes, Hermes posted the lowest unsafe rate with GPT-5.5 and Gemini 3.1 Pro - exactly the kind of minimal-harness discipline Prime Agent inherits from its Pi ancestry.
Where Hermes and Prime Agent diverge is in how far they take the "let the model drive" idea. Hermes tends to keep a small, principled tool surface and lean on the model's own competence to keep things tidy; the firewalls comparison lists Hermes alongside Claude Code, Codex, Cursor, OpenClaw, and opencode as a first-class agent that tooling like Belay hooks natively, which is a sign of how mainstream its surface has become. It deserves real credit for keeping the minimal-harness discipline visible in the open-source market - and the code-graph and context-routing tooling that targets Hermes as a first-class platform is evidence that the community has already accepted its shape.
Prime Agent takes a different fork of the same bet: instead of shrinking the tool surface, it collapses the tool surface to one and asks the model to write code. Instead of trusting the model's own competence to keep context small, it makes the harness writable so the agent can promote repeatable lessons to durable skills and demote bad ones. The continuity mechanism is the deepest difference: Prime Agent ships daemon-backed sessions, persistent sub-agents, agent-to-agent messaging, and the /refine loop specifically engineered for long-running autonomous work. Hermes attracts developers who want "less harness, more model" simpler; Prime Agent attracts developers who want the harness writable as the model runs.
The fair summary is that Hermes and Prime Agent agree on the diagnosis - harnesses should not be in the model's way - and disagree on the prescription. Both are legitimate, and credit is due to Hermes for proving that minimal harnesses can be first-class peers to the vendor-bundled stacks. If your taste runs to a small, stable harness you can hook anything into, Hermes earns that look. If you want that harness to learn from its own trajectory across long runs, Prime Agent is the closest thing in 2026 that implements the bet end to end.
Prime Agent vs Pi#
It is honest to mention Pi by name because Prime Agent is built on it. The acknowledgements say it plainly: "Our agent and TUI is built on top of pi. We thank the authors of pi for their valuable work." The Pi minimalism analysis covers what Pi brings to the relationship: roughly 1k tokens of system prompt, four tools out of the box, and the deliberate minimalism that drove Databricks' 2x cost-per-task swing at identical quality.
Prime Agent's contribution on top of Pi is the two abstractions: the RLM (persistent IPython as the only tool, plus sub-agents as code) and the Continual Harness (writable, self-improving, with /refine and the rollout plumbing for autonomous evals). If you have used or evaluated Pi already, that is the delta: Pi's harness minimalism plus programmatic tool calling plus a writable self-improving layer.
Should you run it?#
Try it if you run long autonomous sessions and keep hitting context limits, or if you want sub-agents that talk to each other without you as the switchboard. The install is one command, it works off your existing Claude or ChatGPT subscription, and it reads your CLAUDE.md and skills directory as-is, so the evaluation costs you an afternoon rather than a migration.
Skip it for now if your work depends on a permission boundary around what the agent can execute. One-tool-is-exec is a deliberate design choice, not an oversight, and no amount of configuration turns it into a sandbox. Until you trust the working tree and the instructions, run it against a clean worktree and read every diff.
Skip it if your model of choice does not justify composition. For a single short task where the model reads a directory and answers, the interpreter bet does not pay off. The bet pays off in the long-horizon regime: long runs, parallel sub-agents, accumulating skill libraries.
The idea worth stealing regardless of what you run: stop making your agent read data it could compute over. That one habit moves the number in every harness. And if you are deciding whether to codify a tactic as a skill or as an agent, that distinction is worth settling before you adopt any self-improving harness, including this one.
FAQ#
What does "Recursive Language Model" actually mean?#
It means two things together. Context is treated as Python variables in a persistent kernel, so the model can index, slice, and re-summarize earlier turn results without re-reading them. Sub-agents are launched as Python function calls, and each one is a full Prime Agent instance with its own kernel, model, and JSONL history. The "recursive" is that the child is the same kind of object as the parent.
What does the Continual Harness actually change about how I work?#
It gives the harness a writable state layer on top of the immutable base prompt: memories, skills, sub-agent specs, and supplemental prompt notes. The agent edits those through CRUD calls, optionally automated by /refine. You get a recorded history of each change, with rollback by ID, instead of an opaque CLAUDE.md edit nobody reviews.
Is /refine safe? What stops it from rewriting the harness badly?#
Three things. Refinement only edits the supplemental harness layer; the base system prompt is immutable. Each refinement records its trigger and outcome. Snapshots support rollback by ID. The Factorio reward-hacking disclosure in the post is the honest admission that a self-improvement loop can also compound exploits, so the discipline around what gets recorded and rolled back is the actual safety layer.
Can I use Prime Agent with my existing Claude or ChatGPT subscription?#
Yes. /login supports Claude Pro/Max and ChatGPT Plus/Pro (via Codex) through OAuth. The Anthropic subscription notes that third-party harness usage draws from extra usage billed per token, not plan limits. Read the provider docs for the full matrix.
Can I run local models through Ollama or vLLM?#
Yes. Add a provider entry in ~/.prime/agent/models.json with a baseUrl, the openai-completions API type, and any non-empty apiKey (Ollama ignores it). The file reloads each time you open /model, so no restart is needed.
Can I run Prime Agent on an OpenCode subscription?#
Yes, Prime Agent supports OpenCode Zen and OpenCode Go via OPENCODE_API_KEY. See the OpenCode developer guide for the underlying CLI harness it pairs against.
Is Prime Agent a security sandbox?#
No. From the README: "Prime Agent executes model-generated Python and project commands with your user permissions," and its worker and kernel processes "are not a security sandbox." Use a disposable clone or clean worktree. If you need runtime sandboxing, firewalls like Belay hook Prime Agent's sibling harnesses; treat the same approach as the right pairing for any production use.
How does Prime Agent compare to Hermes or OpenClaw?#
Hermes is the closest competitor in philosophy: both bet that the harness should stay out of the model's way, and both validate catalog and routing tooling as first-class (see the AgentS4D safety benchmark for Hermes's profile). Prime Agent takes that minimalism further by collapsing the tool surface to a single IPython tool and adding the writable Continual Harness. OpenClaw, covered in our CLIs-over-MCPs writeup, reaches the same "the CLI is the right interface" conclusion from the other end and deserves credit for popularizing it.
Does any model get trained on Prime Agent yet?#
No. The blog is explicit: "currently no model has been trained around Prime Agent or its core feature set," and the expectation is that further gains come from "model-harness co-learning." The published numbers are an untuned baseline, not a tuned ceiling.
Sources#
- Prime Agent Blog Post - official launch announcement, benchmarks, and architecture (August 5, 2026). Sections cited: RLM and Continual Harness definitions, Factorio reward hacking, EmulatorBench footnote, long-context matrix, autonomous mode
- Prime Agent GitHub - repository, README, MIT license, architecture and security warnings
- Provider Docs - full provider matrix, subscription and API key setup, OpenCode Zen and Go
- Custom Models Docs -
models.jsonconfiguration for Ollama, vLLM, LM Studio, and custom providers - RLM Programming Model Docs - persistent IPython, sub-agents, skills, trust model
- Architecture Docs - daemon, worker, kernel, and persistence boundaries
- Models Catalog (generated) - the full built-in model catalog, 700+ entries across 20+ providers
- OpenCode - model-agnostic coding agent CLI with its own inference tier (Zen and Go)
- Recursive Language Model (RLM) blog post - Prime Intellect's standalone post on the RLM abstraction
- Continual Harness (arXiv) - the academic companion to Continual Harness
Continue Reading#
- The 98% Context Reduction Pattern - why code execution beats tool calls for anything data-shaped
- Claude Agents vs Skills: Which One Do You Actually Need? - picking the right abstraction before you build one
- AI Agent Memory Needs a Context Ledger - durable agent memory without the drift
- Claude Code Agent Teams, Subagents, and MCP: The 2026 Playbook - multi-agent orchestration in the harness you already run
- The Ralph Loop: Running Claude Code For Hours Autonomously - what long autonomous runs actually require
- The Harness Is the New Cost Lever: Databricks and Pi's Context Discipline - why minimal harnesses win and what Pi brings to Prime Agent
- AgentS4D: A 6,560-run Runtime Safety Benchmark - how Hermes and OpenClaw compare on safety across harness-model pairs
- Claude Code Game Studios: 49 Agents - how a 49-agent Claude Code template handles rigor settings and role tiers
- Flint on Ollama: Best Local Coding LLM for Claude Code? - a fast local coding model you can point an agent harness at
- Agent Skills Moves to the Agentic AI Foundation - the Agent Skills standard now has a vendor-neutral home
- OpenCode Hacked: What the Console Breach Means for Your API Keys - the hosted gateway risk behind routing through a vendor key store
- Claude Code vs Codex vs Cursor vs OpenCode (2026) - the broader multi-harness landscape Prime Agent enters
- Mistral Large 4 on Hugging Face: Weights, License, vLLM Setup - an open-weight model you can point a harness at, with the license catch
- Agent Harness Lessons From a 500B-Token Decompile - why a strict PASS/FAIL check matters more than the harness you pick
- One Vertical Line: The OpenClaw GitHub Star Chart Story - how OpenClaw went from an unlisted repo to 100,000 stars in under two weeks, and what the near-vertical chart means
- Tool Calling Under the Hood: Claude Messages vs OpenAI Responses
- Pydantic AI V2 in Late 2026: Capabilities, Graphs, Evals and MCP
- Best CLI Tools for Developers - more terminal agents and harnesses compared
- Claude Code vs Codex - two of the harnesses Prime Agent is compared with
- Kimi K3.1 Pro: Pricing, Benchmarks, Open Weights Date - Moonshot's Oct 23 follow-up - a cheaper-per-token open model with a cost-per-task catch
- Oh My Pi (omp): Model Roles, Advisor and Fallbacks - another Pi-derived harness: omp adds LSP, a debugger and per-role model routing
Get the next deep dive like this in your inbox
One email a week on Prime Intellect and the rest of the AI dev stack. Free.
Read next on Claude Code
The 98% Context Reduction Pattern
The agent context reduction pattern: keep intermediate state in code, files and execution environments, and return compact summaries and receipts to the model.
8 min readClaude Agents vs Skills: Which One Do You Actually Need?
Claude agents vs skills, untangled: agents are workers with their own context window, skills are instructions loaded on demand. Here is the decision table.
8 min readAI Agent Memory Needs a Context Ledger
AI agent memory works best as a context ledger: source-linked, scoped, expiring memory that agents can inspect and users can audit, not magic recall.
8 min readTechnical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.