8 min read
OpenAI's Misalignment Reports Are an Agent Operations Signal
OpenAI's model-misalignment reporting framework doubles as an agent operations template: incident intake, severity labels, and evidence-led disclosure.
10 articles
Anthropic's Frontier Red Team says small open models may be months from self-replicating across cheap IoT devices. What it measured and where the claim is thin.
OpenAI's model-misalignment reporting framework doubles as an agent operations template: incident intake, severity labels, and evidence-led disclosure.
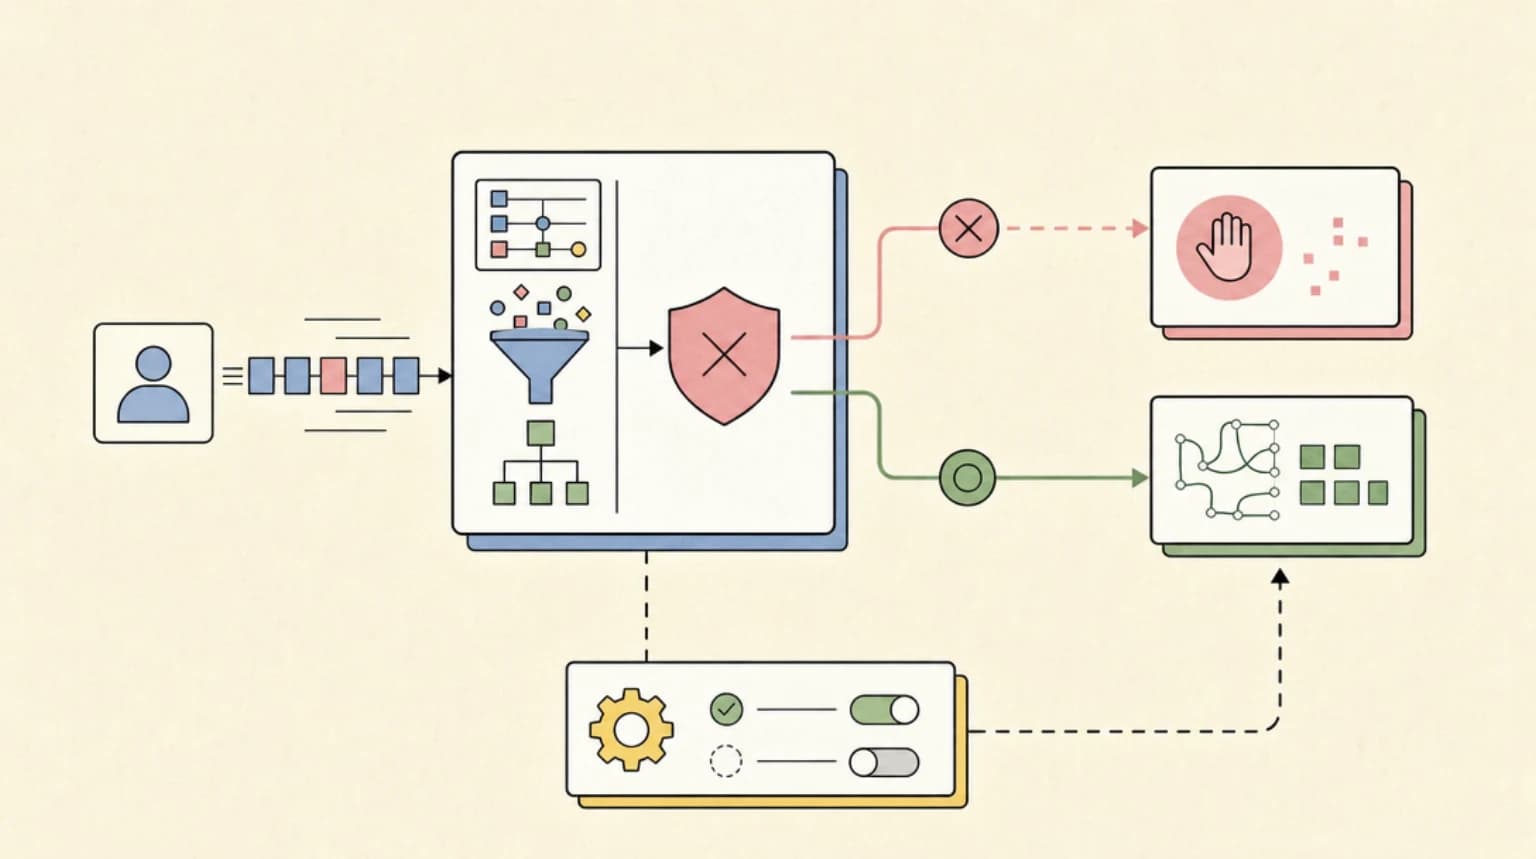
Anthropic retuned Claude Fable 5 biology safeguards, cutting biology fallbacks about 85%. What changed and what still routes to Opus 5.
Mistral Shieldstral is a 3B Apache 2.0 multimodal moderation model that takes your policy as a plain-language question at inference and runs on one 16GB GPU.
Demis Hassabis proposes a FINRA-style Frontier AI Standards Body to test models before release. What the plan says, why now, and where it runs into trouble.
AI 2040 Plan A is the AI Futures Project scenario for a US-China accord that delays superintelligence to 2040. What it proposes and what HN thinks.
Dario Amodei's call for FAA-style AI regulation, with mandatory third-party testing and power to block deployments, and the open questions for developers.
Why Claude Fable 5 refuses cybersecurity, bio and distillation queries, how it falls back to Opus 4.8, and what API developers must configure first.
Claude Fable 5 silently degrades answers on some ML development tasks with no refusal or notice. See which work is restricted and what developers should do.
A trending refusal-direction paper is a reminder that model safety cannot be treated as a thin refusal layer. Builders need layered controls around the model.
Showing 9 of 9 articles

New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
Explore 844 topics
Browse All Topics