12 min read
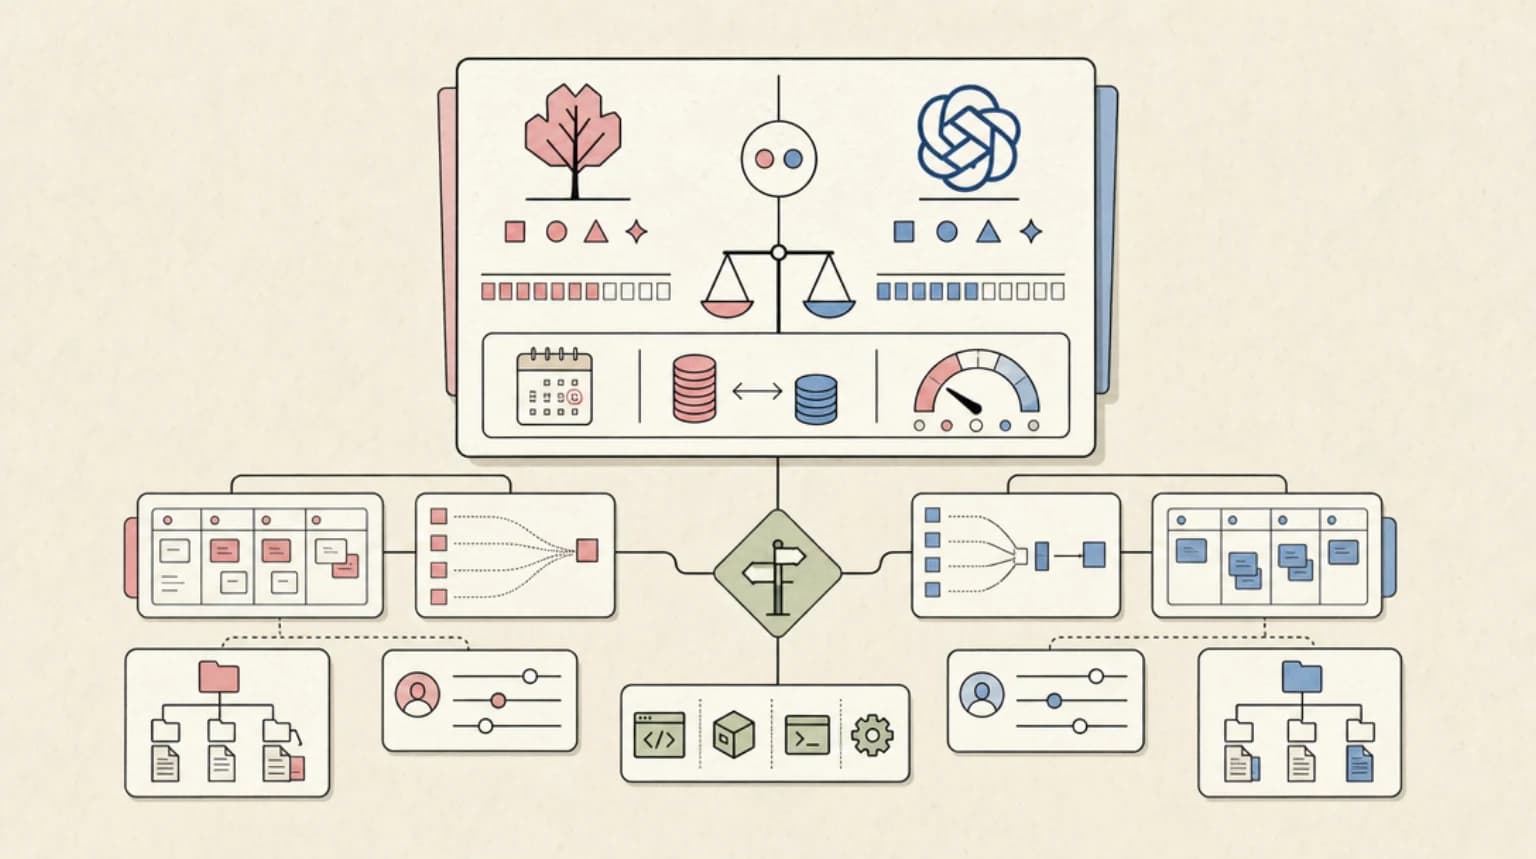
Claude Fable 5 vs GPT-5.6 Sol: Benchmarks, Pricing, and When Each Wins
Fable 5 is API-only at 2x GPT-5.6 Sol's price with a 15-point SWE-Bench Pro gap. Here is the decision framework for choosing between them in August 2026.
32 articles - page 3 of 3
Fable 5 is API-only at 2x GPT-5.6 Sol's price with a 15-point SWE-Bench Pro gap. Here is the decision framework for choosing between them in August 2026.
FrontierCode grades AI coding agents on whether maintainers would merge their PRs, not on passing tests. Why SWE-Bench misleads and how to adjust review.
GPT-5.5 and 5.5 Pro for developers: pricing, which tier fits which workload, agentic gains from real evals, a regression to watch, and a migration playbook.
Web Dev Arena compares AI coding models on real frontend work: same prompt, different models, live output, plus frontend evals worth running beyond benchmarks.
Claude Sonnet 4.6 nears Opus on agentic work and computer use at half the cost. Benchmarks, adaptive thinking, model card findings and the 1M context beta.

xAI has launched Grok 4, claiming the title of the world's most powerful AI model. With a $300/month Super Grok tier, saturated AMI benchmarks, and a coding model on the horizon, this is xAI's bigge...
xAI's Grok 3 launch explained: the 200,000-GPU cluster, benchmarks against GPT-4o and Sonnet 3.5, the reasoning modes, and what it all means for developers.
Showing 25-31 of 31 articles

New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
Explore 840 topics
Browse All Topics