Topic
LOCAL AI
Running AI models locally - Ollama, open-source models, and on-device inference.
26 resources - 18 posts, 8 tools
Blog Posts
View in blog →
Muse Spark Open Weights: 816B Model, Benchmarks, and How to Run It
Meta released Muse Spark Open weights on October 15, 2026: 816B total, 42B active, 1M context. Run recipes, hardware floor, license catch, and where it trails.
8 min read
EmbeddingGemma 2 Guide: Local Multimodal Embeddings for Code
EmbeddingGemma 2 is a 740M open model that embeds code, images, video and audio in one space. Specs, Matryoshka storage math, and where it breaks.
11 min read
Hermes Agent Guide (2026): What It Is, Local Setup With Ollama, Skills, and Hermes vs OpenClaw
Hermes Agent is Nous Research's open-source, self-improving AI agent. Run it locally with Ollama, see how its skills system works, and compare it with OpenClaw.
10 min read
GitHub Copilot for JetBrains Gains Persistent Memory and Ollama BYOK
GitHub Copilot for JetBrains adds memory across chat sessions, Ollama as a BYOK provider, and enterprise settings for MCP access. What each feature does.
7 min read
Cactus Needle 2: The 14MB Agentic LLM That Runs on a Raspberry Pi 5
Cactus open-sourced Needle 2, a 45M-parameter agentic LLM in a single 14MB binary that runs a full tool-calling session in 28MB of RAM. 500 tok/s on a Raspberry Pi 5, ESP32-S3 class parts, Apache 2.0. Here is what the benchmarks actually show.
7 min read
Muse Glimmer 30B: Meta's Open-Weight Local Agent Model, Benchmarks, and Hardware Reality
Muse Glimmer 30B is Meta's Apache 2.0 open-weight multimodal agent model that runs in 24GB. Benchmarks, hardware reality and what the numbers actually say.
8 min read
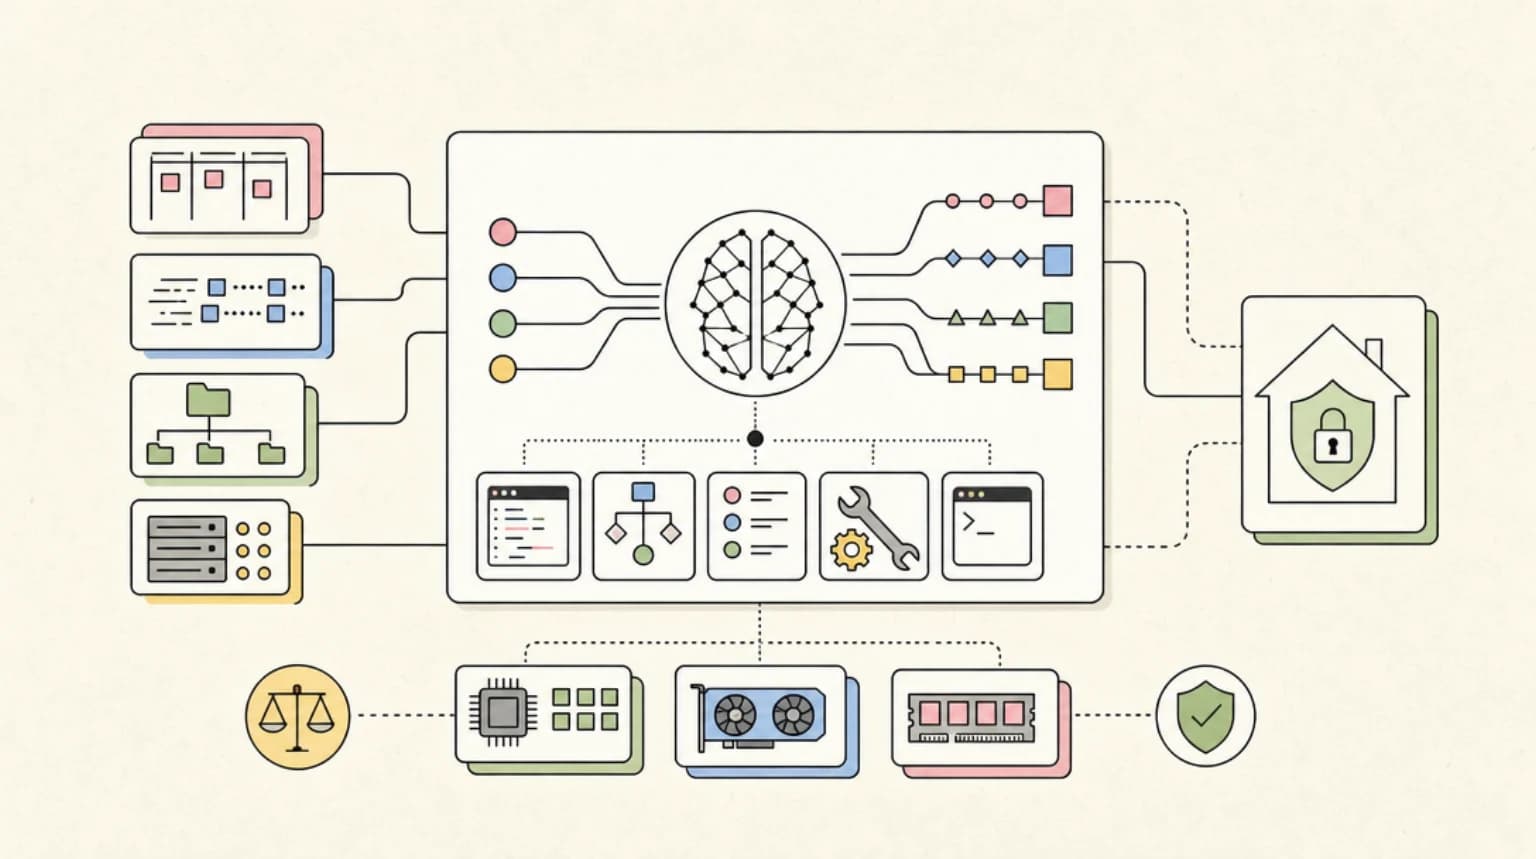
Running Gemma 4 26B at 5 Tokens/Sec on a 13-Year-Old Xeon With No GPU
Gemma 4 26B on a 2013 Xeon with no GPU: how a sub-$300 box reached about 5 tokens/sec, the silent MoE bug behind the gibberish, and the upstream fix.
6 min read
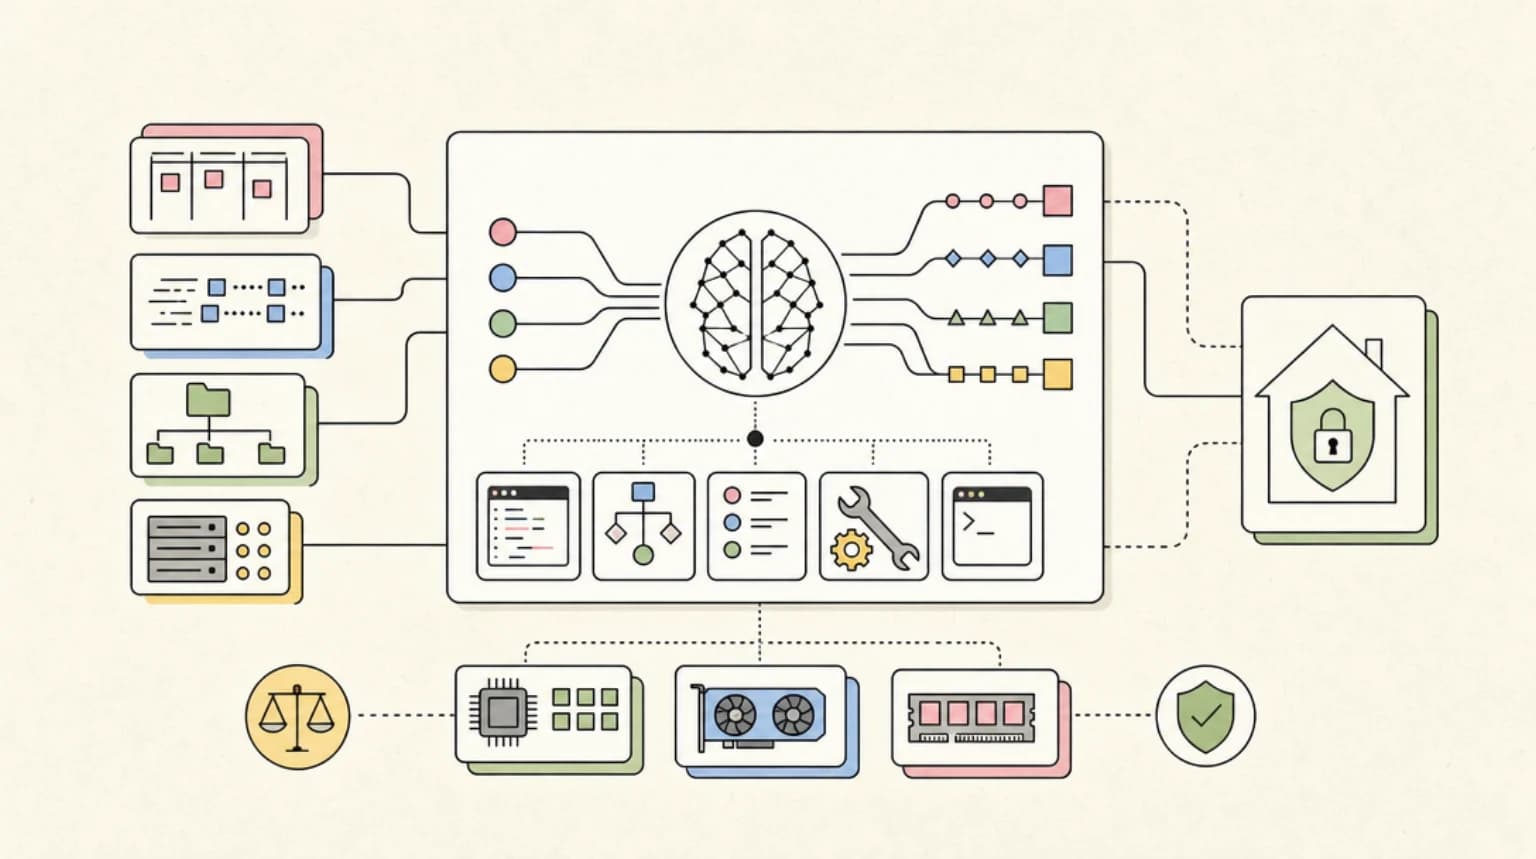
Colibri: Run GLM 5.2 on a 32GB Laptop With Disk Streaming
A solo developer built a 1,300-line C inference engine that runs the 744B GLM 5.2 model on consumer hardware by streaming routed experts from disk.
6 min read
Kokoro: Local, CPU-Friendly TTS That Actually Sounds Good
An 82M parameter text-to-speech model that runs on CPU and produces high-quality speech across multiple languages - no cloud APIs or GPU required.
6 min read
Program-as-Weights Turns Prompts Into Local Fuzzy Functions
Program-as-Weights compiles prompts into compact local adapters that act as fuzzy functions. What the paper claims and where developers could use it first.
7 min read
GLM-5.2 Local Deployment: Running Z.ai's 744B Model on Consumer Hardware
Run GLM-5.2 locally with Unsloth dynamic quantization: hardware math for a 256GB Mac or 24GB GPU, quantization tradeoffs and lessons from the HN thread.
7 min read
DiffusionGemma: Google Bets Diffusion Can Make Text Generation 4x Faster
DiffusionGemma is Google's 26B MoE open model that generates 256-token blocks in parallel. What diffusion generation means for latency and local inference.
8 min read
What Is Cline? The Open-Source AI Coding Agent for VS Code
Cline is a free, open-source VS Code extension for agentic AI coding. Bring your own model, a cloud API or a local one via Ollama, with no vendor lock-in.
9 min read
Client-Side Tool Calling Is the Privacy Pattern AI Apps Need
Client-side tool calling keeps sensitive documents in the browser while the model requests narrow actions. How it works and what still leaves the machine.
7 min read
DeepSeek R1 and V3: The Developer's Guide to Open-Source AI
DeepSeek R1 and V3 developer guide: use the MIT-licensed models through the API, run them locally with Ollama and decide when they beat closed-source models.
9 min read
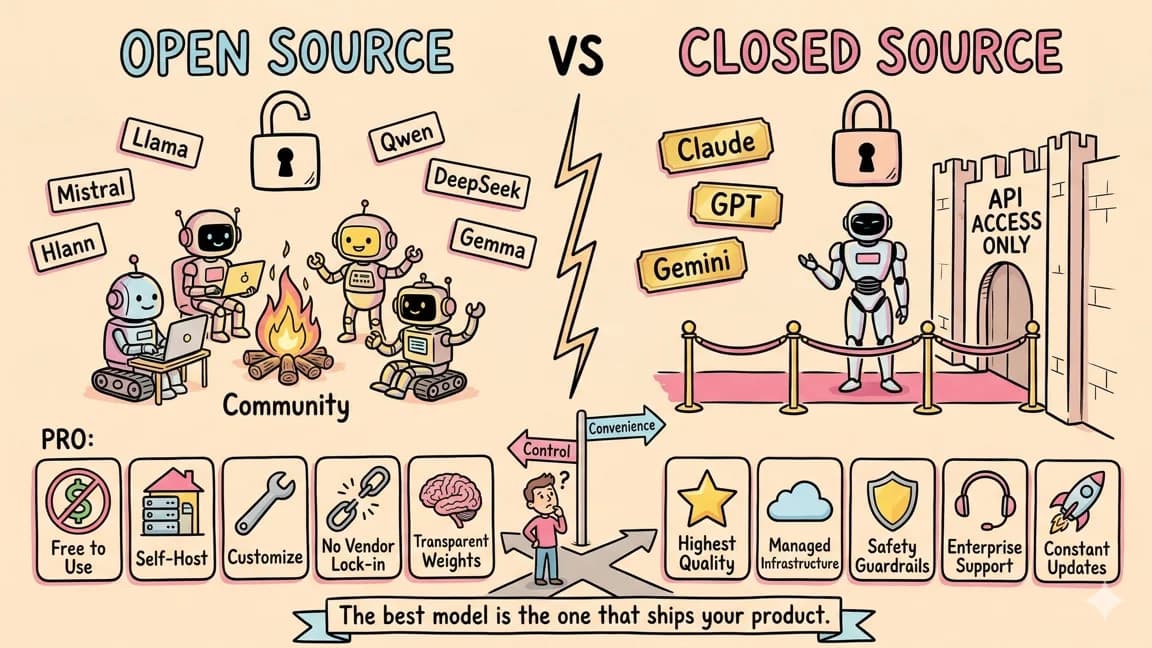
Llama 4: The Complete Developer's Guide to Meta's Open Source Models
Llama 4 developer guide to Scout and Maverick, the open mixture-of-experts models from Meta: run them locally, call them via APIs and know when to pick them.
10 min read

NVIDIA Nemotron Nano 9B V2: Local AI That Punches Up
NVIDIA Nemotron Nano 9B V2 is a hybrid Mamba-transformer small model that runs on consumer GPUs. See how its reasoning controls, open data and tool use work.
7 min read
Microsoft PHI-4: A 14B Parameter Model That Rivals Models 5x Its Size
Microsoft PHI-4 is an MIT-licensed 14B model that matches Llama 3.3 70B on key benchmarks. See its specs, how to run it locally with Ollama, and when to use it.
9 min read
Related Tools
All tools →Ollama
The easiest way to run LLMs locally. One command to pull and run any model. OpenAI-compatible API. 52M+ monthly downloads. Supports GGUF, Safetensors, and custom Modelfiles.
Local AILM Studio
Desktop app for discovering, downloading, and running local LLMs. Clean chat UI, OpenAI-compatible API server, and automatic GPU detection. MLX engine optimized for Apple Silicon.
Local AIJan
Open-source ChatGPT alternative that runs models fully offline. Desktop app with local models, cloud API connections, custom assistants, and MCP integration. Apache 2.0 licensed.
Local AIGPT4All
Private local AI chatbot by Nomic. MIT licensed with 77K+ GitHub stars. LocalDocs lets you chat with your own files. Runs on Windows, macOS, and Linux; latest release is v3.10.0 from February 2025.
Local AILocalAI
Open-source OpenAI API replacement. Runs LLMs, vision, voice, image, and video models on any hardware, no GPU required. 60+ backends. Distributed mode for scaling.
Local AIllama.cpp
C++ inference engine for LLMs. GGUF format, quantization, CPU and Metal/CUDA support. The foundation most local tools build on.
Local AIvLLM
High-throughput inference server for LLMs. PagedAttention memory management. The go-to for serious local or self-hosted serving.
Local AIMLX
Apple's array framework for machine learning on Apple Silicon. Native Metal support, unified memory, first-class LLM inference.
Local AIKeep exploring
More on Local AI
- - Ollama - recommended Local AI tool from the Developers Digest directory
- - Tools Directory - dive deeper across the Developers Digest knowledge base
- - All Local AI articles in the blog archive
- - Developers Digest on YouTube - video tutorials covering Local AI and more
Get Smarter About AI Dev
New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
One email per weekReal code, not theoryFree forever
Explore 848 topics
Browse All Topics