cdnjs Runs Entirely on Cloudflare's Developer Platform: 9 Billion Requests a Day on Workers
TL;DR
cdnjs now runs entirely on Cloudflare Workers, Workflows, R2, and Queues. How the publishing pipeline was rebuilt and the two platform limits it raised.
Last updated: July 31, 2026
As of June 23, 2026, cdnjs runs exclusively on Cloudflare's Developer Platform. Cloudflare announced the completion of the migration on July 30, and the numbers behind it are worth a second read: cdnjs serves an average of 108,000 requests per second, 9 billion per day, across 330+ data centers, with a 98.6% cache hit rate. It is used on roughly 12% of all websites and holds a 48.3% share of the JavaScript CDN market.
What changed#
cdnjs is the free, open-source CDN for JavaScript and CSS libraries. Instead of bundling jQuery, Bootstrap, or Lodash yourself, you drop a script tag pointing at cdnjs.cloudflare.com. Ryan Kirkman and Thomas Davis built it in 2011, Cloudflare started hosting it months later, and took over maintenance in 2019.
The serving side has been on Cloudflare for years. In 2020, Cloudflare moved file delivery onto Workers and KV with Brotli and gzip pre-compression. The publishing side was the holdout: the pipeline that watches npm and GitHub for new versions, downloads tarballs, minifies, and compresses files stayed on GCP, because Workers lacked long-running orchestration primitives at the time.
The old pipeline was a chain of GCP Cloud Functions, a git-sync VM, and the GitHub repository as source of truth. It had five structural pain points:
- No shared trace. A single package update passed through Cloud Functions, GCS, Pub/Sub, a VM, and Workers KV, with no common correlation ID. Partial success was undetectable: a version could serve fine for weeks while the two stores silently diverged.
- Split-brain storage. Files lived in Workers KV and the GitHub repo at once, and neither was authoritative.
- Storage as a message queue. Cloud Functions handed off through object events, with no dead-letter queue, no backlog visibility, and no replay on failure.
- 26 functions for 26 letters. One Cloud Function per alphabet letter checked npm for updates, each with its own deployment and logs.
- A repo GitHub could not serve. Years of releases pushed cdnjs/cdnjs past 1.1TB of packed storage, so GitHub's archive service refused to generate tarballs, forking was impractical, and .gitignore carried 274 hand-curated entries.
The new architecture#
The rebuilt pipeline is the interesting part, because it is a template for anyone running multi-hour ingestion jobs on Workers:
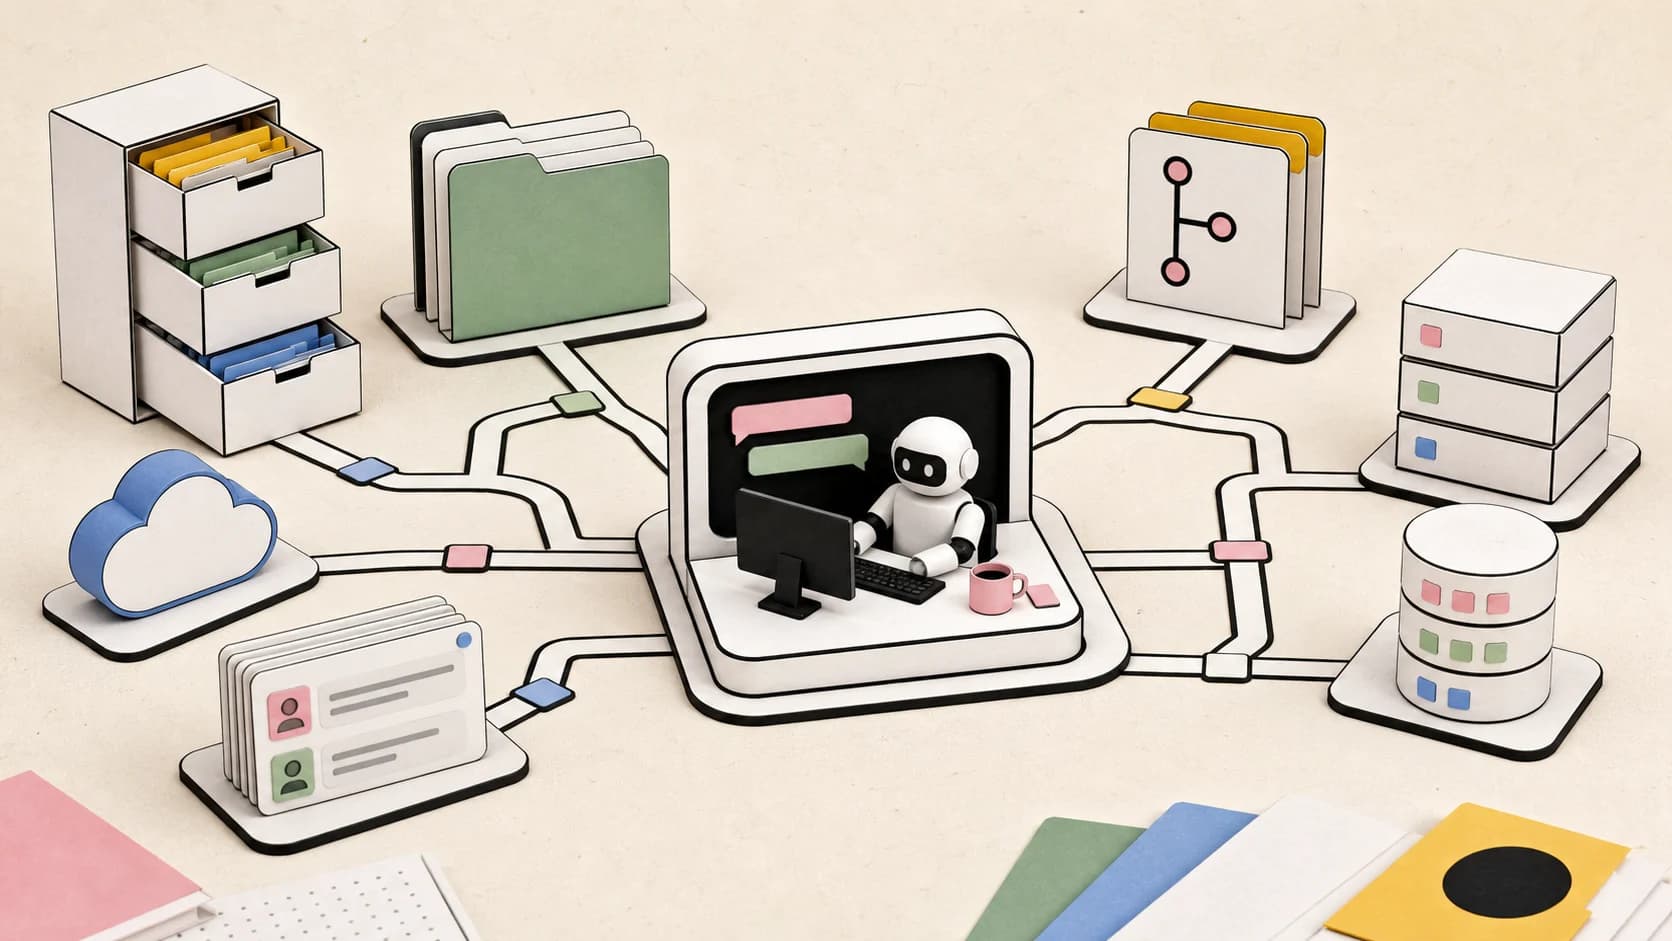
- R2 is now the single source of truth for file content, with no practical size limit. Source maps, big bundles, and font packs that never fit in KV now live there. The S3 API exposes the entire catalog to any S3 client.
- KV stores metadata only: package info, version lists, and SRI hashes.
- Workers Cache, the tiered cache Cloudflare launched this year, sits in front and replaced a separate internal caching layer.
- DigitalOcean Spaces mirrors every published file as a disaster-recovery copy and a live fallback. The serving chain is cache to R2 to DigitalOcean.
- A cron job fires PackageUpdatesWorkflow every 10 minutes. It spawns DownloadPackageWorkflow per new version, ProcessingWorkflow per file, and PublishingWorkflow to write results to R2, KV, and the Algolia search index.
- Workflows provide durable execution: each step's state is preserved, and a failed workflow resumes from the last successful step.
- File compression runs in an external container running a Rust service. Each ProcessingWorkflow writes an uncompressed file to R2, sends a job to a Queue, and hibernates. The container picks it up, compresses, and writes back. An R2 event notification wakes the workflow.
- A small Durable Object acts as a counter for fan-in: the parent increments per spawned child, children decrement on completion, and the parent wakes when the counter hits zero.
Two platform limits, raised for everyone#
The migration surfaced two hard limits, and instead of just working around them, Cloudflare raised them:
- Workers subrequests capped at 1,000 per invocation on paid plans. cdnjs needed to copy millions of files without regenerating them. The limit is now 10 million per invocation on paid plans.
- Workflows capped at 1,024 steps. They now default to 10,000 steps, configurable to 25,000.
There is also a cautionary tale in the migration history. Cloudflare had tried this once before and rolled back: re-processing old packages produced files that did not byte-match what KV was serving, because minifiers and compressors are not fully deterministic across versions. For a CDN where users pin SRI hashes in their HTML, that is a serving break. So the team migrated existing content as-is instead of regenerating it, trading a reprocessing problem for a copy problem.
Why this matters#
Three things stand out for developers.
First, the boundary between "edge serving" and "long-running pipeline" has effectively dissolved. A year ago, this workload would have required a VM or a cloud functions chain. Today it runs on the same primitives Cloudflare sells to everyone: Workers, Workflows, R2, KV, Queues, Containers, and Durable Objects. The failure-recovery model of Workflows - resume from the last successful step - is exactly what ingestion pipelines need, and it is the same durable-execution idea now spreading across platforms. If you are evaluating durable execution for your own stack, compare how Cloudflare handles state resumption against Vercel's programming model.
Second, cdnjs is now a supply-chain surface worth paying attention to. Every file ships with an SRI hash, versions are immutable, and the project is open source. Cloudflare notes it is still verifying that all historically stored hashes match reality, because the old system had bugs. In a world where AI agents install dependencies on autopilot, an immutable, hash-verified mirror is meaningful infrastructure - the same trust-boundary problem that showed up in the TanStack npm compromise and in hallucinated package names.
Third, the LLM angle is real: when ChatGPT, Claude, or Cursor scaffold a quick HTML demo, they reach for cdnjs because their training data is full of it. The URL pattern is consistent and versions are immutable, which makes it the rare dependency a model can produce without hallucinating. That means every AI-scaffolded demo in the next few years inherits this migration's correctness.
The honest take#
This is a dogfooding post, and it is unusually candid for one. Cloudflare names the failures (the rolled-back migration, the byte-mismatch trap, the hashes that need auditing), shows the exact limits it had to lift, and retires a 1.1TB repository it relied on for a decade. The "what's next" section is also refreshing: serving browser-native ES modules from cdnjs is now possible to consider, which was not true a year ago. For anyone building on Cloudflare's platform or comparing it to the distributed-systems work coming out of the same network, the cdnjs migration is the most complete proof of what the platform can actually carry.
FAQ#
Does cdnjs run on Cloudflare Workers now?#
Yes. As of June 23, 2026, cdnjs runs exclusively on Cloudflare's Developer Platform, and Cloudflare announced the completed migration on July 30. File serving moved to Workers and KV back in 2020; the publishing pipeline, which had stayed on GCP, now runs on Workers, Workflows, R2, KV, Queues, Containers, and Durable Objects.
Which Cloudflare platform limits did the cdnjs migration raise?#
Two. Workers subrequests, previously capped at 1,000 per invocation on paid plans, now go up to 10 million per invocation on paid plans. Workflows, previously capped at 1,024 steps, now default to 10,000 steps and are configurable to 25,000.
Why didn't Cloudflare regenerate existing cdnjs files during the migration?#
An earlier attempt was rolled back because re-processing old packages produced files that did not byte-match what KV was serving, since minifiers and compressors are not fully deterministic across versions. With users pinning SRI hashes in their HTML, that is a serving break, so the team migrated existing content as-is instead.
Where does cdnjs store its files now?#
R2 is the single source of truth for file content, KV stores metadata only (package info, version lists, and SRI hashes), and Workers Cache sits in front. DigitalOcean Spaces mirrors every published file as a disaster-recovery copy and live fallback, so the serving chain is cache to R2 to DigitalOcean.
Continue Reading#
- Cloudflare Temporary Accounts: Let Agents Deploy Without OAuth Flows
- Cloudflare Meerkat: A New Approach to Global Consensus Without Leaders
- Vercel's New Durable Execution Programming Model
- HalluSquatting Makes AI Coding Agents a Supply-Chain Problem
- TanStack's npm Compromise Is the CI Lesson Agent Teams Needed
- Workers Can Now Accept Inbound TCP and Serve gRPC: Cloudflare Closes the HTTP-Only Gap
Sources#
Get the next deep dive like this in your inbox
One email a week on News and the rest of the AI dev stack. Free.
Read next
Kitesurf: Cloudflare's Agent-First Browser Runs in V8 Isolates on Workers
Cloudflare shipped Kitesurf, an agent-first browser that runs entirely on Workers: Rust and WebAssembly rendering, per-page isolates, CDP compatibility, and 3-7x less memory and CPU than Chromium for common agent tasks. Free in beta in Browser Run.
7 min readWorkers Can Now Accept Inbound TCP and Serve gRPC: Cloudflare Closes the HTTP-Only Gap
Cloudflare Workers can now accept inbound TCP and serve gRPC: a connect() handler via Spectrum, full-duplex gRPC from Containers, and gRPC-web translation.
6 min readCloudflare Now Lets AI Agents Deploy Workers Without Signup
Cloudflare's wrangler deploy --temporary flag gives AI agents an ephemeral account to deploy Workers with no OAuth or browser, plus a claim link to keep it.
8 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.