Topic
CODE QUALITY
All blog posts, tools, and guides about Code Quality from Developers Digest.
7 resources - 7 posts
Blog Posts
View in blog →
OwlPath: Ontology-Based Code Retrieval Cuts Agent Tokens 29%
OwlPath encodes code into an OWL2 ontology so coding agents can answer multi-hop structural queries with SPARQL, cutting tokens 28.8% on SWE-bench Pro.
6 min read
SWE-NFI: The Benchmark That Catches What Coding Agents Miss
SWE-NFI benchmarks coding agents on 188 behavior-preserving improvement tasks. The best hits 70% correctness, but all lag humans on structural refactors.
6 min read
Benchmarking Opus 5 on SlopCodeBench: AI Code Quality Under Iteration
Opus 5 on SlopCodeBench hit a 24% strict pass rate, beating Opus 4.8 and Sonnet 5, yet code quality still degraded. What it shows about coding agents over time.
7 min read
Write Code Like a Human Will Maintain It - The AI Era Debate
Write code like a human will maintain it: why AI-generated shortcuts teach future models bad patterns, and what the HN debate suggests for keeping quality up.
6 min read
Clean Code Makes AI Agents 34% More Efficient - New Research
A controlled study of 660 Claude Code trials shows clean codebases reduce token usage by 7-8% and file revisitations by 34%, while pass rates stay the same. Traditional maintainability principles still matter in the age of AI coding.
7 min read
Does Code Cleanliness Affect AI Coding Agents?
Does code cleanliness affect AI coding agents? A SonarSource study finds the same pass rate, but 7-8% fewer tokens and 34% fewer file revisits on clean code.
5 min read
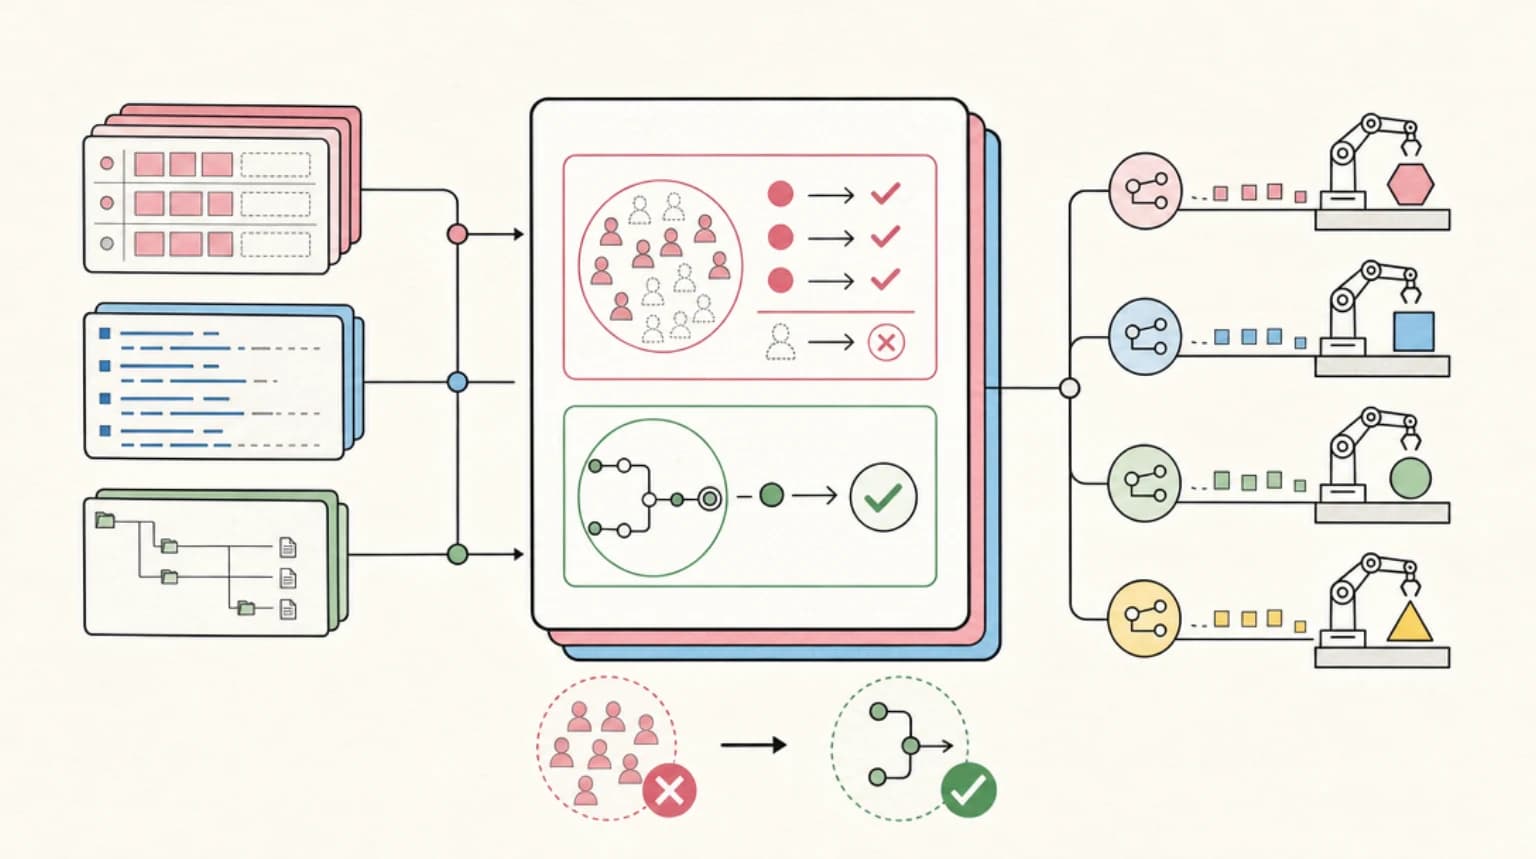
FrontierCode Benchmark Explained: Why AI Coding Quality Scores Are Wrong (And the Fix)
FrontierCode grades AI coding agents on whether maintainers would merge their PRs, not on passing tests. Why SWE-Bench misleads and how to adjust review.
8 min read
Keep exploring
More on Code Quality
- - Compare Tools - dive deeper across the Developers Digest knowledge base
- - All Code Quality articles in the blog archive
- - Developers Digest on YouTube - video tutorials covering Code Quality and more

Get Smarter About AI Dev
New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
One email per weekReal code, not theoryFree forever
Explore 841 topics
Browse All Topics