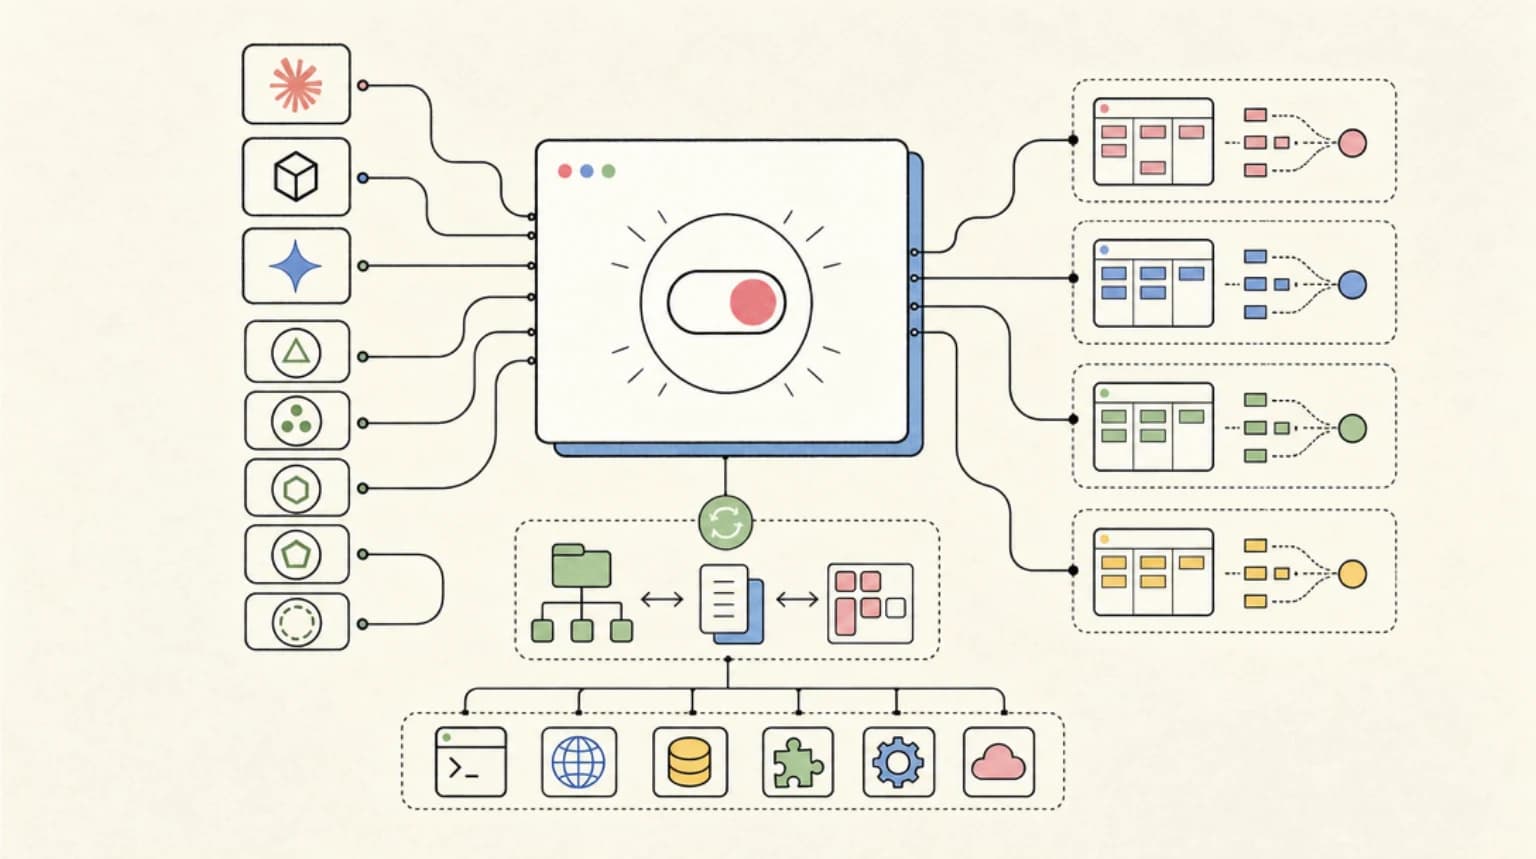
Claude Code Plugin Evals Make Agent Extensions Testable
TL;DR
Claude Code plugin evals score a plugin against a no-plugin baseline, write JSON and HTML reports and gate CI, making plugins testable agent infrastructure.
Claude Code 2.1.269 shipped a feature that looks small until you maintain agent tooling for a team: claude plugin eval.
Last updated: September 13, 2026
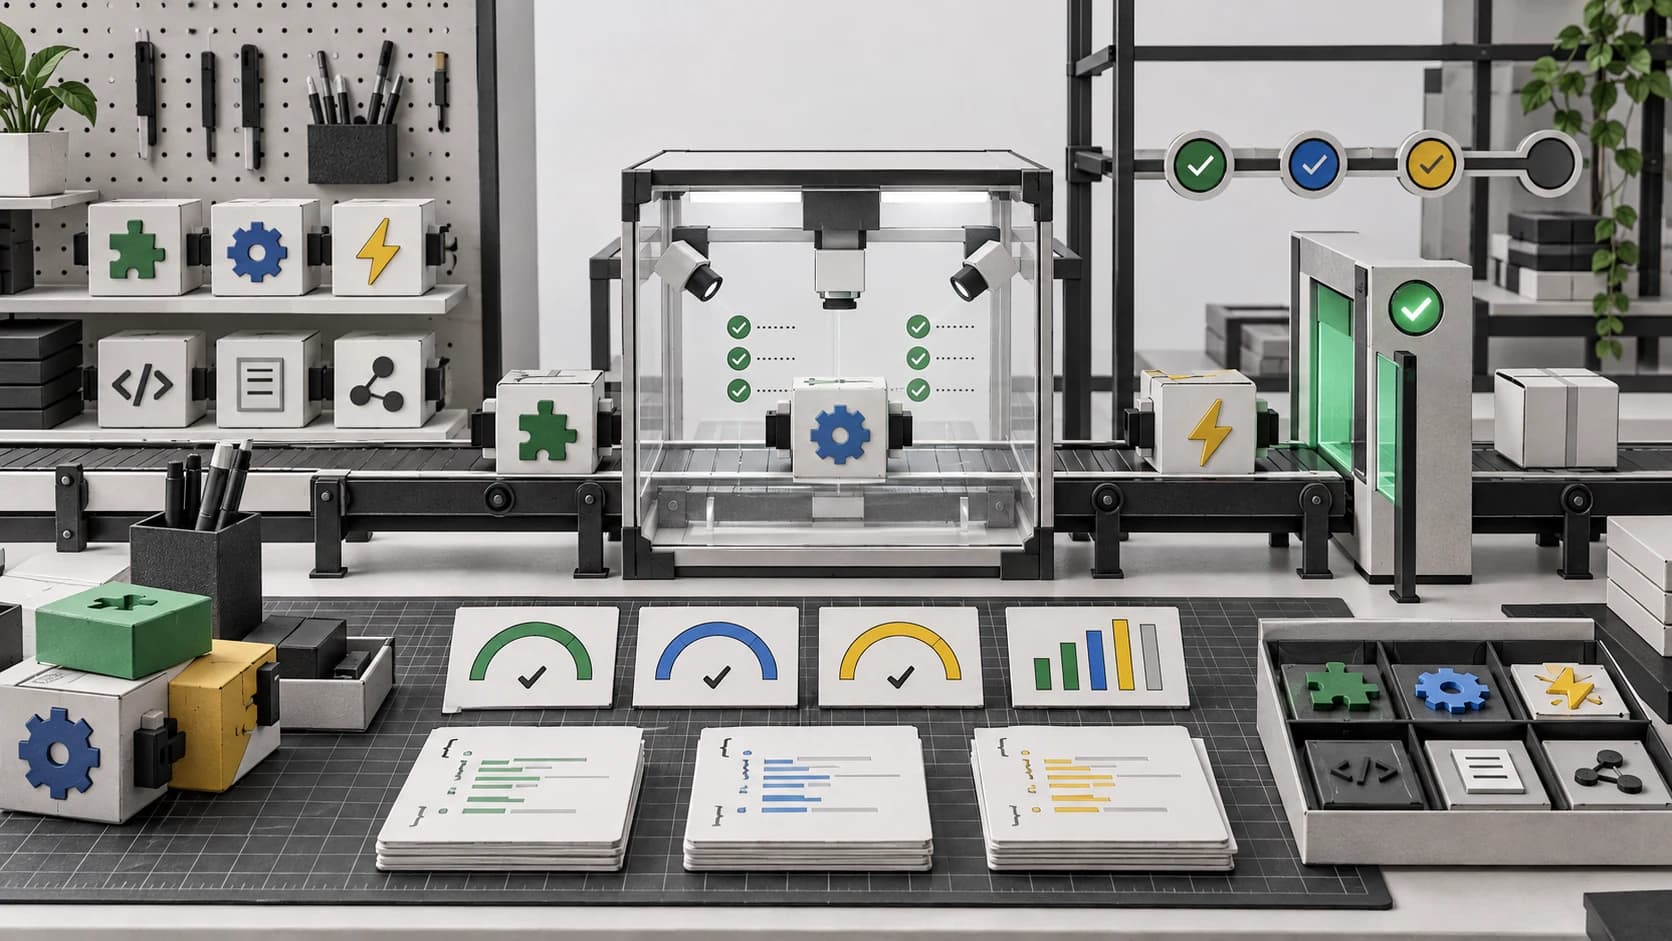
The command runs a plugin against a suite of cases, scores what happened, compares it with a no-plugin baseline, and writes JSON plus an HTML report. In other words, Claude Code plugins can now have regression tests that measure behavior, not only syntax.
That matters because plugins, skills, hooks, and MCP servers are quickly becoming the operating layer around coding agents. We have written before that skills beat giant prompts, but reusable agent knowledge creates a new problem: how do you know a skill or plugin still works after you edit it, update Claude Code, change a model, or add another tool to the environment?
Plugin evals are Anthropic's answer. They turn "this plugin feels helpful" into "this plugin improved the score over baseline on the cases we care about."
What Shipped#
The 2.1.269 release notes include several useful changes, but three are especially relevant for agent operators:
claude plugin evalruns a plugin eval suite and produces scored JSON plus HTML reports./output-style [name]can list and switch output styles across local, remote-control, cloud, and headless sessions.- Bash tool results can include a diff of files changed when Bash handled file edits, behind the
bashEditDiffEnabledsetting.
There is also a cluster of operational fixes: prompt-cache reuse after output-limit resumptions, better resumed headless-session behavior, clearer background-agent status, stricter permission-rule scoping for ! negations, current git status after compaction, synced plugin MCP server reconnection, and a configurable workflow-agent concurrency limit.
Then 2.1.270 followed the next day with a narrow regression fix for read-only git commands unexpectedly asking for permission in long-running Bash sessions. That is worth noting because it reinforces the same point: agent runtimes are now operational systems with regressions, fixes, gates, and release hygiene.
The Important Part Is the Baseline#
The plugin eval docs describe the core idea plainly: each case is a realistic user prompt plus graders that inspect the final reply, transcript, tool use, or produced files. By default, a case runs multiple times with your plugin and again with no plugin loaded.
That no-plugin arm is the important bit.
Without a baseline, a plugin score can fool you. Claude might pass the case because the underlying model already knows what to do. Or it might pass because the prompt is too easy. Or your grader might reward a generic answer that never used the plugin at all - the same failure mode behind coding agents learning to please the grader.
The baseline gives you a delta. If the with-plugin arm scores 1.0 and the without-plugin arm scores 0.33, the plugin probably added real behavior. If both score 1.0, the plugin may still be useful for consistency or style, but it did not prove extra capability on that case.
That is a healthier evaluation culture than treating every plugin demo as evidence.
Why This Changes Plugin Authoring#
Claude Code plugins used to be easiest to judge by inspection:
- Does the manifest load?
- Do the commands appear?
- Does the skill description look specific enough?
- Does the MCP server connect?
- Does a demo prompt produce a convincing answer?
Those checks are necessary, but they are shallow. They catch packaging errors and obvious failures. They do not prove the plugin reliably steers an agent under realistic phrasing.
Plugin evals push authors toward a better loop:
- Write the plugin.
- Create eval cases from the way users actually ask for help.
- Add deterministic graders where possible.
- Compare with and without the plugin.
- Gate changes in CI on a score threshold.
- Re-run when Claude Code, the model, or the plugin changes.
That is exactly the direction argued in Agent Skills Need Exit Criteria. A reusable skill is not production-ready because it has a polished README. It is production-ready when it has trigger tests, failure cases, scope boundaries, and evidence that it improves the agent's work.
What an Eval Case Measures#
The docs list six grader types. The most practical split is deterministic checks versus judge-model checks.
Deterministic graders include regex matches, tool-use checks, tool-order checks, and file-exists checks. These are cheap and stable. Use them whenever the expected behavior has a concrete artifact:
- the plugin's skill fired
- a command was called
- a file was created
- the final answer included a required phrase
- a generated file contains a required field
Judge-model graders are useful when the answer needs semantic review, but they add cost and variance. The docs recommend concrete pass and fail conditions, and they warn that small judges can mark a correct answer wrong when formatting differs from the rubric.
That maps cleanly to coding-agent work. Let deterministic graders prove the boring parts. Use model judges only for the parts that genuinely need judgment.
CI Is Where This Gets Real#
The docs explicitly position plugin evals as something teams can gate in CI. That is the shift from hobby plugin to shared infrastructure, and it pairs with distributing plugins through a company marketplace, covered in Claude Code plugins for teams. For a public listing, running evals is also a sensible step before you submit a plugin to the Claude directory.
A useful CI policy might look like this:
- Run one cheap smoke case on every plugin PR.
- Run the full eval suite before release.
- Require a positive baseline delta on cases where the plugin claims unique behavior.
- Save JSON reports as build artifacts.
- Keep HTML reports for human review on failures.
- Re-run the suite when upgrading Claude Code across the team.
This is also where costs need to be visible. Anthropic's docs state that eval runs and judge graders are real model calls on your account. A case can multiply quickly because it may run with the plugin, without the plugin, across multiple repetitions, and with judge calls after each run.
That is not a reason to skip evals. It is a reason to tier them. Keep cheap deterministic smoke tests in the hot path, and reserve broad model-judged suites for releases or nightly checks.
The Bash Diff Feature Belongs in the Same Story#
The release also adds an option for Bash tool results to include a diff of files changed when Bash handles file edits. That sounds unrelated, but it solves the same category of problem: making agent behavior inspectable after the fact.
When a model edits a file through a direct edit tool, the review surface is usually obvious. When it runs a shell command that changes files, the user may only see that a command succeeded. Surfacing the diff closes that gap.
Pair that with plugin evals and you get a better receipt trail:
- the plugin was loaded
- the right skill or tool fired
- the task produced the expected artifact
- file-changing shell commands showed their diff
- the run cleared a threshold
- the result was saved as JSON or HTML
That is how agent work becomes auditable instead of vibes-based.
Demand Signal: Steady Claude Code, Sparse Plugin Search#
Google Trends was usable for this run. In a US 90-day check on September 13, 2026, Claude Code had steady relative interest, while Claude Code plugin, Claude Code plugins, and coding agent eval were sparse or near zero. AI coding agent had modest recurring interest, but it was much smaller than the broad Claude Code query.
So this is not a breakout-keyword article. The release is worth covering because it sits at the intersection of two durable lanes: coding agents and repeatable agent skills.
Hacker News search showed the same shape. A September 11 story titled "Anthropic released a CLI to evaluate skills and plugins" had only a few points and comments at fetch time, while broader Claude Code and Anthropic stories had more activity. This is a practitioner topic, not a mass-market launch.
What I Would Test First#
If you maintain a Claude Code plugin or a skills-directory plugin, start with three cases:
- A positive trigger case where the plugin should clearly help.
- A near-miss case where the plugin should stay out of the way.
- A regression case based on a real failure your team has seen.
For the first case, include a grader that checks the useful artifact, not only whether the skill fired. For the second, make sure the plugin is not over-triggering. For the third, encode the failure in the simplest possible form so it survives model updates.
Then run the suite with the no-plugin baseline enabled. The goal is not a vanity score. The goal is to learn where the plugin changes behavior and where the model already handles the request without help.
That is the difference between authoring a clever extension and maintaining an agent control surface.
Bottom Line#
Claude Code plugin evals are not flashy, but they are a maturity signal.
The developer tooling market has spent the last year adding more agent extensions: skills, commands, hooks, MCP servers, output styles, subagents, remote sessions, scheduled work, and cloud runners. The next bottleneck is proving those extensions still do what teams think they do.
claude plugin eval gives plugin authors a way to measure that. It will not make agent behavior perfectly deterministic, and it will not replace human review. But it gives teams a concrete loop: cases, graders, baseline, report, threshold, CI.
That is what agent infrastructure has been missing.
Continue Reading#
- Why Skills Beat Prompts for Coding Agents in 2026 - the control-stack argument behind reusable agent methods
- Skills Are the New Agent Operating System - why packaged workflows are becoming the unit of agent distribution
- Agent Skills Need Exit Criteria - a practical checklist for shipping reusable skills safely
- Claude Code Plugin URL Supply Chain Risk - the trust boundary around installable agent extensions
- Claude Code 2.1.128 Is an Ops Release, Not a Feature Drop - earlier evidence that Claude Code is becoming an operable runtime
- Claude Code Power User course - packaging plugins, wiring hooks, and running Claude Code headless in GitHub Actions
- How to Evaluate AI Agents in Practice: Trajectories, Tool Calls and Judges
- Claude vs Claude Code: What the Difference Is and Which to Use - the chat app against the coding agent, and how they share plan limits
- CleanYourTV: Debloat Your TV With Claude Code, Safely - a prompt-and-scripts repo as a distribution format, and what its failure rules teach
FAQ#
What is claude plugin eval?#
claude plugin eval is a Claude Code command that runs a plugin against test cases, scores the results with graders, compares behavior against a no-plugin baseline, and produces JSON plus HTML reports.
Why does the no-plugin baseline matter?#
The baseline shows whether the plugin actually improved the result. If Claude passes the same case with and without the plugin, the plugin may not be adding measurable behavior for that scenario.
Can Claude Code plugin evals run in CI?#
Yes. Anthropic's docs describe CI gating as a primary use case. Teams can run plugin eval suites, enforce score thresholds, and save JSON or HTML reports as review artifacts.
Are plugin evals free to run?#
No. Eval runs and judge-model graders are real model calls against the account or provider used by Claude Code. Teams should keep cheap deterministic checks in the fast path and reserve broader suites for release or nightly runs.
Does this replace human review?#
No. Plugin evals make behavior more measurable, but agent extensions still need human review for scope, security, usefulness, and failure modes.
Sources#
- Claude Code v2.1.269 release notes - fetched September 13, 2026
- Claude Code v2.1.270 release notes - fetched September 13, 2026
- Anthropic docs: Test plugins with evals - fetched September 13, 2026
- Claude release notes: smart reports beta - checked September 13, 2026 as adjacent enterprise observability context
- Google Trends Explore request for
Claude Code,Claude Code plugin,AI coding agent,Claude Code plugins, andcoding agent eval- fetched September 13, 2026 - Hacker News Algolia search for recent Claude Code stories - fetched September 13, 2026
Get the next deep dive like this in your inbox
One email a week on Claude Code and the rest of the AI dev stack. Free.
Read next on Claude Code
Why Skills Beat Prompts for Coding Agents in 2026
Skills beat prompts for coding agents because giant prompts do not scale. The 2026 control stack: project rules, reusable skills, bounded sub-agents and tools.
9 min readSkills Are the New Agent Operating System
Agent skills turn team process into small, reusable operating procedures that load when relevant. Why skills beat one giant prompt for coding agents.
9 min readAgent Skills Need Exit Criteria, Not More Prompt Lore
Agent skills work when they carry exit criteria. What Addy Osmani's agent-skills repo gets right about turning AI coding advice into engineering checklists.
7 min readTechnical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.