Meta Ships Muse Code and Muse Spark 1.2: A Terminal Agent With a 12x Cheaper Contributor Tier
TL;DR
Meta Muse Code is a terminal coding agent co-trained with Muse Spark 1.2. How the harness works and what the $0.10/$0.20 contributor tier asks in return.
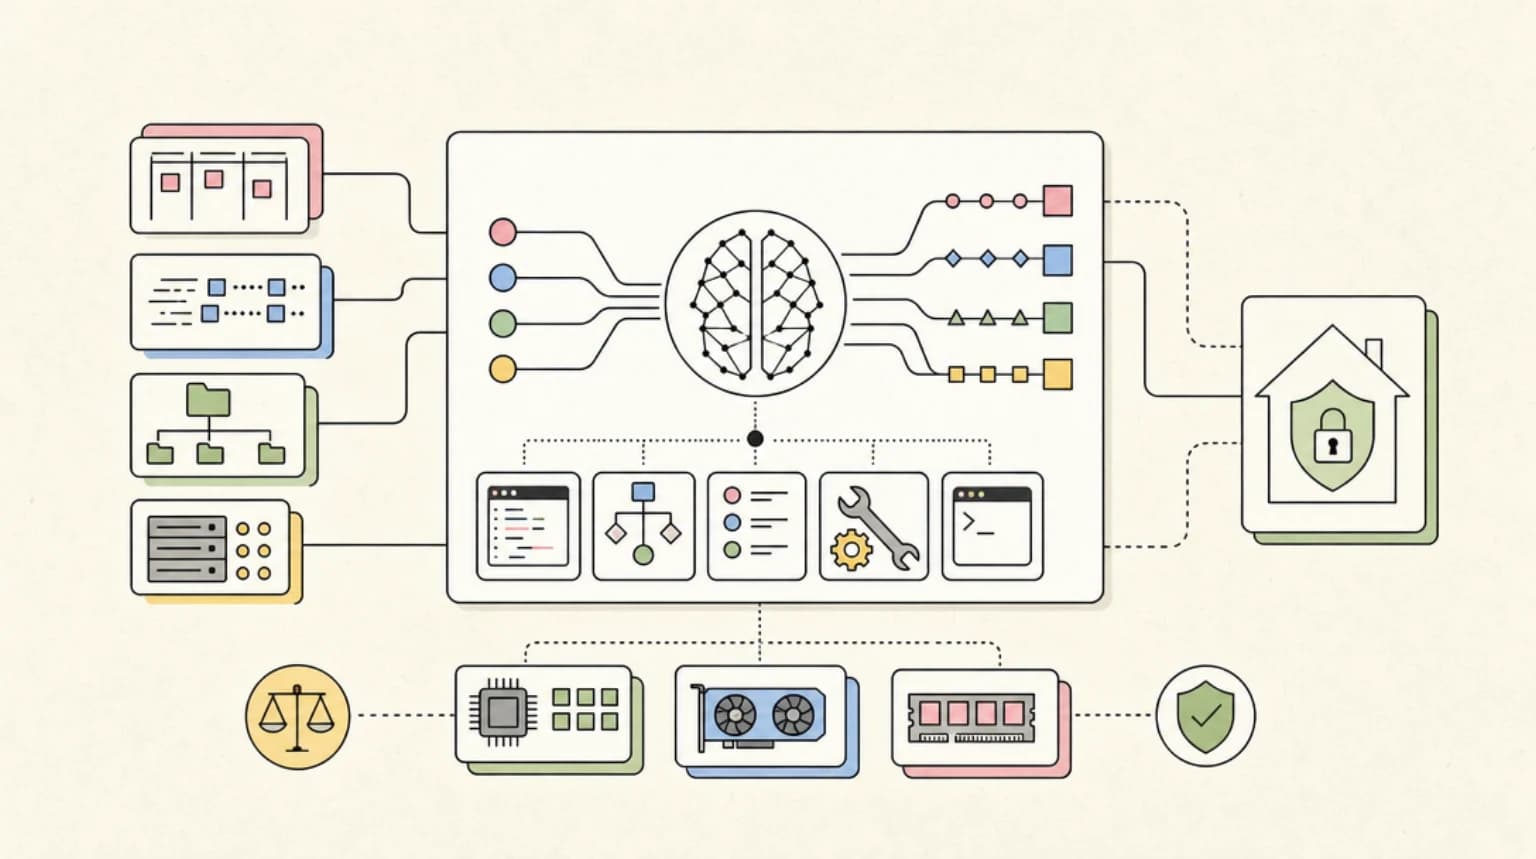
Meta released Muse Code (beta) on August 5, 2026 - a terminal coding agent for macOS and Linux - together with Muse Spark 1.2, the model that powers it. The model and the harness were co-trained, which is the structural choice worth noticing: Muse Spark 1.2 was trained inside its own agent runtime, so the model's behavior and the harness's goals, compaction, and subagent recipes were optimized as one unit.
The pricing is the other headline. The Meta Model API lists two model IDs for the same weights: muse-spark-1.2 at $1.25 per million input tokens and $4.25 per million output, or muse-spark-1.2-contributor at $0.10 input and $0.20 output - roughly 12x cheaper on input - if you agree to let Meta use your data to improve its products. The contributor tier lands in the same band as DeepSeek V4 Flash ($0.14/$0.28) and below GPT-5.6 Luna's post-cut $0.20/$1.20, and it makes the data-for-discount trade explicit in a way most vendors keep implicit.
Official Sources#
| Resource | Link |
|---|---|
| Meta AI Research announcement | research.meta.ai/blog/introducing-muse-code-and-muse-spark-1-2 |
| Muse Code product page | dev.meta.ai |
| Muse Spark model and pricing page | developer.meta.com/ai/models/muse-spark |
| Meta Model API docs | developer.meta.com/docs/model-api |
| Methodology report | research.meta.ai/static/muse-spark-1-2-methodology |
What Muse Code Actually Is#
Muse Code is a terminal coding agent with three design choices that separate it from a repackaged CLI wrapper:
-
Async background agents. Beyond the main agent loop, a set of specialized agents stay alive for the whole session instead of being spawned per task. They run next steps and decide when to report back to the main agent, which Meta says cuts redundant information gathering and reduces steering on long multi-step work.
-
A replay-exact event log. Every model call, tool run, approval, and edit is appended to a local log that acts as the single source of truth. That makes the runtime restart-safe: after a crash, the agent resumes from the exact point it stopped.
-
Bundled skills out of the box.
/planturns a task into an approval-gated plan,/grillstress-tests the plan until it holds up, and/goaldrives toward completion of the stated objective.
Install is a single command on macOS or Linux:
curl -fsSL https://dev.meta.ai/install.sh | bash
What's New in Muse Spark 1.2#
Muse Spark 1.2 is a coding-focused update to the 1.1 that shipped July 9. Meta scaled up training compute on coding tasks and expanded training-environment diversity. Three specifics from the announcement:
- Co-training with the harness. The training mix included rejection-sampled Muse Code trajectories plus recipe optimizations for goals, compaction, and subagents, with the Muse Code toolset integrated into training.
- Long-horizon training. Whole-repository generation, large end-to-end projects, and auto-research are in scope, supported by planning, goal conditioning, and context compaction.
- A self-improvement loop. Meta used Muse Spark 1.1 to generate challenging coding environments and instruction templates, then had the model grade candidate solutions against them to build a scalable training set for 1.2.
The flagship demonstration is kernel optimization: Muse Code iteratively wrote, compiled, profiled, and improved GPU kernels over 1,000+ tool calls (up to 24 hours of runtime) on NVIDIA Hopper hardware. The model designed two-kernel Triton pipelines for both KDA and MLA kernels - for example pairing a chunk-parallel preparation kernel with a sequential inter-chunk scan for KDA - against an FLA Triton baseline.
The Benchmarks and the Caveats#
Meta published chart comparisons on Terminal-Bench 2.1, DeepSWE 1.1, and a Meta-internal coding bench, and included the kernel-optimization speedup curves in the methodology report. The exact numbers live in the charts rather than a table, so treat any specific score you see quoted elsewhere with suspicion. What the charts do show, per the announcement, is a model that tracks the current mid-tier frontier models on terminal tasks while staying competitive on cost.
Two caveats are worth carrying forward. First, the comparison set is the mid tier - community reviewers noted the charts omit the strongest single-shot models of the current generation, and one benchmark comparison against a stronger model did not go Meta's way. Second, harness affinity cuts both ways: the model was trained on Muse Code's own runtime, and several early reports from people running the weights through other harnesses describe degraded tool-calling behavior. Co-training with one harness is the clearest demonstration yet that "works well in Claude Code" and "works well in your harness" are increasingly different questions.
Pricing#
Per the official Muse Spark model page, both tiers serve the same weights; the contributor tier is the opt-in data-training discount:
| Model ID | Input /1M | Output /1M | Condition |
|---|---|---|---|
muse-spark-1.2 | $1.25 | $4.25 | Standard |
muse-spark-1.2-contributor | $0.10 | $0.20 | Meta may train on your data |
For context, the standard tier is roughly where the 1.1 launch sat - the $1.25/$4.25 pair we broke down in the Muse Spark 1.1 developer guide. The contributor tier is the new conversation: at $0.10/$0.20 it undercuts DeepSeek V4 Flash ($0.14/$0.28) on both axes and sits below GPT-5.6 Luna's new $0.20/$1.20. A typical agentic turn - say 50K input and 2K output - costs about $0.005 on the contributor tier versus $0.07 on standard. Teams running agent inner loops at volume are the obvious audience, and the trade is stated plainly: discounted tokens, data used for product improvement.
Running It#
Muse Code runs on macOS and Linux today via the install command above; it is in beta and requires a login. The model is also available through the Meta Model API, which uses an OpenAI-compatible format, so existing SDK code can switch endpoints with minimal changes.
One honest note: Muse Spark 1.2 is not available in OpenCode at the time of writing - the model is closed-weight and gated behind Meta's own platform. If you live in a harness-agnostic setup, the API path matters more than the agent, and the co-training story should make you expect harness-specific behavior differences. Our model routing recipes cover where a 12x-cheaper tier changes routing math.
Contributor vs Standard: Which One Now?#
Use the standard tier when:
- You cannot accept Meta training on your data - code, prompts, and traces included
- You are evaluating Muse Spark 1.2 against other API models on equal data-policy terms
- You need the stable, support-backed path for production workloads
Use the contributor tier when:
- Your code is not sensitive and you are price-sensitive - agent inner loops make per-token cost the dominant factor
- The 12x delta ($0.10 vs $1.25 input) is material to your cost-per-task math
Skip both when:
- You need open weights or a self-hosted path - Muse Spark remains closed, unlike the Llama family
What Developers Are Saying#
The launch discussion split into three camps. The engineering camp found the runtime details genuinely interesting: persistent background agents, the replay-safe event log, and the kernel-optimization curves drew specific, technical engagement - several people noted the speedup charts showed models still improving when the experiment was cut off. The affordability camp treated the contributor tier as the real story: a frontier-adjacent coding model at a roughly 12x discount, with the data trade stated explicitly. The skeptical camp dominated the rest of the thread: the login requirement, the closed weights from the company that built its AI reputation on Llama, and the benchmark comparison set drew the sharpest responses. Early quality reports ran in both directions. The bottom line: pricing and data policy, not raw capability, decide whether this release matters for a given team.
Our Take#
Two things are genuinely new here, and neither is the model's benchmark position. First, model-and-harness co-training as a shipped product, not a research demo: Meta trained the model inside its own agent runtime, and harness affinity is now a real, measurable property. That means model choice and harness choice are becoming a single decision - the same direction Databricks and Prime Intellect are pushing, and the direction we flagged when GLM 5.2 landed in OpenCode as a harness-first release.
The contributor tier is the cleanest statement yet of the data-for-discount trade. Most vendors hide this distinction inside subscription terms or abuse clauses; Meta priced it on the model page as an explicit tier. For teams that keep code out of training data, the standard price is the real price. For teams that do not care, $0.10/$0.20 is now the cheapest frontier-adjacent coding path in the market, and it pressures the DeepSeek V4 Flash pricing floor from the closed-weights side. Expect the next round of coding-model price cuts to come with the same explicit opt-in structure.
FAQ#
What is Muse Code?#
Meta's terminal coding agent (beta, macOS and Linux) powered by Muse Spark 1.2, with persistent async background agents, a replay-exact local event log, and bundled /plan, /grill, and /goal skills. Install with curl -fsSL https://dev.meta.ai/install.sh | bash.
What does Muse Spark 1.2 cost?#
$1.25 per million input tokens and $4.25 per million output on the standard tier, or $0.10 input / $0.20 output on the muse-spark-1.2-contributor tier, which requires opting in to Meta training on your data.
How does the contributor tier compare to other cheap coding models?#
At $0.10/$0.20, the contributor tier undercuts DeepSeek V4 Flash ($0.14/$0.28) and GPT-5.6 Luna ($0.20/$1.20 after the July 30 price cut) on both input and output.
Is Muse Spark 1.2 available in OpenCode?#
No. Muse Spark is closed-weights and available through Muse Code and the Meta Model API only. It is not in OpenCode at the time of writing.
What changed from Muse Spark 1.1?#
More training compute on coding tasks, expanded training-environment diversity, long-horizon coding training, a self-improvement dataset loop, and co-training with the Muse Code harness. Standard-tier pricing is unchanged from 1.1.
Sources#
| Source | URL |
|---|---|
| Meta AI Research announcement | https://research.meta.ai/blog/introducing-muse-code-and-muse-spark-1-2 |
| Muse Spark model and pricing page | https://developer.meta.com/ai/models/muse-spark/ |
| Muse Code product page | https://dev.meta.ai |
| Meta Model API docs | https://developer.meta.com/docs/model-api |
| Muse Spark 1.2 methodology report | https://research.meta.ai/static/muse-spark-1-2-methodology |
Last updated: August 6, 2026
Continue Reading#
- Meta Muse Spark 1.1 Developer Guide - the 1.1 launch, API setup, and the $20 free credits
- DeepSeek V4 Flash 0731: Benchmarks, Pricing, OpenCode Setup - the open-weight model the contributor tier undercuts
- OpenAI Cuts GPT-5.6 Luna 80%: Cost-Per-Task Math - the other price cut reshaping agent economics
- AI Coding Tools Pricing 2026 - where every major coding model's price stands
- Model Routing Recipes - how to route around 12x price deltas like this one
- How to Use Claude Code and Codex With Meta Muse: Every Setup That Actually Works - running Claude Code and Codex on Muse Spark 1.3 through the Meta Model API, from OpenCode Go, and inside Muse Code
- Muse Spark Open Weights: 816B Model, Benchmarks, and How to Run It - the open-weights release the 1.2 roadmap teased, now shipped
Get the next deep dive like this in your inbox
One email a week on AI Models and the rest of the AI dev stack. Free.
Read next on AI coding tools
Meta Muse Spark 1.1 Developer Guide: First Paid Meta API for Agentic Tasks
Meta Muse Spark 1.1 developer guide: Meta's first paid model API, with 1M-token context, OpenAI-compatible endpoints, pricing and setup for agentic tasks.
7 min readMeta Launches Muse Spark 1.1: A Closed-Weights Agentic Model with Aggressive Pricing
Meta Muse Spark 1.1 is Meta's first paid, closed-weights API model, with $1.25/M input tokens and 1M context. The pricing, benchmarks and HN debate.
5 min readDeepSeek V4 Flash 0731: The Official Release, Benchmarks, and How to Run It in OpenCode
DeepSeek V4 Flash 0731 is the official V4 Flash API release, re-post-trained to beat V4-Pro-Preview on agent benchmarks. How to run it in OpenCode today.
7 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.