The Agent Reliability Cliff: Why Your 10-Step Chain Only Succeeds 20% of the Time
AI Agents Deep Dive
10 parts- 1AI Agents Explained: A TypeScript Developer's Guide
- 2How to Build AI Agents in TypeScript
- 3Multi-Agent Systems: How to Orchestrate Multiple AI Agents in TypeScript
- 4The Agentic Development Tech Stack for 2026
- 5How to Debug AI Agent Workflows
- 6AI Agent Memory Patterns
- 7Over-Editing: Why Your AI Coding Agent Rewrites What Isn't Broken
- 8Intent Debt: The AI-Era Debt Nobody Is Tracking
- 97 AI Agent Orchestration Patterns Developers Should Know
- 10The Agent Reliability Cliff: Why Your 10-Step Chain Only Succeeds 20% of the TimeCurrent
TL;DR
The agent reliability cliff: 85% per-step success compounds to about 20% over 10 steps. Why long chains collapse, and six patterns that fight the decay.
Last updated: June 7, 2026
| Official Sources | |
|---|---|
| Anthropic Claude Documentation | Claude Code overview, agent patterns, and best practices |
| Anthropic API Pricing | Current model pricing including prompt caching discounts |
| OpenAI API Pricing | Model pricing and batch API discounts |
| Temporal Documentation | Durable execution and workflow orchestration |
| Inngest Documentation | Event-driven durable functions for agent pipelines |
| Redis Pub/Sub | Message queue patterns for agent state management |
The math nobody wants to do#
Your agent pipeline is a compound probability problem, and the compound destroys you faster than you think.
Assume a single agent step succeeds 85 percent of the time. That is a generous number. Real-world per-step reliability for non-trivial tasks is often closer to 80 percent. Now chain ten of those steps together. The end-to-end success rate is 0.85 to the tenth, which is roughly 20 percent.
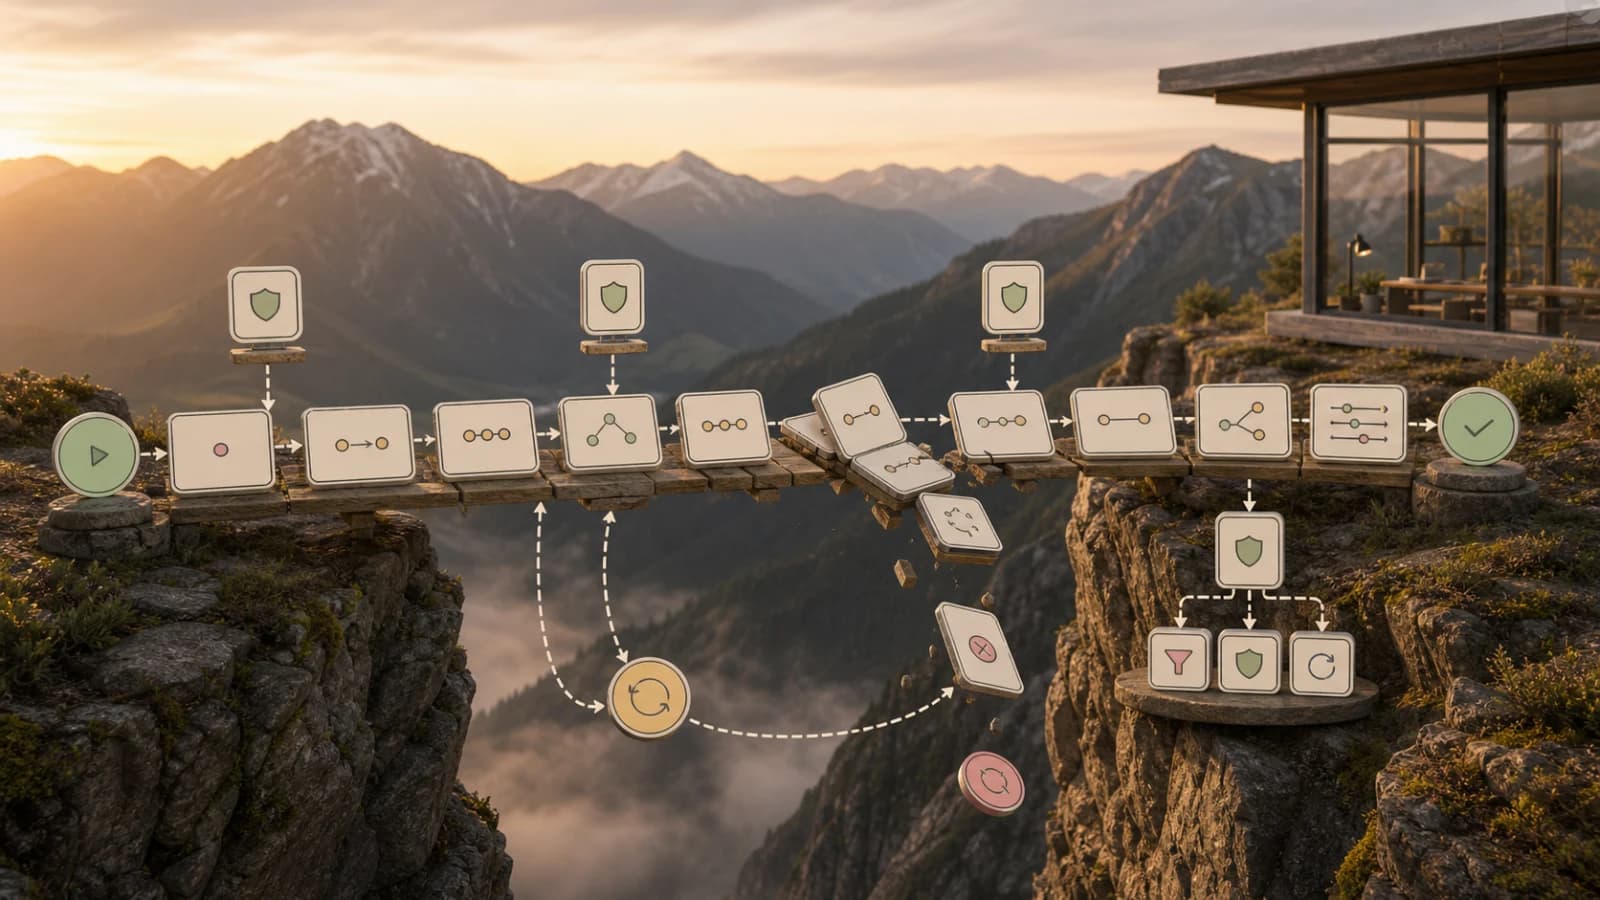
That is the agent reliability cliff. Five steps holds up decently at 44 percent end-to-end. Ten steps collapses to 20 percent. Twenty steps is effectively zero. This is not a tooling problem or a model problem. It is the arithmetic.
Everyone who has shipped a multi-agent pipeline has hit this wall. You prototype a five-step flow and the demo video looks amazing. You add five more steps for the production edge cases and suddenly four out of five runs fail partway through. You blame the model, or the prompt, or Anthropic having a bad day, and you cannot figure out why it worked yesterday and it does not work today. The answer is usually that it was never really working. Your demo was sampling the 20 percent of runs that happened to succeed end-to-end.
This post is a rough map of what the field has converged on to fight this. The patterns are not new, but they are finally common vocabulary in production agent work.
Why 85 percent is optimistic#
Per-step reliability is a moving target. Here is what affects it.
Task complexity. An agent that summarizes a paragraph succeeds above 95 percent. An agent that writes a bug fix to a real codebase succeeds in the 60-80 percent range depending on the specificity of the bug. An agent that has to decide whether to refactor or patch is rarely above 70 percent.
Context pressure. Agents that operate near their context window limit start truncating, hallucinating, and dropping instructions. A prompt that works at 10k tokens of context may fail at 100k tokens on the same task.
Tool use surface area. Every tool the agent can call is a place where the agent can call the wrong tool, pass the wrong arguments, or interpret the response incorrectly. More tools means more error modes.
Environment variance. The exact same prompt produces different outputs run to run. Temperature is usually non-zero. Even with temperature zero, provider-side fluctuations matter.
The practical implication: optimistic planners assume 90 percent per step and build 15-step pipelines. Realistic planners assume 80 percent per step and cap chains at five steps, with verification gates between them. The realistic planners are the ones whose agents ship.
The six patterns that actually work#
After two years of production agent work, six reliability patterns keep showing up. None of them are exotic. All of them are boring infrastructure-engineering instincts applied to agent pipelines.
1. Retry with backoff#
The baseline. If a step fails, retry it. Exponential backoff between retries to avoid hammering a flaky upstream. Cap at three or four retries, then escalate.
Retry only works for transient failures. A hallucination in agent output is not a transient failure. It is often a deterministic failure that will reproduce on retry. So retry is necessary but insufficient.
2. Self-healing loops#
The step produces output and also a verification pass. If verification fails, the step retries itself with the failure as context. This is the evaluator-optimizer loop in production.
The key is that the verification has to be executable. A test suite. A schema validator. A linter. A rubric evaluated by another LLM. If "verification" is the same LLM eye-balling its own output, you have not actually added verification. You have added self-congratulation.
This pattern works extraordinarily well for code generation. Generate, run the tests, loop if they fail, cap at three iterations. Empirically, a single retry on a test failure captures 60-70 percent of the cases where the first attempt was wrong.
3. Circuit breaker#
Underused. If the error rate from a specific sub-agent exceeds a threshold over a rolling window, stop routing work to it and alert. Prevents cascade failures where one broken agent drags the whole system down.
Circuit breakers are the pattern that lets you run the pipeline overnight without waking up to a $400 API bill from an infinite retry loop.
4. Checkpoint and resume#
Long-running agent work should save state after every major step. When a failure happens in step seven, you resume from the checkpoint before step seven, not from step one.
The state has to be external. Postgres, Redis, Convex, a flat JSON file. Anything but "in the agent's memory" because the agent's memory is what just failed.
Checkpointing changes the math. A 10-step chain with checkpoints and per-step retry is functionally a 10 x 2-step chain, which at 85 percent reliability is 72 percent end-to-end. Ten times more reliable than the same chain without checkpoints.
5. Early stopping#
Sometimes the right move is to stop and escalate rather than retry. If the agent has tried three approaches and all failed, the fourth will probably fail too. Stop. Surface the failure to a human or a different specialist agent.
Early stopping is a cost control as much as a reliability control. The failure mode without early stopping is $50 of tokens burned on an agent stuck in a confusion loop.
6. Human escalation#
The best agents know when to ask. The worst agents never ask. Every production pipeline needs a clear definition of the conditions under which the agent stops and requests human input rather than continuing to guess.
Common escalation triggers: the agent has made the same kind of mistake twice. The agent's confidence (if you can measure it) drops below a threshold. The next action crosses a blast-radius line the agent is not authorized to cross alone.
State management, briefly#
The reliability patterns above assume agents are stateless and state lives somewhere durable. This is the production winner and the debate is mostly over.
Agents load their state at the start of a run and save it at the end. Benefits: resumability, full auditability, parallel execution without race conditions, the ability to run the same agent on the same state from two different machines without corruption.
Message queue architectures (Redis Pub/Sub, SQS, Kafka) decouple agents for high-volume workloads. They are overkill for most agent pipelines, but if your workload spikes or needs durable semantics, Temporal or Inngest are the two orchestrators most agent teams pick.
Cost as the other side of reliability#
Cost optimization and reliability are tied. A pipeline that costs $0.10 per run can tolerate 20 percent success rates if retries are free. A pipeline that costs $5 per run cannot.
The three cost levers that matter in production:
Model tier routing. Use the cheapest model that can handle each sub-task. Tiny models for routing and classification. Medium models for worker tasks. Large models only for planning and synthesis. A Claude Opus orchestrator with Haiku workers can cut costs by an order of magnitude versus using Opus throughout, with minimal quality loss on the worker side.
Prompt caching. Anthropic and OpenAI both support prompt caching. System prompts and tool definitions repeated across thousands of agent calls should hit 70 percent-plus cache rates. At current pricing that is a 60-90 percent cost reduction on cached tokens. If you are not using prompt caching in production, you are leaving money on the table.
Batch API. Both Anthropic and OpenAI offer 50 percent discounts for async batch jobs with 24-hour windows. Most agent pipelines have at least some batchable work: nightly report generation, bulk document analysis, overnight data enrichment. Run the non-urgent parts of your pipeline through the batch API and cut that cost line in half.
The practical shape#
Put the whole picture together and a reliable production agent pipeline looks like this.
Five steps or fewer in any single chain. Each step has executable verification. Each step is checkpointed to durable state. Retries are bounded with exponential backoff. Circuit breakers guard expensive sub-agents. Unrecoverable failures escalate to a human via a defined trigger. The cheapest sufficient model runs each step. Prompt caching hits 70 percent-plus. Batch API absorbs anything that does not need to run now.
That is not exciting. It is plumbing. But it is plumbing that ships, and plumbing that does not ship is why 80 percent of demo agent pipelines never make it to production.
Where this goes next#
The field is converging on two answers to the reliability cliff.
The first is "smaller, better-scoped steps." If you cannot make a single step 95 percent reliable, break it into two steps that are each 97 percent reliable and run them with verification between.
The second is "specialized sub-models fine-tuned for narrow tasks." A sub-model trained specifically to produce JSON that passes a schema check is more reliable than a general model asked to produce JSON and hope. This is where agent-specialized fine-tuning is headed over the next eighteen months.
In the meantime, the boring answer is the right answer. Shorter chains. Executable verification. Durable state. Bounded retries. Circuit breakers. Escalation paths. Cheapest sufficient model. Caching. Batching.
Agent reliability is an infrastructure problem. Most of what looks like AI is just good plumbing.
FAQ#
What is the agent reliability cliff?#
The agent reliability cliff describes how per-step success rates compound exponentially across multi-step agent pipelines. If each step succeeds 85% of the time, a 10-step chain only succeeds about 20% end-to-end (0.85^10). The math is brutal: 5 steps holds at 44% success, 10 steps drops to 20%, and 20 steps is effectively zero. Most failed agent projects hit this wall without understanding the compound probability math.
Why do my agent demos work but production fails?#
Demo videos sample the runs that happened to succeed. A 10-step pipeline with 20% end-to-end success means four out of five runs fail partway through. In a demo, you re-record until you get a good run. In production, users see every failure. The pipeline was never really working - the demo was just statistical cherry-picking.
How do I improve agent pipeline reliability in production?#
The six patterns that work: (1) Retry with exponential backoff for transient failures, (2) Self-healing loops with executable verification (tests, schema validators, linters), (3) Circuit breakers to stop cascade failures, (4) Checkpoint and resume to avoid restarting from scratch, (5) Early stopping after repeated failures, and (6) Human escalation when the agent should ask rather than guess. None are exotic - they are boring infrastructure engineering applied to agent pipelines.
What is executable verification for agents?#
Verification that runs code, not vibes. A test suite that passes or fails. A JSON schema validator. A linter. A rubric evaluated by a separate LLM. If verification is the same LLM reviewing its own output, that is not verification - it is self-congratulation. Executable verification is what makes self-healing loops actually heal.
How do circuit breakers help agent reliability?#
Circuit breakers stop routing work to a sub-agent when its error rate exceeds a threshold over a rolling window. They prevent cascade failures where one broken agent drags the whole system down. More importantly, they prevent the $400 overnight API bill from an infinite retry loop. If you run agent pipelines unattended, circuit breakers are mandatory.
How does checkpointing improve agent pipeline success rates?#
Checkpointing changes the math. A 10-step chain with checkpoints and per-step retry is functionally a series of 2-step chains (step + retry). At 85% reliability, that is 72% end-to-end instead of 20%. The key: state must be external (Postgres, Redis, Convex, flat file), not in the agent's memory, because the agent's memory is what just failed.
What is the optimal number of steps in an agent chain?#
Realistic planners cap chains at 5 steps with verification gates between them. At 80% per-step reliability, 5 steps gives 33% end-to-end success. 10 steps gives 11%. Optimistic planners assume 90% and build 15-step pipelines that never ship. If you need more than 5 steps, add checkpoints and treat it as multiple 5-step chains with durable state handoffs.
How do I reduce AI agent pipeline costs while maintaining reliability?#
Three levers: (1) Model tier routing - use tiny models for classification, medium models for workers, and large models only for planning. Claude Opus orchestrator + Haiku workers cuts costs 10x. (2) Prompt caching - system prompts and tool definitions should hit 70%+ cache rates for 60-90% cost reduction. (3) Batch API - 50% discount for async jobs. Cost and reliability are tied: a $0.10 pipeline can tolerate 20% success; a $5 pipeline cannot.
Further reading#
- 7 AI Agent Orchestration Patterns Every Developer Should Know
- Over-Editing: Why Your AI Agent Rewrites What Isn't Broken
- Building Multi-Agent Workflows with Claude Code
Sources#
Get the next deep dive like this in your inbox
One email a week on AI Agents and the rest of the AI dev stack. Free.
Read next on AI coding tools
7 AI Agent Orchestration Patterns Developers Should Know
Seven AI agent orchestration patterns for production, from single-agent baselines to multi-level hierarchies, each with a decision rule, sketch and tradeoffs.
10 min readOver-Editing: Why Your AI Coding Agent Rewrites What Isn't Broken
Over-editing is when AI coding agents make huge diffs for tiny fixes. Why models do it, why tests miss it, and how to keep agent edits minimal.
9 min readBuilding Multi-Agent Workflows in Claude Code: A Practical Tutorial
Multi-agent workflows in Claude Code: use the Task tool, custom sub-agents and worktrees to run parallel development, with real prompts and agent configs.
11 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.