Topic
API
All blog posts, tools, and guides about API from Developers Digest.
30 resources - 24 posts, 5 tools, 1 guide
Blog Posts
View in blog →
How to Cut Your LLM API Bill in 2026: Prompt Caching, Batch and Flex Tiers Compared Across 15 Providers
Caching a shared prompt cut our worked example by about 78-80% on four models; batch takes 50% off at most providers but 40% at Moonshot and 20% at xAI. Only Anthropic, Fireworks and xAI say the two stack. The math, the assumptions and the quotes.
12 min read
Which AI APIs Train on Your Data? Free Tiers, Paid APIs and Retention, Checked Against 18 Providers' Own Terms (October 2026)
Free tiers are where training happens: Google's unpaid quota outside the EEA, Switzerland and the UK, Mistral's Free mode, and some OpenRouter free models. Paid APIs mostly say no. Retention is a separate question, and four providers' own docs disagree with themselves.
14 min read
Claude Fable 5.1 and Mythos 5.1: The Developer Migration Guide
Claude Fable 5.1 keeps $10/$50 pricing but cuts cache reads to $0.25/MTok. The three breaking API changes, new betas, and when Opus 5.5 is enough.
16 min read
GPT Image 2.5 Sunburst and Flare: How to Use OpenAI's New Models
GPT Image 2.5 Sunburst and Flare add xhigh and max quality at GPT Image 2 token rates. Model IDs, type-checked code, costs and when to pick each.
10 min read
Migrate Off whisper-1 and gpt-4o-transcribe Before Feb 26, 2027
OpenAI shuts down whisper-1 and the gpt-4o transcribe models on Feb 26, 2027. Move files to gpt-transcribe ($0.0045/min) and live audio to gpt-live-transcribe.
16 min read
Run Your Coding Agent as an API: OpenCode Server on Railway
OpenCode server on Railway: run opencode serve in a container as a password-protected HTTP API with a persistent volume, reachable from any machine or webhook.
11 min read
Automate Video Editing with the Descript API: Raw Recording to Published Cut in One Script
Automate video editing with the Descript API: one script takes a raw recording to a cleaned, captioned, published cut without opening the editor.
11 min read
GitHub Apps Can Now Be Installed at the Enterprise Level, Opening the Platform to Third-Party Integrators
GitHub Apps can now be installed at the enterprise level, opening enterprise management to third-party integrators, with a security boundary on top permissions.
6 min read
AI Session Portability Compared 2026: OpenAI vs Anthropic vs Gemini
AI session portability compared across OpenAI, Anthropic, and Gemini: storage defaults, encrypted reasoning, compaction, and what you can move or audit.
11 min read
GitHub Models Is Retired: What to Use for Model Access Now
GitHub Models is retired as of July 30, 2026 - the playground, inference API and BYOK are gone. The shutdown timeline and where to get model access now.
6 min read
The Underground Relay Market for AI API Tokens: How Resellers Get 97% Off
AI API token relays resell OpenAI, Anthropic, and Google access at up to 97.8% off. How the gray market works and what it means for developers on AI APIs.
9 min read
Meta Muse Spark 1.1 Developer Guide: First Paid Meta API for Agentic Tasks
Meta Muse Spark 1.1 developer guide: Meta's first paid model API, with 1M-token context, OpenAI-compatible endpoints, pricing and setup for agentic tasks.
7 min read
Gemini 3.5 Pro Developer Guide: 2M Context Window and Deep Think Mode
Google's Gemini 3.5 Pro arrives with a 2-million-token context window and Deep Think reasoning mode. Here is how to access it, what it costs, and when the massive context actually helps.
8 min read
OpenAI's June API Updates Are Really a Control-Plane Upgrade
OpenAI June 2026 API updates as an agent control plane: workload identity, Admin APIs, Secure MCP Tunnel, moderation scores, billing and cache retention.
8 min read
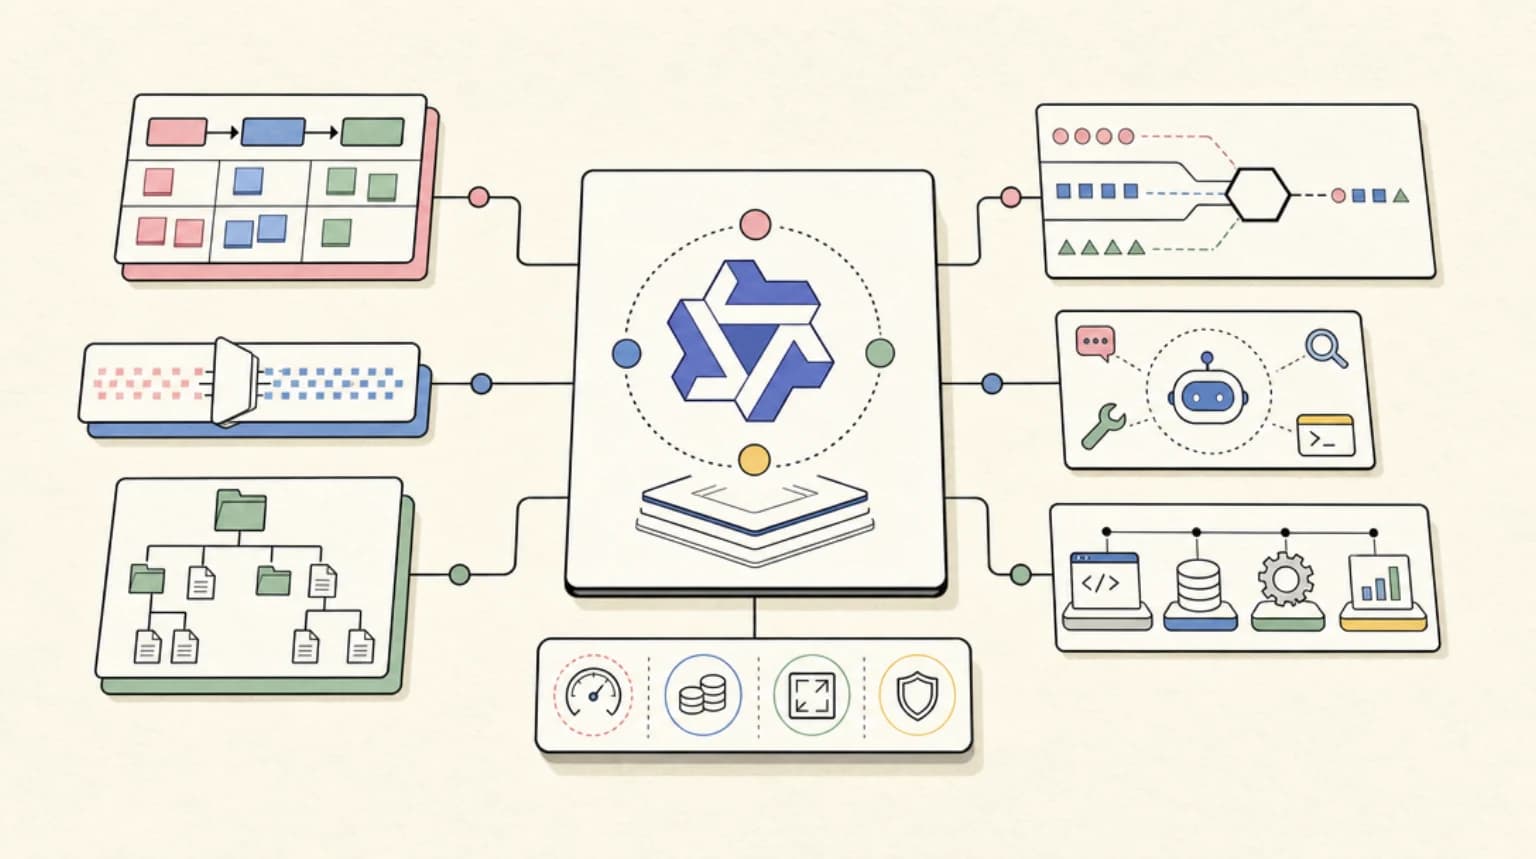
Qwen 3.7 Max Developer Guide: 1M Context, $1.25/MTok, and Agent-First Architecture
Qwen 3.7 Max developer guide: the 1M token context window, pricing, Anthropic and OpenAI-compatible API, benchmarks, and when to pick it over Claude or GPT.
8 min read
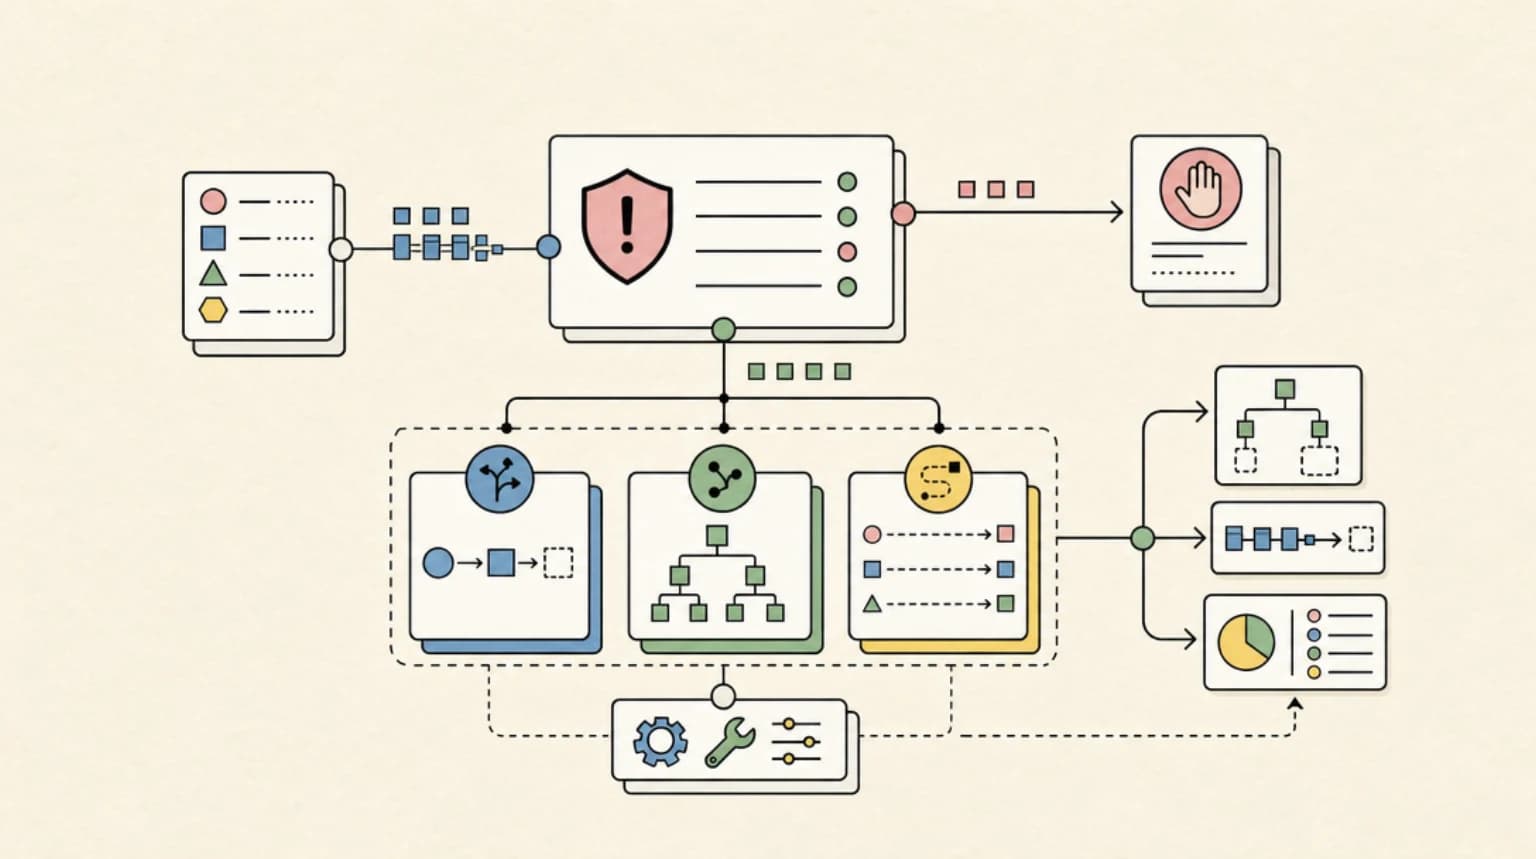
Handling Fable 5 Refusals: A Working Guide to the Fallback API
Handle Claude Fable 5 refusals with the fallback API: what a refusal looks like on the wire, three ways to handle it with code, and the billing rules.
10 min read
Fable 5 Broke Enterprise ZDR Agreements: What Dev Teams Must Do Now
Claude Fable 5 mandates 30-day data retention on every platform, overriding Zero Data Retention contracts. What compliance teams should audit before deploying.
8 min read
Fable 5 Before June 22: The Decision Checklist for Every Plan Tier
Fable 5 June 22 decision checklist for Pro, Max, Teams and API users: what to decide and test before the window closes, and when Opus 4.8 is the right call.
9 min read
Why Fable 5 Refuses Your Cybersecurity Queries (And How the Fallback Works)
Why Claude Fable 5 refuses cybersecurity, bio and distillation queries, how it falls back to Opus 4.8, and what API developers must configure first.
8 min read
Migrating to Claude Fable 5: The Practical Guide
Migrating to Claude Fable 5 from Opus 4.8 or older models - every breaking change, what to delete from your code, and the prompt audit to run before switching.
9 min read
OpenRouter in 2026: Review, Setup, and When Model Routing Pays
OpenRouter review and setup - one API key for 300+ models with fallbacks and provider routing, what it costs, and when to go direct to a provider instead.
8 min read
DeepSeek V4: The Developer's Guide to Flash and Pro
DeepSeek V4 developer guide: Flash vs Pro, pricing, OpenAI SDK setup with thinking mode and tool calling, and when to pick V4 over Claude or GPT.
10 min read
Mercury 2 Developer Guide: Building With a Diffusion LLM in Production
Mercury 2 developer guide: the OpenAI-compatible API, tool use, structured outputs, reasoning levels, and when a diffusion LLM beats an autoregressive one.
10 min read
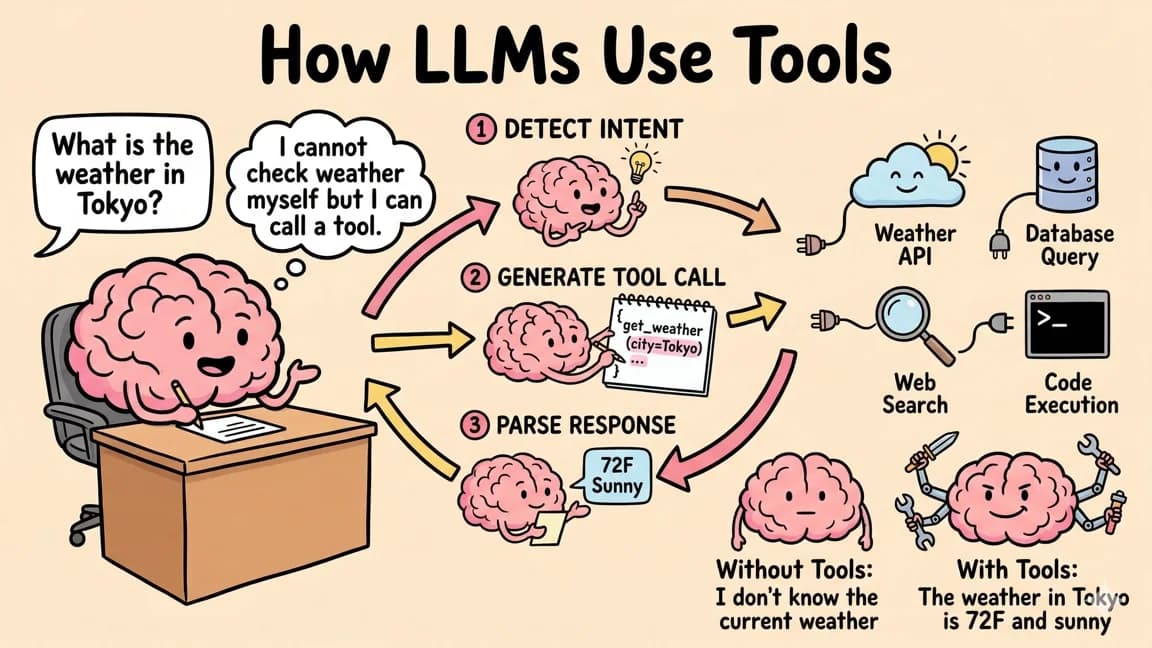
Assistants to Responses API: A Migration Field Guide
Migrate from the OpenAI Assistants API to the Responses API: a tested plan covering code, state, threads, tool-use parity, and an eval-gated cutover.
13 min read
Related Tools
All tools →OpenRouter
Unified API for hundreds of models. One API key, one billing dashboard. OpenAI, Anthropic, Google, Meta, Mistral, and more. Automatic fallbacks and load balancing.
AI ModelsReplicate
Run 50,000+ ML models with a simple API. No infrastructure management. Pay-per-second billing. Deploy custom models with Cog. Popular for image generation and audio.
InfrastructureTogether AI
Fastest inference for open-source models. 200+ models via unified API. Ranks #1 on speed benchmarks for DeepSeek, Qwen, Kimi, and Llama. Serverless pay-per-token pricing.
InfrastructureGroq
LPU-powered inference at about 500 to 1,000 tokens/sec on GPT OSS models. Purpose-built chip with on-chip SRAM instead of HBM. OpenAI-compatible API. Free tier available.
InfrastructureCerebras
Wafer-scale AI inference at 3,000+ tokens/sec. The WSE-3 chip has 4 trillion transistors and 900K AI cores. 20x faster than GPU providers. OpenAI partnership for inference.
InfrastructureKeep exploring
More on API
- - OpenRouter - recommended API tool from the Developers Digest directory
- - Compare Tools - dive deeper across the Developers Digest knowledge base
- - All API articles in the blog archive
- - Developers Digest on YouTube - video tutorials covering API and more

Get Smarter About AI Dev
New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
One email per weekReal code, not theoryFree forever
Explore 844 topics
Browse All Topics