Claude API Reliability: Error Handling Best Practices
TL;DR
Claude API error handling for production: retry shapes, backoff with jitter, circuit breakers, fallback chains, and the observability to debug failures at 3am.
Last updated: October 18, 2026
Updated October 18, 2026: Two bugs in the retry sample are fixed. In @anthropic-ai/sdk, APIConnectionError and its timeout subclass extend APIError with no status, so the old isRetryable returned false for network failures before it reached the connection checks; it now tests for connection errors first. err.headers is a Headers object, so retry-after is read with .get() instead of bracket indexing, which always returned undefined. The sample also turns off the SDK's own retries (two by default, per Anthropic's errors docs) so attempts do not multiply, stops on a 429 with no retry-after (the documented spend-cap case), and the error list now includes 529 overloaded_error.
Official Sources#
| Resource | What it covers |
|---|---|
| Claude API errors | Status codes, error types, SDK retry defaults, request IDs |
| Anthropic Rate Limits | Token and request limits, rate limit headers, usage tiers |
| Anthropic SDK Reference (TypeScript) | Official SDK documentation with retry configuration |
| Messages API | Request format, streaming, timeout configuration |
| Anthropic Pricing | Token costs for budgeting and cost monitoring |
The reason your Claude app falls over#
Most production incidents I have seen with Claude integrations are not about the model. They are about the network between you and the model.
For broader context, pair this with What Is Claude Code? The Complete Guide for 2026 and 60 Claude Code Tips and Tricks for Power Users; those companion pieces show where this fits in the wider AI developer workflow.
Rate limits. Timeouts. Transient 5xx. The occasional auth blip when an API key gets rotated and not propagated. None of these are interesting bugs. All of them will take your app down if you don't have the defensive layer in place.
The good news: the defensive layer is small. Maybe 200 lines of code. Once it is in, your reliability story flips from "depends on whether Anthropic had a good day" to "depends on whether you wrote your retry loop correctly," which is a much better problem to have.
This post is the playbook. Error categorization, retry shape, rate limit handling, fallback strategy, and the monitoring you need to know any of it is working.
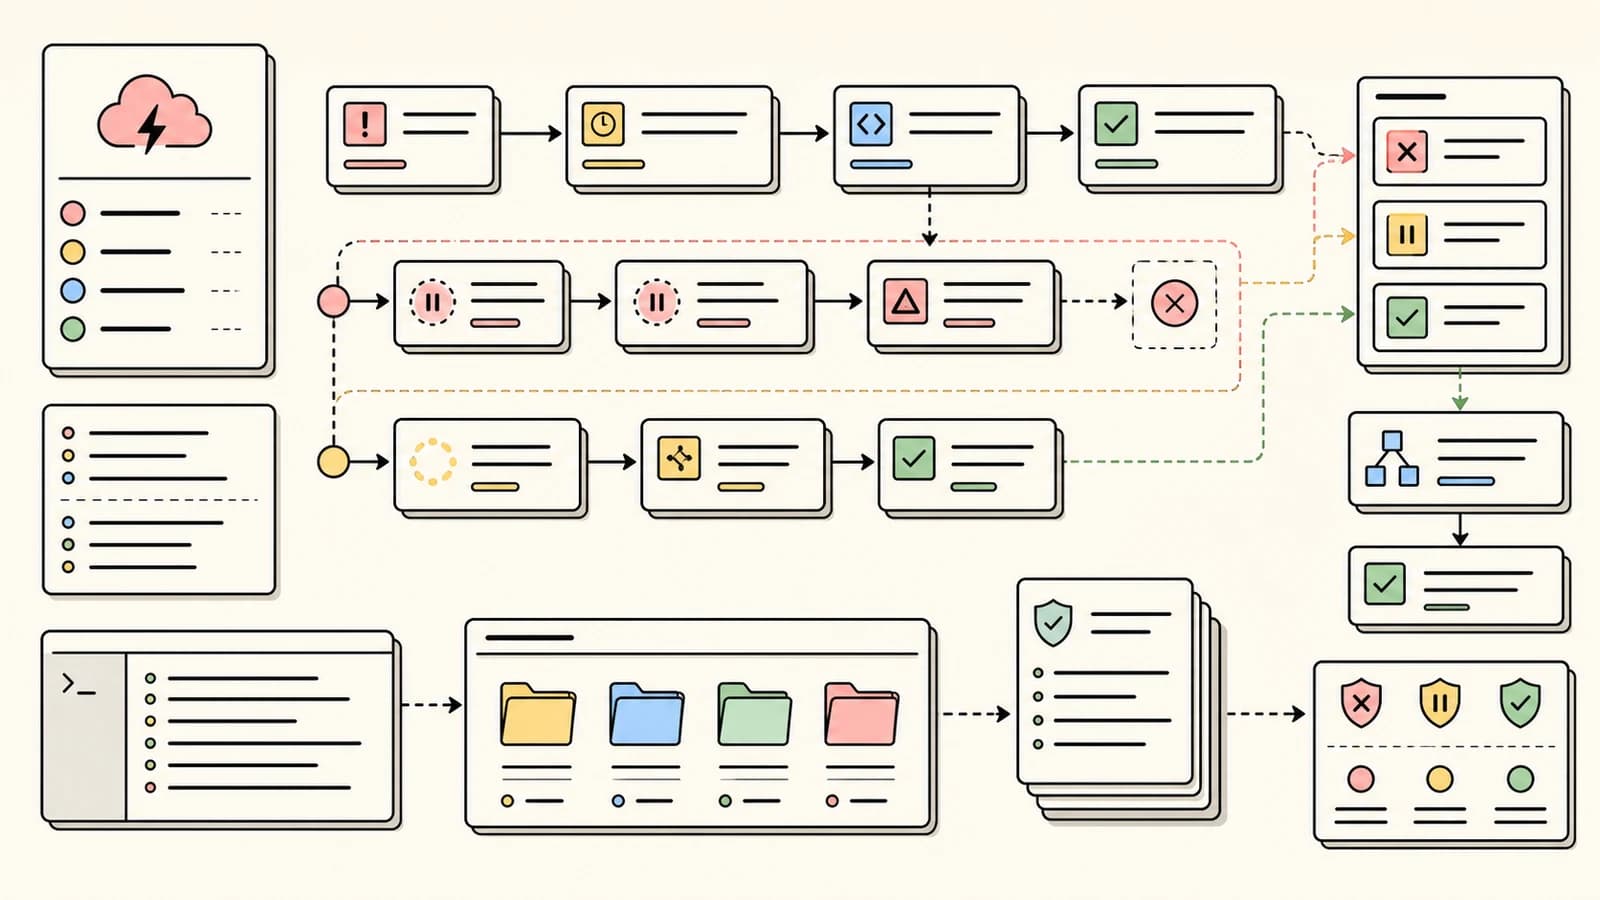
The five error categories that matter#
Anthropic returns standard HTTP status codes plus a structured error body. The five buckets:
400 - bad request. Invalid JSON, malformed message structure, schema violation on tool input. Permanent. Do not retry. Log the request body and fix the call site. The error message in the response body usually points directly at the problem.
401 - authentication. API key is missing, wrong, or revoked. Permanent for this request. Do not retry. Alert immediately - this means your secrets pipeline is broken.
429 - rate limit. Usually transient. Retry with exponential backoff. Anthropic returns a retry-after header on rate limit responses. Respect it. Don't guess. The exception: a 429 for reaching your usage tier's monthly spend cap has no retry-after header and keeps failing until access resumes, so do not retry that one.
500, 504 and 529 - server errors. Transient. Retry with backoff. A 500 is api_error, a 529 is overloaded_error (the API is temporarily overloaded), and a 504 is timeout_error, a timeout while processing. For long generations Anthropic recommends the streaming Messages API rather than retrying the same non-streaming call. 502 and 503 from a proxy or load balancer in your path deserve the same retry treatment.
Network errors. ECONNRESET, ETIMEDOUT, DNS failures, TLS handshake failures. Transient. Retry with backoff. These are not from Anthropic, they are from the path between you and them.
For the full list of status codes and error types across Anthropic, OpenAI, Gemini, Bedrock and eight other model APIs, each with its documented fix and whether the docs say to retry, see our AI API error reference. For the cross-provider retry rules, including the Anthropic spend-cap 429 that must never be retried, see AI API 429, 529 and 503 errors: retry rules that match the docs.
The Anthropic SDK exposes these as typed errors, which makes the dispatch clean.
import Anthropic from "@anthropic-ai/sdk";

// The SDK retries transient errors twice by default. Turn that off when the
// wrapper below is your retry layer, or the attempts multiply.
const client = new Anthropic({ maxRetries: 0 });

function isRetryable(err: unknown): boolean {
  // APIConnectionError (and APIConnectionTimeoutError, its subclass) extends
  // APIError with no status, so test for it before the status checks.
  if (err instanceof Anthropic.APIConnectionError) return true;
  if (err instanceof Anthropic.APIError) {
    if (err.status === 429) return true;
    if (err.status && err.status >= 500) return true; // 500, 504, 529
    return false;
  }
  return false;
}
The SDK wraps network failures (resets, DNS, TLS, timeouts) in APIConnectionError and APIConnectionTimeoutError, so you do not need to catch raw fetch errors. One case the status codes do not cover: on a streaming request, an error can arrive as an SSE error event after the API has already returned 200, so handle mid-stream errors in your stream consumer too.
Retry with exponential backoff and jitter#
The naive retry is "wait one second, try again, wait two, try again." This works for one client. With a hundred concurrent clients all retrying on the same wall-clock schedule, you get a thundering herd that takes the upstream down a second time the moment it recovers.
The fix is jitter. Add random noise to the backoff so retries spread out instead of stacking. Full jitter (random between zero and the cap) is the safest variant.
async function sleep(ms: number) {
  return new Promise((r) => setTimeout(r, ms));
}

function backoffMs(attempt: number, base = 500, cap = 30_000): number {
  const exp = Math.min(cap, base * 2 ** attempt);
  return Math.floor(Math.random() * exp);
}

async function withRetry<T>(
  fn: () => Promise<T>,
  options: { maxAttempts?: number; onRetry?: (attempt: number, err: unknown) => void } = {}
): Promise<T> {
  const maxAttempts = options.maxAttempts ?? 5;
  let lastErr: unknown;

  for (let attempt = 0; attempt < maxAttempts; attempt++) {
    try {
      return await fn();
    } catch (err) {
      lastErr = err;
      if (!isRetryable(err) || attempt === maxAttempts - 1) throw err;

      let delay = backoffMs(attempt);
      if (err instanceof Anthropic.APIError && err.status === 429) {
        // err.headers is a Headers object: use .get(), not bracket indexing.
        const retryAfter = err.headers?.get("retry-after");
        // A spend-cap 429 has no retry-after and keeps failing: stop here.
        if (!retryAfter) throw err;
        delay = Math.max(delay, Number(retryAfter) * 1000);
      }

      options.onRetry?.(attempt, err);
      await sleep(delay);
    }
  }

  throw lastErr;
}

const response = await withRetry(() =>
  client.messages.create({
    model: "claude-sonnet-4-5",
    max_tokens: 1024,
    messages: [{ role: "user", content: "Hello" }],
  })
);
A few things worth noting. The retry-after header takes precedence over the calculated backoff because Anthropic knows better than you do when to come back. The onRetry callback is where you push metrics - don't skip it. The max-attempts cap is at five because beyond that you are throwing good money after bad, and the human at the other end of your API has been waiting too long anyway.
Note that the official Anthropic SDKs already retry connection errors, rate limits and 5xx responses with exponential backoff, twice by default, honoring retry-after. You can configure this with maxRetries on the client. The wrapper above is for the cases where you want explicit control - logging every retry, custom backoff shape, integration with a circuit breaker - which is why it sets maxRetries: 0. Keep one retry layer, not two.
If you use the Python SDK, note that 1.0 moved its HTTP layer to httpx2: err.response is now an httpx2.Response, so isinstance checks and annotations that name httpx types need updating. Our Anthropic Python SDK 1.0 migration guide has the full list. The newer SDK majors (Python 2.0, TypeScript 1.0) also change how the API key is sent; see the 2026-10-21 migration if a gateway starts returning 401s.
Circuit breakers stop the bleeding#
When Anthropic is having a real outage (rare, but it happens), retrying is counterproductive. You burn budget on doomed requests and prevent your app from falling back to a degraded mode that might actually serve users.
Circuit breakers solve this. Track recent failure rate. When it crosses a threshold, open the breaker - skip the upstream entirely and short-circuit to a fallback. Periodically try one request to see if upstream is back. Close the breaker when it recovers.
type BreakerState = "closed" | "open" | "half-open";

class CircuitBreaker {
  private state: BreakerState = "closed";
  private failures = 0;
  private openedAt = 0;

  constructor(
    private threshold = 5,
    private resetMs = 30_000
  ) {}

  async run<T>(fn: () => Promise<T>): Promise<T> {
    if (this.state === "open") {
      if (Date.now() - this.openedAt > this.resetMs) this.state = "half-open";
      else throw new Error("circuit open");
    }

    try {
      const result = await fn();
      if (this.state === "half-open") {
        this.state = "closed";
        this.failures = 0;
      }
      return result;
    } catch (err) {
      this.failures++;
      if (this.failures >= this.threshold) {
        this.state = "open";
        this.openedAt = Date.now();
      }
      throw err;
    }
  }
}

const breaker = new CircuitBreaker();

async function callClaude(input: string) {
  return breaker.run(() =>
    withRetry(() =>
      client.messages.create({
        model: "claude-sonnet-4-5",
        max_tokens: 1024,
        messages: [{ role: "user", content: input }],
      })
    )
  );
}
Tune the threshold to your traffic. For an app doing 1000 RPM, a threshold of 5 fires too eagerly on a normal 1 percent failure rate. For an app doing 10 RPM, a threshold of 50 takes 5 minutes to detect a real outage. A rolling-window failure rate (e.g. open if 50 percent of the last 20 requests failed) is more robust than absolute counts.
Rate limits: prevent before retry#
Retrying 429s is fine. Not hitting them is better.
Anthropic rate limits are organization-wide and measured in input tokens per minute, output tokens per minute, and requests per minute. The exact numbers depend on your usage tier. The mistake teams make is assuming the rate limit applies per-key or per-host - it does not.
Three patterns to stay under the limit.
Token bucket on your side. Estimate the input + output tokens for each call. Refill the bucket at your tier's rate. Block (or queue) when the bucket is empty. This is the single best rate limit prevention pattern.
Spread bursts. If you have 100 agent runs to launch, don't fire them all at once. Stagger over 60 seconds. Same total throughput, none of the burst pain.
Watch the headers. Anthropic returns anthropic-ratelimit-requests-remaining and similar headers on every response. When remaining drops below 10 percent of your limit, slow down. The headers are the only honest source of truth.
class TokenBucket {
  private tokens: number;
  private lastRefill = Date.now();

  constructor(private capacity: number, private refillPerMs: number) {
    this.tokens = capacity;
  }

  async take(amount: number): Promise<void> {
    while (true) {
      this.refill();
      if (this.tokens >= amount) {
        this.tokens -= amount;
        return;
      }
      const needed = amount - this.tokens;
      const waitMs = Math.ceil(needed / this.refillPerMs);
      await sleep(waitMs);
    }
  }

  private refill() {
    const now = Date.now();
    const delta = (now - this.lastRefill) * this.refillPerMs;
    this.tokens = Math.min(this.capacity, this.tokens + delta);
    this.lastRefill = now;
  }
}
Timeouts: pick a number and enforce it#
Default SDK timeout is 10 minutes. That is too long for almost every production use case. Pick a real number based on your UX budget.
Interactive chat: 30 seconds total, but stream so the user sees tokens at 1s. If generation hasn't finished by 30s, cancel.
Agent step: 60-90 seconds. Long enough for a slow tool result to come back. Short enough that a stuck agent doesn't burn budget for an hour.
Batch job: whatever your batch SLA allows, but always finite.
const response = await client.messages.create(
  {
    model: "claude-sonnet-4-5",
    max_tokens: 1024,
    messages: [{ role: "user", content: "Hello" }],
  },
  { timeout: 30_000 }
);
For streaming requests, time-to-first-token and total-time are different timeouts. Time-to-first-token should be 5-10s. Total time depends on how long an answer you want.
Fallback strategies#
When Claude is down or slow or rate-limited and you cannot wait, the question is what to do instead. Options in increasing order of "effort to set up":
Cached response. If the same question was asked recently, return the prior answer with a "cached" badge. Free, fast, sometimes wrong.
A smaller model. Fall back from Sonnet to Haiku. Lower quality, much higher availability headroom, lower cost. For a lot of use cases the user won't notice. Claude Code ships this pattern as --fallback-model, alongside retry settings for unattended runs; see the Claude Code retry watchdog guide.
A different provider. Have a parallel path through OpenAI or Google. Triggered only when the breaker is open. Be honest with yourself about what fraction of your prompts are portable - tool use schemas, prompt caching, and extended thinking will not transfer cleanly.
A static degraded UX. Show "AI is temporarily unavailable, here are some prewritten resources." Last resort. Better than a blank page.
The right choice depends on the business cost of latency versus the business cost of a wrong answer. For a customer support chatbot, cached or smaller-model is usually better. For a financial advisor, static degraded is better.
Observability: you can't fix what you can't see#
The reliability work above does nothing if you don't know when it fires. Five metrics, every Claude call.
Latency p50, p95, p99. Error rate by status code. Tokens in, tokens out, cost per call. Cache hit rate (if you are using prompt caching). Retry count distribution.
Log structured. Every call gets request_id, status, latency, tokens, retries, model. The Anthropic response headers give you a request ID that is what their support team will ask for if you file a ticket. Save it.
We run all of this on agent-finops for cost and rate-limit visibility, and replay the actual prompt/response pairs through tracetrail when something looks weird. The combination is the difference between "we had an incident yesterday" and "we know exactly what happened, here is the fix."
If you want to see the full reliability stack assembled in a working app, the DevDigest YouTube channel walks through the wrapper, the breaker, and the dashboards on a real service. The patterns are not exotic. The discipline of actually shipping them is what separates the apps that stay up from the ones that don't.
Frequently Asked Questions#
What is the best retry strategy for Claude API errors?#
Use exponential backoff with jitter. Start with a base delay of 500ms, double it on each retry up to a cap of 30 seconds, and add random noise (full jitter) to prevent thundering herd problems when many clients retry simultaneously. Respect the retry-after header on 429 responses. Limit to 5 retry attempts maximum - beyond that, the request is unlikely to succeed and the user has waited too long.
Which Claude API errors should I retry?#
Retry transient errors only: 429 (rate limit, except the spend-cap 429 that has no retry-after header), 500, 504 and 529 (server errors and overload), and network errors, which the SDK surfaces as APIConnectionError. Never retry permanent errors like 400 (bad request) or 401 (authentication) - these indicate bugs in your code or configuration that won't be fixed by retrying. The Anthropic SDK exposes typed error classes that make this classification straightforward; check APIConnectionError before APIError, because it is a subclass.
How do I handle Claude API rate limits in production?#
Implement a client-side token bucket that estimates input/output tokens per call and blocks when empty. Watch the anthropic-ratelimit-requests-remaining header on every response and slow down when below 10% of your limit. Spread burst workloads over time instead of firing all requests at once. Remember that rate limits are organization-wide, not per API key or per host.
What timeout should I set for Claude API requests?#
Pick based on UX budget, not defaults. The SDK default of 10 minutes is too long for production. Use 30 seconds for interactive chat (stream to show progress), 60-90 seconds for agent steps, and finite SLA-based limits for batch jobs. For streaming requests, set separate time-to-first-token (5-10s) and total-time limits.
When should I use a circuit breaker with Claude?#
Use a circuit breaker when Anthropic is having a real outage to prevent wasting budget on doomed requests. Track recent failure rate and open the breaker when it crosses a threshold (e.g., 50% of last 20 requests failed). When open, skip upstream calls and fall back to cached responses, a smaller model like Haiku, or a static degraded UX. Periodically try one request to detect recovery.
What fallback strategies work when Claude is unavailable?#
From easiest to hardest: return cached responses from recent identical queries with a "cached" badge; fall back to a smaller model like Haiku (lower quality but higher availability); route to a different provider like OpenAI (but tool schemas and prompt caching won't transfer); or show a static "AI temporarily unavailable" page. Choice depends on business cost of latency vs wrong answers.
What metrics should I track for Claude API reliability?#
Track five metrics on every call: latency (p50, p95, p99), error rate by status code, tokens in/out and cost, cache hit rate if using prompt caching, and retry count distribution. Log structured JSON with request_id (from Anthropic response headers), status, latency, tokens, retries, and model for every request. The request_id is what Anthropic support needs for debugging.
Does the Anthropic SDK handle retries automatically?#
Yes. Per Anthropic's errors docs, the official SDKs retry connection errors, rate limits and 5xx responses with exponential backoff, twice by default, honoring the retry-after header. Configure it with the maxRetries option on the client. If you add your own retry wrapper for logging, custom backoff or a circuit breaker, set maxRetries: 0 so the two layers do not multiply attempts.
Reliability is not a feature you add at the end. It is the layer underneath every Claude call from request one. Build it once, build it right, and the model failures stop being your problem.
Continue Reading#
- Claude - the model family, pricing, and rate limits on one page
- Claude Agent SDK - pricing, features, and alternatives on one page
Get the next comparison like this in your inbox
One email a week on Claude and the rest of the AI dev stack. Free.
Read next on Claude Code
The Agent Reliability Cliff: Why Your 10-Step Chain Only Succeeds 20% of the Time
The agent reliability cliff: 85% per-step success compounds to about 20% over 10 steps. Why long chains collapse, and six patterns that fight the decay.
9 min readAgent Architecture: Building Multi-Step AI Workflows That Survive Production
Agent architecture for multi-step Claude workflows: loop patterns, state management, error recovery, and the production gotchas that break agents at scale.
11 min readRAG with Claude: Add Context Without Retraining
RAG with Claude in production: structure-aware chunking, hybrid retrieval, citation tracking, and the prompt caching trick that makes RAG cheap enough to ship.
10 min readTechnical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.