Factory Router, Explained: How Automatic Model Routing Cuts Coding-Agent Spend 20-25%
TL;DR
Factory Router explained: automatic model routing and failover for Droid sessions, which spend and reliability claims are vendor claims, and router vs DIY.
Last updated: June 24, 2026
Official Sources#
- Factory Router announcement - the primary source for the product claims in this post
- Factory 2.0: From coding agents to software factories - the self-improving system thesis
- Factory raises $150M Series C - the funding round and roadmap
- Choosing Your Model - the docs for manual model selection that the router sits on top of
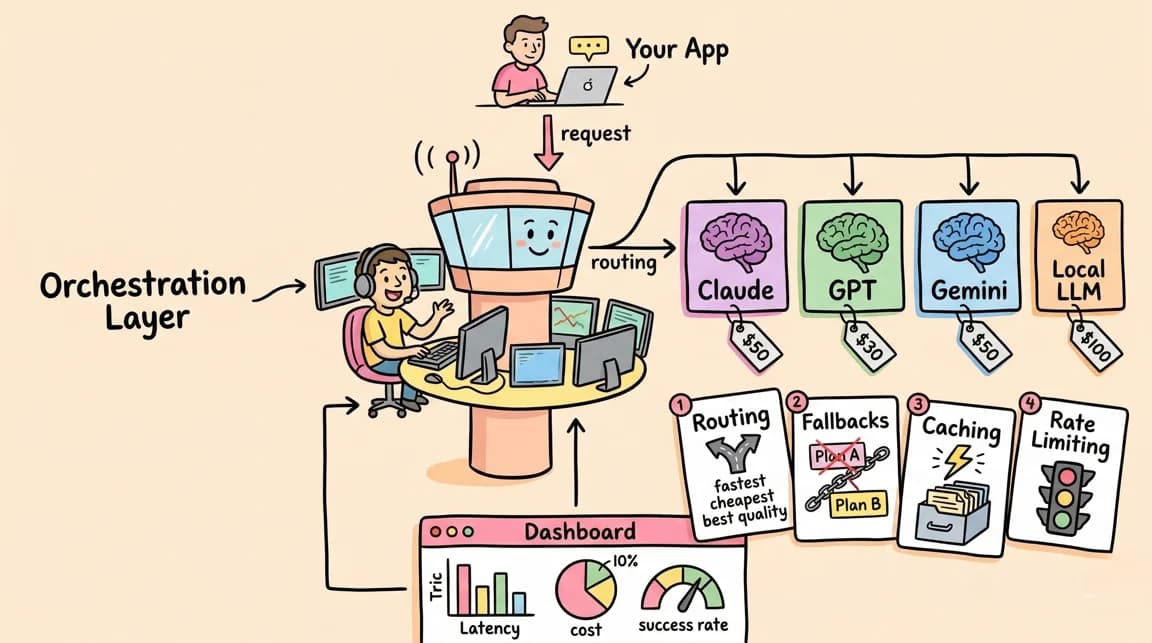
We have argued before that the orchestration layer is the next big play next to the labs: as frontier model quality flattens and commodifies, the durable value moves to the system that decides which model runs which task. Factory.ai's new Factory Router is the cleanest flagship example of that thesis shipping inside a real coding agent. So it is worth a close, favourable-but-factual look. The headline numbers are good. They are also vendor numbers, and we will keep flagging them as such.
For the broader buying decision, pair this with LLM routers compared, model routing recipes, and OpenRouter in 2026. Factory Router is the managed-agent version of a wider routing and gateway category.
What Factory Router Actually Is#
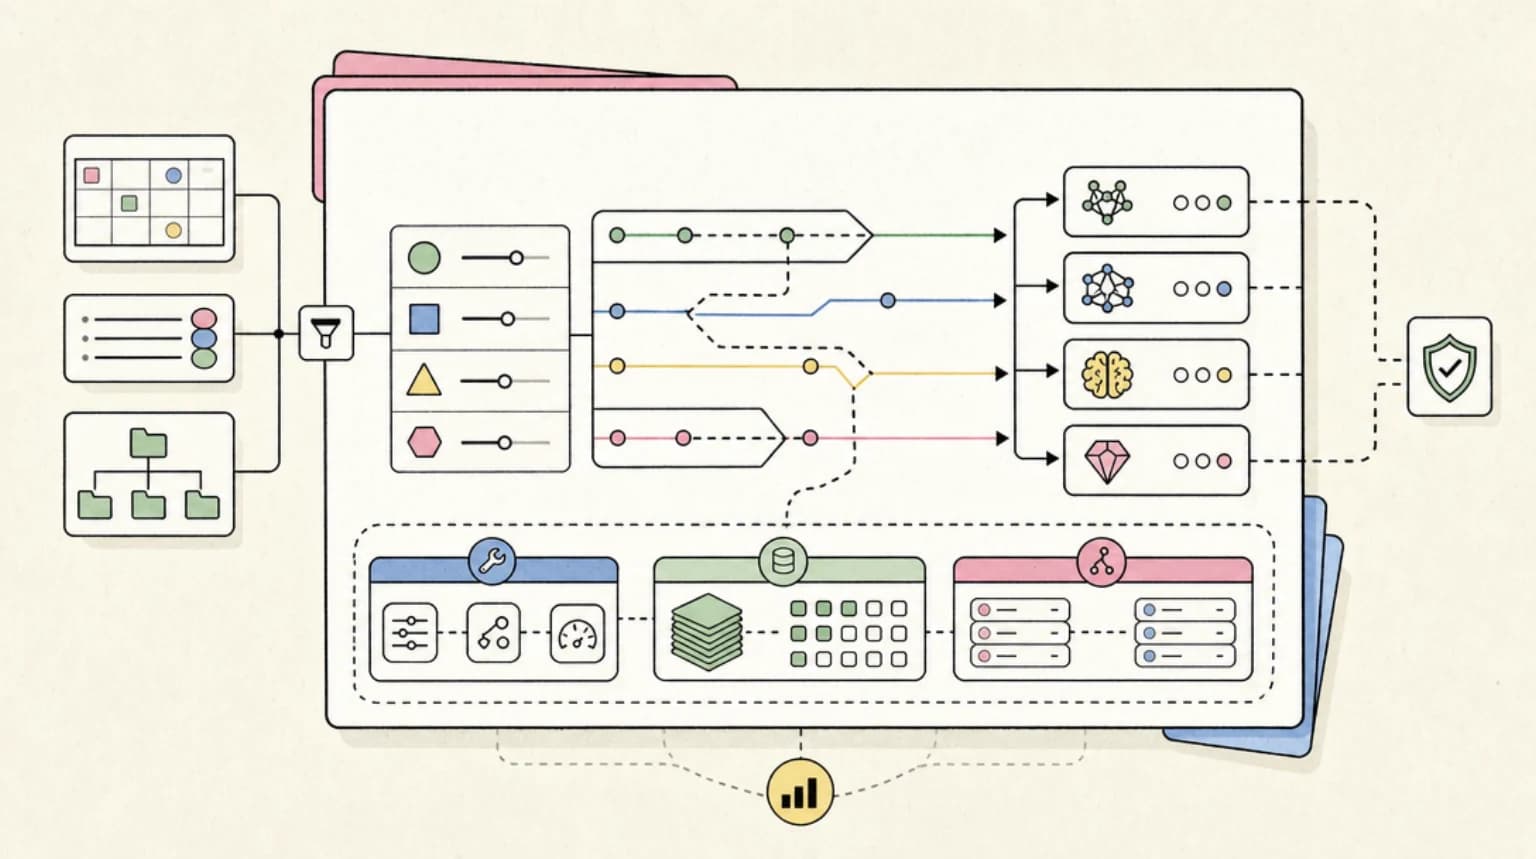
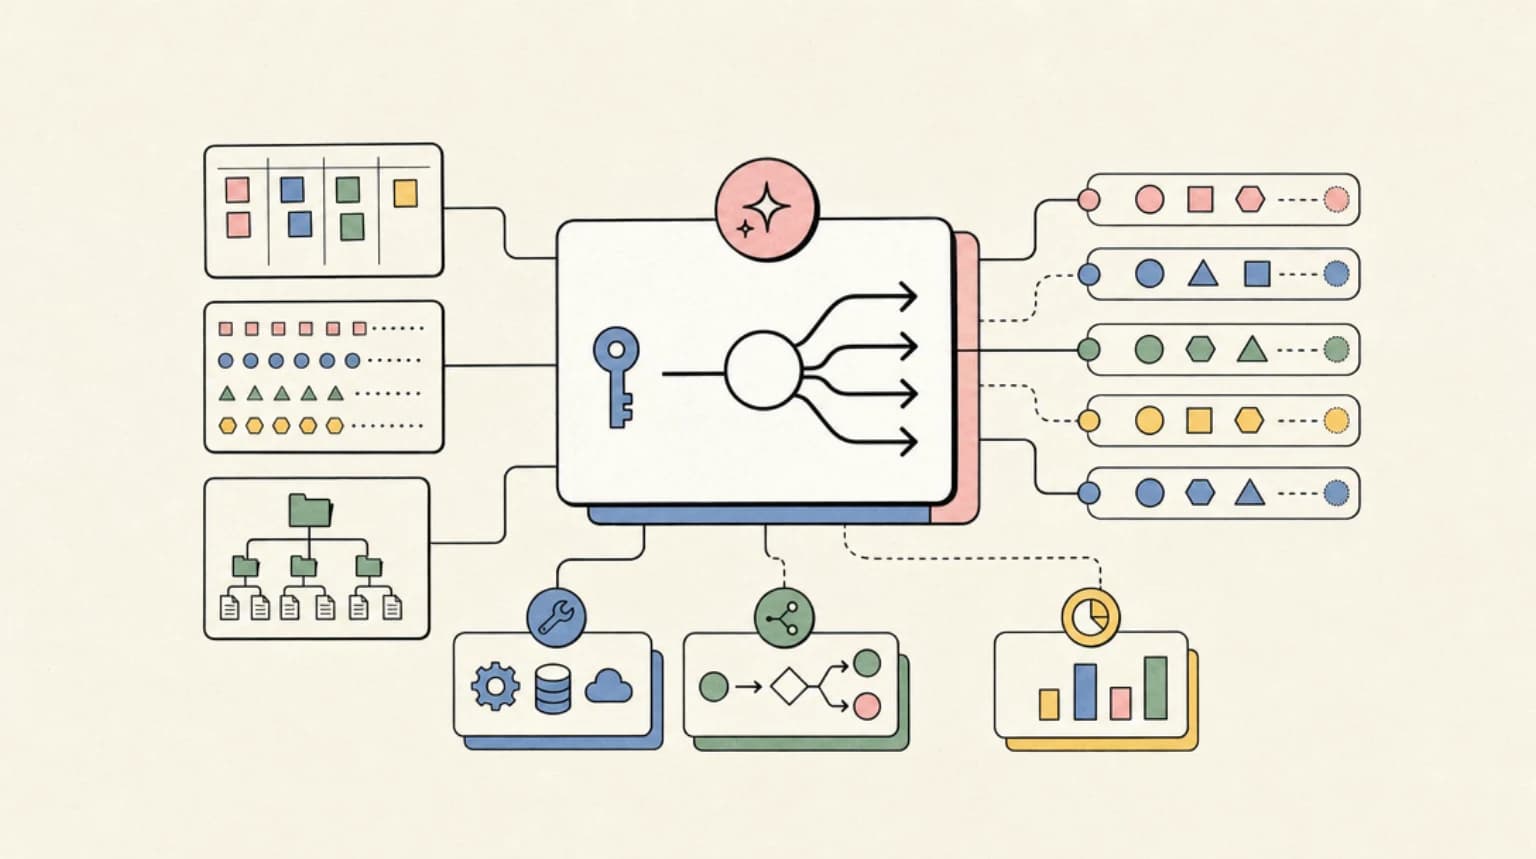
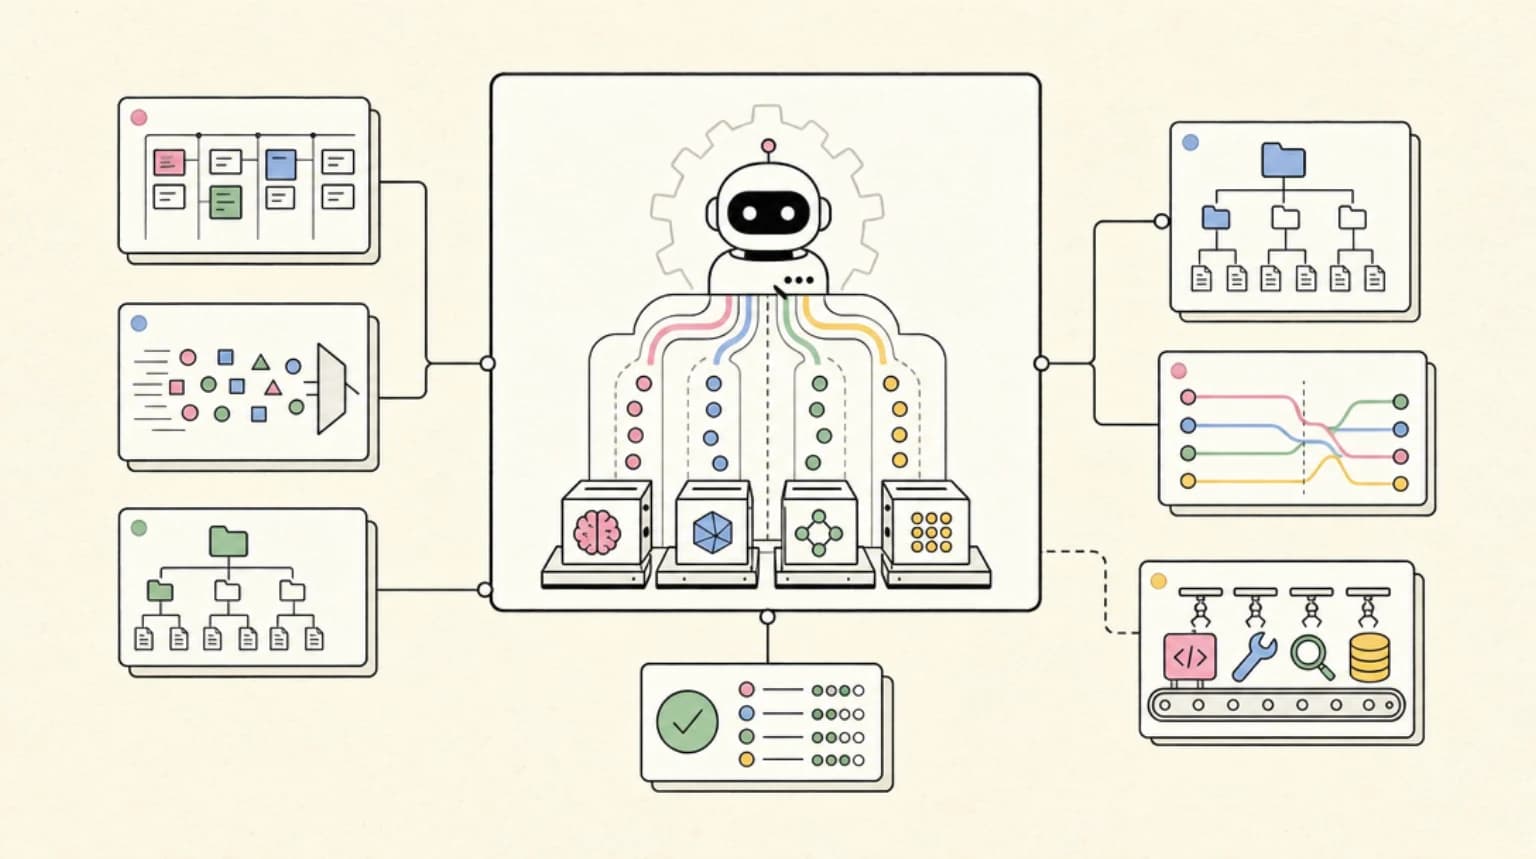
Factory Router is a routing layer baked into Factory's Droid coding agent. Per the announcement, it "automatically selects the right model for each task, and routes across providers if an endpoint degrades." Instead of expecting every engineer to manually pick the best model for every session, the router does the selection for them, drawing "from a diverse pool of frontier and efficient models."
Two things make it more than a thin proxy. First, it operates per Droid session, not per account, so the model choice tracks the actual work in front of it. Second, it escalates mid-flight: Factory says that if "the selected model struggles to complete the task, Factory Router moves the session to a more capable model." That escalation behavior is the same pattern we documented in our model routing recipes field guide - start cheap, escalate on signal - except here it is managed for you rather than wired up by hand.
It ships as part of the broader Droid product (CLI and Desktop App). Factory describes it as being in private research preview, and notes that once an org enables it, the router shows up in the model picker for every user with no per-developer setup.
The Model-Agnostic Foundation It Sits On#
The router only works because Droid was model-agnostic from the start. Factory's own framing in Factory 2.0 is that a Droid "is model agnostic, and can change models mid-session," routing its reasoning through frontier models from multiple providers depending on the task. The pool spans frontier models, more efficient models, and US-hosted open-source models, and Factory says it "keeps frontier models available as they come online."
This is the part worth internalizing: the router is not picking from one lab's menu. It arbitrages across providers. That is precisely why provider failover is possible at all, and it is the structural reason an orchestration vendor can claim independence from any single model's pricing or availability. We covered the architectural groundwork - Custom Droids, per-task model flags, droid exec - in our earlier piece on Factory AI and the model routing era. Factory Router is the automatic layer that sits on top of that manual control surface.
The Numbers (And Whose Numbers They Are)#
Here are the claims, stated plainly as Factory's claims, not as independently verified results:
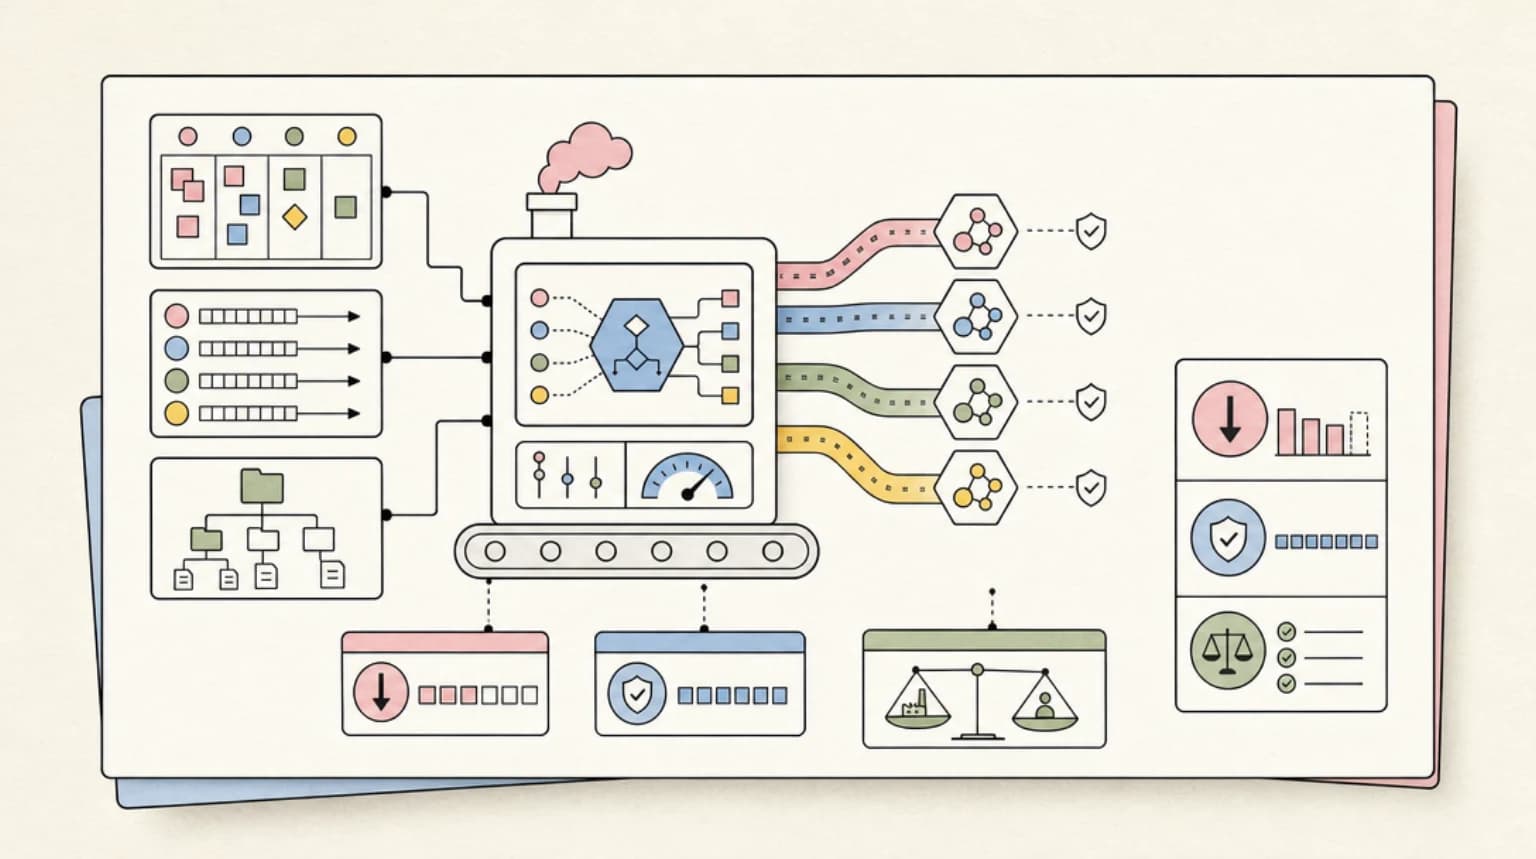
- 20-25% lower token spend "while maintaining frontier performance." (Factory)
- Terminal-Bench 2: 99% of Claude Opus 4.7's pass rate at 20% lower cost per session. (Factory)
- Legacy-Bench: 96% of Claude Opus 4.7's pass rate at 25% lower cost per session. (Factory)
- 99.9%+ request reliability by routing across models, providers, and capacity sources. (Factory)
A few honest caveats. These benchmarks are Factory's own, run by Factory, and the comparison baseline is a single frontier model (Opus 4.7). Holding 96-99% of a top model's pass rate while shaving a fifth to a quarter off cost is a genuinely strong result if it generalizes - but "if it generalizes" is doing real work. Your codebase, task mix, and tolerance for the occasional missed escalation will move those numbers. Treat 20-25% as a plausible ceiling for the easy-task share of your workload, not a guaranteed line-item cut. None of this is independently reproduced as of this writing.
The reliability claim is more believable on its face, because it is mechanical rather than statistical: if you can route the same request across multiple providers and reserved capacity, you genuinely do dodge any single provider's outage. Factory backs this with "provider failover" and an optional "Dedicated TPM" tier for "reserved throughput for critical Droid work." That is a real architectural lever, not a benchmark.
Self-Learning and Enterprise Control#
Factory's larger pitch in Factory 2.0 is a system that "must improve over time by observing itself," feeding "every agent session, code review, and resolved incident back into the loop." The router is the first concrete surface of that idea: routing decisions are meant to get better as the system sees more of your work.
That said, the public material is light on the mechanics of the learning loop - how feedback is captured, what gets tuned, on what cadence. So read "self-learning" as a stated direction with a credible architecture behind it, not a measured capability you can audit today. What is concrete is the manual override: admins can set "routing rules and context" that "describe workflow patterns" - codebase areas, toolchains, model preferences - to shape automatic selection. So it is not a black box you cannot steer.
Why This Matters Now: The Series C Read#
The router is not a side feature. Factory raised a $150M Series C in April 2026, led by Khosla Ventures with Sequoia, Insight, Blackstone, NEA and others, at a $1.5B valuation. Factory's stated use of funds explicitly named "model routing, always-on background agents, and enterprise governance" as product priorities, alongside long-horizon reliability research. In other words, the router is part of the thesis investors funded, and Factory reports hundreds of thousands of daily developers across enterprises like Nvidia, Adobe, EY, and Adyen, with revenue doubling month over month for six straight months (again, Factory's figures).
Strip away the specific company and you get the orchestration-layer bet in its purest form: own the routing decision, sit above every provider, and capture margin from efficiency rather than from owning a model. That is the structural story we have been tracking, and Factory is now the most fully realized instance of it inside a shipping coding agent.
This also connects to Models.dev as routing infrastructure: the more models, prices, context windows, and providers change, the more value sits in the current metadata and policy layer above them.
Router vs DIY Routing: Should You Use One?#
This is the practical question. You can build your own routing with OpenRouter, LiteLLM, or per-task model flags - we have published the recipes to do exactly that. So when does a managed router earn its keep?
Reach for a managed router (like Factory Router) when:
- Your routing is tied to a specific agent's session lifecycle (mid-session escalation, spec-vs-execute phases) rather than simple per-request model selection. That coupling is hard to replicate from outside the agent.
- You want provider failover and reliability without operating the plumbing yourself, and uptime on coding agents is a real cost to your team.
- You have many engineers and no appetite to make each of them a routing expert. Org-wide defaults with admin rules beat per-developer model-picking.
- You value the self-improving loop enough to accept some opacity in how decisions get made.
Roll your own when:
- You need full transparency and auditability over every routing decision (cost attribution, compliance, deterministic behavior).
- Your spend is concentrated in a workload you understand well enough to tier by hand - a static "cheap model for X, frontier for Y" config can capture most of the savings with zero vendor lock-in.
- You are routing across surfaces beyond a single agent (your own apps, CI jobs, internal tools) where an agent-bound router does not reach.
- Avoiding lock-in to one orchestration vendor is itself a priority.
The honest middle ground: a managed router is most compelling precisely where DIY is hardest - inside the agent's session loop, with failover, at team scale. It is least compelling for static, well-understood, single-axis cost tiering you could express in a config file. And whichever path you choose, the discipline from our $400 overnight bill piece still applies: a router optimizes cost-per-task, but it does not cap your total spend. You still need budgets, alerts, and FinOps guardrails on top.
The Bottom Line#
Factory Router is a credible, well-positioned flagship for the orchestration-layer thesis: model-agnostic routing across providers, per-session escalation, mechanical failover, and a self-improving ambition, backed by a $150M round that names routing as a core priority. The efficiency claims - 20-25% lower spend at 96-99% of Opus pass rate - are strong but are Factory's own benchmarks against a single baseline, and should be treated as a plausible upper bound rather than a promise. The reliability story is more structurally sound because it is mechanical, not statistical.
If you are already on Droid at team scale, the router is close to free upside: enable it, set a few routing rules, and watch your cost-per-task. If you are routing across your own stack, the DIY recipes still win on transparency and reach. Either way, the strategic takeaway holds: the model is increasingly a commodity input, and the system that decides which model runs is where the leverage now lives.
FAQ#
What is Factory Router?#
Factory Router is Factory.ai's managed model-routing layer for Droid sessions. Factory says it automatically chooses the right model for each coding-agent task, escalates to a stronger model when needed, and routes across providers when endpoints degrade.
Are the 20-25% savings independently verified?#
No. The 20-25% lower token-spend claim is Factory's own benchmark claim. Treat it as a vendor-reported result to test against your own task mix, not as a guaranteed savings number.
How is Factory Router different from LiteLLM or OpenRouter?#
LiteLLM and OpenRouter are general routing or gateway surfaces that can sit in front of many applications. Factory Router is tied to Factory's Droid agent session loop, which means it can make routing decisions based on the coding-agent workflow itself.
When should a team use a managed router?#
Use a managed router when routing is coupled to agent sessions, provider failover matters, and you do not want every engineer choosing models manually. Build your own routing when auditability, cross-app reach, or vendor independence matters more.
Does routing replace spend guardrails?#
No. Routing can reduce cost per task, but it does not cap total spend. Teams still need budgets, alerts, per-key limits, and workflow stop conditions.
Continue Reading#
Sources#
Get the next deep dive like this in your inbox
One email a week on factory-ai and the rest of the AI dev stack. Free.
Read next on AI coding tools
LLM Routers Compared: LiteLLM vs Portkey vs OpenRouter in 2026
LiteLLM vs Portkey vs OpenRouter compared for production AI apps: cost tracking, fallbacks, caching, and load balancing, plus when to use each router.
10 min readAI Model Routing: Why the Orchestration Layer Is the Next Big Play Next to the Labs
AI model routing and orchestration decide which model handles which task. How routing differs from orchestration, and practical ways to cut your model spend.
12 min readModel Routing Recipes: Practical Config Patterns to Cut AI Spend
Model routing recipes with paste-ready OpenRouter and LiteLLM configs for task tiers, fallback chains, cost ceilings and cache-aware routing that cut AI spend.
11 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.