AI Model Routing Strategies for Cost-Effective Coding in 2026
TL;DR
AI model routing for cost-effective coding: pick Claude, GPT-5.6 or Kimi tiers by task complexity, cost and latency, with decision frameworks and code.
Last updated: August 31, 2026. Prices in the tables below verified from official pricing pages on August 31, 2026; the What Changed sections preserve the July 31 baseline for context.
What Changed on August 31, 2026#
Since the July 31 refresh, three pricing facts moved:
Claude Sonnet 5's $2/$10 rate became permanent (August 15). Anthropic removed the promotional framing: $2 input / $10 output per MTok is now the standard price, and the September 1 increase to $3/$15 will not occur. Drop the "(promo)" arithmetic from routing math - Sonnet 5's mid-tier slot no longer expires.
DeepSeek's peak/off-peak policy is now in effect (August 16, 16:00 UTC). No more "date TBD": V4 Flash bills at $0.22 / $0.66 per MTok off-peak ($0.44 / $1.32 peak), and V4 Pro at $0.66 / $1.98 off-peak ($1.32 / $3.96 peak), with peak hours 01:00-04:00 and 06:00-10:00 UTC. The old $0.14/$0.28 flat floor is gone - even off-peak, output rates roughly doubled, so schedule batch-heavy work outside peak hours and re-base any budget built on the July numbers.
GPT-5.6 Sol was cut to $4/$20 (August 27). OpenAI's pricing page now lists Sol at $4 input / $20 output (from $5/$30), putting its output below Claude Opus 5's $25 and undercutting Opus 5 on input too. The premium-routing escape hatch got cheaper.
What Changed on July 31, 2026#
GPT-5.6 Luna dropped 80% to $0.20/$1.20 per MTok (July 30). OpenAI cut Luna from $1/$6 and Terra from $2.50/$15 to $2/$12, and renamed Priority Processing to Fast mode (2x pricing, up to 2.5x speed). Full detail in our price-cut analysis.
This changes routing math in two concrete ways:
- Luna is now the cheapest closed-provider worker tier. At $0.20 input and $1.20 output, it undercuts Claude Haiku 4.5 ($1/$5) by 5x on input and 4x on output. If you route to Haiku today for simple tasks and you are not locked to Anthropic, re-eval with Luna - the same task budget now buys 5x the simple-task volume on the OpenAI side. The cost-per-task comparison is in our budget tier post.
- The escalation threshold moved. The old advice was "send easy calls to a cheap model, escalate hard ones." With Luna at $0.20/$1.20, the cost of trying Luna first and escalating on failure is now negligible (a failed Luna attempt costs cents), so Luna-first fleets with Sol or Opus 5 reserved for planning steps are defensible where they looked stingy a month ago.
DeepSeek announced peak/off-peak pricing (July 31). The pricing page now warns that rates will double during peak hours (09:00-12:00 and 14:00-18:00 Beijing Time, UTC+8), effective date to be announced. V4 Flash also updated to version DeepSeek-V4-Flash-0731 with 1M context, 384K max output, and Anthropic-format API support. If you route to DeepSeek, expect peak-hour economics to change when the policy lands, and schedule batch work off-peak.
The era of one model for everything is over. Between Claude Fable 5 at $10/$50 per MTok and DeepSeek V4 Flash at $0.22/$0.66 off-peak, the cost spread is about 45x on input and 76x on output. Using the same model for every task is like buying first-class tickets for every flight - comfortable, but your budget does not survive first contact with production traffic.
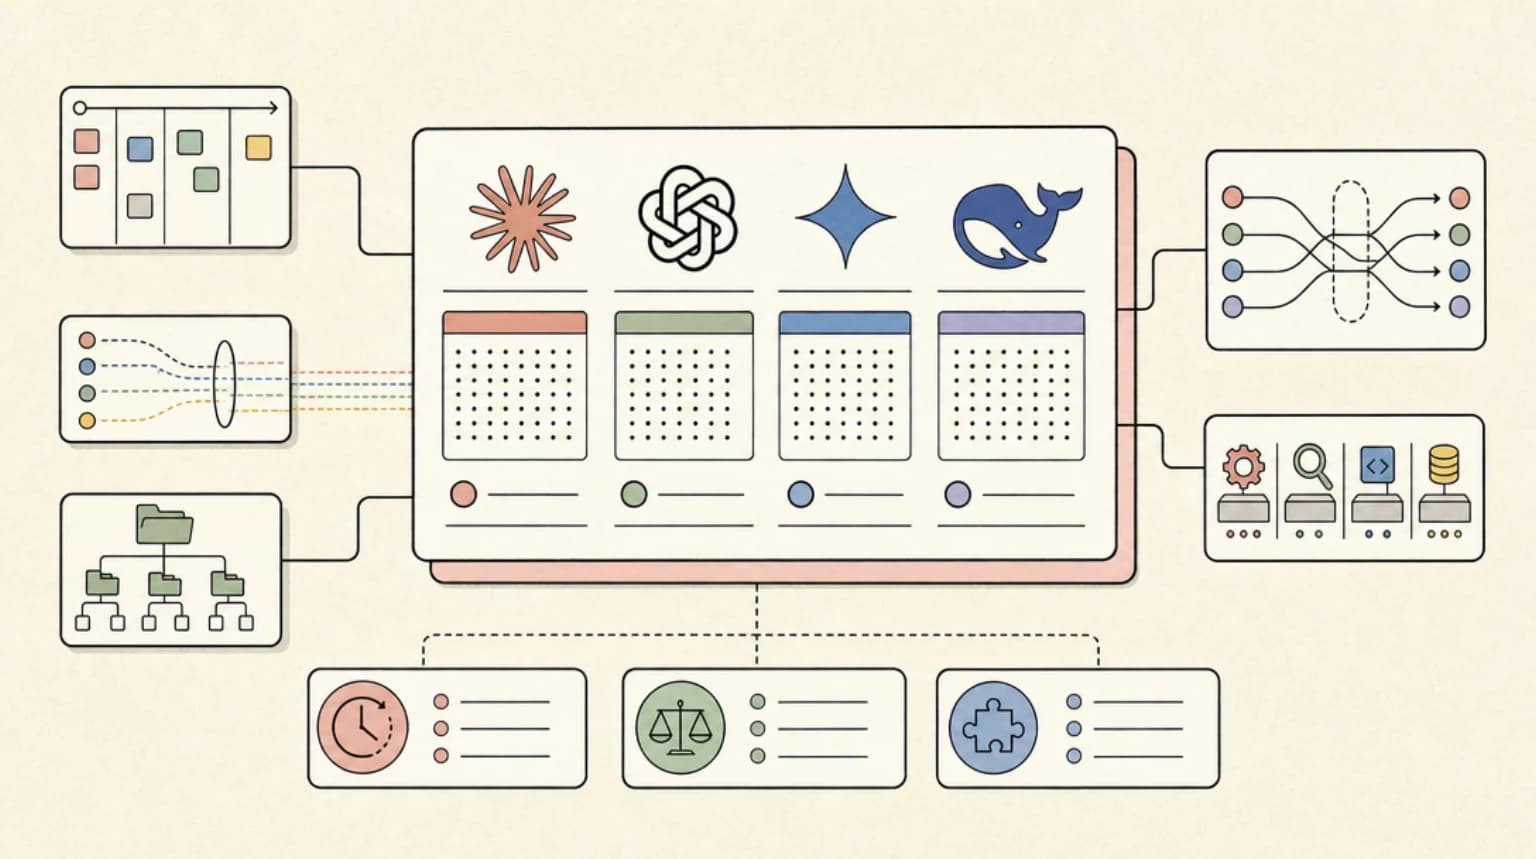
Model routing is the practice of sending each request to the cheapest model that can handle it correctly. This post covers the current model landscape, routing strategies by task type, implementation patterns, and a decision framework you can apply today.
The Routing Problem#
A coding agent performs many different operations in a single session. It browses files (trivial), reads documentation (simple), writes boilerplate (medium), debugs a race condition (complex), and occasionally rewrites a core architecture (frontier). Routing each subtask to the right model saves money without sacrificing quality.
Without routing, you have two bad options:
- Always use the cheapest model - works for simple tasks, fails on complex ones. Your agent looks smart until it hits something hard.
- Always use the most capable model - works for everything, but you pay Fable 5 or Sol prices for every file-read and every lint fix.
Routing splits the difference. Simple tasks go to cheap models. Hard tasks go to capable models. The savings compound across thousands of agentic steps per day.
Current Model Landscape (August 2026)#
All prices verified August 31, 2026 from official pricing pages. See the frontier API pricing tracker for the full table with cache and batch rates.
Pricing by Tier#
| Tier | Model | Input/MTok | Output/MTok | Best For |
|---|---|---|---|---|
| Frontier | Claude Fable 5 | $10 | $50 | Max intelligence, long-running agents |
| Frontier | GPT-5.6 Sol | $4 | $20 | Complex reasoning, code generation (cut August 27) |
| High | Claude Opus 5 | $5 | $25 | Complex agentic coding, enterprise work |
| Mid | Claude Sonnet 5 | $2 | $10 | Best speed/intelligence balance (rating now permanent) |
| Mid | GPT-5.6 Terra | $2 | $12 | Mid-tier coding tasks (cut 20% July 30) |
| Mid | Kimi K3 | $3 | $15 | Self-hosted open-weight coding |
| Low | GPT-5.6 Luna | $0.20 | $1.20 | Default budget worker (cut 80% July 30) |
| Low | Claude Haiku 4.5 | $1 | $5 | Fastest Claude, simple tasks |
| Budget | DeepSeek V4 Pro (off-peak) | $0.66 | $1.98 | High-volume tasks, 1M context (peak $1.32/$3.96) |
| Budget | DeepSeek V4 Flash (off-peak) | $0.22 | $0.66 | Maximum cost efficiency (peak $0.44/$1.32) |
The July 30 cuts reordered the low tier: Luna at $0.20/$1.20 is now cheaper than Haiku 4.5 on both input and output, making it the default budget worker for OpenAI shops. DeepSeek V4 Flash remains the absolute floor at $0.22/$0.66 off-peak; the peak/off-peak policy landed August 16, so route batch-heavy work outside peak hours (01:00-04:00 and 06:00-10:00 UTC) and budget by off-peak numbers.
Intelligence by Coding Task#
These are directional assessments based on published benchmarks and production experience. Not every model shines at every task type.
| Task Type | Models That Handle It Well |
|---|---|
| File read, grep, simple refactors | Haiku 4.5, Luna, V4 Flash, V4 Pro |
| Boilerplate generation, test writing | Sonnet 5, Terra, Kimi K3, V4 Pro |
| Bug diagnosis, code review | Opus 5, Sonnet 5, Terra |
| Architecture design, complex refactoring | Opus 5, Sol, Fable 5 |
| Multi-file orchestration, agentic workflows | Fable 5, Sol, Opus 5 |
| Documentation, explanation | Sonnet 5, Haiku 4.5, Luna |
Routing Strategies#
1. Task-Complexity Routing#
The simplest and most effective strategy. Classify each request by complexity and route to the appropriate tier.
Simple (Luna / Haiku 4.5 / V4 Flash):
  - Read a file
  - Search for a pattern
  - Run a linter
  - Generate a getter/setter

Medium (Sonnet 5 / Terra / Kimi K3):
  - Write a test suite
  - Refactor a function
  - Generate API route handlers
  - Review a PR for style issues

Complex (Opus 5 / Sol):
  - Debug a race condition
  - Design a database schema
  - Rewrite a core module
  - Plan a multi-step refactor

Frontier (Fable 5 / Sol Pro):
  - Novel algorithm design
  - Security audit
  - Complex multi-agent coordination
Implementation is straightforward - tag each request with a complexity level and switch models:
type Complexity = 'simple' | 'medium' | 'complex' | 'frontier';

const MODEL_MAP: Record<Complexity, string> = {
  simple: 'gpt-5-6-luna',        // $0.20/$1.20 after the July 30 cut
  medium: 'claude-sonnet-5',     // $2/$10 (permanent since August 15)
  complex: 'claude-opus-5',      // $5/$25
  frontier: 'claude-fable-5',    // $10/$50
};

function routeRequest(task: Task, complexity: Complexity) {
  const model = MODEL_MAP[complexity];
  return callModel(model, task.prompt);
}
2. Cost-Budget Routing#
Set a per-request or per-session budget and let the router pick the model dynamically. Useful for cost-sensitive workloads like CI/CD pipelines or bulk processing.
interface BudgetConfig {
  maxInputCostPerMTok: number;
  maxOutputCostPerMTok: number;
}

function pickModelByBudget(budget: BudgetConfig): string {
  const models = [
    { name: 'gpt-5-6-luna', input: 0.2, output: 1.2 },
    { name: 'claude-haiku-4-5', input: 1, output: 5 },
    { name: 'claude-sonnet-5', input: 3, output: 15 },
    { name: 'deepseek-v4-flash', input: 0.22, output: 0.66 },
  ];
  const candidates = models.filter(
    m => m.input <= budget.maxInputCostPerMTok
      && m.output <= budget.maxOutputCostPerMTok
  );
  return candidates.sort((a, b) => a.input - b.input)[0]?.name ?? 'claude-opus-5';
}
3. Provider-Level Routing#
Run models from multiple providers and route based on availability, latency, or pricing shifts. This protects against provider outages and lets you arbitrage pricing differences.
interface ProviderConfig {
  provider: 'anthropic' | 'openai' | 'moonshot' | 'deepseek';
  model: string;
  priority: number;
}

const PROVIDER_CHAIN: ProviderConfig[] = [
  { provider: 'anthropic', model: 'claude-sonnet-5', priority: 1 },
  { provider: 'openai', model: 'gpt-5-6-terra', priority: 2 },
  { provider: 'moonshot', model: 'kimi-k3', priority: 3 },
];

async function routeWithFallback(task: Task): Promise<Result> {
  for (const config of PROVIDER_CHAIN.sort((a, b) => a.priority - b.priority)) {
    try {
      return await callProvider(config.provider, config.model, task);
    } catch (err) {
      console.warn(`${config.provider}/${config.model} failed:`, err);
      continue;
    }
  }
  throw new Error('All providers failed');
}
4. LLM-as-Router#
Use a cheap model to decide which model to use for the actual task. The router model analyzes the request and returns a complexity score or model recommendation.
async function routerLLM(task: Task): Promise<Complexity> {
  const routerPrompt = `Classify this coding task as "simple", "medium", "complex", or "frontier".
Task: ${task.description}
Respond with exactly one word.`;
  const response = await callModel('claude-haiku-4-5', routerPrompt);
  return response.trim().toLowerCase() as Complexity;
}

async function routedCall(task: Task) {
  const complexity = await routerLLM(task);
  const model = MODEL_MAP[complexity];
  return callModel(model, task.prompt);
}
The routing LLM costs about $0.001 per classification with Haiku 4.5. On a 10:1 simple-to-complex ratio, this saves 90%+ on the simple tasks while keeping the routing overhead below 1% of total cost.
Decision Framework#
By Team Profile#
| Team Type | Recommended Strategy | Estimated Savings vs Always-Opus-5 |
|---|---|---|
| Solo dev, daily coding | Task-complexity routing (Haiku + Sonnet + Opus 5) | 40-60% |
| Small team on a budget | Cost-budget routing with Haiku + Luna + Terra | 60-80% |
| CI/CD pipelines | Budget routing with V4 Flash + Haiku | 80-95% |
| Production agent platform | LLM-as-router + provider fallback | 50-70% |
| Enterprise with fixed budget | Provider-level routing across all tiers | 40-50% |
By Task Volume#
| Daily Token Volume | Model Strategy | Recommended Setup |
|---|---|---|
| < 10M tokens | Single model | Sonnet 5 or Terra |
| 10M - 100M tokens | 2-tier routing | Haiku + Sonnet |
| 100M - 1B tokens | 3-tier + caching | Haiku + Sonnet + Opus 5 |
| 1B+ tokens | Full routing + provider fallback | All tiers, multi-provider |
When Routing Does Not Help#
Routing is not free. It adds complexity, testing surface, and potential failure modes. Skip it when:
- Your volume is under 10M tokens/month. The engineering cost of building and maintaining a router exceeds the savings.
- Your tasks are uniformly complex. If every prompt is a difficult refactor, you want Opus 5 or Fable 5 for all of them. Routing just slows you down.
- You are prototyping. Use the best single model and ship. Add routing when you hit production costs.
- Your provider SDK does not support fast model switching. Some tools (Claude Code, Cursor) have limited or no routing support. The model selection happens at the tool level, not the API level.
FAQ#
What is model routing in AI coding?#
Model routing is the practice of sending different coding tasks to different AI models based on task complexity, cost sensitivity, or latency requirements. Simple tasks like file reads go to cheap models like GPT-5.6 Luna ($0.20/$1.20 after the July 30 cut) or DeepSeek V4 Flash. Complex tasks like architecture design go to capable models like Claude Opus 5 or GPT-5.6 Sol. The goal is to maximize output quality while minimizing token cost.
How much can model routing save on API costs?#
Savings depend on your task distribution. A typical coding agent session has about 70% simple tasks, 20% medium tasks, and 10% complex tasks. Routing these appropriately saves 40-60% compared to using Opus 5 for everything, and 80-95% compared to using Fable 5 for everything. CI/CD pipelines see the largest savings because most automated tasks are simple.
Which models should I use for each task tier?#
A common three-tier setup: GPT-5.6 Luna ($0.20/$1.20) or Claude Haiku 4.5 ($1/$5) for simple tasks, Claude Sonnet 5 ($2/$10, permanent since August 15) or GPT-5.6 Terra ($2/$12) for medium tasks, and Claude Opus 5 ($5/$25) or GPT-5.6 Sol ($4/$20 after the August 27 cut) for complex tasks. Budget workloads can substitute DeepSeek V4 Flash ($0.22/$0.66 off-peak) for the simple tier. All prices verified August 31, 2026.
Can I route between Anthropic and OpenAI models?#
Yes. Provider-level routing between Anthropic and OpenAI is common for fallback and cost arbitrage. Both providers have compatible API formats. The main consideration is response quality differences - Opus 5 and Sol are close on coding benchmarks but may handle specific task types differently. Test your routing logic with both providers before production deployment.
Does Claude Code support model routing?#
Claude Code uses the model selected in its configuration for all tasks within a session. It does not support per-request model routing. For routing at the API level, build your own routing layer and call the Claude API directly with different model parameters per request. Cursor, Codex, and Windsurf similarly use a single model per session - routing is an API-layer concern, not a tool feature.
What is the cheapest coding model in 2026?#
DeepSeek V4 Flash at $0.22/$0.66 per MTok (off-peak; $0.44/$1.32 during peak hours) is the cheapest available coding model as of August 2026, verified on DeepSeek's pricing page August 31. GPT-5.6 Luna at $0.20/$1.20 (after the July 30 cut) and Claude Haiku 4.5 at $1/$5 are the cheapest options from major US providers, with Luna now undercutting Haiku on both rates. For self-hosted workloads, Kimi K3 open weights or DeepSeek V4 self-hosted eliminate per-token costs entirely (infrastructure costs still apply). Note DeepSeek's peak/off-peak policy has been in effect since August 16: peak-hour rates double during 01:00-04:00 and 06:00-10:00 UTC, so schedule batch work off-peak.
Is routing worth it for a small team?#
Only if your token volume exceeds about 10 million tokens per month. Below that threshold, the engineering cost of building and maintaining routing logic exceeds the savings. Use a single mid-tier model like Claude Sonnet 5 or GPT-5.6 Terra and switch to routing when your costs justify the complexity.
Sources#
Prices verified August 31, 2026 (July 31 for the price-cut announcement links):
- Anthropic Models Overview - Claude model lineup and pricing
- Anthropic Pricing - official Claude API pricing
- OpenAI API Pricing - GPT-5.6 family pricing (Luna and Terra cuts effective July 30)
- OpenAI: Advancing the price-performance frontier with GPT-5.6 - July 30 price-cut announcement
- Moonshot Kimi K3 Pricing - Kimi K3 API pricing
- DeepSeek API Pricing - DeepSeek V4 pricing and peak/off-peak notice
Official Sources#
| Source | Description |
|---|---|
| Anthropic Models | Current Claude model IDs, capabilities, and pricing |
| Anthropic Pricing | Official Claude API per-token rates |
| OpenAI API Pricing | Current OpenAI model pricing (GPT-5.6 family) |
| OpenAI Price-Performance Announcement | July 30 Luna/Terra price cuts and Fast mode |
| Moonshot Kimi K3 Pricing | Kimi K3 API per-token pricing |
| DeepSeek Pricing | V4 Pro and V4 Flash per-token rates, peak/off-peak notice |
| Frontier Model API Pricing Tracker | Full comparison table with cache and batch rates |
Continue Reading#
- Frontier Model API Pricing Tracker - full pricing comparison with cache and batch rates
- GPT-5.6 Price Cuts: Cost-Per-Task Math for Agent Builders - the July 30 cuts that reshaped this post's numbers
- Budget AI Coding Models Compared 2026 - Luna vs DeepSeek V4 Flash vs Haiku 4.5 head-to-head
- AI Coding Tools Pricing Compared 2026 - what you actually pay for coding agent subscriptions plus API costs
- Claude Opus 5 vs Opus 4.8 vs Fable 5 Comparison - benchmark and cost-per-task analysis
- MAI-Code-1-Flash Is a Model Routing Signal
Get the next deep dive like this in your inbox
One email a week on AI Coding and the rest of the AI dev stack. Free.
Read next on Claude Code
LLM API Pricing, October 2026: Claude vs OpenAI vs Gemini
LLM API pricing for October 2026 per million tokens: Claude Haiku 5.5, Sonnet 5.5, Opus 5.5 and Fable 5.1 vs GPT-6, Gemini and DeepSeek, plus the caveats.
12 min readAI Coding Tools Pricing Comparison 2026
AI coding tools pricing, verified Sep 28, 2026: Claude Code, Codex, Cursor, Copilot, Antigravity, Windsurf and more. Free tiers, pro plans and hidden costs.
12 min readClaude Opus 5 vs Opus 4.8 vs Fable 5: Benchmark Comparison (July 2026)
Claude Opus 5 launched July 24, 2026 at $5/$25 per MTok - matching Opus 4.8 pricing while delivering near-Fable 5 intelligence. Full benchmark comparison across 7 evals, pricing breakdown, and decision guide.
22 min readTechnical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.