Best Claude Model Now That Fable 5 Is Disabled (Mythos vs Opus vs GPT-5.5)
TL;DR
Fable 5 and Mythos 5 are gone for now.
Last updated: June 15, 2026 - the ranking below is the June 2026 answer. For the newer Claude 5.5 lineup, see Opus 5.5 vs Sonnet 5.5 vs Haiku 5.5: Which Claude Model to Use.
The Short Answer#
With Fable 5 and Mythos 5 suspended, your best available model for most serious work is Claude Opus 4.8. It is the closest thing to Fable that you can actually call today, and it is fully unaffected by the directive.
But "best" depends on what you are doing. Here is the breakdown.
The Replacements, Ranked#
Claude Opus 4.8 (claude-opus-4-8): the default pick.
Closest in capability to Fable, available everywhere Fable was, and the lowest-friction swap. If you had pinned claude-fable-5, change it to claude-opus-4-8 and you are running again. The main thing you give up is Fable's long-horizon task persistence, the ability to grind on a multi-step goal without losing the thread, which was the clearest difference between the tiers.
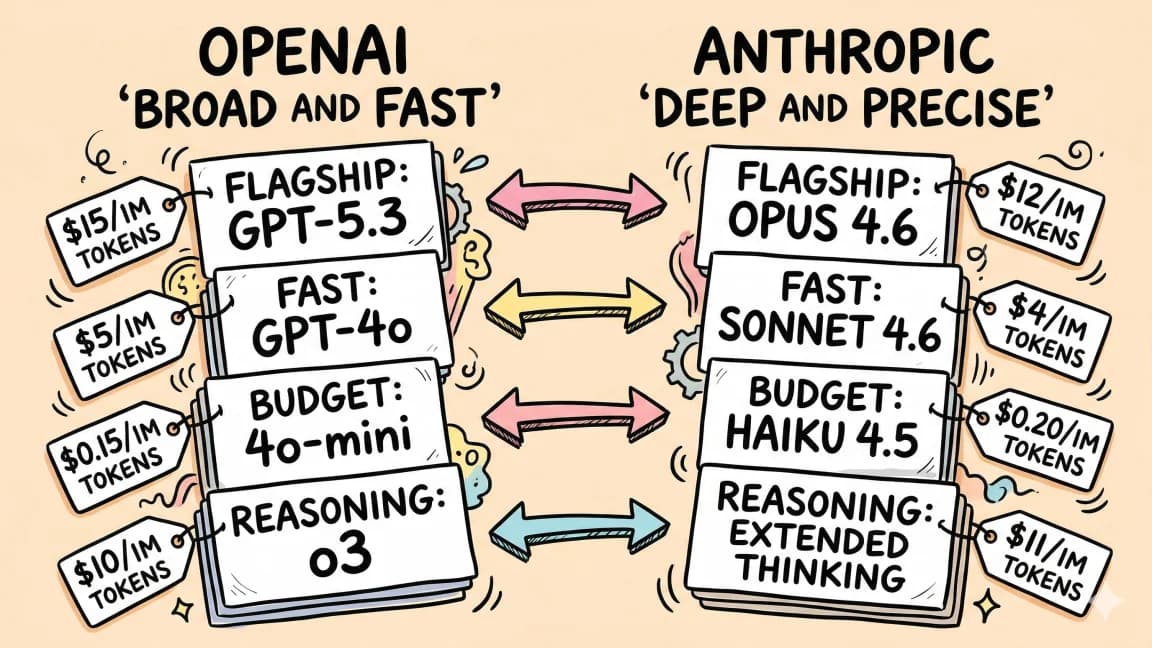
OpenAI GPT-5.5: the cross-vendor hedge. If today taught you anything, it is that a single provider can vanish overnight. GPT-5.5 is a strong second source, and notably, Anthropic itself pointed to GPT-5.5 as having comparable capability on the specific task the government flagged. For agentic coding, Opus 4.8 still edges it in our testing, but having a tested fallback on a different vendor is no longer optional.
Claude Sonnet 4.6 (claude-sonnet-4-6): the cost-aware workhorse.
For high-volume, latency-sensitive, or cost-sensitive workloads, Sonnet 4.6 is the right tool. You would not reach for it to replace Fable on your hardest reasoning tasks, but for most production traffic it is the sensible default that Fable was overkill for anyway.
Open-weight models (Qwen, Kimi, GLM, DeepSeek): the floor nobody can pull. The strongest argument for open weights was never benchmark parity. It is that no government letter can switch them off. They define your worst-case capability floor: the level your product degrades to but never below, because the weights are on your disk. After today, deciding your open-weight floor is a real architectural decision, not a hobby.
Pick by Task#
- Agentic coding, hard reasoning, long multi-step jobs: Opus 4.8, with GPT-5.5 as your tested fallback.
- High-volume API traffic, summarization, classification: Sonnet 4.6.
- Cheap, fast, simple calls: Haiku 4.5 (
claude-haiku-4-5-20251001). - Anything that absolutely cannot go down: an open-weight model you control, as your floor.
Do Not Just Swap the String#
The lesson of the Fable suspension is not "use Opus instead." It is that model availability is now operational risk. Hardcoding any single model ID, from any vendor, is a single point of failure.
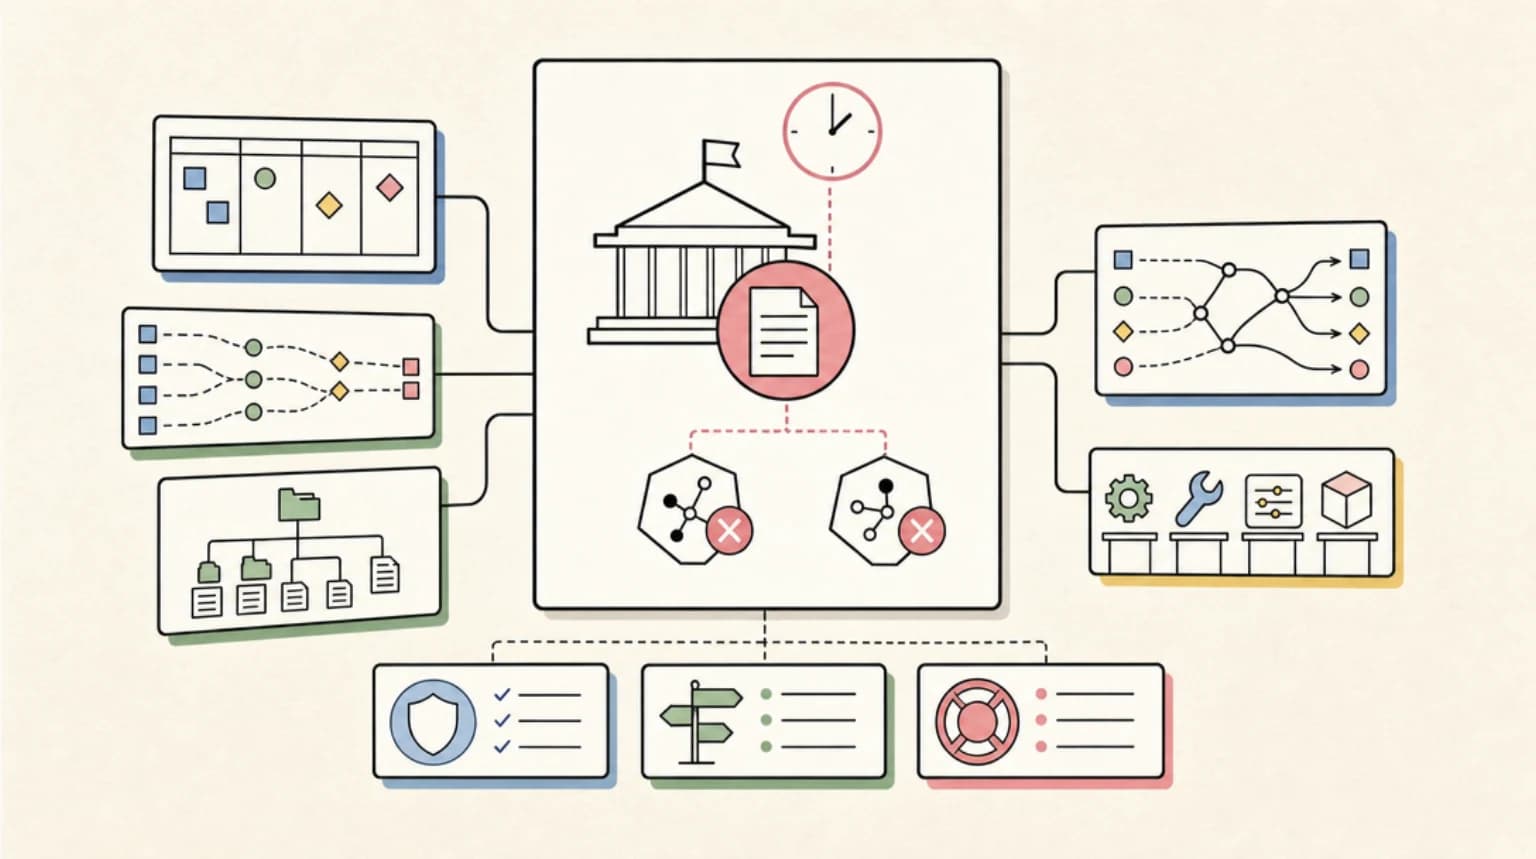
The fix is a model abstraction layer: one config switch for provider and model, a fallback chain you actually test against your eval suite, and a canary that detects silent model substitution. A router like OpenRouter or LiteLLM makes the provider swap a config change instead of a code change. We wrote the full playbook in Your Stack Has a Single Point of Failure.
If you are running most of this through Claude Code day to day, the model picker setting is the fastest place to test a fallback before you wire up a full abstraction layer.
Background#
If you are still catching up on why your model disappeared: what happened, why it happened, and the difference between Mythos and Fable. To check whether Fable is back yet, see Is Claude Fable 5 Down?.
Official Sources#
| Resource | Link |
|---|---|
| Anthropic Models Documentation | docs.anthropic.com/en/docs/about-claude/models |
| Claude API Pricing | anthropic.com/pricing |
| GPT-5.5 Announcement | openai.com/index/introducing-gpt-5-5 |
| OpenAI API Pricing | openai.com/api/pricing |
| Claude Code Documentation | docs.anthropic.com/en/docs/claude-code |
FAQ#
Is Claude Opus 4.8 a true replacement for Fable 5?#
For most agentic coding and reasoning workloads, yes. It is the closest available model in capability and works everywhere Fable did. The main gap is Fable's long-horizon task persistence on very long multi-step jobs.
Should I hardcode a fallback to GPT-5.5 instead of switching my primary model?#
Treat it as a tested fallback, not a primary swap. Opus 4.8 still edges GPT-5.5 on agentic coding in most testing, but having a working, tested path to a second vendor matters more after this suspension than it did before.
Do open-weight models replace Fable 5?#
No, not on raw capability. Their value is that no external directive can switch them off. They set a capability floor you control, which is a different job than matching Fable's benchmark scores.
What is the actual fix so this does not happen again?#
A model abstraction layer: a single config switch for provider and model, a fallback chain tested against your own eval suite, and a canary that flags silent model substitution, instead of a hardcoded model string anywhere in your code.
Continue Reading#
Get the next comparison like this in your inbox
One email a week on Claude and the rest of the AI dev stack. Free.
Read next on Claude Code
The US Government Just Pulled Fable 5: What Happened
Fable 5 was pulled by a US export control directive, disabling it and Mythos 5 for every customer. What happened, what still works, and what to do next.
5 min readClaude Mythos vs Fable 5: What Is the Difference?
Claude Mythos 5 vs Fable 5 explained. They are the same underlying model with different access and safeguards, which is why both were suspended together.
5 min readClaude Opus 4.8 Is an Agent Honesty Release
Claude Opus 4.8 for developers: better honesty, dynamic workflows and effort controls that make long-running agent work easier to review.
8 min readTechnical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.