Self-Improving Agents in 5 Minutes: Reflect, Refine, Repeat
TL;DR
Self-improving agents explained: reflection loops, Reflexion, LATS tree search, and meta agents, plus how to ground the critique step so the loop converges.
Last updated: July 26, 2026
Official Sources#
| Topic | Official Source |
|---|---|
| Reflexion (Shinn et al., 2023) | arxiv.org/abs/2303.11366 |
| LATS (Zhou et al., 2024) | arxiv.org/abs/2310.04406 |
| ADAS / Meta Agent Search (Hu et al., 2024) | arxiv.org/abs/2408.08435 |
| LangGraph Reflection Agents | blog.langchain.dev/reflection-agents |
| LangGraph Reflexion + LATS examples | github.com/langchain-ai/langgraph |
| Anthropic building effective agents | anthropic.com/engineering/building-effective-agents |
| Developers Digest video | youtube.com/watch?v=RoaPvj9Ovug |
The Problem#
Most AI agents run in a single pass: prompt in, response out. If the output is wrong, you fix it yourself and move on. The agent never learns what went wrong, and your next session starts from zero.
Self-improving agents flip that. Instead of a fire-and-forget pipeline, the agent reflects on its own output, evaluates what worked and what didn't, and iterates until it converges on a better result. The pattern shows up across three tiers - from a simple 2-node loop you can build in an afternoon to meta-agents that write new agents in code. Here is the map, with real implementations you can use today.
The video above walks through each pattern visually - the post gives you the concepts, the video shows the live demo flow that a static page cannot: seeing an agent correct its own output in real time, backtracking from bad decisions, and converging on a solution it could not reach in one shot.
The Core Loop: Generate, Reflect, Refine#
Every self-improving agent follows the same skeleton:
- Generate - produce an initial response or action
- Reflect - critique the output against some standard (test results, search citations, a second LLM call acting as reviewer)
- Refine - use the critique to produce a better version
- Repeat - loop until the output meets the bar, a max iteration count is hit, or the agent determines it cannot improve further
The magic is in step 2. If the reflection is just "try harder," you get a more confident wrong answer. If the reflection is grounded in external data - test pass/fail, search results, compiler output - the loop converges toward correctness. The difference between a toy demo and a production agent lives in how you ground the reflection step.
For background on the agent infrastructure this runs on, our agent architecture guide walks through state management, error recovery, and the production gotchas that turn a five-step demo into a reliable system.
Pattern 1: Simple Reflection#
The entry point. Two LLM calls wired in a loop: a generator and a reflector. The generator produces output. The reflector is prompted to role-play as a critic - "act as a code reviewer," "act as a teacher grading the response" - and returns constructive feedback. The generator gets another shot with the feedback in context. Loop N times, then return the last output.
from langgraph.graph import MessageGraph

builder = MessageGraph()
builder.add_node("generate", generation_node)
builder.add_node("reflect", reflection_node)
builder.set_entry_point("generate")

def should_continue(state):
    if len(state) > 6:
        return END
    return "reflect"

builder.add_conditional_edges("generate", should_continue)
builder.add_edge("reflect", "generate")
graph = builder.compile()
This works for: polishing writing, improving code comments, catching obvious logic gaps. It costs 2x-3x the tokens of a single pass.
It fails when: the reflection has no external grounding. A generic "be more thorough" critique produces a longer response, not a better one. If your generator already missed something, a same-model reflector in the same session often misses it too.
The LangGraph reflection example ships a full implementation. Start here before reaching for heavier approaches.
Pattern 2: Reflexion (Verbal RL)#
Reflexion, from Shinn et al. (2023), adds the missing piece: episodic memory. The agent stores its reflections in a persistent buffer and references them on future attempts. It also grounds criticism in external data - search citations, test results, compiler errors - rather than free-form commentary.
The three-part architecture:
- Actor - generates a response plus tool calls (search queries, code execution requests)
- Evaluator - scores the output against ground truth or heuristic metrics
- Self-reflection - stores what went wrong in memory for the next attempt
On the HumanEval coding benchmark, Reflexion hit 91% pass@1 on GPT-4, up from the baseline 80%. That 11-point gain comes entirely from the reflection loop - no model fine-tuning, no weight updates.
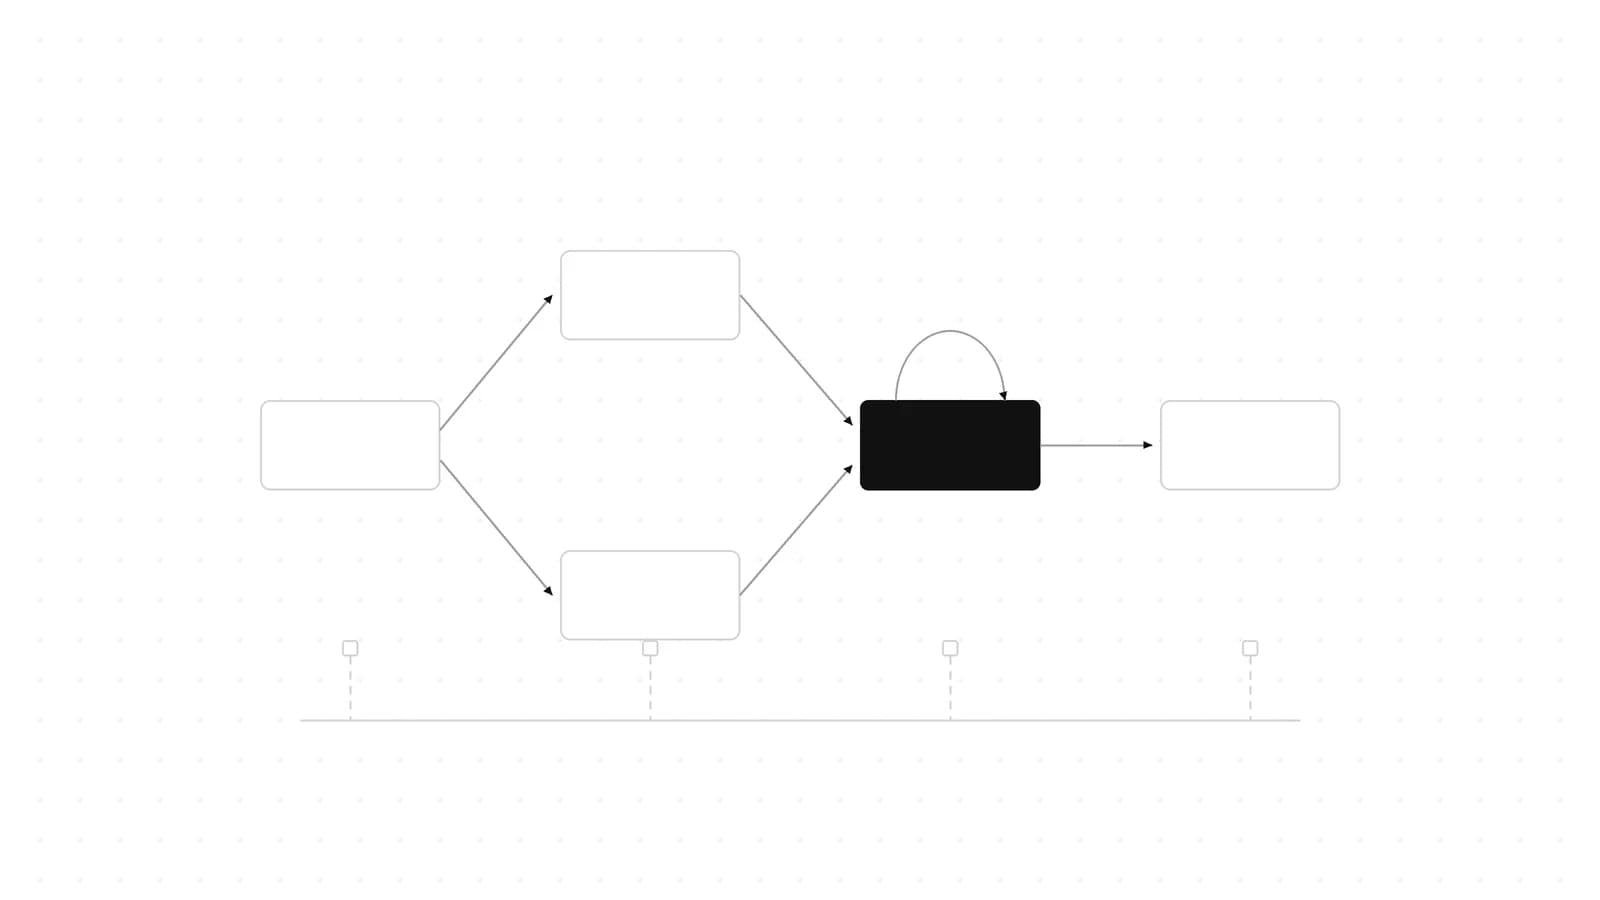
The LangGraph Reflexion example implements this with a draft -> execute_tools -> revise loop. The key difference from simple reflection: the revise node is grounded in external tool output, and reflections persist across iterations.
When to use Reflexion over simple reflection:
- Tasks with objective correctness criteria (coding, math, factual QA)
- Environments where you can run tool calls for ground truth (compiler, test runner, search API)
- Multi-step problems where early mistakes cascade into later errors
For a real-world example of agent loops scaling in production, see how AI agent evaluation tools compare across 2026 - the reflection pattern is the backbone of most eval harnesses shipping today.
Pattern 3: LATS and Meta Agents#
Language Agent Tree Search (LATS, Zhou et al. 2024) replaces the single-path loop with tree search. Instead of one refine pass, the agent generates multiple candidate next actions, evaluates each in parallel, and picks the best path using Monte Carlo tree search. If one branch dead-ends, it backpropagates the failure signal and explores alternatives.
This unifies reasoning, planning, and reflection into a single algorithm. The LangGraph LATS example shows it in ~300 lines of Python.
At the top of the complexity curve: Automated Design of Agentic Systems (ADAS, Hu et al. 2024) uses a meta-agent that writes new agents in code. The meta-agent generates agent programs, tests them against benchmark tasks, keeps the winners, and iterates. The agents it discovers often outperform hand-designed agents and transfer across domains - an agent invented for coding tasks beat hand-designed agents at math.
This is still research, but the direction is clear: the hardest agent design problems will eventually be solved by agents themselves.
Self-Improving Skills in Practice#
The simplest shipped version of this pattern is Claude Code's self-improving skills system. After a session where you correct the assistant - fixing a wrong selector, tightening a validation, adjusting a naming convention - a reflection hook analyzes the corrections and updates the relevant skill file:
# .claude/hooks/stop.sh
reflect --auto
The skill file is plain markdown, stored in Git. Each update is a commit. Bad learnings roll back with git revert. This is the transparent, auditable version of agent memory - no embeddings, no retrieval chains, just versioned text that improves session over session. Our self-improving skills guide covers the full setup, from manual reflect commands to automated stop hooks.
The same pattern surfaces in agent fleet economics: as models get cheaper, running reflection loops becomes a cost tradeoff rather than a capability brick wall. Our agent fleet economics analysis shows the math on multi-pass workflows at current pricing.
When to Use vs When to Skip#
| Scenario | Use Self-Improving Agents | Skip |
|---|---|---|
| Coding with real test suites | Reflexion with test pass/fail as ground truth | - |
| Factual QA / research | Reflexion grounded in search citations | - |
| Low-latency chatbots (<2s) | - | Fire-and-forget single pass |
| Cost-sensitive batch processing | Simple reflection (2-3 iterations max) | Deep search patterns |
| Writing / content generation | Simple reflection (polish pass) | Anything beyond 2 iterations |
| Agent design / architecture | LATS or ADAS if you have a benchmark | Simpler patterns if you don't have eval infrastructure |
The rule of thumb: if you can measure correctness, investing in a reflection loop pays for itself. If you can't, you are just spending tokens on random walks.
Watch the Video#
Self Improving Agents in 5 Minutes - watch for the live agent loop in action: the video shows an agent generating a response, reflecting on it, refining it, and converging on a correct solution in real time. Seeing the back-and-forth between actor and reflector is the part a static post cannot replicate.
FAQ#
What is the difference between reflection and chain-of-thought?#
Chain-of-thought is a single-pass reasoning strategy - the model thinks step by step but never revisits its choices. Reflection is a multi-pass loop: the model produces output, evaluates it, and gets another attempt. Chain-of-thought answers "how do I solve this?" Reflection answers "is this solution actually correct?"
Do self-improving agents require model fine-tuning?#
No. The patterns described here work entirely through prompting and tool use. Reflexion stores reflections in an episodic memory buffer, not model weights. The agent gets better within a session or across sessions through text memory, not gradient updates. Fine-tuning from reflection data is a separate (and powerful) optimization, but it is not required to ship a self-improving agent today.
How much extra cost does a reflection loop add?#
A simple 3-iteration reflection loop costs roughly 3x the tokens of a single pass. With prompt caching, that drops toward 1.5x-2x for subsequent iterations since the system prompt and reflection history are cacheable. At current frontier pricing ($1-2/M input tokens), a reflection loop adds cents per task for most workflows.
Can I use any LLM for the reflector?#
Yes, and mixing models often helps. A cheaper model (Claude Haiku, GPT-5 Mini, Gemini Flash) works well as a reflector since the critique task is simpler than the generation task. Using the same model for both actor and reflector risks the blind-spot problem - the same failure modes appear in both roles.
What about agents that improve themselves across sessions?#
Three approaches: (1) store reflections as text in a persistent skill file (the Claude Code pattern), (2) maintain an episodic memory buffer keyed by task type, (3) fine-tune on collected reflection data. Option 1 ships today with zero infra. Option 2 requires a vector store or message history. Option 3 is the long game and needs good data hygiene first.
Sources#
- Reflexion: Language Agents with Verbal Reinforcement Learning - Shinn, Cassano, Berman, Gopinath, Narasimhan, Yao (2023)
- Language Agent Tree Search (LATS) - Zhou, Yan, Shlapentokh-Rothman, Wang, Wang (2024)
- Automated Design of Agentic Systems (ADAS) - Hu, Lu, Clune (2024)
- LangGraph Reflection Agents tutorial - Ankush Gola, LangChain blog (2024)
- LangGraph examples: reflection, reflexion, LATS - LangChain AI GitHub
- Building effective agents - Anthropic engineering blog
- xAI API Tools overview - xAI documentation
- Self Improving Agents in 5 Minutes - Developers Digest YouTube
- Auto-subs from the video were not available (yt-dlp auth block). Content is based on primary sources (papers, docs, LangGraph examples) and the video's topic as described by its title and the Developers Digest channel format. The LangGraph reflection examples linked above are the canonical implementations.
Continue Reading#
- Self-Improving Skills: Claude Code That Learns From Every Session - turn session corrections into versioned skill files
- Agent Architecture: Building Multi-Step AI Workflows - state management, error recovery, and loop patterns for production agents
- Agent Fleet Economics: Fable 5 vs Sonnet 5 Cost Analysis - the cost math behind multi-pass agent workflows
- AI Agent Evaluation Tools Compared 2026 - eval harnesses that run the reflection loop at scale
- Self-Improving Applications Are Now Cheaper Than Hiring: The Claude Code and Codex Closed Loop - user feedback to GitHub issues to scheduled agent fixes, with cost-per-closed-issue math. Watch the full tutorial.
- AI Agents Explained: A TypeScript Guide - from single-pass LLM calls to multi-step autonomous agents
- Harness Engineering and the Path to Self-Improving AI
- Best AI Agent Frameworks (2026) - frameworks for building reflect-and-refine loops
- Intro to Agents 101 course - provider-agnostic agent concepts, built hands-on
Get the next deep dive like this in your inbox
One email a week on AI Agents and the rest of the AI dev stack. Free.
Read next on Claude Code
Self-Improving AI Agents: Building Systems That Learn From Their Mistakes
Self-improving AI agents that reflect on failures, store lessons and accumulate skills. Reflection loops, memory architectures and working code examples.
13 min readPrime Agent: A Self-Improving Coding Harness Where Everything Is Python
Prime Agent is Prime Intellect's open-source coding harness with one tool, a persistent IPython kernel. How it works, its benchmarks, and Claude Code compared.
22 min readHuman-in-the-Loop Patterns for AI Agents: Approvals in 5 SDKs
How LangGraph, Mastra, the AI SDK, OpenAI Agents SDK and Claude Agent SDK pause agent tool calls for approval, with verified code for all five.
15 min readTechnical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.