Topic
MODEL COMPARISON
All blog posts, tools, and guides about Model Comparison from Developers Digest.
7 resources - 7 posts
Blog Posts
View in blog →
Cheapest Subagent Model: Haiku 5.5 or GPT-6 Luna? Routing, Compaction and Cost per Task
Which cheap model belongs under your orchestrator? Haiku 5.5 vs GPT-6 Luna as a subagent or worker: routing by prompt length, compaction, tool-call gotchas and cost per agent task.
15 min read
Opus 5.5 vs Sonnet 5.5 vs Haiku 5.5: Which Claude Model to Use
Sonnet 5.5 is the default, Opus 5.5 is for open-ended long-horizon work, and Haiku 5.5 is for bounded steps and subagents. Prices, benchmarks, cost math.
8 min read
Claude Opus 5 vs Opus 4.8 vs Fable 5: Benchmark Comparison (July 2026)
Claude Opus 5 launched July 24, 2026 at $5/$25 per MTok - matching Opus 4.8 pricing while delivering near-Fable 5 intelligence. Full benchmark comparison across 7 evals, pricing breakdown, and decision guide.
22 min read
GPT-5.6 vs Claude 5: What the New Tiers Mean for Choosing a Coding Model
GPT-5.6 vs Claude 5 for coding: how OpenAI's Sol, Terra, and Luna tiers compare with Claude Fable 5 and Mythos 5 on pricing, benchmarks, and model choice.
9 min read
Why Price Per 1M Tokens Is a Misleading Metric for LLM Costs
Comparing LLMs by token pricing alone can lead you to choose worse, more expensive models. Cost per task tells the real story.
6 min read
Best Claude Model Now That Fable 5 Is Disabled (Mythos vs Opus vs GPT-5.5)
Fable 5 and Mythos 5 are gone for now. Here is the honest ranking of what to use today, from Opus 4.8 to GPT-5.5 to open-weight models, by task.
6 min read
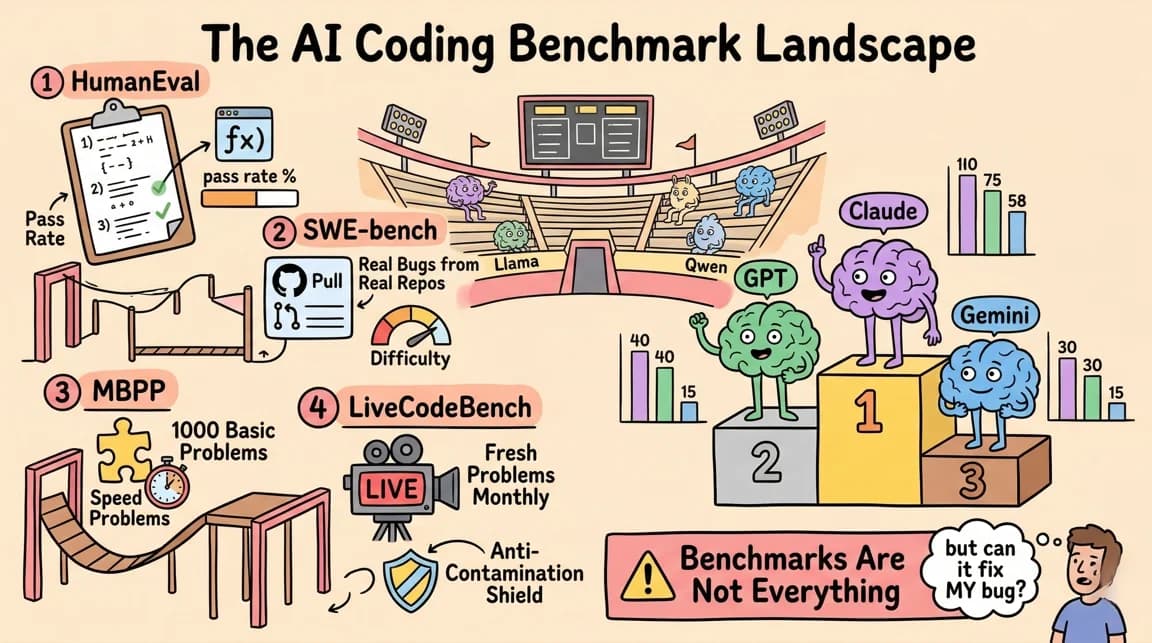
Web Dev Arena: How to Test AI Coding Models on Real Frontend Work
Web Dev Arena compares AI coding models on real frontend work: same prompt, different models, live output, plus frontend evals worth running beyond benchmarks.
8 min read
Keep exploring
More on Model Comparison
- - Glossary - dive deeper across the Developers Digest knowledge base
- - All Model Comparison articles in the blog archive
- - Developers Digest on YouTube - video tutorials covering Model Comparison and more

Get Smarter About AI Dev
New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
One email per weekReal code, not theoryFree forever
Explore 840 topics
Browse All Topics