Claude Context Is Code Search For Agents. Treat It Like Retrieval Infrastructure.
TL;DR
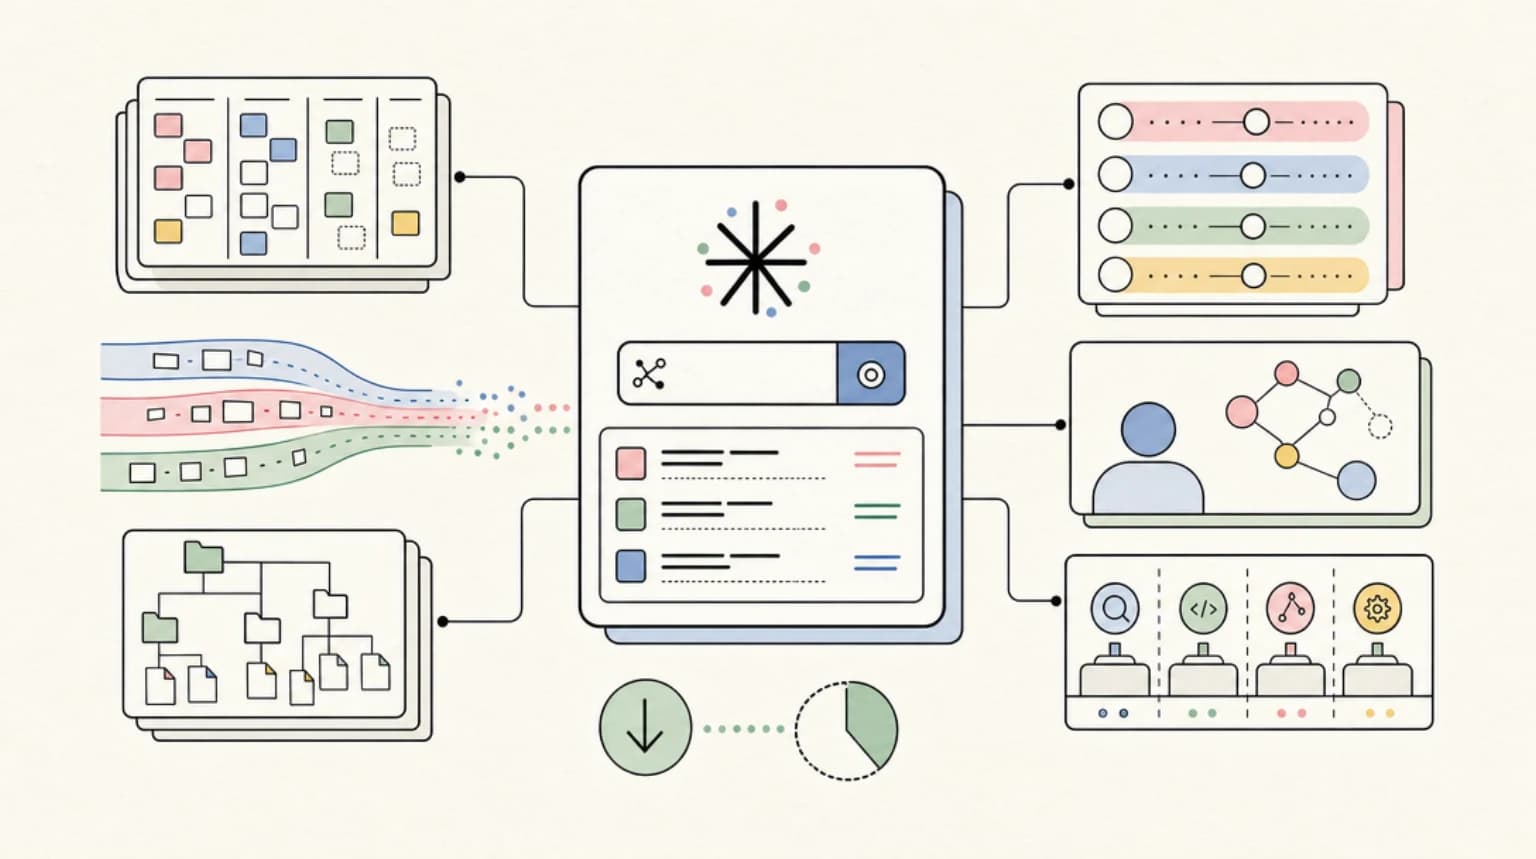
Claude Context gives coding agents semantic code search over MCP. The real test is whether retrieval makes agent work cheaper, more reviewable, and verifiable.
Last updated: June 24, 2026
The Better Question#
The April version of this post was written like a GitHub Trending snapshot: zilliztech/claude-context had crossed 10,000 stars, the README claimed meaningful token savings, and the obvious headline was "semantic code search for Claude Code."
That framing is too small now.
Claude Context is still a semantic code search MCP, but the better question is operational: when does retrieval infrastructure make coding agents better, and when does it become another opaque layer the reviewer has to trust?
As of this refresh, the repo is active on the master branch, was pushed on June 22, 2026, and the public GitHub API reports TypeScript, MIT license, about 11.9k stars, and roughly 890 forks. The npm packages @zilliz/claude-context-mcp and @zilliz/claude-context-core are at 0.1.15. The current README describes Claude Context as an MCP plugin that gives Claude Code and other coding agents semantic code search over an entire codebase.
The product shape matters because code search is becoming part of the agent runtime. We have written about terminal agents needing a portable runtime surface, agent workspaces needing filesystem contracts, and long-running agents needing harnesses. Retrieval belongs in that same stack. It is not just "find files faster." It is how an agent decides what evidence to inspect before changing code.
What Claude Context Does Now#
Claude Context runs as an MCP server. You configure it with a vector database and an embedding provider, then expose tools that let an agent index a codebase, search it, check indexing status, and clear an index.
The current docs describe the required pieces:
- Node.js
>=20.0.0 - a vector database, either Zilliz Cloud or local Milvus
- an embedding provider, with docs covering OpenAI, VoyageAI, Gemini, or local Ollama
- the MCP package
@zilliz/claude-context-mcp
The project is no longer just a Claude Code-specific setup snippet. The README includes configuration examples for Claude Code, Codex CLI, Gemini CLI, Qwen Code, Cursor, Void, Claude Desktop, Windsurf, VS Code, Cherry Studio, Trae, Cline, and Augment Code. That is the important ecosystem signal: code retrieval is being packaged as a portable tool, not a single-editor feature.
The package exposes the same basic workflow:
- Start indexing a resolved absolute path.
- Chunk the code and generate embeddings.
- Store chunks in Milvus or Zilliz Cloud.
- Let the agent search with natural language.
- Return relevant snippets instead of loading whole directories.
The async indexing docs add two current details worth knowing. Indexing starts and returns quickly while processing continues in the background, and search_code can work during indexing with partial results. Status is coarse and phase-based, not an exact per-file progress meter.
That is a practical improvement for agent work. A long indexing run should not freeze the entire session. But it also means the agent and reviewer need to know whether a result came from a complete index, a partial index, or a stale snapshot.
Why Semantic Search Helps Agents#
Coding agents fail when they modify code without reading the right surrounding context.
Sometimes they know the file name. Often they do not. The task might say "fix billing retries," while the relevant behavior lives across a queue consumer, an API route, a config file, a cron job, and a test helper. Plain keyword search can miss the connection. Dumping a directory into context is expensive and noisy. Manual file selection turns the human into the retrieval system.
Semantic code search is useful because it can turn intent into a candidate evidence set. A query like "where do we retry failed payment events" can surface files that do not share the exact phrasing. Hybrid retrieval helps because code has both meanings and exact identifiers. Dense vectors help with intent. Keyword search helps with function names, file paths, and constants.
That is also why retrieval should produce receipts. If an agent uses Claude Context to change code, the final handoff should say which searches it ran, which files or chunks mattered, and which checks passed. Otherwise the reviewer sees a diff but not the evidence path that led to it.
This is the same argument behind agent swarms needing receipts and local OpenTelemetry traces as agent receipts. A retrieval call is part of the work. It should be inspectable.
The Token-Savings Claim#
The older articles leaned on a roughly 40% token reduction claim from the project. That claim is still directionally plausible, but it should not be treated as a universal benchmark.
Retrieval saves tokens when it replaces broad context loading with a small, relevant evidence set. It can waste tokens when it returns too many chunks, stale chunks, duplicate chunks, or plausible but irrelevant code. It can also create a false sense of coverage: the agent may search, retrieve something convincing, and never inspect the file that actually matters.
The useful metric is not "did retrieval reduce tokens?" It is:
- Did the agent find the right code faster?
- Did it avoid loading unrelated directories?
- Did the final diff become easier to review?
- Did the final report cite the files and searches that mattered?
- Did tests or typechecks catch mistakes that retrieval missed?
That last point matters. Retrieval is not verification. It is evidence discovery. Verification still belongs to tests, typechecks, smoke checks, screenshots, route checks, and human review. See agent evals need baseline receipts for the same distinction at the benchmark layer.
The Current Setup Shape#
For Claude Code, the README still shows the same broad MCP pattern: add the MCP server with environment variables for the embedding provider and vector database, then let Claude call the tools during a session.
The default OpenAI setup uses an API key and text-embedding-3-small, but the docs also cover VoyageAI's code-focused embeddings, Gemini embeddings, and Ollama for local embeddings. That provider flexibility matters for teams with privacy, cost, or data-residency constraints.
Zilliz Cloud is the easiest vector database path. Local Milvus is the advanced path. The local option is important because some teams will not want code embeddings stored in a managed service, even if only embeddings and chunks are involved.
Two newer operational details are worth calling out.
First, file inclusion and exclusion rules matter. A code index should not ingest secrets, generated artifacts, private uploads, build outputs, or huge vendor directories. The MCP docs include custom extension and ignore-pattern configuration. Treat those patterns as policy, not convenience.
Second, the trigger-file watcher means external tools can request an immediate sync by touching ~/.context/.sync-trigger. The docs show this as useful for Claude Code hooks after edits or writes. That is powerful, but it also connects retrieval to the hook system. If you use it, review it the way you would review other automation. Claude Code hooks explained is the companion layer here.
Where It Fits#
Claude Context is a good fit when the codebase is too large for manual file curation but stable enough that indexing is worthwhile.
It is especially useful for:
- onboarding to a large repo
- debugging behavior spread across several modules
- planning refactors where callsites are not obvious
- answering architecture questions before editing
- giving headless agents a way to discover context before making changes
It is less useful for small projects where the relevant files are obvious, or for high-churn generated code where the index is constantly stale. It is also not a substitute for a codebase map, ownership docs, tests, or a careful review process.
If you already run multi-agent workflows, retrieval should be part of the workspace contract. Each agent should know which path was indexed, whether it used a partial or complete index, and how retrieved files map to the branch it edited. That connects directly to parallel coding agents needing merge discipline and how to coordinate multiple AI agents.
The Opposing View#
There is a serious skeptical case against semantic code search for agents.
First, code is not prose. Exact identifiers, types, imports, call graphs, and control flow matter. A vector match can feel semantically close while missing the one file that enforces the invariant.
Second, retrieval can hide uncertainty. If the agent receives five plausible chunks, it may act as if the whole codebase was searched thoroughly. A reviewer may not know whether the index excluded generated files, tests, migrations, or private packages.
Third, vector infrastructure adds failure modes: embedding provider outages, rate limits, stale collections, path-hash confusion, local snapshot drift, and vector DB credentials. The current Claude Context docs are honest about some of this by documenting status states, partial indexing, path identity, and stale snapshot behavior.
The right conclusion is not "skip retrieval." It is "treat retrieval as infrastructure." Put it behind ownership, config review, status checks, and final receipts.
That is the same governance pattern as MCP server debugging with MCP Lens and best MCP servers in 2026. MCP servers are tools with state, credentials, and failure modes. They deserve the same operational attention as any other tool in the agent loop.
The Take#
Claude Context is useful because it moves code discovery out of the human's clipboard and into an agent-callable tool. That is the right direction for large repositories.
But semantic search is not magic context. It is retrieval infrastructure. It needs clean inclusion rules, fresh indexes, understandable status, provider choices, security boundaries, and reviewable search receipts.
The teams that get the most out of it will not be the ones that install it and trust every result. They will be the ones that ask the agent to show its evidence path before they accept the diff.
FAQ#
What is Claude Context?#
Claude Context is an MCP server and TypeScript package from Zilliz that lets AI coding agents index and semantically search a codebase.
Is Claude Context only for Claude Code?#
No. The README includes setup examples for Claude Code, Codex CLI, Gemini CLI, Cursor, Windsurf, VS Code, Claude Desktop, Cline, and other MCP clients.
What services does Claude Context require?#
It needs Node.js 20 or newer, an embedding provider such as OpenAI, VoyageAI, Gemini, or Ollama, and a vector database such as Zilliz Cloud or local Milvus.
Does semantic code search replace tests?#
No. It helps the agent find relevant code. Tests, typechecks, smoke checks, and human review still verify whether the change is correct.
What is the biggest risk?#
The biggest risk is trusting retrieved snippets without knowing index freshness, inclusion rules, search queries, and omitted files. Retrieval needs receipts.
When should a team skip it?#
Skip it for small codebases, obvious one-file tasks, or workflows where code embeddings and chunks cannot leave a controlled environment and local Milvus/Ollama are not acceptable.
Sources#
- zilliztech/claude-context GitHub repository
- Claude Context README
- Claude Context MCP package README
- Claude Context prerequisites
- Claude Context async indexing workflow
- npm registry: @zilliz/claude-context-mcp
- npm registry: @zilliz/claude-context-core
- Claude Code MCP docs
- Model Context Protocol documentation
Get the next deep dive like this in your inbox
One email a week on MCP and the rest of the AI dev stack. Free.
Read next on Claude Code
Codex and Claude Code in July 2026: Agent Controls Are the Feature
Codex and Claude Code July 2026 updates compared: why approval modes, resumable work, MCP auth, artifacts and review surfaces now matter as much as models.
8 min readGitHub Copilot Agent Finder: What ARD Means for Third-Party AI Tools in 2026
GitHub Copilot Agent Finder discovers and invokes MCP servers, skills and agents like Claude and Codex. How the open ARD spec changes AI tool integration.
8 min readClaude Code 2.1.128 Is an Ops Release, Not a Feature Drop
Claude Code 2.1.128 is an ops release: fixes for MCP, worktrees, OTEL, plugins and permissions that matter for teams running coding agents every day.
6 min readTechnical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.