Topic
COMPARISON
Side-by-side comparisons of AI coding tools, models, and frameworks to help you pick the right one.
44 resources - 43 posts, 1 guide
Blog Posts
View in blog →
Claude vs Claude Code: What the Difference Is and Which to Use (2026)
Claude vs Claude Code: one app for chat, docs and general work, one agent for your codebase. Same model family and shared plan limits, different jobs.
6 min read
MCP vs A2A vs Function Calling: Which Layer Does What in 2026
MCP vs A2A vs function calling compared on the 2026-07-28 MCP spec and A2A 1.0: what each protocol does, where they overlap, and how to stack them.
13 min read
Claude Code vs Codex vs Copilot CLI: Local Sandboxes Compared
Copilot CLI local sandboxing is GA. How it compares with Claude Code and Codex on defaults, network, credentials, Windows, and what still runs outside.
11 min read
Antigravity vs Cursor (2026): Pricing, Limits, Models, and Which to Pick
Antigravity vs Cursor: Antigravity is free with a weekly limit; Cursor starts at $20/month with the widest model menu. Pricing, limits and a decision guide.
9 min read
Claude Cowork vs Claude Code (2026): Which One Should You Use, and What Does It Cost?
Claude Cowork vs Claude Code: Code is for software, Cowork for documents, spreadsheets and research. Both are in every paid Claude plan. How to pick.
9 min read
GPT-6 Sol vs Claude Opus 5.5 vs Grok 4.7: The September 2026 Price War
GPT-6 Sol vs Claude Opus 5.5 vs Grok 4.7 pricing: verified per-token rates, cost-per-task math and a decision guide for the September 2026 price war.
9 min read
pi vs Claude Code vs OpenCode: Picking Your Agentic CLI
pi vs Claude Code vs OpenCode vs Codex CLI: a verified capability matrix and pick-X-if verdicts for choosing your main agentic coding harness.
10 min read
Don't Paste the AI vs Vomit vs NoBuzz: AI Slop Tools Compared
Don't Paste the AI, Vomit and NoBuzz compared: AI slop tools for a shared link, a local rewrite or a second-model Claude Code skill, and when to skip them.
8 min read
Slack Code vs Claude Code vs Cursor vs OpenCode: When Agents Belong in Chat
Slack Code gives coding agents their own Slack channels with diffs, previews, and an audit log. When it beats Claude Code, Cursor, or OpenCode, and when not.
7 min read
Qwen3.8-27B vs Opus 4.6 Max: Local Agentic Coding Benchmarks
Qwen3.8-27B is a 27B dense Apache-2.0 model that beats Opus 4.6 Max on SWE-bench Pro (61.7 vs 53.4). Benchmarks, hardware, cost and when to run it.
10 min read
AMD MI355X vs NVIDIA B200 vs B300 for Open-Weight Serving
AMD MI355X vs NVIDIA B200 vs B300 for serving Kimi K3's about 1.5TB of open weights: verified specs, the Wafer benchmark, and cost per token for each.
9 min read
AI Session Portability Compared 2026: OpenAI vs Anthropic vs Gemini
AI session portability compared across OpenAI, Anthropic, and Gemini: storage defaults, encrypted reasoning, compaction, and what you can move or audit.
11 min read
Antigravity CLI vs Claude Code vs Codex: The Terminal Agent Field Guide (July 2026)
Antigravity CLI vs Claude Code vs Codex: how Google's Gemini CLI replacement compares on architecture, pricing, multi-agent workflows, and daily coding.
9 min read
Budget AI Coding Models, October 2026: Haiku 5.5 vs GPT-6 Luna
Claude Haiku 5.5 and GPT-6 Luna both list at $0.10/$0.50 per MTok. The price tie breaks at Haiku's 100K cliff, and Anthropic's benchmarks favor Haiku. Checked Oct 8, 2026.
11 min read
MCP Apps vs Tool Calling vs Standalone UIs: Interactive Interfaces for Agent Tools Compared
MCP Apps vs tool calling vs standalone web UIs: how sandboxed interactive UIs for MCP servers compare to the other two, and when to use each approach.
9 min read
MCP vs Agent Skills: When to Use Which (and Why You Need Both)
MCP vs Agent Skills: MCP gives agents live access to tools and data, Skills give them packaged procedure. The decision rule for when to use which, or both.
11 min read
AI Coding Agent Firewalls and Security Layers Compared 2026
AI coding agent firewalls compared: Belay, Claude Code hooks, Codex CLI sandboxes and MCP proxies vs destructive commands, secret leaks and prompt injection.
9 min read
AI Coding Agent Security Models Compared 2026: Permissions, Sandboxing, and Threat Models for Every Major Tool
AI coding agent security models compared: how Claude Code, Cursor, Codex, Copilot, Aider and Windsurf handle permissions, sandboxing and prompt injection.
10 min read
Kimi K3 vs K2.7 Code: Is the Upgrade Worth It for Coding?
Kimi K3 vs K2.7 Code: 1M vs 256K context, $3/$15 vs $0.95/$4 per million tokens, and when the bigger model earns its price on coding work.
6 min read
Prompt Management Tools Compared: Langfuse vs PromptLayer vs More
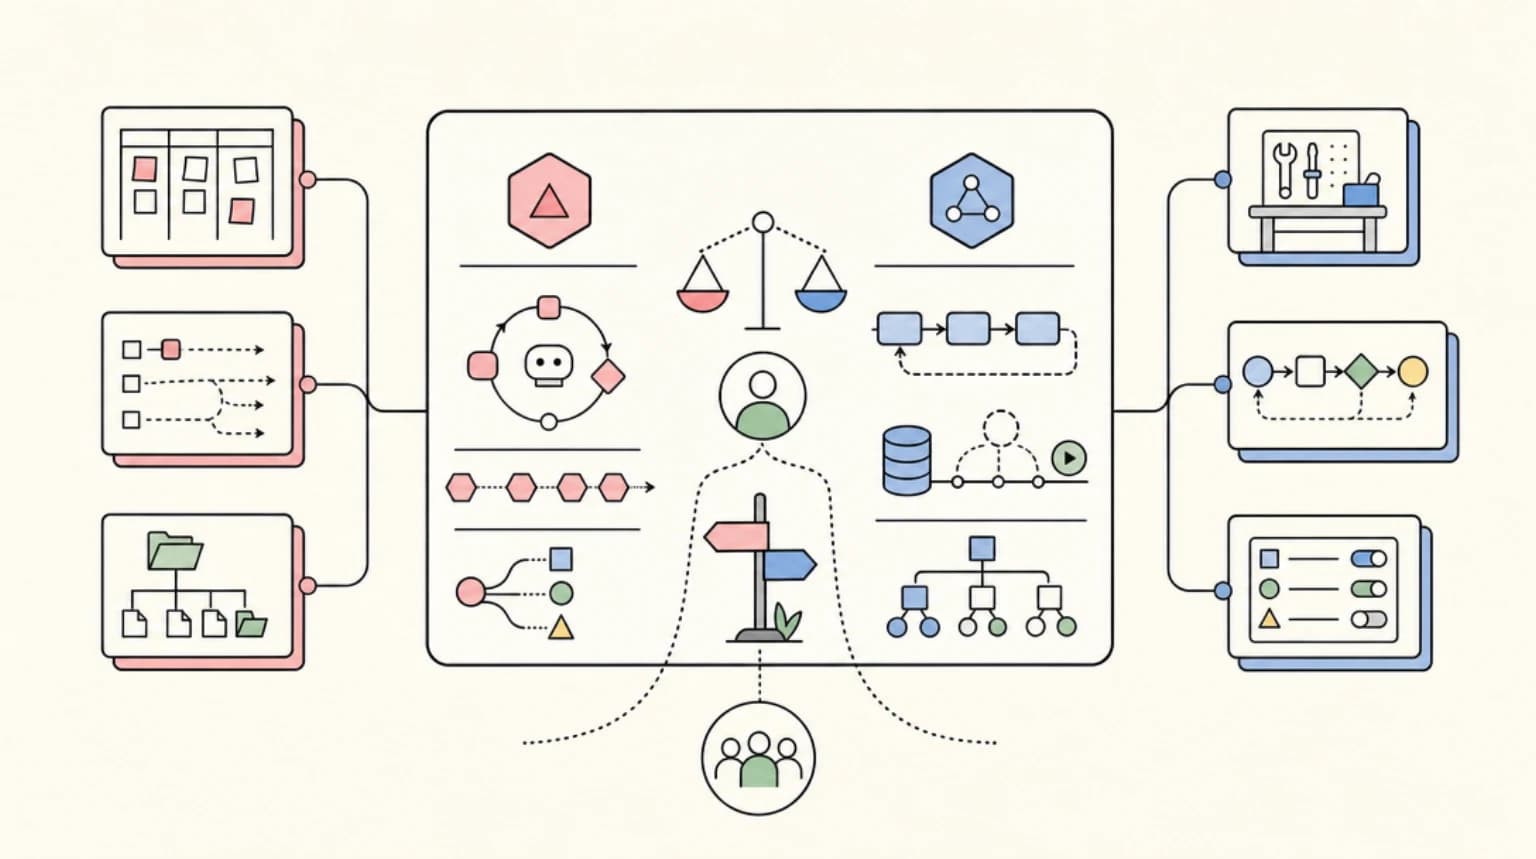
A fair look at Langfuse, PromptLayer, Promptfoo, Helicone, Latitude, and Agenta for versioning, evals, and deploying LLM prompts.
10 min read
GLM-5.2 vs DeepSeek V4 vs Qwen3: The Open-Weights Coding Model Showdown (2026)
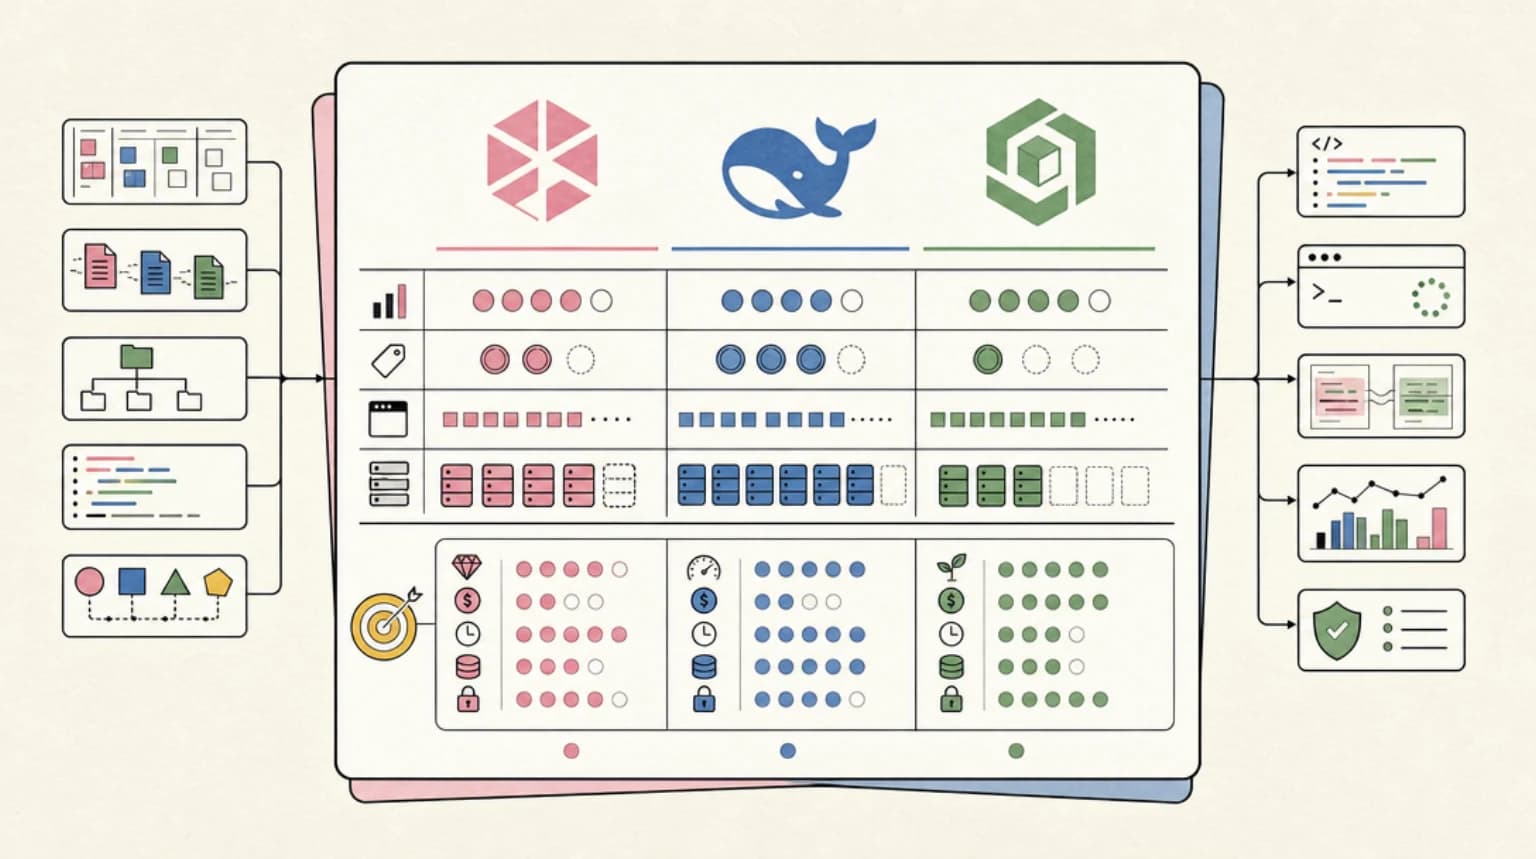
GLM-5.2 vs DeepSeek V4 vs Qwen3 vs Kimi K3: open-weights coding models compared on benchmarks, pricing, context windows, self-host footprint and best picks.
14 min read
Claude Agent SDK vs Claude Code: When to Build and When to Drive
Claude Agent SDK vs Claude Code explained: same engine, two surfaces. Here is the concrete decision line, plus where Managed Agents fits as the hosted third option.
8 min read
Claude Code Routines vs Managed Agents Schedules: Where Recurring Agent Work Should Live
Claude Code Routines vs Managed Agents scheduled deployments: how triggers, pricing and limits differ, and where your recurring agent work should run.
9 min read
Subagents vs Agent Teams vs Workflows: Claude Code's Parallelism Primitives, Compared
Claude Code subagents vs agent teams vs workflows: who holds the plan, the hard limits from the docs, and which parallelism primitive fits your task.
9 min read
Claude Fable 5 vs Gemini 3.1 Pro: July 2026 Comparison
Claude Fable 5 vs Gemini 3.1 Pro: Anthropic's $10/$50 API-only model vs Google's $2/$12 preview on price, context and benchmarks, and how Opus 5 shifts it.
10 min read
The Frontier Model Landscape, July 2026 Edition
Frontier AI model directory for July 2026 covering Claude Fable 5, Opus 5, GPT-5.6, Sonnet 5, Gemini 3.1 Pro, Kimi K3 and DeepSeek V4, with verified pricing.
12 min read
The Mid-Tier Shootout: GPT-5.4 vs Gemini 3.1 Pro vs DeepSeek V4 Pro
GPT-5.4 vs Gemini 3.1 Pro vs DeepSeek V4: pricing, benchmarks, context behavior, and license terms for the mid-tier models that carry most production traffic.
11 min read
GPT-5.6 Sol vs Claude Opus 5: The $5 Workhorse Head-to-Head
GPT-5.6 Sol vs Claude Opus 5: both cost $5 per million input tokens, so the workhorse-tier decision comes down to output pricing, benchmarks, and tooling.
11 min read
Best AI Coding Tools July 2026: Updated After Opus 5 and Fable 5 API-Only
Best AI coding tools for July 2026, re-ranked after Opus 5 launched at half Fable 5's price and Fable 5 went API-only - pricing, picks and stacks by profile.
10 min read
Codex vs Claude Code in 2026: Which AI Coding Agent Should You Use?
Codex vs Claude Code in 2026: pick Claude Code for ambiguous multi-file work with skills and MCP, or Codex for well-scoped tasks and strong defaults.
12 min read
Claude Fable 5 vs GPT-5.6 Sol: Benchmarks, Pricing, and When Each Wins
Fable 5 is API-only at 2x GPT-5.6 Sol's price with a 15-point SWE-Bench Pro gap. Here is the decision framework for choosing between them in August 2026.
12 min read
GitHub Copilot's New Usage-Based Billing: What Changed June 1 and What It Costs Now
GitHub Copilot moved to AI Credits billing on June 1. What changed, how Copilot Max and budgets work, and how costs compare to Claude Code and Codex for teams.
8 min read
Microsoft's MAI Models and MoE Strategy: What Developers Need to Know for Copilot and Beyond
Microsoft's MAI models from Build 2026, including MAI-Code-1-Flash in GitHub Copilot. What the MoE designs, benchmarks and rollout mean for your toolchain.
7 min read
Vercel AI SDK 6 vs LangGraph 1.0: Which Agent Framework Should TypeScript Teams Use?
Vercel AI SDK 6 vs LangGraph 1.0 for TypeScript agents - ToolLoopAgent versus durable state graphs, and how to choose the right framework for your team.
8 min read
Astro vs Next.js 16: Which to Choose in 2026
Astro vs Next.js 16 in 2026: Astro ships far less JavaScript for content sites, while Next.js wins for apps. A decision guide with real config examples.
12 min read
Claude Code vs Codex vs Cursor vs OpenCode: Which Agent Ships More Code?
Four agents, same tasks: honest trade-offs between Claude Code, Codex CLI, Cursor Agent and OpenCode from a developer shipping production apps with all of them.
10 min read
Every AI Coding Tool Compared: The 2026 Matrix
Every AI coding tool compared: 15 terminal, IDE, cloud and browser tools side by side on pricing, model surface, strengths, weaknesses and best use cases.
18 min read
Claude Code vs Cursor vs Codex: Which Should You Use?
Terminal agent, IDE agent, local-plus-cloud agent. Three architectures compared - how to decide which fits your workflow, or why you should use all three.
8 min read
Claude vs GPT for Coding: Which Model Writes Better TypeScript?
Claude vs GPT for real TypeScript work: benchmarks, pricing, model families, and the practical differences that matter when picking a coding model.
9 min read
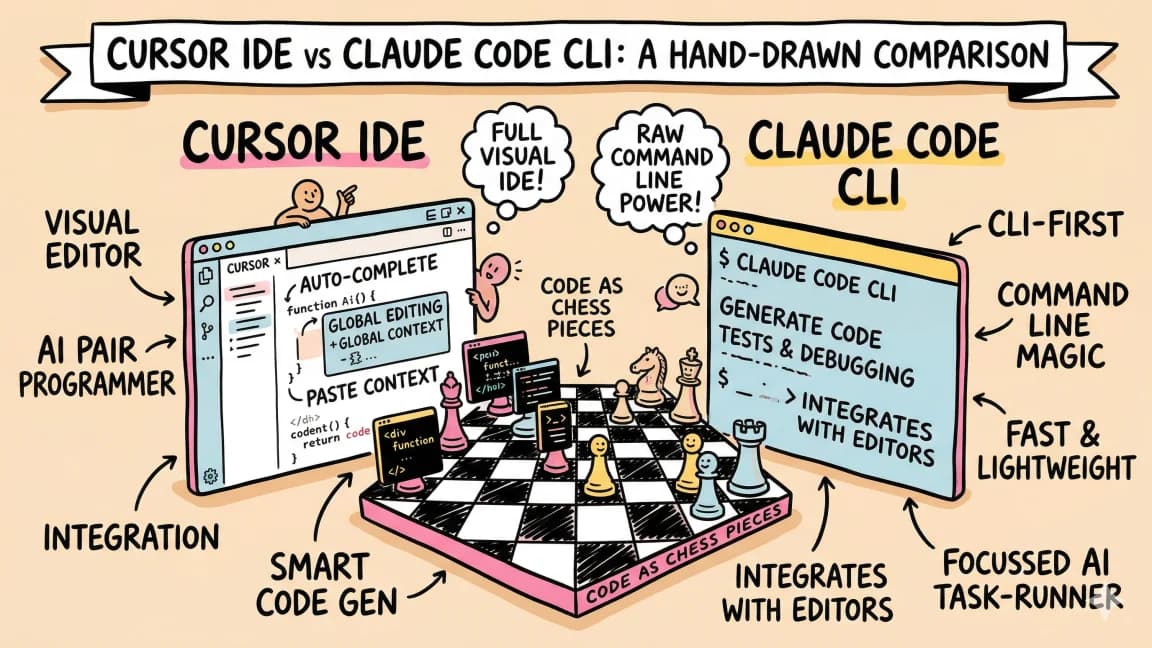
Claude Code vs Cursor in 2026: Which Should You Use?
Claude Code vs Cursor in 2026: Claude Code for autonomous terminal-first multi-file work, Cursor for editor-native iteration. Pricing and a decision framework.
11 min read
Cursor vs Codex: IDE Agent vs Terminal and Cloud Agent for TypeScript
Cursor is editor-first. Codex is terminal, cloud, and PR-first. Here is when to use each for TypeScript projects.
5 min read
OpenAI vs Anthropic in 2026 - Models, Tools, and Developer Experience
A developer's comparison of OpenAI and Anthropic ecosystems - models, coding tools, APIs, pricing, and which to choose for different use cases.
18 min read
Windsurf vs Cursor: Which AI IDE for TypeScript Developers?
Windsurf vs Cursor for TypeScript. Windsurf, now Devin Desktop, has Cascade and Cursor has Composer 2.5 - how they compare on context, pricing and models.
6 min read
Keep exploring
More on Comparison
- - Glossary - dive deeper across the Developers Digest knowledge base
- - All Comparison articles in the blog archive
- - Developers Digest on YouTube - video tutorials covering Comparison and more
Get Smarter About AI Dev
New tutorials, open-source projects, and deep dives on coding agents - delivered weekly.
One email per weekReal code, not theoryFree forever
Explore 848 topics
Browse All Topics